Tag: cloud infrastructure

  • Report Finds Most Cloud Security Issues Left Unaddressed

    Report Finds Most Cloud Security Issues Left Unaddressed

    Accurics, a provider of a platform for assessing the security of cloud computing environments, has published a report that finds that even once discovered, only 4% of issues reported in cloud production environments are addressed.

    Based on research conducted using its platform and other public sources of data, the report also finds 90% of organizations allow privileged users to make configuration changes directly to a cloud infrastructure after it is deployed.

    Issues such as open security groups, overly permissive identity access management (IAM) and exposed cloud storage services make up 67% of the most common cloud security issues being uncovered, according to the report.

    The Accurics report echoes similar findings published by Unit 42, the cybersecurity arm of Palo Alto Networks, which found more than 199,000 templates have medium-to-high vulnerabilities in use on public clouds.

    Accurics CEO Sachin Aggarwal said that as more organizations embrace infrastructure as code using tools such as Terraform, policy guardrails aren’t being put in place. More troubling still, security assessments seem to be few and far between. That’s especially problematic because cybercriminals now routinely probe every layer of the application stack looking vulnerabilities, he noted. In effect, cybercriminals are assessing cloud applications and infrastructure more frequently than IT teams.

    Aggarwal said beyond making sure the appropriate guardrails are in place in terms of overall security posture, organizations need to have confidence in the DevOps processes being adopted. That doesn’t mean cybersecurity teams should put rules in place that slow that application development process down. Rather, tools that surface cybersecurity issues and then provide a method to automate the remediation of any vulnerabilities discovered need to be put in in the hands of IT professionals, he said.

    The challenge organizations face is the processes that are employed to secure on-premises IT environments largely don’t translate well to highly dynamic cloud computing environments that assume a shared responsibility approach to IT. Public clouds are obviously popular with DevOps teams that can programmatically invoke resources on demand. However, those teams generally don’t have much cybersecurity expertise. Too often, DevOps teams assume cybersecurity tasks are being handled by a cloud service provider. Of course, the cloud service provider is only securing the services they provide. Any configuration issue is not their responsibility.

    The result is as more changes are made to the IT environment, the more likely that mistakes will be made. Catching all those issues without the aid of tools is an unreasonable expectation for any IT organization, much less a DevOps team that may be working beyond the purview of the rest of the IT organization.

    No one sets out to create a cybersecurity issue. But in the rush to deploy or update an application it’s easy to overlook a cybersecurity issue. The goal should be to eliminate as many of those mistakes as possible before they are ever made. However, as long as humans are involved, there will be errors. So the next most important thing is to be able to correct those mistakes as quickly as possible without having to disrupt the entire IT environment.

  • Lucidchart Launches Tool to Visualize AWS Cloud Environments

    Lucidchart Launches Tool to Visualize AWS Cloud Environments

    Lucidchart today added a visualization tool that generates interactive diagrams of an IT organization’s Amazon Web Services (AWS) environment.

    Dan Lawyer, senior vice president of product at Lucidchart, said Lucidchart Cloud Insights makes it possible to automatically visualize all the services an organization is consuming from the cloud service provider, with support for other cloud platforms planned.

    One of the biggest challenges organizations regularly encounter today is the only way they have of understanding what services are being consumed is to analyze the monthly bill made available by a cloud service provider, he said.

    Lucidchart Cloud Insights is designed to make it easy to determine what services are being consumed in real-time, Lawyer said, noting IT teams can also visualize cloud governance data along and apply filters and save views.

    Armed with that information, IT organizations can then better control spending across cloud services that, in terms of costs, are often widely divergent. Developers, for example, don’t always pay close attention to which tiers of service provide the optimal level of cost of a certain class of workloads. A high-fidelity approach to visualizing how services are consumed provides an effective means to have that conversation, noted Lawyer.

    Once an issue arises it can be resolved faster because everyone involved is capable of visually inspecting the same set of interactions occurring at the same time, he added.

    Lucidchart already provides visual workspaces in the cloud that combine diagramming, data visualization and collaboration tools to make it easier for teams to collaborate. Lucidchart Cloud Insight now extends that capability into IT operations, Lawyer said, noting IT teams traditionally have relied on tools such as Microsoft Powerpoint to try and visualize consumption patterns.

    The launch of Lucidchart Cloud Insight comes at a time when more workloads are moving on to public clouds in the wake of the COVID-19 pandemic. Given the uncertainties surrounding when IT staff might be able to access an on-premises IT environment, many organizations are accelerating the rate at which application workloads are being deployed in the cloud.

    The challenge IT organizations face is that moving applications into the cloud doesn’t always yield consistent cost savings. IT teams constantly need to monitor how IT infrastructure resources are being consumed to keep IT budgets under control. The issue is that developers frequently spin up cloud services without telling anyone in IT about it until a bill shows up. Worse yet, many developers often forget to de-provision virtual machines and other cloud resources they’re no longer using.

    Of course, as more cloud platforms are invoked, the management issue only becomes that much more complex. Going forward IT teams will want to visually compare and contrast how services are being consumed across multiple clouds. Whatever the motivation, it’s a lot easier to overlook the implications of a cloud service that is presented as part of a static bill than it is one that visually presents itself as part of an interactive diagram that is always up to date.

  • Commvault Deepens Ties With NetApp to Automate Data Protection

    Commvault Deepens Ties With NetApp to Automate Data Protection

    Commvault has extended its alliance with NetApp to make it possible to recover files nearly instantaneously from an all-flash memory array.

    Ranga Rajagopalan, vice president of product management for Commvault, said NetApp Scale-out Data Protection (SDP) from Commvault builds on its backup and recovery software to make it possible to use to NetApp hyperconverged infrastructure in combination with all-flash arrays running StorageGRID object storage software to now recover data stored on-premises or in the cloud.

    The on-premises capability is critical because it eliminates potential downtime in the event of a ransomware attack, Rajagopalan said, noting data can be recovered from an all-flash array residing on-premises using a scale-out architecture in a matter of seconds.

    At the same time, IT organizations can take advantage of an object storage system from NetApp that is compatible with the S3 application programming interface (API) to store data in the cloud, he added.

    Most IT organizations are by now aware the only way to combat ransomware is to be able to access a pristine copy of their data. The challenge they face, however, is finding a way to make that data accessible as fast as possible. It not only takes a significant amount of time to extract data from a cloud service, but it is also expensive. By keeping an organization’s most recent data available in an all-flash array locally, the time to restore data is sharply reduced, said Rajagopalan.

    Of course, organizations have been keeping copies of data on magnetic storage systems for years. However, as the cost of all-flash arrays continues to decline it’s now more affordable for organizations to consider employing much faster all-flash arrays to back up and recover their most mission-critical data, he added.

    Commvault also makes available application programming interfaces (APIs) through which the whole data protection process can be automated, he said.

    In the wake of the COVID-19 pandemic, there are two issues that many organizations are now struggling to manage. The first is the need to automate more processes at a time when many organizations will have smaller IT staffs. The number of IT personnel that can be dedicated to manually managing data protection tasks will be fewer during the economic downturn.

    At the same time, however, the number of ransomware attacks being launched continues to increase. All it takes is one mistake for an organization to find all its data encrypted. As a result, the relationship between data management and cybersecurity has become much tighter as organizations strive to ensure they always have a pristine copy of their data available.

    In the months ahead there is no doubt there will be a lot more focus on the total cost of IT operations. The challenge is, finding a way to reduce those costs must be balanced against the existing commitment to service level agreements (SLAs). The only way to meet those often-conflicting goals is to rely more on IT automation frameworks to make data always available, in a way that requires much less human intervention.

  • Deploying OpenStack: Pick a Distribution With These 7 Qualities

    Deploying OpenStack: Pick a Distribution With These 7 Qualities

    OpenStack, which turns 10 years old in July, remains the leading open source infrastructure component in private clouds. But, there is a plethora of OpenStack distributions out there, and selecting the right one is vital to the success of every organization’s OpenStack project.

    How do you know which is best? It’s an important question because, despite OpenStack’s popularity, companies often face serious challenges when adopting and deploying it. Put simply, OpenStack can be time-consuming and skill-heavy in order to deploy it, unless the chosen distribution is equipped to overcome those challenges.

    Thus, anyone planning to deploy OpenStack should make sure the distribution they pick meets the following seven criteria.

    Strong Economics

    Cloud environments are supposed to be more cost-efficient than proprietary hardware. That’s why enterprises love the cloud, after all. Therefore, the number one priority when choosing an OpenStack distribution is to make sure it can indeed reduce costs. That means steering clear of OpenStack platforms that are hard to deploy, maintain, upgrade and force you to struggle with basic operations. It’s also important that the distribution’s pricing model be clear and predictable so that organizations can plan expenses accurately.

    Totally Open Source 

    While OpenStack itself is open source, the installers provided by the vendors as part of their distributions often are not. This can lead to additional costs being applied to the licenses and situations where organizations are forced to pay for the distribution before even trying it out. Furthermore, all types of environments in use—including staging and development—need to be covered by the license, too. These pitfalls are sidestepped with OpenStack distributions that are 100% open source, providing better economics and flexibility for organizations.

    Predictable Release Cadence 

    While the release cadence of OpenStack is predictable and well documented, not all distributions follow the upstream quickly enough. Making sure the OpenStack distribution you choose supports the latest stable upstream release as soon as possible is crucial for a few reasons. The upstream release may have features that are important for the organization. Or there may be bug fixes that they feel are critical. Picking a downstream distribution with a predictable release cadence that stays in sync with the upstream ensures transparency and allows organizations to plan the upgrade process. 

    Long Support Runway

    Support services are essential for OpenStack production environments, especially when service level agreements (SLAs) apply. But, how long vendors will support older versions of OpenStack can vary. Though there is always an option to upgrade or re-deploy, there are times when it may be beneficial for organizations to stay with the current version. Thus, how long the vendor will provide support services is a key factor in choosing a distribution.

    Upgrades Made Easy

    There inevitably comes a time for most organizations when they want to upgrade their upstream OpenStack. However, OpenStack upgrades are known to be complex, and many commercial distributions do not support them. Even if they do, the process is complex and must be executed manually. Thus, choosing an OpenStack distribution that provides support for fully automated upgrades is essential for the success of the cloud operations team.

    Simplified Operations 

    Even after an OpenStack cloud is deployed, consideration must be given to the ongoing operations that can become complex and fragile. Maintaining the cloud on a daily basis includes operations such as scaling the cluster out or recovering it from failure. While most OpenStack distributions don’t provide mechanisms to simplify these tasks—forcing users to execute them manually—some do. Organizations should look to distributions that do a good job automating complex operational tasks, saving time and money.

    Flexible Technology Choices 

    OpenStack is a flexible cloud platform, supporting various hypervisors, software-defined networking (SDN) solutions and storage plugins. But many distributions are tied to a single stack. That means an organization may need to re-platform or move to a heterogeneous environment in the future. Avoid that trap by selecting a distribution that can adapt to work with new technologies.

    By looking for these seven qualities, organizations can get the most out of their OpenStack distribution and optimize the cloud infrastructure on which they increasingly rely.

  • Despite Downturn, Enterprise IT Budgets Remain Intact

    Despite Downturn, Enterprise IT Budgets Remain Intact

    A survey of 137 IT operations leaders at companies in the U.S with at least 500 employees and an annual IT budget in excess of $5 million finds a surprising amount of resiliency at the beginning of the COVID-19 pandemic.

    Conducted April 1 by OpsRamp, a provider of IT operations tools, the survey finds more than half of the survey respondents (58%) said they expect to either significantly or moderately increase their annual technology budgets, while 38% plan to either significantly or moderately reduce their technology spending.

    The survey also finds 73% of respondents expect to either accelerate or maintain digital transformation initiatives and projects.

    Bhanu Singh, senior vice president of engineering and DevOps for OpsRamp, said that at least for now among larger enterprises, digital business initiatives are being accelerated as organizations recraft their business continuity plans. With most customers and employees working from home, the need for applications that digitize business processes has become more critical, especially since no one knows for sure when the COVID-19 pandemic might subside or whether there will be another one, he said.

    Many of those projects will rely on cloud-native technologies that make it easier for organizations to scale IT resources up and down, added Singh, noting organizations are quickly discovering that monolithic applications even when they are deployed on a public cloud are not as flexible as they now require.

    Specifically, the survey finds IT leaders are investing heavily in AIOps (69%), information security and compliance (62%), self-service platforms (60%), cloud-native observability (51%), network performance monitoring and diagnostics (51%), big data analytics (46%) and cloud infrastructure (45%).

    IT leaders are also planning to drive technology vendor consolidation (59%) to reduce costs and rely more on third-party managed service providers (58%).

    In terms of hiring, IT financial analysts (68%), cloud architects (53%), DevOps engineers (50%) and data scientists (47%) top the list of priorities.

    Of course, as the impact of the COVID-19 pandemic on the global economy becomes more apparent it is too early to say what the impact on IT budgets will be. Industry analysts Gartner and International Data Corp. (IDC) are forecasting a relatively small decline in IT spending of about 5% for the year once the economy begins to recover in the second half. However, it’s clear that certain vertical industry segments, such as travel and hospitality, might have a much longer way to go than, say, healthcare companies.

    In addition, it’s likely that much smaller companies than those surveyed by OpsRamp may find it more challenging to restart operations after being forced to lay most of their employees in some cases.

    Whatever the timing, the one probable thing is many of the IT trends that were just beginning to gain traction are likely to see accelerated adoption once the economy recovers. There will be a natural tendency to limit the adoption of new platforms and processes in the short term. However, now that it’s clear existing platforms and processes are not especially flexible it’s only a matter of time now before most of them one way or will be replaced or at the very least completely modernized.

  • Castles in the Cloud: How to Take Your Business Kingdom Off-Prem with Confidence

    Castles in the Cloud: How to Take Your Business Kingdom Off-Prem with Confidence

    Cloud transformation requires migrating all or part of an organization’s virtual assets off-premises, typically to a public cloud.  This enables greater efficiency and cost savings, among other benefits, but it brings heightened risk as well. At the same time, many organizations moving to the cloud don’t fully understand the implications in terms of security. Consequently, successful cloud migration requires a shift in mindset.

    A Medieval Metaphor for Cloud Infrastructure

    Think of your organization as a kingdom surrounded and protected by a castle. Traditionally, this castle would be outfitted with defensive layers designed to protect the residents, the royal family and the possessions within. Protection of the castle is straightforward. A moat surrounds the castle with drop bridges in and out at strategic points (firewalls).

    In addition, guards are stationed at each entry point, conducting a thorough inspection of the people, carts and the content that they carry both in and out of the castle (IDS/IPS). The guards also check credentials at the gates and within the castle to ensure patrons are cleared for access and use of rooms and resources (IAM). The perimeter and interior walls are continuously checked for weaknesses that could introduce potential blind spots that are unguarded (vulnerability management).

    The castle has a variety of rooms, each with its own function, content and worth. Each door has a lock (AV). Within each room and the correlative hallways exist guards who check credentials, monitor the people who enter and the contents they carry, etc. (behavioral detection and endpoints). In addition, multiple other measures are in place that bolster prevention, detection and response capabilities (DLP, deception, etc.). Information from all of these sources is noted in a central location by a scribe. Guards analyze the information, looking for additional indicators of potential threats to the kingdom (SIEM) and respond accordingly.

    Comprehensively, protection of the kingdom requires an overall model and policies that accounts for new threats and tactics from rival kingdoms and thieves. Architecture of security measures are continuously updated and adaptable. In the event of an incident, the guards have designed and exercised a plan to respond. 

    Understanding the Three Different Models of Cloud 

    Clearly, this is a basic metaphor for the on-prem approach. Moving to the cloud introduces a new level of complexity to protection spread across three different models: Infrastructure as a service (IaaS), Platform as a service (PaaS) or Software as a service (SaaS).

    In the context of our castle analogy, let’s assume the castle has reached productive capacity. Neighboring rivals are creating competitive pressures, offering residents (who pay taxes) the possibility of a better life if they relocate. To keep residents happy, productivity requires expansion beyond castle walls. As production expands, neighboring kingdoms offer different models to achieve productivity. However, each model presents different levels of shared responsibility in protection (referred to as the Shared Responsibility Model).

    • IaaS: In this model, the on-premises kingdom (kingdom A) decides to expand all operations to a neighboring castle (kingdom B). The castle itself and the moats are all controlled and provided by kingdom B. However, the infrastructure, moats, hallways, rooms, access lists, monitoring of activity and protection and usage of its contents are the responsibility of kingdom A.
    • SaaS: Kingdom A decides to have blacksmithing conducted in a neighboring castle (kingdom B). The castle itself, the moats, infrastructure, hallways and blacksmithing room are all protected by kingdom B for a charge. Kingdom B’s responsibility is to control access to the room, but maintaining who’s on the access list to the room and the protection of its contents and usage are the responsibility of kingdom A.
    • PaaS: Kingdom A decides to house and build military operations in a neighboring castle (kingdom B). Kingdom B is responsible for the basic controls, but the configuration and monitoring remain the responsibility of Kingdom A.

    With this transformation, Kingdom A faces a more complex security landscape. Innovation and efficiency are critical to meeting the growing and changing demands of their kingdom, but not without additional risks. New operating models bring new risks and potential vulnerabilities to their system(s). Methodologies and processes used to secure their own kingdom do not necessarily work or apply to protecting their new partner kingdoms. Additionally, people–and experience–that understand these new complexities are harder to come by while the thieves and rival kingdoms discover vulnerabilities and weaknesses and begin to exploit and steal valuables that put the entire kingdom and its residents at risk.

    Protecting Your Castle in the Cloud Takes a Deep Understanding

    Moving to the cloud is almost inevitable at this point, and it carries so much potential to accelerate business outcomes. It takes a different mindset to secure it than what we are used to as an industry–the landscape has been changed from a security perspective. By fully studying and understanding the differences, organizations can continue rapid and secure adoption of the cloud, while reaping the benefits that it promises to bring.

    — Sean Blenkhorn

  • The Disservice of Cloud Consolidation

    The Disservice of Cloud Consolidation

    There’s no secret that over the past five years especially, the major (“tier 1”) cloud infrastructure players—Amazon, Microsoft and Google—have been snatching up smaller specialty providers, particularly cloud migration and security services.

    While this acquisition strategy immediately aims to strengthen and expand the provider’s direct and tangential cloud infrastructure offerings, the long-term goal is customer attraction and retention.

    In consolidating cloud infrastructure and related services, cloud vendors are targeting a basic human desire that often bleeds over into business decisions: convenience.

    • “Finding a cloud provider seems hard.”
    • “Switching to the cloud seems hard.”
    • “Managing more than one cloud seems hard.”
    • “Keeping up with more than one vendor seems hard.”

    The play is transparent; the marketing is already in your psyche. People don’t like doing more than they have to, whenever possible. So, why not apply that tick to the cloud infrastructure experience? Why not use a provider where everything is already in one place?

    Truthfully, the move toward cloud consolidation is a step in the opposite direction from where we should be going. The future lies in a multi-cloud approach, not a consolidated one.

    Multi-cloud approaches offer both businesses and their customers several advantages over consolidated infrastructure.

    • When a business’ cloud infrastructure exists solely with one provider, every cloud-related business activity—and every customer interaction with those activities—is beholden to the provider. A provider outage is a business-wide outage, and a business-wide outage is unacceptable.
    • Multi-cloud approaches allow businesses to take advantage of best-of-breed cloud infrastructure. A business can implement databases, containers and other virtual infrastructure in a more highly optimized way.
    • Data held in disparate systems can be better partitioned and more secure than data stored with a single provider. Also, these disparate systems can bolster adherence to existing (and likely coming) data privacy laws and compliance regulations both nationally and internationally.
    • Utilizing cloud infrastructure housed physically closer to a business or its key users can drastically influence business activities in industries where parts of seconds count (e.g., finance).

    Aside from the standard reasoning, I’d argue that there’s additional economic health in taking a multi-cloud approach. Competition naturally drives innovation, stabilizes costs and encourages improvement. Where one provider may falter, three others might specialize. If the majority of businesses consolidate their cloud resources with a single provider, though, the likelihood increases of services gradually worsening with no alternatives toward which to turn.

    Multi-cloud takes planning and coordination to properly implement, and careful monitoring to maintain. An additional tool or two, such as a cloud management platform or cloud integration solution (which, truthfully, many businesses are likely already utilizing), may be needed.

    But, the benefits far exceed the challenges. After all—to call upon Ken Jenkins’ iconic chief of medicine, Bob Kelso—nothing worth having comes easy.

    — Zack Busch

  • HPE Extends Hybrid Cloud Computing Strategy

    HPE Extends Hybrid Cloud Computing Strategy

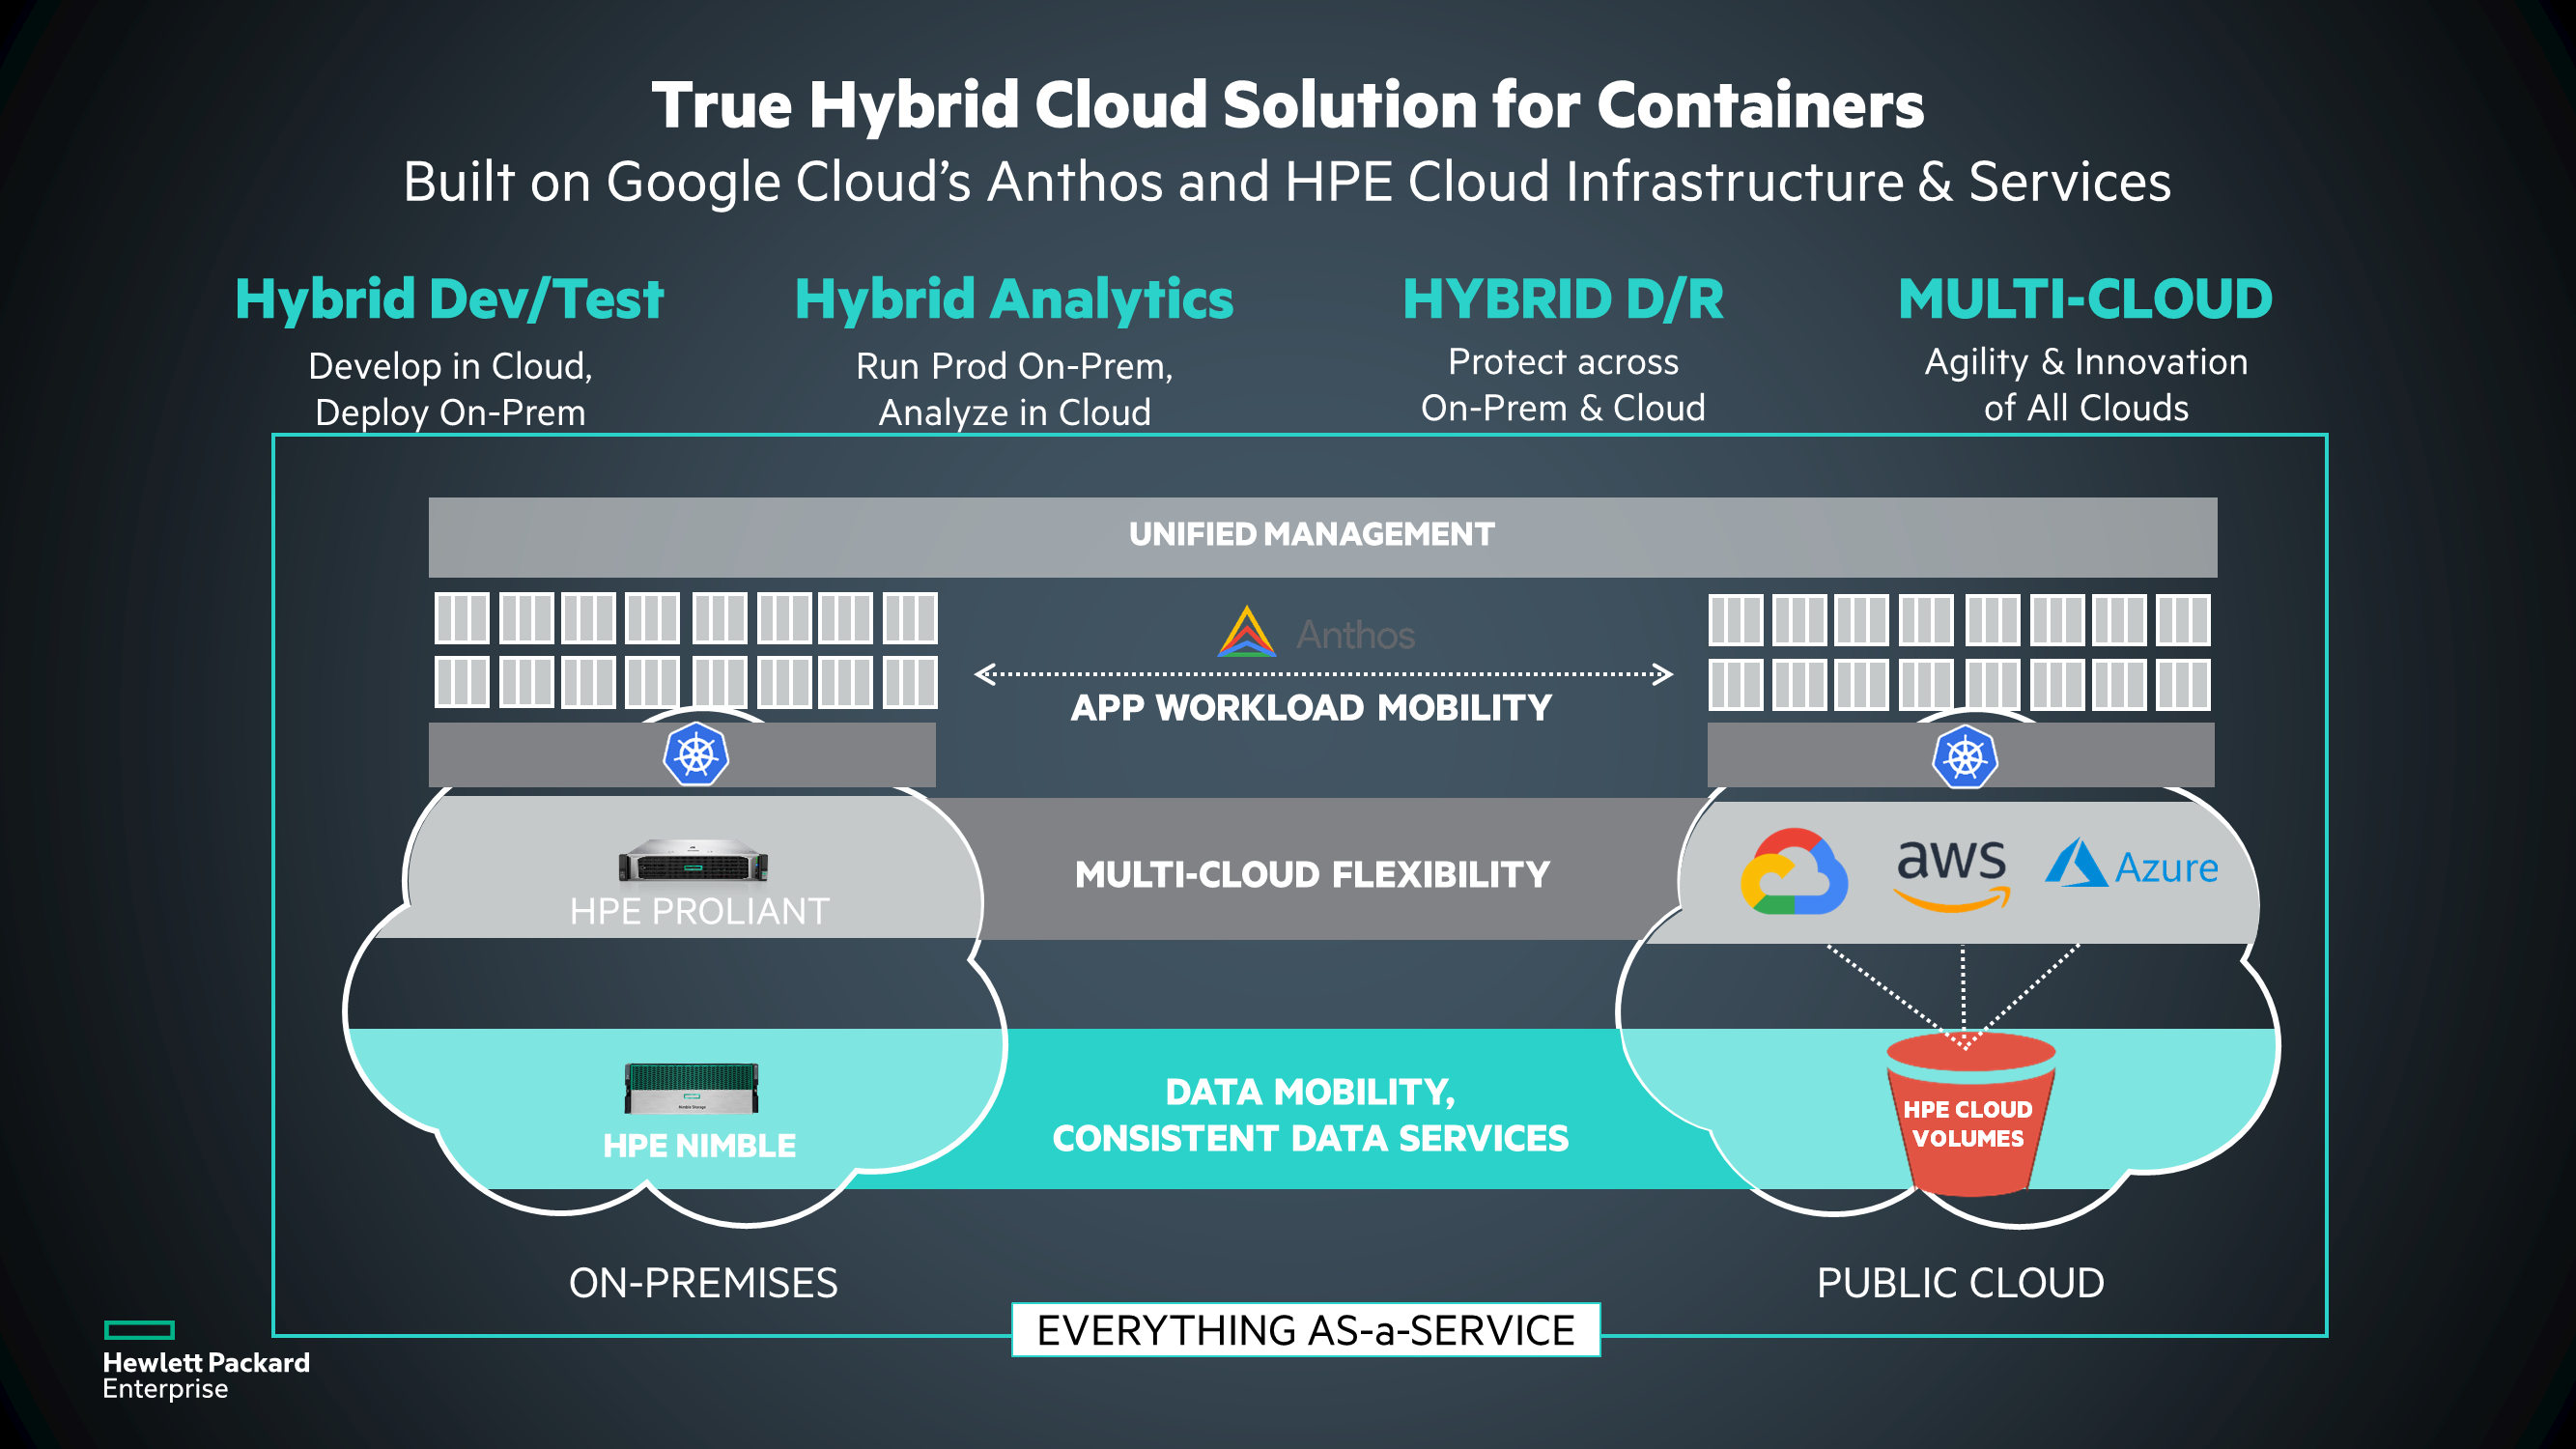
    Hewlett-Packard Enterprise (HPE) today advanced its hybrid cloud computing strategy by announcing at its HPE Discover 2019 conference an alliance with Google to embrace Kubernetes in hybrid cloud computing environments and then extending the reach of its software-defined infrastructure for building private clouds to legacy ProLiant servers.

    Lauren Whitehouse, director of marketing for the software-defined and cloud group at HPE, said the HPE Composable Cloud now extends beyond new ProLiant servers to include everything from legacy hardware to cloud computing platforms running virtual machines or as bare metal servers optimized for Kubernetes.

    To achieve that latter goal, HPE will make it possible to deploy Google Anthos, a previously announced framework for delivering cloud-native computing services across public clouds and on-premises IT environments, on HPE-managed platforms.

    HPE is giving customers the option of deploying configuring local servers with virtual machines with either a VMware vSAN storage software or the HPE SimpliVity hyperconverged infrastructure platform. Additionally, customers can choose to deploy Kubernetes on those platforms or run Kubernetes on a bare-metal server. On top of those stacks, HPE also embeds the HPE OneView IT infrastructure management and HPE Composable Fabric networking solution to create what the company calls a composable rack environment.

    Finally, HPE announced it will extend the reach of the HPE InfoSight artificial intelligence engine, which it gained for storage environments when it acquired Nimble Storage, to the rest of its data center portfolio.

    Whitehouse said that, by extending the reach of its composable computing strategy to include legacy servers, HPE seeks to make it easier to modernize on-premises IT environments within the context of a larger hybrid cloud computing strategy.

    One of the primary reasons so many workloads are being deployed in the cloud is because of the inherent flexibility of the IT environment. HPE is investing in higher levels of infrastructure abstractions to enable an equivalent amount of agility to be injected into on-premises IT environments. Those efforts will then make it easier for organizations to extend best DevOps practices across a hybrid cloud computing environment, said Whitehouse. The company is now removing the objection by organizations to have to implement a forklift upgrade across their entire on-premises IT environment to achieve that goal, she added.

    It’s not immediately clear who will manage what in this brave new world of hybrid cloud computing. Application developers have been exercising a lot more influence over platforms, while advances in automation appear to be heralding a consolidation of management functions within the local data center. As site reliability engineers, or so-called “super administrators” capable of managing compute, storage and networking infrastructure continue to emerge, the silos around job functions in the enterprise were built are breaking down. In fact, the more organizations embrace DevOps best practices, the faster consolidation of job functions is occurring.

    In the meantime, whoever provides the infrastructure that remains in an on-premises IT environment had better be able to enable local IT teams to be just as flexible as any cloud service provider an application developer is likely to encounter.

    — Mike Vizard

  • DevOps and Networking: Working to Achieve Nirvana

    DevOps and Networking: Working to Achieve Nirvana

    Enterprises don’t own the cloud, just the experience. If there’s an outage or even a hiccup in the performance or network service, it’s on the network and application teams (not the cloud provider) to fix it. But often with problems in the cloud comes finger-pointing, as network and application teams look to determine liability and responsibility when it comes down to crisis situations.

    There is no question that applications are growing more complex, as is the infrastructure to power those applications. According to the 2019 “Stack Overflow Developers Survey,” comparing year to year the amount of time it takes for software engineers to become effective on teams is increasing. This trend could be, in part, due to the amount of tooling and rise of an operate-what-you-build model (e.g., the dawn of the full lifecycle developer). As our applications become more distributed—and to cope with scaling and availability demands—skill sets that traditionally were infrastructure and development-based have begun to blur.

    Networking Shifting Left

    Networking-centric capabilities such as service meshes (e.g., Istio and Linkerd) and container networking interfaces (e.g., Calico and WeaveNet) are gaining a lot of traction and visibility in the cloud-native application development world. Though SDN infrastructure has been shifting left toward development pipelines, application development teams are learning networking concepts. However, the core networking infrastructure is still maintained by the networking teams.

    This paradigm of software-defined infrastructure is creating a learning curve for multiple teams. With the dawn of NetOps, software development lifecycle (SDLC) principles are being introduced to the networking teams. Traditionally, ticket- or service-driven networking teams can participate in iterations and they are now building the next generation of cloud-agnostic networking capabilities. With NetOps, there is more interaction and innovation. But change is not without resistance; the dynamic nature of modern infrastructure and the short-lived nature of pre-emptible/ephemeral infrastructure do not bode well for static networking rules.

    Networking Team Pressures Today

    With infrastructure headed to the trifecta of clustering, replication and load balancing, networking teams have to deal with many more dynamic addresses than before. Static ports and addresses that used to be loaded into networking tickets are now being replaced with wide ranges and service addresses powering the networking stack of our cloud-native and containerized workloads. Adding to the complexity, the networking team is leveraging public cloud infrastructure. The infrastructure that the networking teams are responsible for is leaving the data center and distributed web infrastructure technologies, such as distributed domain name systems (DNS) and content delivery networks (CDNs), are common for the networking teams to be involved with. Like the application development teams, the amount of new technology hitting the networking teams is increasing.

    One of the great advantages of using public cloud infrastructure is the ability to quickly expand or contract available resources. With this ability, we can spin up and down test environments to try out changes and even the infrastructure level that was not even possible. With this, we have the ability to integrate more. The application development team, which has been iterating for some time, now has common ground with the networking team to try out iterations.

    All in a CIDR

    To illustrate the needed collaboration between networking and application teams, let’s look at an example:

    In one of the biggest incidents of my career, my company was migrating pieces of our platform to a public cloud vendor. Because the organization was early on in this transformation, a lot of minutiae was yet to be flushed out. We were packaging classless inter-domain routing (CIDR) calculations into our first-time VPC configurations—a task the development team was responsible for at the onset of our cloud migration. It was my job to enter this for my service. Instead of a /8 CIDR, I implemented a /16 CIDR. A seemingly small miscalculation on several configs turned into an incident, blocking a majority of traffic hitting the service. The mistake was quickly corrected, but the incident response framework was well on its way to being executed.

    So, who was responsible? I was the one who created the configuration and pushed to production, so this was my fault. But in retrospect, the best solution would have been to involve the networking team immediately in these types of changes. Because the application development teams were vanguarding into the public cloud, however, we cut out the networking team. This was an organizational problem that needed to be addressed. If we were going to deploy into a data center successfully, the networking teams needed to look over my requests and catch my CIDR error.

    Silver Lining, Right?

    During this CIDR incident, I was trying to look at the silver lining: Since we can’t access our application, that means the instances/app must have a lot of extra capacity, right? Untimely, yes, but the analogy did make sense with the silver lining. We were getting billed by a public cloud vendor and because there was a drop in usage, our bill technically should have been lower. But it still impacted the customer. The money saved in our incident was outweighed by external measures (revenue and brand damage). A cloud outage and a subsequent dip in digital experience can have a massive impact on revenue, averaging $38,855 per hour of outage. During high impact or busier times, this number can be much more.

    DevNetOps Nirvana

    The adage of bringing everyone to the table early proves to be valuable. Each team in an organization can have a strategic impact and improve architecture in multiple parts of the stack. Different teams have different sets of skills and can have mutual respect for the vertical skills of each of the teams. In the end, a transparent and positive relationship between network and application teams will help with network remediation and outage prevention. And, the closer the teams can work together and the more they can communicate, the more their investments and efforts can contribute to the business bottom line and quicker remediation long term.

    — Ravi Lachhman

  • DevOps Chat: Serverless and Abstraction with Nimbella’s Anshu Agarwal

    DevOps Chat: Serverless and Abstraction with Nimbella’s Anshu Agarwal

    Anshu Agarwal has a tremendous record of working in startups that had successful exits. Now for the first time, along with her co-founders, she is actually founding the startup herself. Nimbella is a serverless platform that is cloud-agnostic and makes developing and deploying applications easy. Whether in a public cloud, private data center or both, Nimbella can help.

    In this DevOps Chat, we speak with Anshu about her own personal journey and where Nimbella is and what the plans are for going forward.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.

    Transcript

    Alan Shimel: Hello, everyone, it’s Alan Shimel of staging-devopsy.kinsta.cloud and you’re listening to another DevOps Chat. Today’s chat actually features a company that’s just starting out here, but it’s a guest who’s had a rather long career in the tech space. As long as mine, even, at some point, but I’m sure I’m much older. Anyway, I’d like to introduce you to Anshu Agarwal. And, Anshu, if I messed up your last name, I apologize. Was that good?

    Anshu Agarwal: Thank you, Alan. You said it perfectly right. Thank you for having me today.

    Shimel: Thank you. So, Anshu, let’s start off – I referenced that you’d been in tech a while. Let’s give people an idea of your personal journey that brings you here today, even going back to Speedera and beyond, if you’d like, but if you wanna start with Speedera, that’s fine. But let’s give folks an idea of who you are, what your background is.

    Agarwal: Sure. Thank you. So I am an engineer by background and I moved into product management and marketing after I finished my MBA. And, after that, I joined a startup and then the startup bug never left me. So I joined Speedera, which got acquired by Akamai. Then I joined another startup, Ankeena, which got acquired by Juniper. Another startup, ConteXtream, got acquired by HP. And my most recent startup, Cedexis got acquired by Citrix, so I have been acquired four times. And, in all of those companies, I kind of delivered the success for other people’s ideas because they were all successful startups, got acquired by very, very large companies, so they were indeed – from value standards, they’re considered successful, but, for myself, I had never really done a company of my own.

    So, when I got the opportunity of just starting and being a founder of a cloud infrastructure, because that’s my background – I’ve been doing cloud infrastructure for last 15 to 20 years – there was no question that I wouldn’t do it. And we got started on this company – the company name is “Nimbella.” And it is in the serverless framework or serverless platform space. And we are kind of disrupting what serverless is, so – or we are providing what serverless promises to the developers. So that’s what we are working on now.

    Shimel: Excellent. You know, you’re way too modest and humble because, for many people listening, whether they’re in the valley or Boulder or Austin or New York or Boston or London or Bangalore or anywhere else in this world, having four startups that were acquired by companies like Akamai, HP, Citrix, and I forgot the fourth one – I apologize – a lot of people would call that a career. Right? I mean, whether they founded the companies or not, just being associated with four companies that had successful exits to large companies like that is something to be proud of and it speaks volumes as to either you’re really, really lucky or you’re doing something right. Right? So congratulations to you for that.

    So you’ve mentioned Nimbella and I wanna kind of share with our audience up front that Nimbella is – you have raised some funds for the company and there’s a great startup – there’s a great founders group involved. You mentioned, I think, one of your cohorts from Speedera; I think there’s two other founders in the group. But the company’s sorta still – I don’t wanna say stealth, but pre-product, let’s call it. Pre-public-product. So I don’t wanna put you on the spot. I’d rather talk, I think, if it’s okay, Anshu, about some of the problems you see and potential solutions that we see.

    You know, we live in a great time for developers and engineers. Internet time, right? We’ve gone from servers to hypervisors to containers. Now serverless. And serverless seems to be all the rage, but, like any new technology, it’s not birthed mature, right? It doesn’t come out mature; it doesn’t start mature. And so there’s gonna be growing pains. Can you share with our audience a little bit about what you see as some of the growing pains around serverless or what you’re hearing from people around that?

    Agarwal: Absolutely. Well, thank you for – this is a great question because it is definitely the best thing that’s happening for developers. The reason I say that is because what developers really want is to develop their business logic or develop the code and not worry about the infrastructure. And serverless promise is all about that, that you don’t have to worry about the infrastructure. You don’t ever have to worry about how it scales, how it is secured. Anything that requires the knowledge of infrastructure should not be a developer’s worry.

    But, in today’s serverless frameworks – and there are a few serverless frameworks and some are very popular ones – there is so much complexity still for the developers because they have to combine many services. And, for instance, they have to think about storage, they have to think about identity management, and they have to learn all these services and integrate. Not only that, the management and debugging is still an issue. And these are growing pains, as you mentioned. The serverless computing is still in a nascent stage and, therefore, it’s lacking all the abstractions that are needed for the adoption to accelerate into new markets and application domains.

    Not only that, serverless today, if you look at it, is used only for stateless applications, so you’ll see it in IoT applications, you’ll see it in reactive kind of applications only. It is not suited for long-running or stateful workloads. The reason being is because serverless today is serverless compute; it is not serverless storage. So that’s another problem. We may consider it as a problem or we may consider it as the limited adoption of the technology, but that’s something we have to address if we want this to be adopted in general, across all workloads. Then the –

    Shimel: I’m sorry. We may also consider it as an opportunity, right? I mean –

    Agarwal: Oh, absolutely.

    Shimel: Yeah.

    Agarwal: Absolutely. And that’s what we’re doing. And I’m gonna talk about Nimbella and how Nimbella is addressing it.

    Shimel: Mm-hmm.

    Agarwal: Another important aspect of serverless today is, like any new technology environment, there is serious vendor lock-in because, if you are using AWS’s Lambda serverless framework, you are programming to the nuts and bolts of Lambda. If you are using Google, you are programming to GCP, and so it is with Microsoft Azure. So, in a sense, you are programming to proprietary frameworks and, therefore, your code is not cloud-portable.

    So, tomorrow, if your company decides that, “Now we are going to move from AWS to Google,” you gotta rewrite the whole thing again. So that is actually, again, the serverless promise, and, therefore, vendor lock-in is very real, especially for the companies, actually, that choose not to go to public cloud because they’re part of regulated industry or whatever _____. They want something to be running in their own private cloud; these serverless frameworks are not an option for them. And then, say, you were able to write code for all different frameworks, but then the complexity of operations is there because you can’t monitor and observe at each level since these are proprietary frameworks across these clouds.

    So there are serious issues for widespread adoption and that’s where we come in. That’s the opportunity we looked at when we decided to create this company, is we want to create a platform, a framework, that is providing all the necessary abstractions so the developer is not to worry about how the infrastructure works, how to scale the code, how to secure the code. The code is just nebulous logic that they write. Then it is also suited for long-running, stateful, streaming workloads, such as AI/ML workloads. I mean, we have a greater adoption of AI happening in every industry. If we are not going to be able to handle AI workloads, we are missing a big market.

    And those are real, real problems and we are addressing it with Nimbella, you know, the technical problems. Then there are operational issues where you want cloud portability, so we are also addressing that part because we are providing a layer of abstraction and it’s open-core-based, so a developer can program the way they program the business logic and not worry about which cloud they’re writing.

    Shimel: Got it. Got it, got it, got it. So, again, I don’t wanna be uncomfortable or make you uncomfortable with what we’re gonna talk about, but, you know, I was at KubeCon out in Seattle last month – seems like a year ago, but it was only last month – and, surprisingly or not surprisingly, “serverless” seemed to be on everyone’s lips. Right? And maybe some people listening to this are saying, “Wait a second, Kubernetes is for containers and containers can run on bare metal, yeah, but they run on VMware or hypervisor as well.” What do you think the role of Kubernetes is in the serverless future? Fair?

    Agarwal: Kubernetes is a great technology. I really think it has great future. And serverless frameworks use Kubernetes or something else like that. And we were also at KubeCon. It was actually our first conference as an Nimbella person attending – one of my cofounders, who actually is the creator of OpenWhisk Apache, a serverless framework, he attended it. And he mentioned the same thing that you mentioned, that serverless was on everybody’s slide deck. Okay? It is something everybody is looking at; it is something everybody is kind of they have it on their roadmap, that they wanna work on it. They wanna look at it and see if it works for their environment.

    And Kubernetes is perfect, actually. It provides the platform needed because it is widely accepted these days and it provides the necessary environment, but, again, it should not be the burden of a developer to know how to run, work with Kubernetes. It should be the infrastructure serverless framework that provides that to the developer and the developer’s still only programming the logic. It’s not for the developer to worry on what environment, what container environment they are working on and what VMs are being used and what bare metal is being used. That’s all abstracted away for the developer.

    Shimel: Got it. Got it, got it, got it. So, you know, I’m sure there are people listening to us today who are thinking to themselves, “This woman has been in four startups and has had tremendous success.” And now I’m sure you’re a CEO, right, of Nimbella and you’re cofounder –

    Agarwal: That is correct.

    Shimel: Right? And I’m hoping there’s a whole bunch of women engineers out here or women entrepreneurs who are listening to you, saying, “Hey, if she can do it, I can do it.” And we don’t have a lot of time left, but I wanna address those folks there, that are near and dear to me for a lot of reasons. What’s your advice to them?

    Agarwal: Absolutely. If I can do it, they can do it. That is a very true statement. And, I mean, you said some great words about me, but I consider myself average successful person and, yes, I have been lucky that the four companies I’ve worked for had great exits. But being a founder and CEO is still very different from what I did for the other companies before. So, basically, when you are part of the company, other companies, you’re not bothered by operational aspects of the company. You’re not bothered by hiring for every possible function in the company. So the skill sets that I’m developing now, there is no other experience that could have taught me that, so, even though – I say, “Everybody can do it and anybody can do it,” but they still have to learn the art of running a company on the job. It just – there is no course. There is no education that can be given because you have to experience it.

    So, to all the women engineers that are listening, I would say, “If I can do it, you can do it. You just have to just get into it. You just have to dive into it and it will come to you. You will develop your advisors. You will develop the people who help you on the way because you won’t have all the skill sets, but you will know who to go to for what skill set, as you take that role.”

    Shimel: Absolutely. Absolutely. And, you know, women or not women, entrepreneurs – I’ve also founded and helped start my fair share of companies – I don’t know if it’s courage or just pure moxie, if you will, right? You just put one foot in front of the other, right, and you just keep moving forward. And you can’t boil the ocean, right, but you can – these things are incremental, right, and they’re evolutionary. They’re not _____ –

    Agarwal: Absolutely. You’re absolutely right. These are such an incremental thing and you may be not finding the best solution, but you are optimizing your solution, at every step, because you’re trying to handle so many things and, if you wait for the best solution to arrive, it may be too late. So you’re kind of optimizing the solution for whatever issue or whatever problem you’re handling, and you move on with that. And it’s just only time will tell how successful I am in the role, but this is my experience six months into this company, six or seven months into this company, and I’m still learning the art.

    Shimel: Absolutely, it is. So what do you – short-term future, where can we find out more on Nimbella or when will we find out more, do you think?

    Agarwal: Oh, absolutely. So there is some information on the website – very little information, I would say – but it gives you a flavor of what we are doing. Then, in Q1, this quarter, we are going to be releasing our developer playground, which is actually – because the buyer of serverless technology is the developer and developer experience is the most important thing, a developer has to feel one with the programming experience. And that’s the true serverless promise and we wanna deliver on that promise, so, in Q1, we are going to release that.

    And, in later quarter, in Q2, since I have mentioned private cloud and hybrid cloud, there will be offering for private cloud in Q2. So, as this quarter progresses, we are going to populate the website more with the content and we’re going to host more meetings like this and make it available to the developer community in general, our solution, and then, later on, for enterprise sites.

    Shimel: Great. Great, great, great. Anshu, when I started, I said, “These are only about 15 minutes. It’s gonna go so quick, you won’t believe it.” If I told you we’re closer to 20 minutes already, you’d probably say, “Oh, my,” but we are and we’re gonna need to call an end to this DevOps Chat. You know what? It sounds like there’s a lot going on here and, if we can have you back on, you know –

    Agarwal: Oh, that would be great, Alan. I really hope we can –

    Shimel: Yeah?

    Agarwal: I really hope we can get back when we have our developer playground because I’d love to talk more about it.

    Shimel: I promise you we will.

    Agarwal: Thank you.

    Shimel: Promise you we will. Thank you. Anshu Agarwal, founder/CEO of Nimbella, our guest here on this DevOps Chat. This is Alan Shimel and you’ve just listened to another chat.

    — Alan Shimel