Tag: iterative

  • Iterative Adds Registry to GitOps Portfolio for ML Models

    Iterative Adds Registry to GitOps Portfolio for ML Models

    Iterative added a registry for machine learning models to its portfolio of Git-based tools for infusing artificial intelligence into applications.

    Iterative CEO Dmitry Petrov said the Iterative Studio Model Registry is intended to make it easier for application development teams to track which models are being used as the number of applications infused with AI capabilities continues to grow.

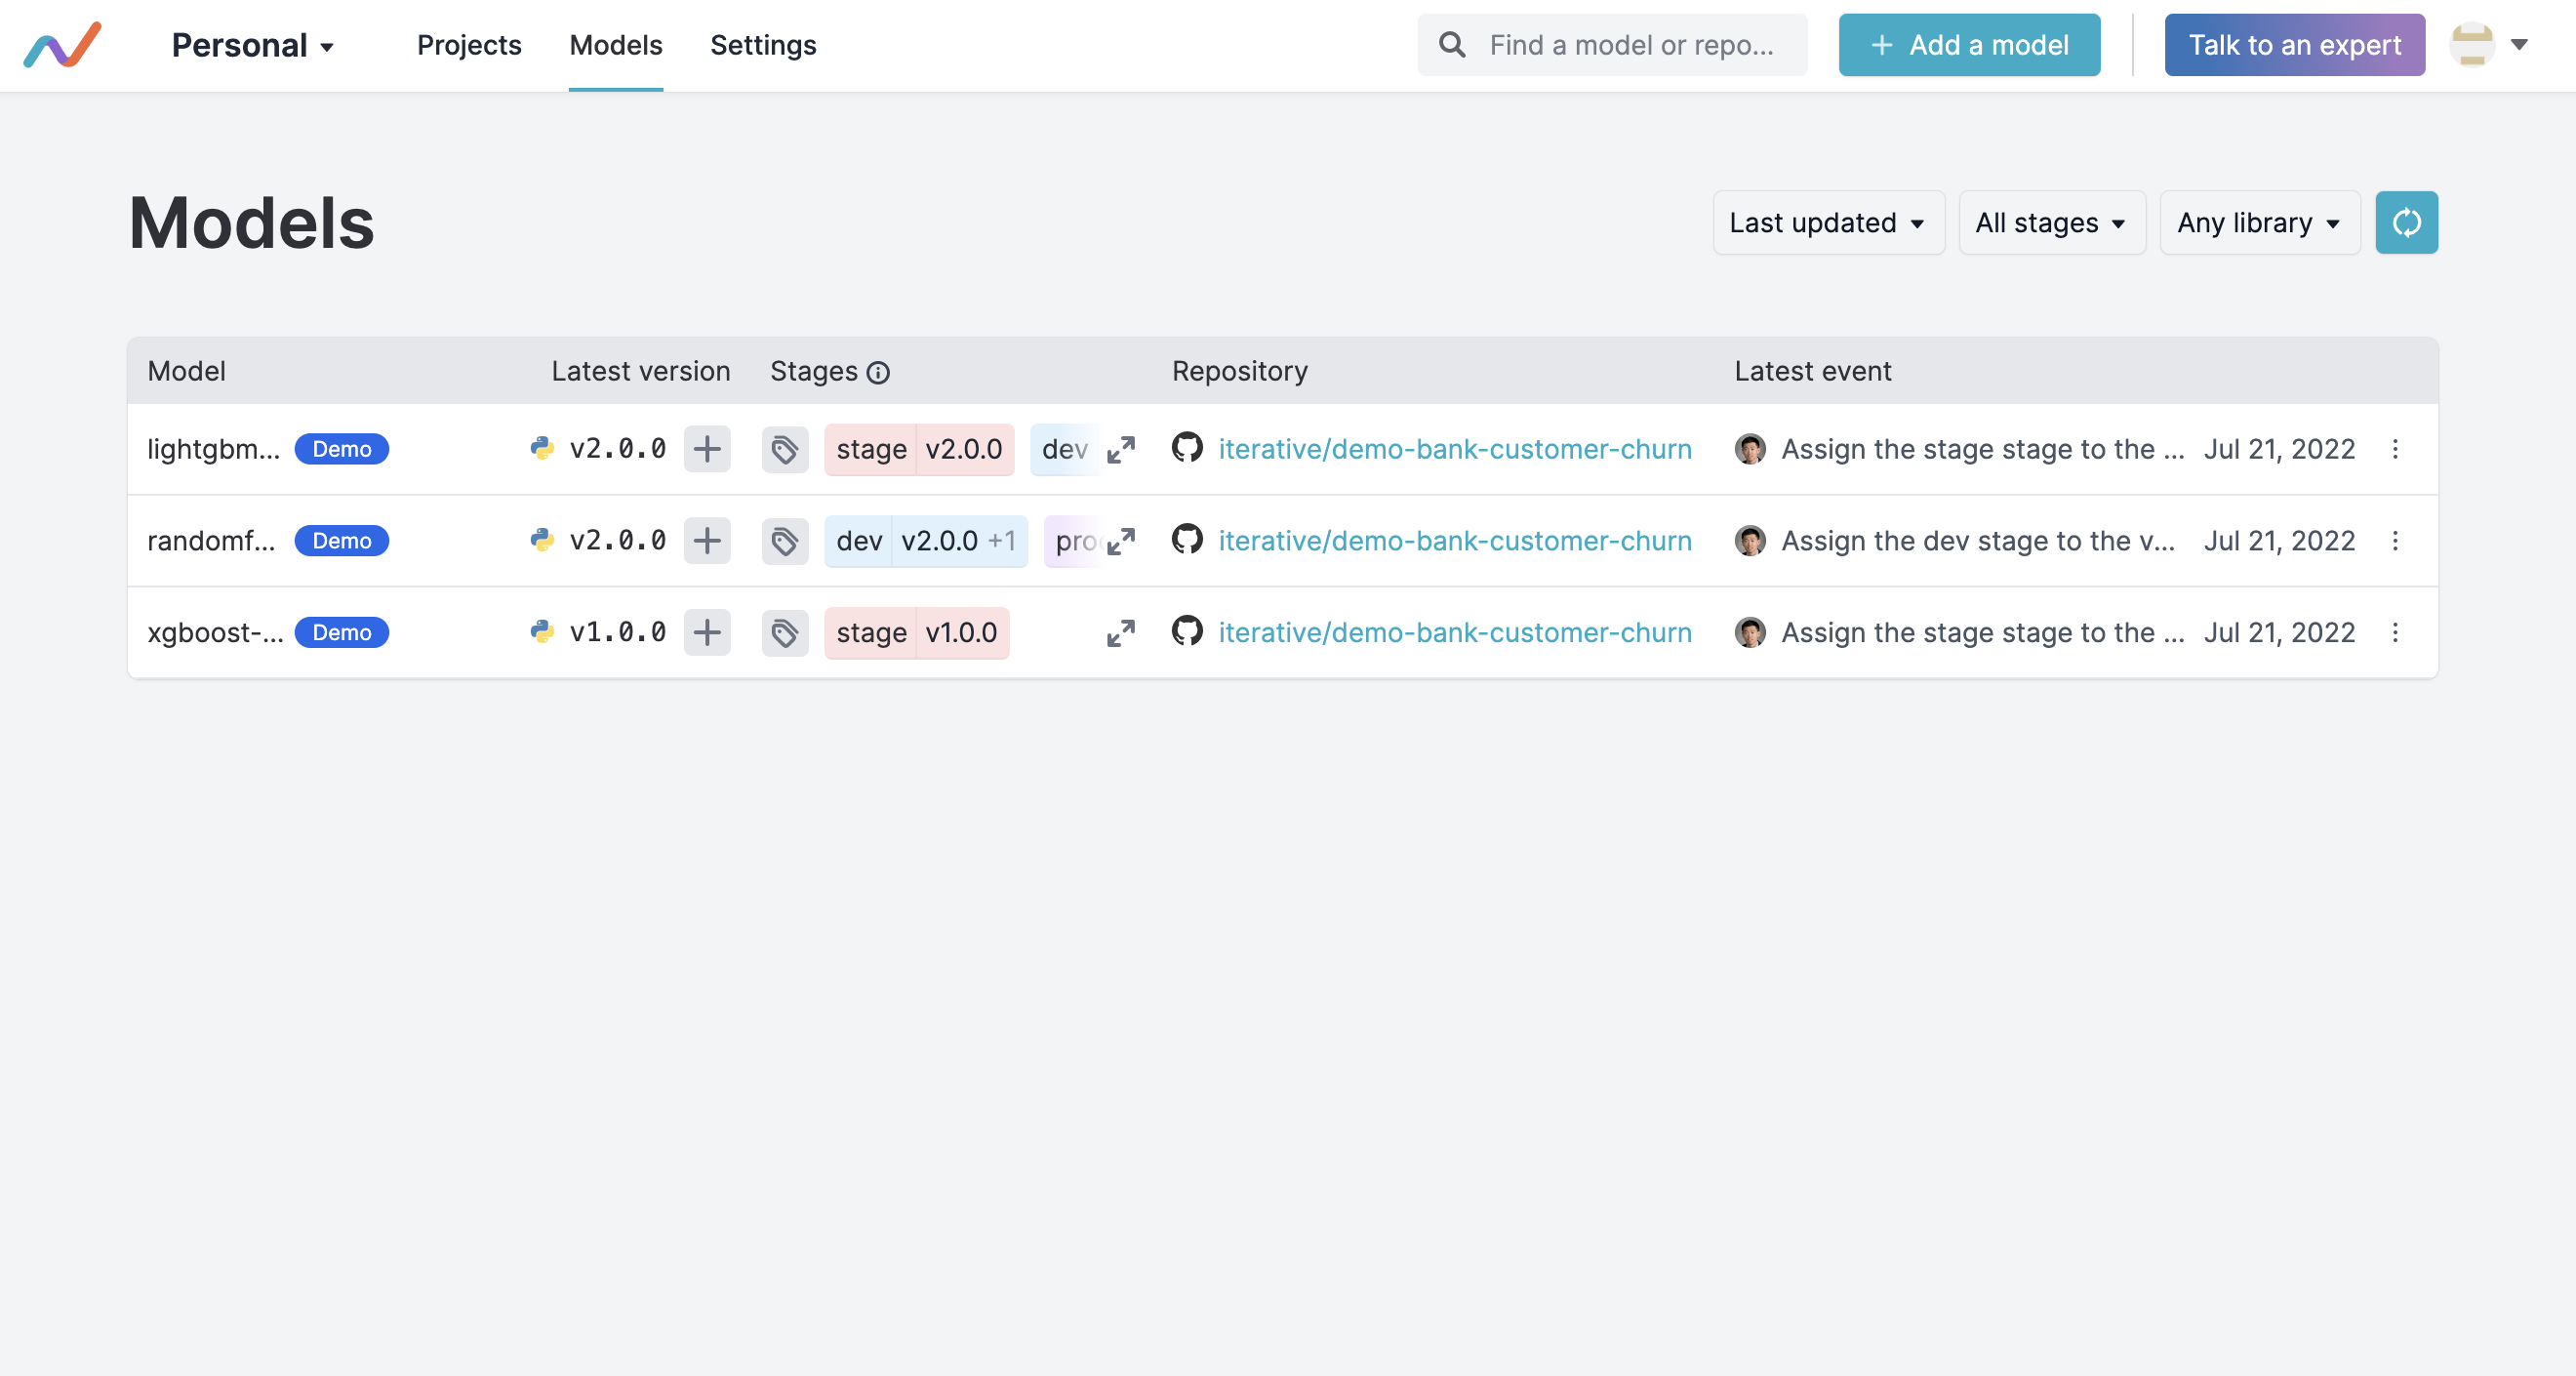
    The Iterative Studio Model Registry, accessible via a graphical interface, command line interface or application programming interface (API), makes it simpler to explore models, including history, versions and stages, via a central dashboard. Teams can also identify the experiment that produced the model and track how, when and by whom a model version was created.

    The Data Versioning Control (DVC) platform created by Iterative exposed a Git-like interface to enable organizations to track multiple versions of data sets, models and pipelines across a machine learning operations (MLOps) workflow. That approach enables those models to be stored in a Git repository alongside other software artifacts versus requiring organizations to deploy a separate platform just to store ML models.

    Providers of platforms used by data science teams have been making a case for separate repositories for tracking the artifacts used to construct an AI model. Iterative contends it is more efficient to employ Git repositories where other types of software artifacts are already being stored because, after all, an ML model is just another type of software artifact.

    That approach also makes it simpler for DevOps and data science teams to collaborate because the DevOps team will have more visibility into what AI models will eventually need to be incorporated into an application, noted Petrov.

    The challenge organizations face is the cultural divide between data science and application development teams. Data science teams today typically have defined their own workflow processes using a wide range of graphical tools. However, as it becomes obvious that almost every application is going to be infused with machine learning and deep learning algorithms to some degree, the need to bridge the current divide between DevOps and data science teams will become more acute.

    In fact, DevOps teams should assume that many more AI models are not only on the way but that those models will need to be continuously updated. Each AI model is constructed based on a set of assumptions; however, as more data becomes available, AI models are subject to drift that results in less accuracy over time. Organizations may even determine that an entire AI model needs to be replaced because the business conditions on which assumptions were made are no longer valid. One way or another, the updating and tuning of AI models are likely to soon become just another continuous process being managed via a DevOps workflow.

    No IT organization can, of course, manage what it can’t track. Registries have become an essential component of a DevOps workflow as the volume of types of artifacts that make up application environments has increased. It remains to be seen to what degree ML models become just another software artifact but one way or another someone in the IT organization needs to know what model is being employed in which application for what purpose.

  • Iterative Adds Experiment Versioning to MLOps Platform

    Iterative Adds Experiment Versioning to MLOps Platform

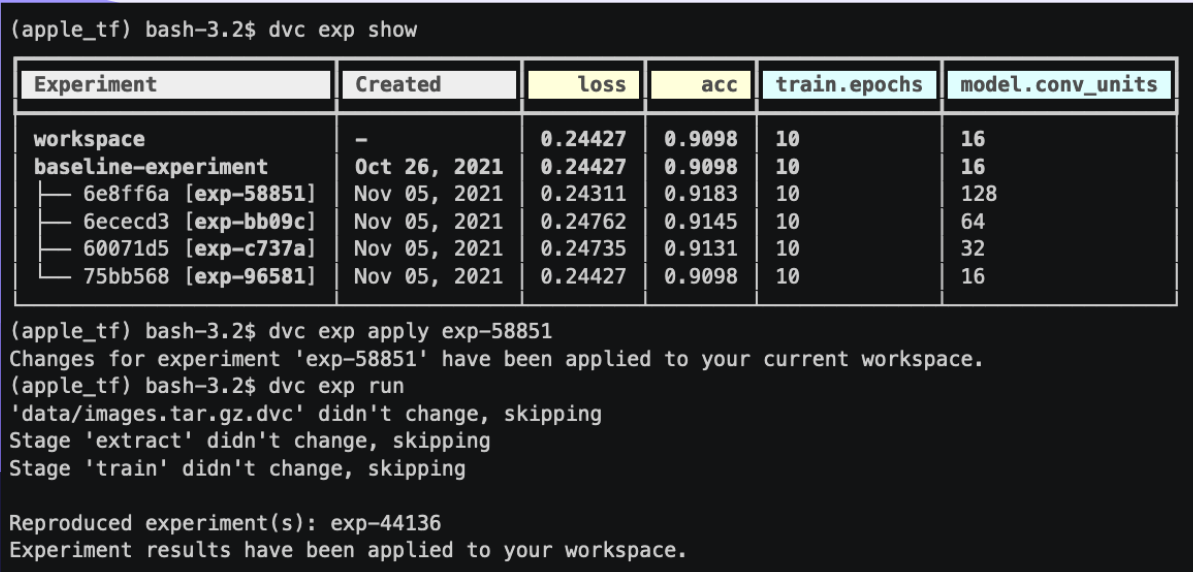
    Iterative today added an experiment versioning capability to an open source platform for managing machine learning operations (MLOps) using GitOps workflows.

    Dmitry Petrov, Iterative CEO, said the latest version of the Data Versioning Control (DVC) platform makes it simpler to save, compare and reproduce machine learning (ML) experiments at scale without requiring organizations to set up an additional repository to track them. Instead, organizations can store those experiments alongside other software artifacts in a Git repository, he said.

    As a result, IT teams will no longer need to try to keep track of experiments using spreadsheets or notebook tools such as Jupyter, he noted. Organizations that are building AI models for applications constructed using DevOps workflows will also find it easier to comply with a wide range of existing and forthcoming compliance mandates, added Petrov.

    The DVC platform makes use of a Git-like interface to enable organizations to track multiple versions of data sets, models and pipelines across an MLOps workflow. That capability is being extended to make it easier to manage the experiments data science teams create during the construction of an AI model.

    Iterative is at the forefront of an emerging debate over how best to infuse AI models into applications. Providers of platforms used by data science teams are making a case for separate repositories for tracking the artifacts used to construct an AI model. Iterative, on the other hand, is arguing for the use of an AI model build framework that uses the same Git repositories where any other type of software artifact is stored and shared. Iterative’s argument is that, in effect, AI models are just another type of software artifact, noted Petrov.

    In addition to reducing the total cost of building AI models by reducing the number of platforms required, a Git-based approach also makes it simpler for DevOps and data science teams to collaborate because the DevOps team will have more visibility into what AI models will eventually need to be incorporated into an application.

    It may be a while before the development of AI models and applications fully converges. Data science teams today typically have defined their own workflow processes using a wide range of graphical tools. However, as it becomes obvious that almost every application is going to be infused with machine learning and deep learning algorithms to some degree, the need to bridge the current divide between DevOps and data science teams will become more acute.

    In the meantime, DevOps teams should assume that many more AI models are not only on the way but that those models will need to be continuously updated. Each AI model is constructed based on a set of assumptions; however, as more data becomes available, AI models are subject to drift that results in less accuracy over time. Organizations may even determine that an entire AI model needs to be replaced because the business conditions on which assumptions were made are no longer valid. One way or another, the updating and tuning of AI models is likely to soon become just another continuous process being managed via a DevOps workflow.

  • Test-First Development: Processes and Tools for Success

    Test-First Development: Processes and Tools for Success

    A lot of software development teams are talking about “test-first” methodologies. The practice involves moving testing up into the very earliest stages of development so automated tests can be written before code. Making this seemingly minor shift can result in much higher quality software and greater efficiencies. Integrating development and testing avoids needless late-stage bugs and complicated redevelopment efforts. It can help software development organizations focus on usability and features and achieve faster time to market. And because of test-first’s reliance on automated tests, organizations gain reusable tests, saving time and increasing standardization for testing and quality assurance overall.

    It’s no surprise, then, that 51 percent of organizations have begun using test-first methodologies, including 37 percent in the past year, according to a recent global survey of 200 software testers conducted by our company. But, despite the enthusiasm for this practice, there are concerns: 44 percent of survey respondents said their biggest fear about moving to this approach was forcing developers to contribute tests prior to completing code, while 19 percent said they worried about removing traditional testing checkpoints on the way to production. Other barriers include the lack of standard practices or tools. That said, test-driven development promises to bring ample benefits to software development teams, the business and, importantly, customers.

    Test-first development is recognized across three broad terms today: behavior-driven development (BDD), test-driven development (TDD) and acceptance test-driven development (ATDD). TDD is an umbrella term for the practice, although it has traditionally focused more on technical, unit testing. BDD and ATDD incorporate user requirements and business benefits along with technical testing. BDD differentiates through its adoption of specific automation frameworks and language for writing and running tests.

    Key Changes for Successful Test-First Development

    Getting started requires change across a few critical areas for most teams. First, evaluate your team for hiring and skills training needs. On the one hand, developers will need to learn basic testing skills, so they can write good tests and run tests before they develop code. Meanwhile, testers must become more proficient in automated testing tools, which usually entails acquiring a fundamental knowledge of programming. Many companies will need to hire key contributors from outside; in which case, leaders should look for well-rounded individuals with past experience using test-first methodologies successfully. An individual who is an expert at one skill, or who is too independent and can’t collaborate well, won’t be an ideal member of a team experimenting with test-first approaches. Leaders also may need to adjust by balancing the ranks more closely between developers and testers so that one group doesn’t rule over the other. Hiring additional experienced testers frequently will be necessary.

    Training of existing staff is paramount, best achieved through a combination of methods including internal training, mentoring, online courses and paired development, where developers and testers can sit side by side and collaborate. More than half of the survey respondents said developers and testers would be jointly responsible for automation test creation within their organizations.

    Beyond cross-training, the cultural challenge of moving to test-first methodologies can be overwhelming. It requires the development of incentives for creating quality products, not just delivering new features at speed. It requires an appreciation and respect for the practice of testing. Unfortunately, testing too often is viewed as a necessary cost of doing business, rather than bringing a clear benefit to the organization and its customers. That mind shift is not only inaccurate, but it doesn’t fly with progressive, Agile thinking. It will take strong leaders to help traditional teams understand the need to change and modernize practices. A leader may forego the buy-in process and instead decide to lay down the law to staff: Staff must move to TDD or BDD, or else. But the results won’t be ideal. Smart developers will find loopholes, such as writing tests that aren’t comprehensive or fully aligned with project goals, so the code will pass more quickly.

    On the process front, organizations that have moved or are moving from Waterfall to Agile and DevOps will have an easier time adopting test-first methodologies. In fact, it’s pretty difficult to implement test-first processes and tools in a Waterfall environment because of the siloed nature of functions and the long release cycles. The survey results support this premise: 55 percent of respondents said their testing process was Scrum/Kanban-driven before transitioning to test-first, while 21 percent said their approach was iterative-requirements driven and 18 percent was Waterfall-requirements driven.

    Along with that shift, test-first teams will need to adopt new metrics that align with this new way of doing business. Instead of looking solely at velocity, development leads should measure how long it takes the team to move a product from feature approval to code release. With a focus on quality and testing, companies also should measure and improve upon bugs, such as number of severe defects post-production. Those types of business and customer-oriented metrics align with the new set of Agile metrics that that many teams are working for today.

    Test-first teams will need to adopt DevOps toolsets, which are designed to push code out to the pipeline faster. Specific technologies that go hand in hand with test-first development include:

    • Continuous integration (CI) platforms such as Jenkins and Team City, to assist in running the automated tests immediately for quick build feedback.
    • Container technology for rapid deployment of test and pre-production environments, to capitalize on having features production-ready soon after coding.
    • Test management platforms including qTest Scenario or Cucumber Pro.
    • Test automation frameworks including Cucumber, SpecFlow , and other open source tools which enable easier support for customization and collaboration.

    There’s a lot to think about when moving toward test-first development. While it may seem overwhelming at first, all of this is achievable in a reasonable time frame if you have the right dedicated resources to see it through. One-third of survey respondents said it took them less than three months to complete the transition to a test-first approach, while 30 percent said it took less than one year. The payoff for software teams, in terms of improving quality, customer experience and reducing costs of innovation, can deliver higher customer loyalty and even faster growth in the marketplace.

    About the Author / Kevin Dunne
    Kevin Dunne picKevin Dunne is vice president of Business Development & Strategy at QASymphony.