Tag: load testing

  • Grafana Labs Acquires k6 to Add Open Source Load Testing Tool

    Grafana Labs Acquires k6 to Add Open Source Load Testing Tool

    During its online GrafanaCONline 2021 conference today, Grafana Labs revealed it has acquired k6, a provider of an open source load testing tool.

    Raj Dutt, Grafana Labs CEO, said load testing will complement the observability platform Grafana Labs currently provides based on open source Prometheus software. Most of the output of any load testing processes are typically evaluated using a platform that analyzes metrics, he noted.

    The k6 platform has been gaining traction among developers that require access to a tool that makes it simpler to dynamically scale load testing up and down as required versus having to guess how much infrastructure might be required to test an application workload, said Dutt. That capability not only makes it simpler to integrate testing within a DevOps workflow, Dutt added, but also serves to reduce testing costs.

    In general, Dutt noted testing is shifting further left as developers assume more responsibility for quality assurance. The challenge is finding a way to enable developers to automatically incorporate testing within a continuous integration (CI) process that allows them to easily observe how synthetic tests are executing, added Dutt.

    There’s no doubt developers are running more tests before promoting workloads into a production environment as part of an effort to reduce the number of issues that might be encountered when an application is deployed in a production environment. In many cases, the support calls that arise now go directly to developers who now have a vested interest in reducing the volume of those calls.

    The issue that developers are contending with is as they embrace microservices, the dependencies that exist across multiple applications makes it more challenging to successfully deploy those applications. Grafana Labs has been making a case for a cloud platform that makes it simpler to centrally view data collected from instances of Prometheus distributed across multiple application development environments. Prometheus, now being advanced under the auspices of the Cloud Native Computing Foundation (CNCF) that oversees the development of Kubernetes, is now being deployed more widely by IT teams to observe legacy monolithic applications alongside emerging microservices-based applications.

    It’s not clear the degree to which organizations are also employing dedicated application testers. In many cases, those testers will surface issues that developers overlooked (or simply chose to ignore) in the face of tight application delivery deadlines.

    In the longer term, however, it’s also apparent artificial intelligence (AI) will be playing a larger role in application testing. Someone will still need to review those tests, but many more rote tasks will increasingly be automated.

    One way or another, the total cost of testing is declining, thanks in part to increased reliance on open source testing tools that, in many cases, developers are simply downloading themselves. Those tools are reducing much of the licensing friction and cost restrictions that developers might otherwise encounter.

    In fact, the easier it becomes to test applications, the better overall application quality will become in the months and years ahead. At at time when organizations have never been more dependent on software, that potential improvement to the overall state of application quality can’t arrive soon enough.

  • Tricentis Aquires Neotys to Gain Load Testing Tools

    Tricentis Aquires Neotys to Gain Load Testing Tools

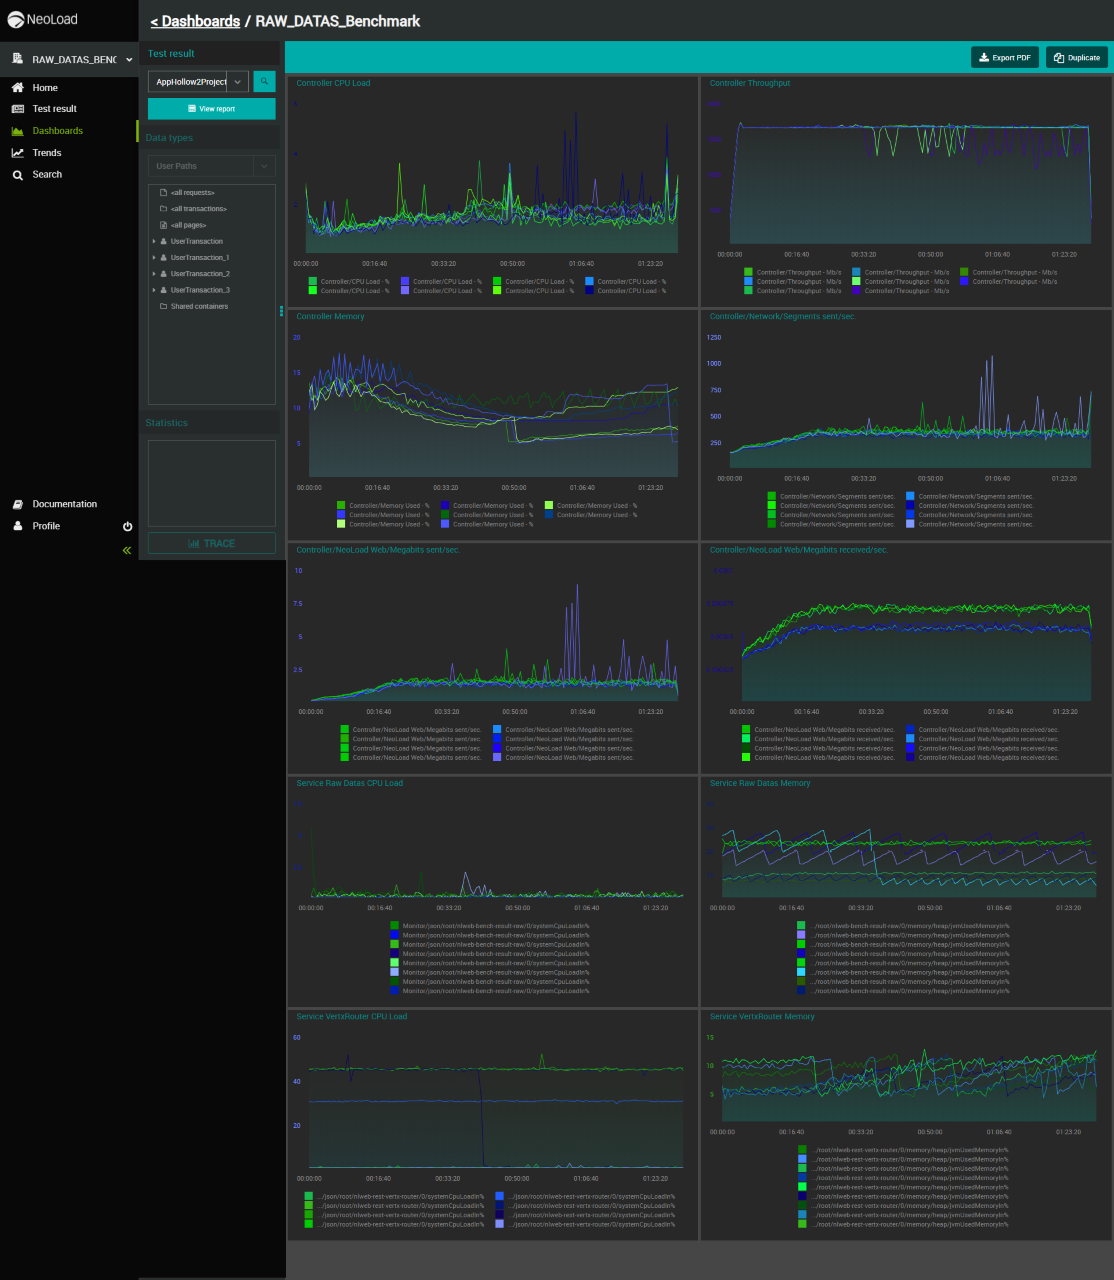
    Tricentis announced today it has acquired Neotys as part of an effort to expand the scope of its tools portfolio into the realm of load testing. Terms of the deal were not disclosed.

    Neotys provides application testing teams with automatic test design and maintenance, user behavior simulation and root cause analysis capabilities using a set of tools that are designed to be integrated within a DevOps toolchain.

    Sandeep Johri, Tricentis CEO, said the Neotys platform will extend the scope of Tricentis’ Tosca testing platform that today enables DevOps teams to employ machine learning algorithms to test the functions within an application.

    In general, Johri said there’s now a lot more focus on load testing, thanks in part to the rise of microservices-based applications that are starting to be deployed at scale. DevOps teams are, first, trying to identify, as early as possible, a single point of failure that might bring down an application. Second, modern microservices-based applications are designed to degrade gracefully when there is no single point of failure. Identifying what issues are leading to that degradation can be challenging, given all the dependencies that might exist within a microservices-based application.

    Neotys claims to have more than 600 enterprise customers, including BNP Paribas, Dell, Lufthansa, McKesson and Verizon. Tricentis claims to have more than 1,800 customers, including McKesson, Accenture, Nationwide Insurance, Allianz, Telstra, Rockwell Automation, Moët Hennessy-Louis Vuitton (LVMH PCIS) and Vodafone. The acquisition of Neotys will reduce the number of vendors that an organization needs to engage to gain access to a portfolio of testing tools, Johri noted.

    As IT organizations embrace DevOps best practices, more responsibility for application testing is clearly shifting left toward developers. However, it’s not quite clear to what degree that shift is either eliminating or reducing the need for dedicated application testing teams at the back end of the application development process.

    At the same time, many rote testing tasks are now being automated using machine learning algorithms. Those algorithms don’t completely eliminate the need for humans to test applications, but they do significantly reduce the testing time required. They should also create more time for developers to collaborate with one another to review more complex interactions within an application that machine learning algorithms are unlikely to be able to automate any time soon.

    The amount of time organizations devote to application testing has always been constrained. As deployment deadlines approach, often the first thing that gets reduced is the amount of time allocated to application testing. In many cases, developers deliberately don’t address some known issues until the first or second update to an application that has already been deployed in a production environment.

    Of course, integrating application testing within a DevOps process enables organizations to identify more potential issues earlier when they are easier and less expensive to fix. The challenge has always been getting developers to appreciate the value of testing early and often in the application development process.

    Regardless of how application testing continues to evolve in the age of DevOps the one thing that is certain is no matter how automated it gets developers are going to be more involved than ever.

  • Challenges of Designing API-Driven Experiences

    Challenges of Designing API-Driven Experiences

    As SaaS and mobile application development–and cross-software integration and communication–continue to become increasingly important for organizations across all industries to remain competitive today, APIs play a critical role. In fact, APIs dominate digital experiences today, with an average of 220 new APIs published every month, representing a 30% increase over the previous four years.

    As more organizations shift to an API-first development strategy to further drive innovation, partnerships and rich end user experiences, the proliferation of demand and consumption of APIs can bring its own challenges, if not properly executed from the get-go. Amidst the ever-increasing rush to develop and publish an API to remain competitive, we see several common issues arise–and often only after the API is rolled out–that negatively impact integrations, future partnership opportunities and end user experiences. Read on for a look at these common challenges and how to address them before you hit publish on your next API.

    Infrastructure Costs

    One of the biggest challenges when it comes to API design is the ability to manage costs, in particular infrastructure costs. From managing multiple gateway servers and instances, to building an entire API management program from the ground up, we see many common infrastructure approaches that organizations deploy today when designing APIs that lead to unnecessary and often unwieldy expenses.

    Critical to avoiding spiraling infrastructure costs is leveraging a single gateway to deploy, govern, secure and deliver global API traffic across various data centers. By using this approach, organizations can reduce man-hours spent managing and synchronizing servers; increase reliability by eliminating the need to manage multiple gateway instances; govern APIs without needing to build and maintain a separate API management platform; and eliminate regional gateway replication.

    By considering an API gateway at the onset of a design project to ensure API centric operations (such as authentication, authorization and throttling) are happening at the edge, organizations can proactively control costs and avoid financial surprises.

    Scale

    To a developer, there’s nothing worse than having a wildly successful API that can’t scale to meet the demand.

    Addressing scalability early on in the process can help define both early adoption, future success and the lifespan of the API. However, organizations commonly overlook the need to manage scalability in several ways–including planning for surges in API traffic and managing the volume of API requests consumers can make–which can lead to damaged user experience.

    Developers should look to a combination of load testing, authentication, throttling, quota management and API caching at the edge to improve and predict traffic, while preventing infrastructure from being overwhelmed by requests to ensure availability and reliability for consumers. Building in load testing early on can help a developer determine the traffic volume the application can withstand when surges in requests occur.

    Quota management can help enforce business service level agreements and limit the number of API requests that a partner is allowed to make. When it comes to API caching, some good places to start include: any resource accessible via HTTP GET, static data, immutable responses, infrequently altered or predictable responses and frequently requested data.

    Security

    While the commercial value of API development is clear, the reality is APIs can come with great cybersecurity risk. For one, APIs can provide a glimpse into the back-end of an application implementation and even the database it is connected to, providing hackers with new avenues for attacks. As the communication bridge between multiple applications, APIs left unprotected can also increase an organization’s attack surface and expose it to downtime and malicious attacks, including unintended misuse by legitimate users.

    Critical to protecting APIs is incorporating security at the infrastructure level with a multi-pronged approach that includes leveraging an API gateway to easily validate, authorize and control the access of legitimate API consumers (and block legitimate users), and endpoint protection against malicious traffic. Additionally, rate limiting–which puts caps on the number of requests per minute or second that API consumers can make–can prevent adversaries from overloading origin in an attempt to bring down API infrastructure in the form of a DDoS attack.

    Organizational Decentralization

    As speed and agility increase exponentially and API development evolves from microservices to nanoservices with individual team members owning what feels like ever-shrinking components, it’s easy to see how teams can organizationally splinter. While autonomy is important to making the development process flow quickly, decentralization is creating major governance and communication issues within many organizations today.

    This lack of governance creates its own challenges related to configuration visibility, changes and duplications across implementations which could lead to wasted resources, data leakage and more. Organizations should consider a single gateway that can expose APIs across multiple, distinct implementations but also provide suitable isolation so as to not affect the performance of other APIs when requests occur, while also providing separate control pages and the ability to set up distinct authorization and access rules for each API. The idea is the APIs are managed in the same decentralized way that is required to meet speed and agility requirements under a centralized infrastructure and governance policies.

    Strategic API design is not a simple task, but it is absolutely critical to organizations that desire long-term API success. By seeking cost-effective infrastructure, tapping tools to ensure scalability, building security protocols, practices and policies, and taking steps to more centrally manage the API design process early on will ensure longevity for the API, driving strong partnerships and, ultimately, providing better user experiences.


    This article was co-authored by Anthony Larkin, director of product marketing at Akamai. Anthony leads the go-to-market strategy for Akamai’s performance product portfolio. For more than 11 years at Akamai he has been dedicated to helping businesses remove barriers and unlock their potential to better engage users through web and mobile applications.

    — Sid Phadkar

  • DevOps Chat: Performance Testing with SmartBear’s Keshav Vasudevan

    DevOps Chat: Performance Testing with SmartBear’s Keshav Vasudevan

    In this DevOps Chat we speak with Keshav Vasudevan, product manager for performance testing at SmartBear. Keshav talks about the move to “end-to-end DevOps,” the importance of shifting left with testing and the latest state-of-the-art in performance and load testing with SmartBear.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation. Enjoy!

    Transcript

    Alan Shimel: Hey, everyone, it’s Alan Shimel, staging-devopsy.kinsta.cloud. You’re listening to another DevOps Chat. Joining me in this DevOps Chat is Keshav Vasudevan – and I’m sure I mispronounced that; we’ll let him correct it. Keshav is with SmartBear and he’s our guest in this DevOps Chat. Keshav, welcome.

    Keshav Vasudevan: Hey, thanks, Alan. So happy to be here and, yeah, I will correct it – it’s actually Keshav Vasudevan, so that’s how you say my last name. And I’m – I currently work at the –

    Shimel: Vasudevan, okay.

    Vasudevan: Yeah. I work –

    Shimel: I’m glad you _____ –

    Vasudevan: Uh-huh?

    Shimel: Well, give us your – okay, so – and we’ll call you Keshav for the rest of the podcast today. But, Keshav, you’re with SmartBear, but why don’t you give our audience a little background? What’s your own personal journey here?

    Vasudevan: Oh, of course. I mean, personally, I’m coming from an engineering background. Yeah, I love all things code. I love building applications and, in my spare time, I just love building mobile apps and Web-based apps as just hobby projects, which is why it felt like a natural fit to be at SmartBear Software. I’m incredibly passionate about quality as a whole and I understand and know the importance of having consistent quality to ensure the best optimal end-user experience.

    So, at SmartBear, currently, I’m the product manager for performance testing and specifically in the LoadNinja application. And I help communicate the value of shift-left testing in the Agile- and DevOps-based ecosystems that typically we’re seeing the world shift towards. And, of course, I’m responsible for the product management and execution of our innovative, new, revolutionary platform in the performance-testing space, essentially allowing people to do real browser-based load testing at scale, which is unprecedented so far.

    Shimel: Very cool. So, Keshav, you’re right in the heart of it of what SmartBear’s about, but SmartBear is a company – you know, when we look at the DevOps space, the move is obviously towards “bigger is better.” We have all these companies who are trying to do end-to-end DevOps and complete-life-cycle DevOps. SmartBear is a company that, for as long as I’m familiar with them, have had multiple products and plays – you know, I’m not saying you’re end-to-end DevOps or that’s what you aspire to be at SmartBear, but SmartBear is definitely a company where you aren’t singular product, singularly product-focused on any one area. SmartBear – you know, there was a lot of testing products, but there was a lot of other products too.

    And, recently – well, historically, each of those products almost had their own identity, as they should, but the SmartBear moniker was almost secondary to the individual products. And, recently, we’ve seen that change, right? Where SmartBear has made a broader effort to bring all of these disparate products into a cohesive type of vision of going to market under “SmartBear.” You wanna elaborate on that a little bit? Or, better yet, give our audience kind of the breadth of all the different solutions SmartBear can help with.

    Vasudevan: You bring up a great point, Alan. So SmartBear’s been around for almost ten years now. And, since our inception in 2009, we’ve grown into a global company, which testers and developers and architects and designers have come to trust with their overall software-development needs. Our initial focus, when we first started, was around software collaboration and testing, but, eventually, of course, as the company grew and as we added more talented people to the company and also as we grew in user base, we realized that we could actually solve much more broader functional use cases.

    And so, since our inception, we right now have 11 global offices. We are a big advocate of open-source platforms and tools, and so a combination of our open-source tools, which is SoapUI, which is one of the most popular API-based testing tools, and Swagger, which includes, of course, the Swagger UI, the Editor, the Codegen, and the commercial SwaggerHub, are all part of our ecosystem. And so, in total, we have over  6.5 million users and over 22,000 customers of our commercial platforms. And, since we’ve started, we have over 500 employees. So that is history of SmartBear and where we are in its current state, but you’re absolutely right. We have a breadth of different products, that each essentially cater to different aspects of the overall software development life cycle.

    And so, if you look at the overall life cycle, we have tools that cater to solving and solving use cases and problems and seeing the design phase of the software journey, the actual development and testing and collaboration aspect, cross-functional and performance testing. We’d integrated a bunch of our partners in the deployment phase, with AWS, for example, or Kubernetes. And, finally, in the actual post-production and post-deployment, we actually have monitoring tools as well. So we essentially play in the entire software development life cycle, and we cater to different audiences and our tools overall cater to different use cases in those journeys.

    Now we’ve gotten a lot of good feedback for each of these products, but we also recognize, at the end of the day, that, today’s day and age, Agile and DevOps is the way products – or software-development teams are moving towards. This is primarily, again, because software development has evolved in order to meet the growing demands of consumers. And consumers right now, today’s consumers of software applications, are looking two important things. The first is they want features, right? The switching cost to go from one application to the next is going lower and lower, so, if I, as a consumer, am not getting the best features on a regular basis or new updates or enhancements on a regular basis, I might get frustrated and I might just move to another vendor. And the second thing is we have started to expect a lot of good quality in all the things that we’re consuming because, again, as we’re digital consumers, we know that, every day, we spend over 11 hours in front of our computer and looking through different applications. So we have come to expect a certain standard of quality.

    And all of this ideal of fast development and incorporating testing and quality into every aspect of this journey is achieved with the ideal of incorporating Agile and DevOps into your workflow. And so we know that, to go across all of these different functions in a seamless and automated fashion, you have to essentially integrate all of the different tools that we have that cater to all of these individual use cases, in a seamless fashion as well. And so – oh, one other thing that we pride ourselves on is we, from a product level, we have a seamless integration across all of these different verticals, right?

    So, for example, we have the ability in the performance-testing space to essentially integrate with Jenkins, with LoadNinja, that essentially now allows you to automate your load testing with real browsers at scale, meaning with 10 virtual users or 10,000 users. You can be rest assured that is the most accurate representation of load. All of this can be integrated and automated using Jenkins with a simple plug-in. Right? And this also then integrates with other tools. For example, we have an integration with our design tool, which is SwaggerHub, with our API-testing tool, which is SoapUI. So then you can essentially easily design your API, architect it easily, design the API, make sure it solves the end-user use cases, and then push it to the tester and developer to actually test out each of these functionalities. So we wanna make sure that this process, this ideal of DevOps, is actually achieved in execution with the seamless integration.

    Now one level higher is the actual story and the marketing and the branding around it. And we’re proud to say that SmartBear recently unveiled its new brand that gives our customers and prospects and users a more cohesive understanding of how each of these tools fit together, feel proud of the fact that they’re now part of the SmartBear ecosystem, and allow them to, essentially, seamlessly move from one tool to the next because of maintaining the branding and user experience across each of these tools. And that was a huge undertaking that we did and we just unveiled it last year at our user conference, Connect. And we’ve gotten lot of, lot of, lot of good feedback about our new brand, our logo, and everything else around that. So it’s a long–winded way of saying, “Yes, you’re absolutely right. And we’re making sure that that we are achieving that as well.”

    Shimel: Absolutely. And you know what? I have one of the shirts with the new logo they sent me too, so thanks for that. But, you know, the interesting takeaway here – I hear from so many and I recently received an e-mail from a fellow in the field who said, “Where do you see – we need to be moving to platforms. We need platforms to build on. And how do you build a platform? And where do you see the need for a platform?” And then you look at, as you’ve just laid out here, SmartBear and you take these tools and individual solutions, point-solutions that you guys had put together over the years, and showing how integration among them, as well as integrating with best-of-breed kinda tools out there, like a Jenkins and some of – and we were blessed in DevOps to have a lot of open-source solutions as well, but integrating with a lot of these open-source. I mean, this is how you stitch together a platform. This is how you get “one plus one equals three.” Right?

    Vasudevan: Yes, exactly. Absolutely.

    Shimel: Yep. So, Keshav, we’ve waste – we didn’t waste but we’ve spoken an awful lot about kind of background on SmartBear. I really wanted to spend our time talking about what’s new and what’s going on with you and your team there, so why don’t we dig down and peel the onion back a couple layers on that? What do you have – imagine you may – you know, you alluded to it earlier but let’s dig in: what’s happening?

    Vasudevan: Absolutely. So one of the things, as I mentioned in my introduction, as something which we as a company are really passionate about, is ensuring quality. Right? And, over the last 15 to 30 years, over the last – well, let’s say over the last 15 years, we as users – and when I say “users,” anyone – me, you, our friend; it’s essentially consumers of applications – have started to expect a certain level of quality. And this is how software development has evolved, in order to meet this demand.

    And, as we have touched upon, this is why Agile has evolved, which is essentially moving fast, allowing developers and engineers to build features in a much more faster way and deploy them seamlessly so that the end users get them in the quickest way possible. Right? And we’re always listening to the end-user feedback and updating the platform. Then there’s DevOps, right? Which is, again, trying to follow the same ideal and essentially having a much more collaborative approach towards testing, operations, and development together.

    Now let’s go dissect quality, the testing aspect of it. Right? So Agile, to allow for Agile- and DevOps-based testing, functional testing tools have done a great job of keeping up with the times. Right? For example, we have two tools like that, which is SoapUI and TestComplete. And they’ve done a phenomenal job in terms of allowing people to quickly come in and create their test scripts, make sure it all works, make sure to write the test cases really quickly because they have features to do that, and then, again, automate the entire process, using maybe a REST API or, of course, using an existing CI/CD tool.

    Performance testing, though, which is a huge – which is a big business KPI in today’s day and age, right, is something that people are still, to this day, scared to do. We talk to product teams and engineering teams on a daily basis, who tell us how important they know performance testing is. For example, we know that, if consumers take more than – if it takes more then 3 seconds for a certain e-commerce page to load, for a customer, they’ll leave. They’ll just go to another platform. The switching costs are getting lower and lower and people are getting more impatient, so, if it’s gonna take a while to do a certain transaction, people will leave. And that is a huge business loss at scale for your company, for your platform, and as an organization as a whole.

    So product and engineering teams, Agile teams, want to do performance testing. However, performance testing, to this day, has not evolved to keep up with the growing needs of Agile and DevOps-based workflows. To this day, it takes such a long time, for me as a performance tester, to create a test script. I have to essentially learn – and, if I was a developer or functional tester wanting to do performance testing, I have to forget about it. I have to hire a consultant because my learning curve is gonna be so steep. I have to allocate a lot of time in my day-to-day operation in order to create a simple test script. This is because, over the last 30 years of performance testing, the technological process has not evolved at all. To this day, if you’re creating a performance test script, you have to record all the transactions between the browser and the server. You’re doing this under the protocol level. That is typically how you actually create a performance test script.

    Now, as you know, the responses and the requests between server and client will have certain dynamic characteristics, like session IDs, cookies, and so on. So, in order to play this back across 1 user or 10,000 users to do the performance testing, you will have to do this programming and dynamic correlation. This process takes anywhere between several hours to a few days to even become successful, for the most basic transactions. Now imagine doing this for the complex applications that we have today, some of the AJAX applications which are very client-rich, in terms of actions and allowing users to do multiple things. The effort that is involved to do this multiplies threefold. Right?

    And so this is why performance testing is still, to this day, seen as something which no one wants to touch. They’ll hire a consultant; they’ll have a centralized function to do this. Then there’s, of course, the actual process of emulating and creating the load itself because, to this day, we still use emulators to generate the load, which is not necessarily representative of the end-user experience.

    So this is something we saw over the last one year and we decided to do something about it, which is what – you know, our engineers came together. We said, “We are passionate about this. We face this issue ourselves. Let’s do something about it.” And so, essentially, we productized a new approach to doing load testing, essentially allowing users or testers or developers or functional testers – anyone who’s passionate about performance testing, anyone who’s behind an application, be it a marketer, a product manager, a functional tester, or a performance tester – to essentially come in, record, and instantly play back the transactions that they record in the test script, without doing any programming or dynamic correlation whatsoever. Right?

    And, from here, of course, you can – and take the script that you have and spin up tens of thousands of real browsers to go ahead and do the load test, based on these transactions. Right? This is a – I don’t use the word lightly here, but a revolutionary approach to actually doing performance testing because this is unprecedented, to essentially create browser-based test scripts without doing any sort of protocol-based recording, which allows you then to create test scripts out of the box. And then simulate tens of thousands of real browsers to run these scripts on them. So, as a user, as a tester, you’re, one, going to save over 50 to 70 percent of your time, doing the actual load testing, because the scripting process has become so much more easier. And you’re gonna get results that are coming straight from the browser, so you can be rest assured that this is the most accurate and realistic representation of the performances that your application will be showing for end users. And this is what LoadNinja is, as a product.

    And, over the last five months, since we launched in October, end of October, during our user conference, we’ve seen tremendous traction in the market. We’ve seen so many customers come to us, sign up for annuals and partner with us, to essentially allow them to do load testing. And it’s just phenomenal, as a product manager, and it’s like seeing the vision come to fruition and actually seeing the people who are behind products – product managers, functional testers, all of them – coming and saying, “Hey, we can now do performance testing by ourselves, without necessarily having to get a certification with an expensive tool. Without having to spend so much more money and dollars trying to get a consultant.” They can do this all by themselves and that’s the most gratifying thing I ever heard. So, yeah. So there’s a lot happening, but the LoadNinja’s primarily something that we’re super proud of, as a company. It was built in house by us. The revolutionary technology to do this it’s something which performance testing has never seen to this day.

    Shimel: You know, listening to you, all I can think of is back to my own days as a entrepreneur and developing security solutions, and we’d have to go get performance testing done. We were selling to DOD – it was large, large networks – and this is pre-DevOps, obviously, and pre-automation and pre-continuous. And, my god, the budget for the performance testing was bigger than the budget for the development team. It was nuts. I mean, it was – so, when I hear now about how this stuff is being done in the cloud and “automated” and “scalable” and the price points, it’s just crazy.

    Vasudevan: It is. It is. We’ve come a long way. And, to this day, there’s still – performance testing is seen as a monolithic and centralized function, right? And so, to this day, what you saw years ago, many of the factors are still there. So, yeah. So you’re absolutely right and it’s good to see the cloud coming in, but as a performance-testing industry and tool vendors, we can do a lot more to push the boundaries and keep up with the growing demands of engineering and quality as a whole.

    Shimel: Yep. Got it. Got it. You know, Keshav, I told you when we started things get out of control. We were supposed to go 15; we’re at 20 minutes.

    Vasudevan: [Chuckles]

    Shimel: We’ll have to continue our SmartBear discussion on another DevOps Chat, at another date. We’ll have you back on soon. But why don’t we put an end for it right here? But, before we do, people listening, they like what they heard; they’re interested. Where can they go get more information?

    Vasudevan: Oh, absolutely. So the best place to go is loadninja.com, so L-O-A-D-N-I-N-J-A-dot-com. And you should have all the required information to become successful and get started. One of the things we pride ourselves, as a product and engineering team, is our turnaround for new features and enhancements. We deploy almost every week and, again, using the – many of the learnings, we learned from your website, Alan, in the DevOps world, to essentially continuously integrate and deploy every now and then, every week, in order to get the features and enhancements that users require. So go to loadninja.com; you’ll have all the required information to become successful.

    Shimel: Fantastic. Thank you very much for being a guest on this DevOps Chat. And I am serious – we’ll have to have you back on here – but, for now, I think we’re gonna pull the plug on this episode. Thanks, everyone, for listening. This is Alan Shimel for staging-devopsy.kinsta.cloud, Security Boulevard, Container Journal, Digital Anarchist. You’ve just listened to another DevOps Chat. Have a great day, everyone.

    — Alan Shimel

  • We’re All Load Testers Now (Maybe)­

    We’re All Load Testers Now (Maybe)­

    More than 94 percent of organizations already have Agile or DevOps initiatives or plan to adopt them within the immediate future, according to a survey by VersionOne. As part of the process transformation required to adopt these more iterative and rapid methods of delivering software, organizations are reassessing all practices associated with software development and test, including load testing.

    Traditionally, load testing has been deferred until the late phases of waterfall release cycles. Specialized performance testers applied legacy load testing tools to validate application performance prior to release. Why is this no longer sufficient?

    1. With teams moving to more componentized applications (including cloud-native apps, microservices, etc.), an application involves many highly distributed components—and a performance issue in any of them could have a ripple effect across the entire application.
    2. Now that new functionality is being released weekly, daily or hourly, each team needs instant insight into whether their incremental changes negatively impact performance.
    3. The later you start load testing, the more difficult, time-consuming and costly it is to expose, debug and resolve performance problems.

    In-depth load testing by performance-testing specialists remains critical, but it doesn’t provide the level of fast, on-demand load testing that’s critical for Agile and DevOps. Developers and testers need a way to expose critical performance issues before new functionality progresses through the delivery pipeline. To achieve this, DevTest team members must be able to easily:

    1. Create load tests that provide fast feedback on the functionality they’re evolving; and
    2. Execute and scale those load tests as needed—without the exorbitant costs and efforts traditionally required to establish, configure and maintain a performance test lab.

    Traditional Load Testing Isn’t for Everyone

    However, load testing has long been the domain of performance testing specialists for a reason: it’s difficult. Today’s developers and testers don’t have the time (or desire) to wrestle with all the technical details required to get load tests working correctly and to keep brittle load tests in sync with the rapidly evolving application.

    The traditional way of approaching load test scripting is at the protocol level (e.g., HTTP). This includes load testing with open source tools such as JMeter and Gatling, as well as legacy tools including LoadRunner. Although simulating load at the protocol level has the advantage of being able to generate large concurrent load from a single resource, that power comes at a cost. The learning curve is steep and the complexity is easily underestimated.

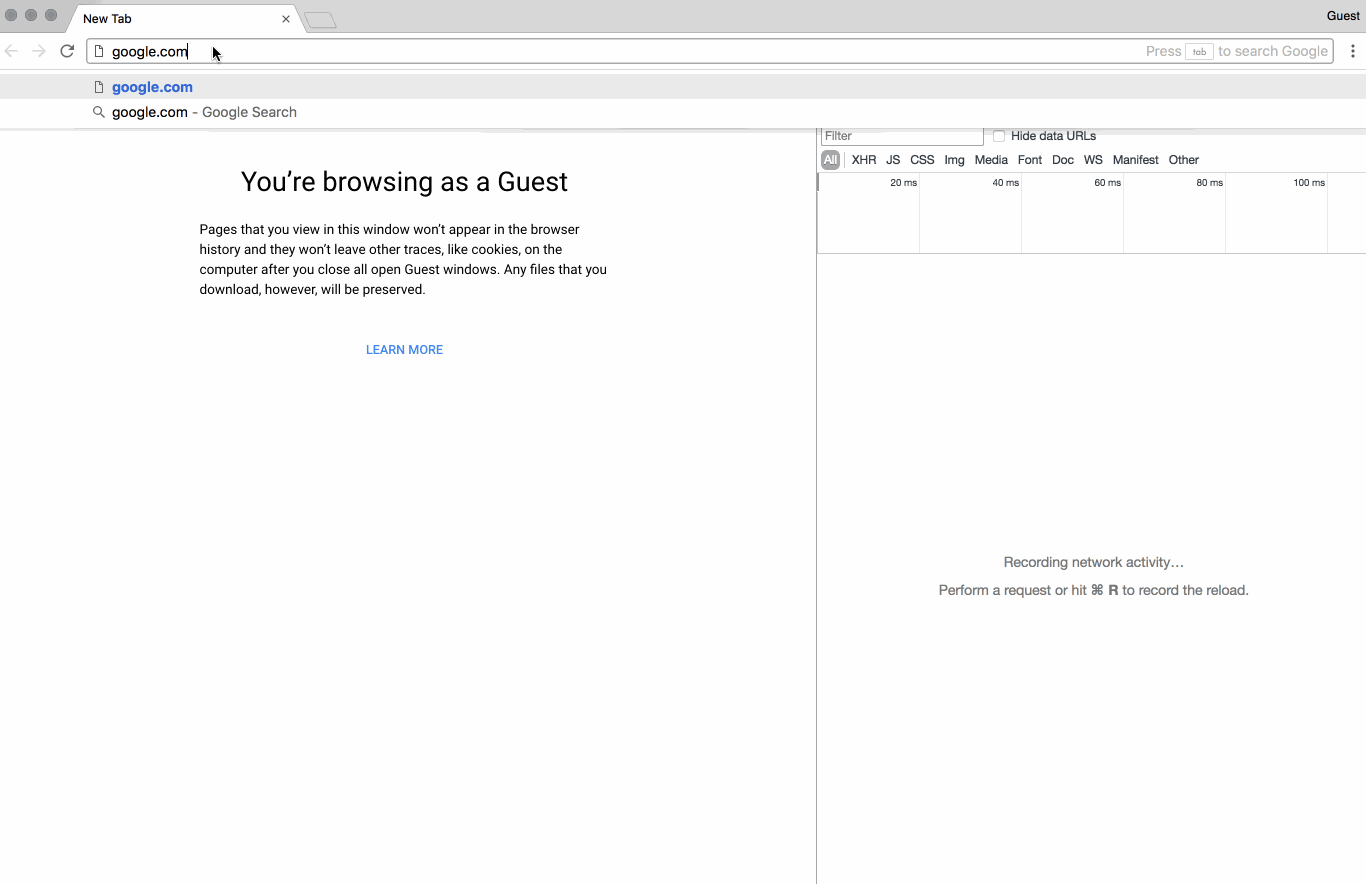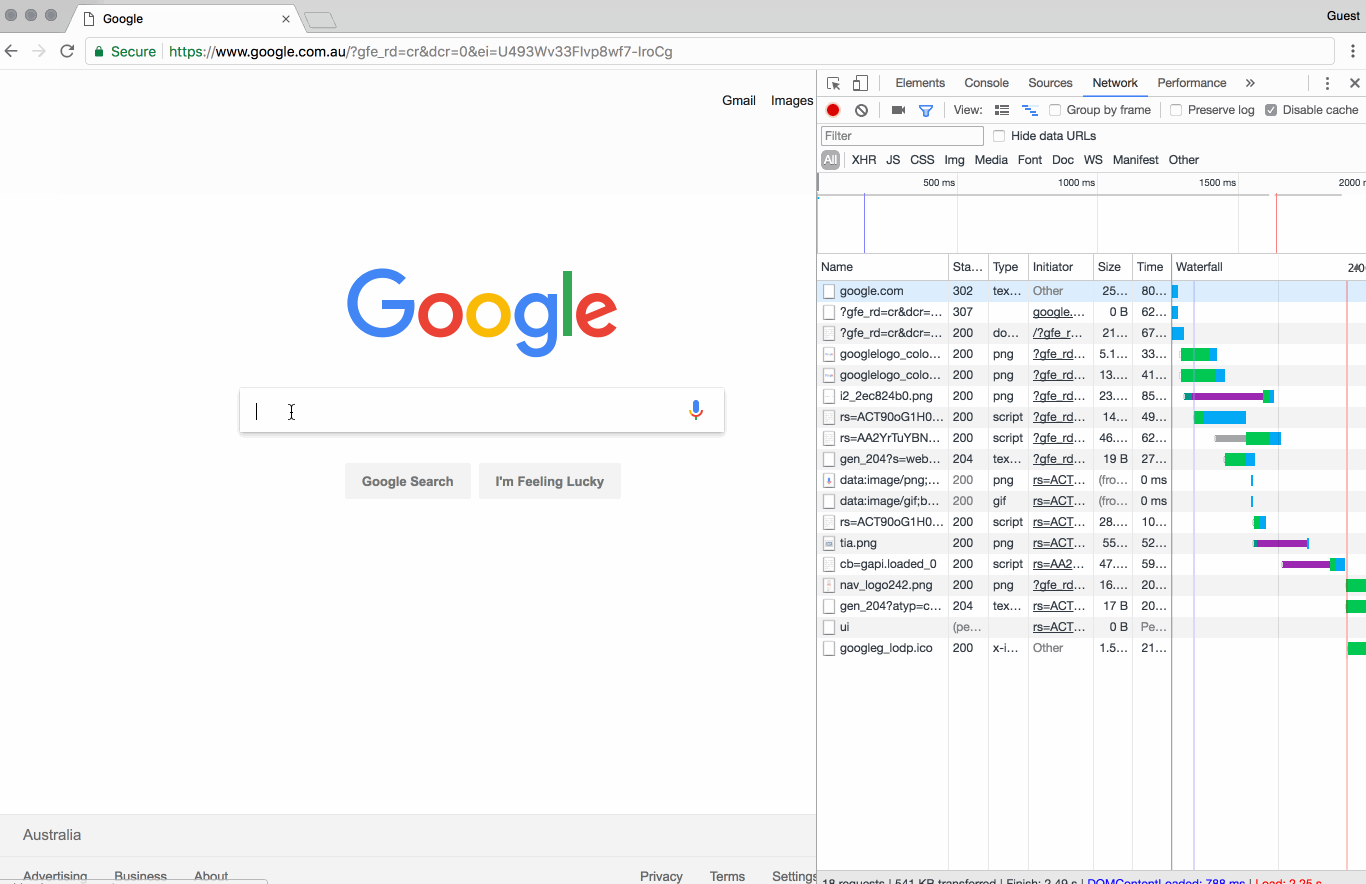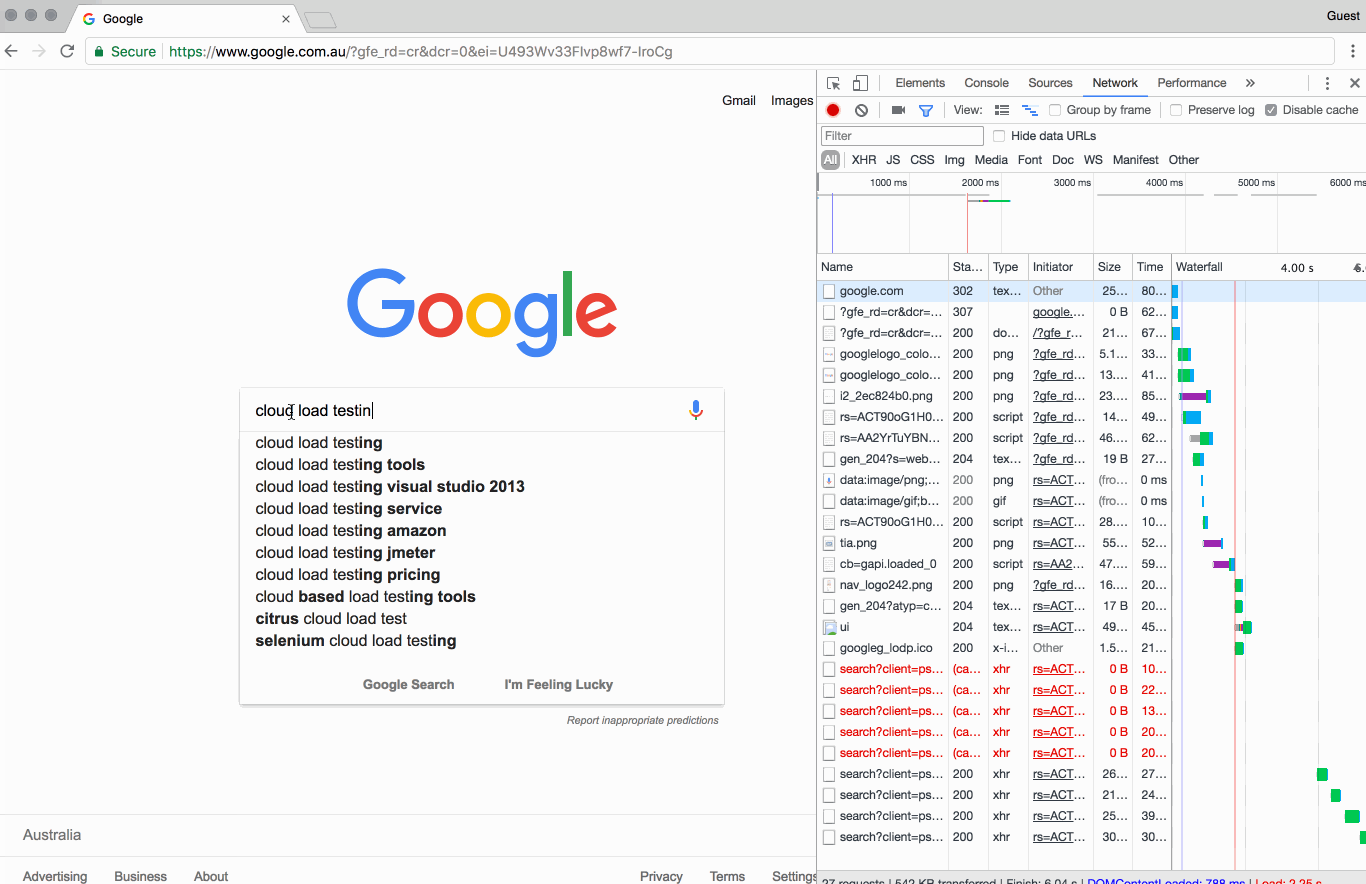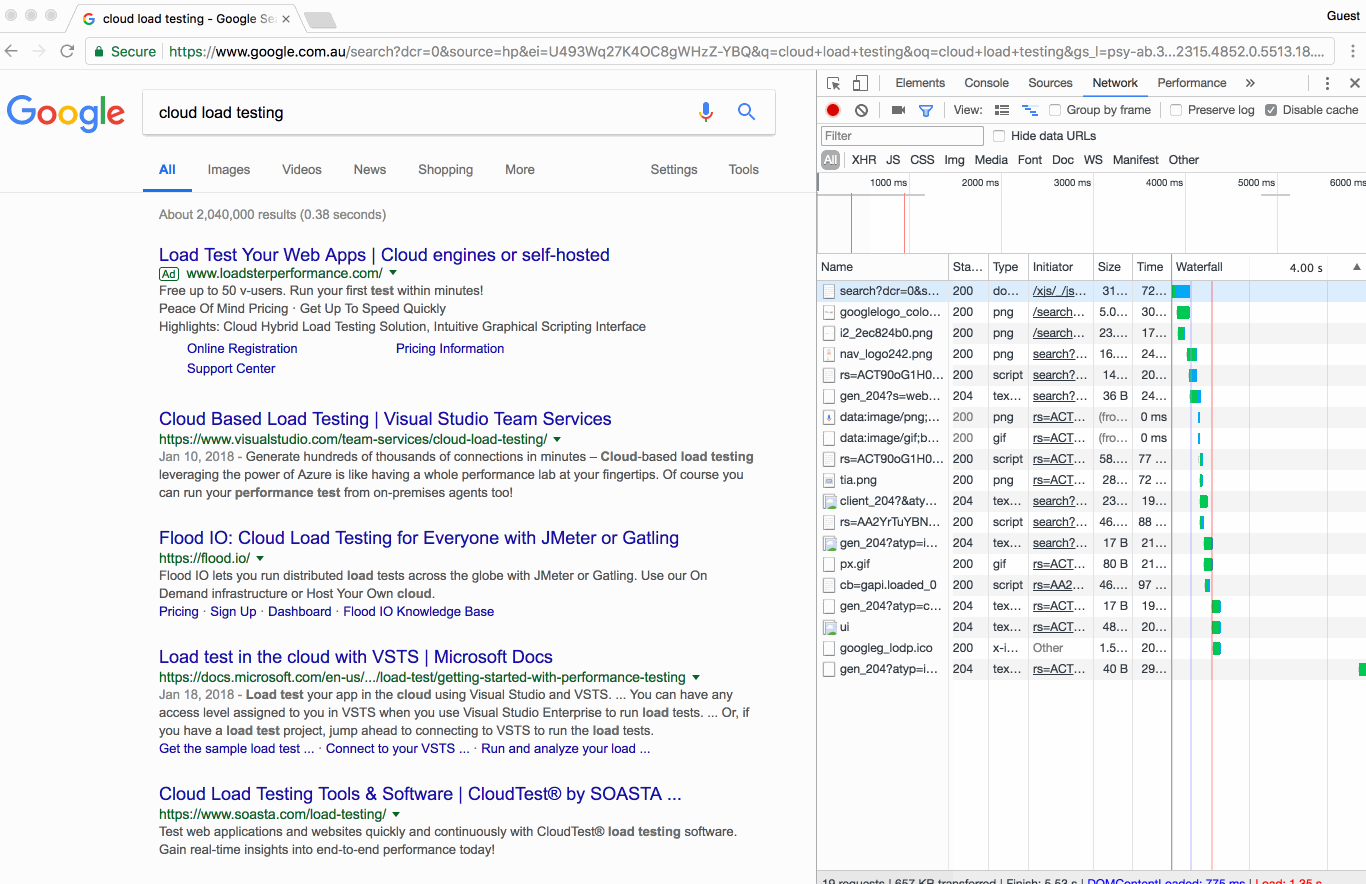
    The main culprit for this complexity is JavaScript. In 2011, there was usually less than 100 KB of JavaScript per page, which spurred around 50 or fewer HTTP requests. Now, that’s doubled: We see on average  200 KB of JavaScript per page, and this gives us more than 100 requests per page.

    Just running a search on a simple search page involves things such as XML HTTP requests processed asynchronously after page load. You also find things such as dynamic parsing and execution of JavaScript, the browser cache being seeded with static assets and calls to content delivery networks.

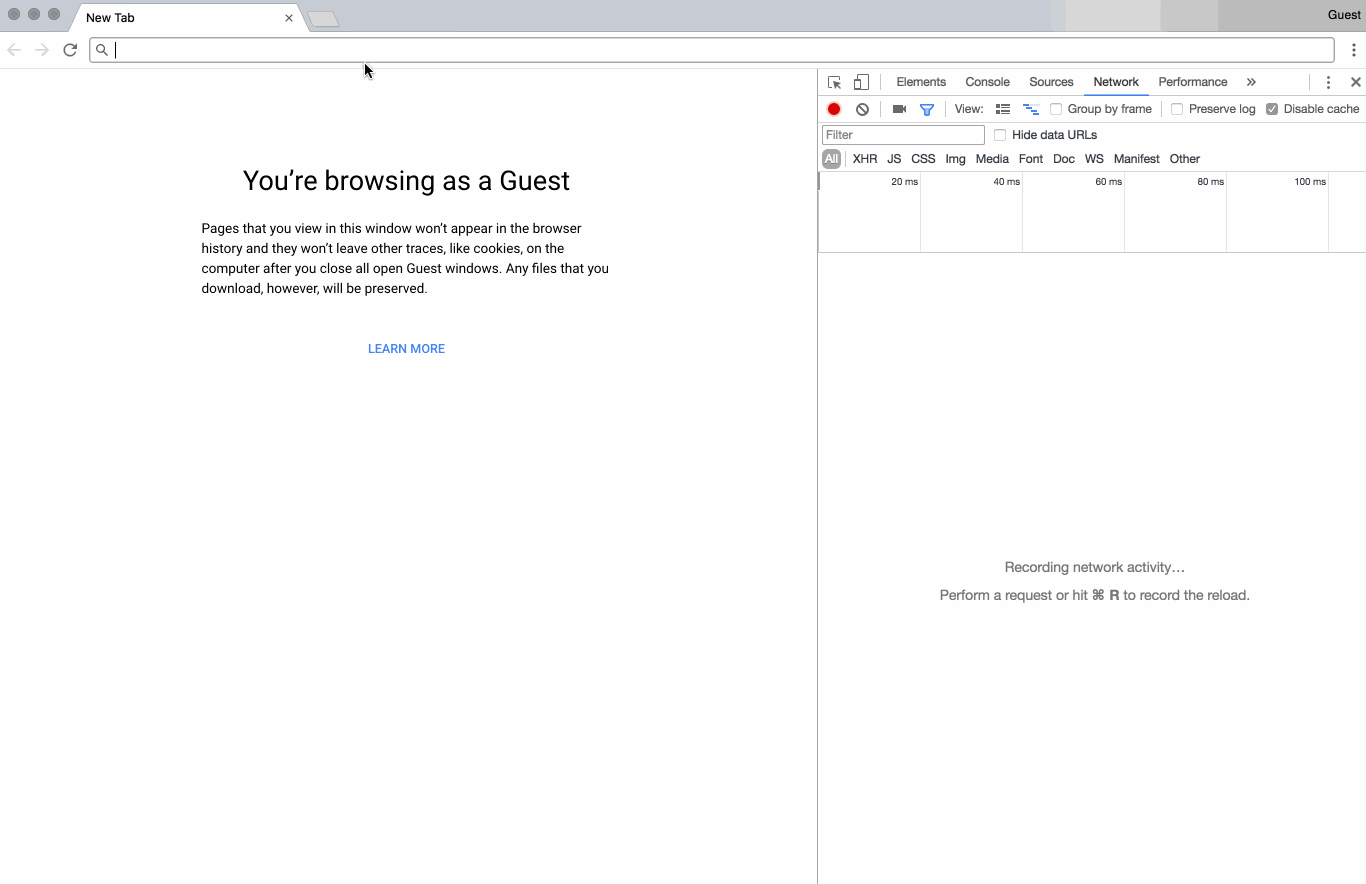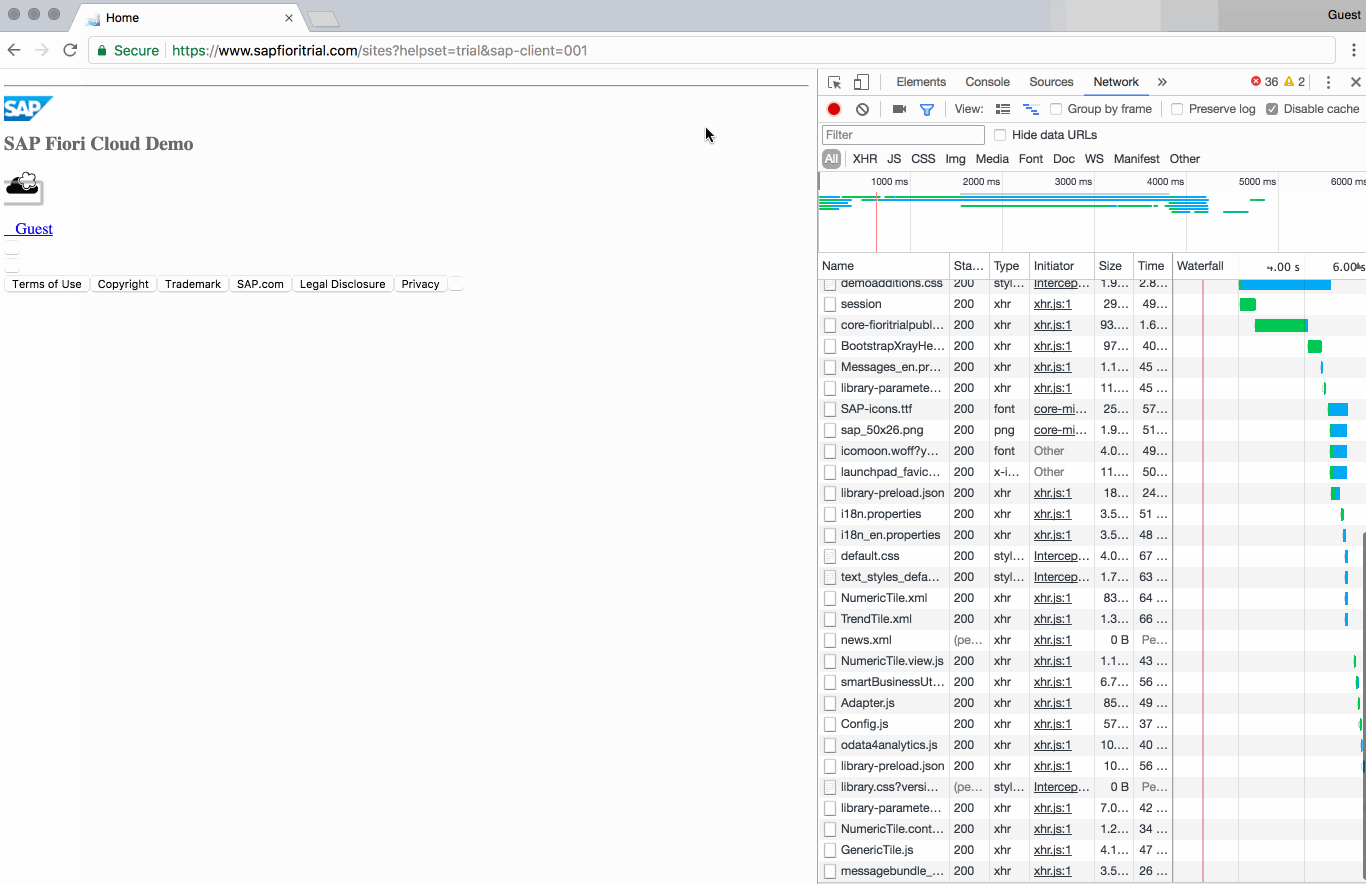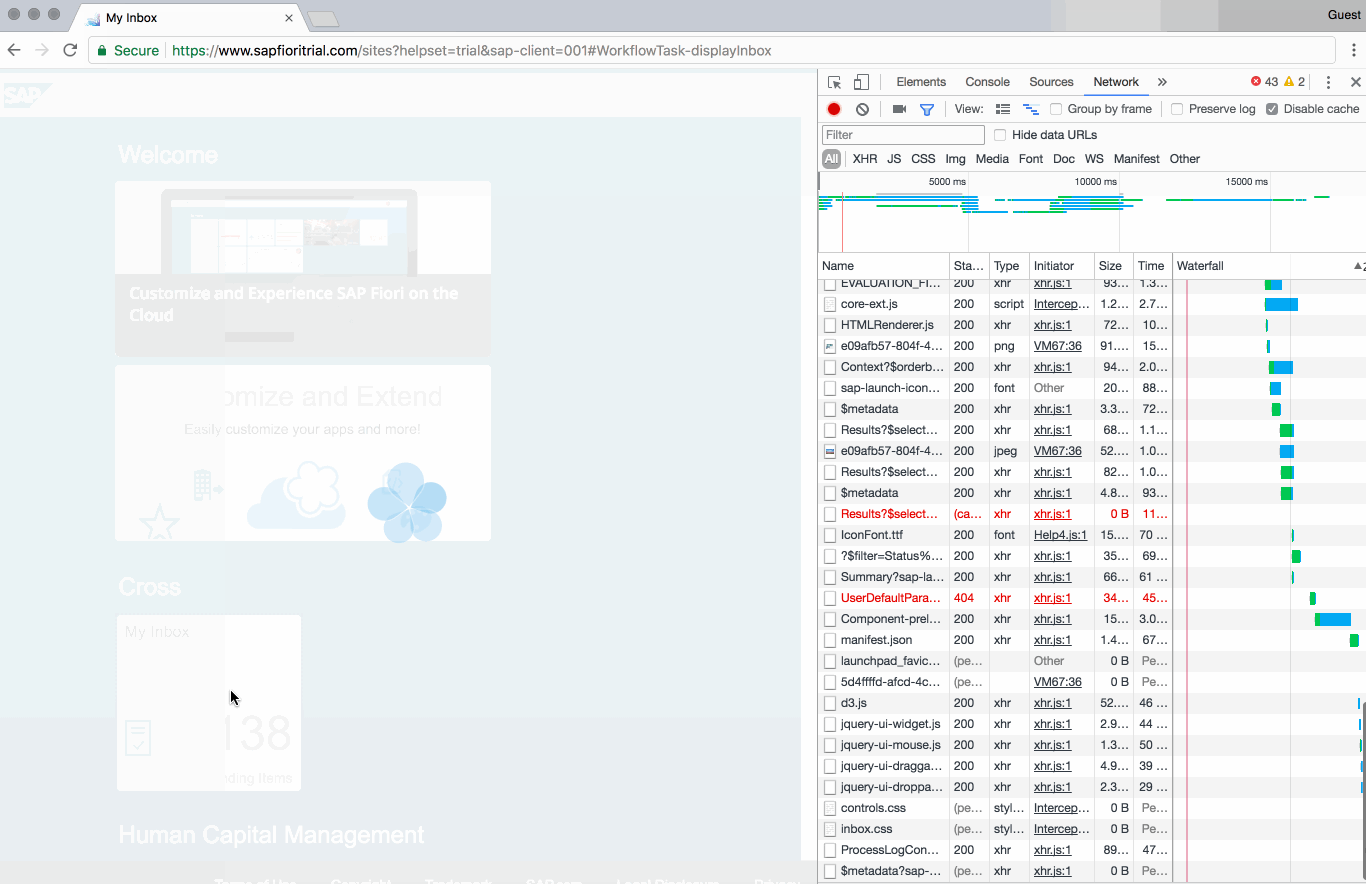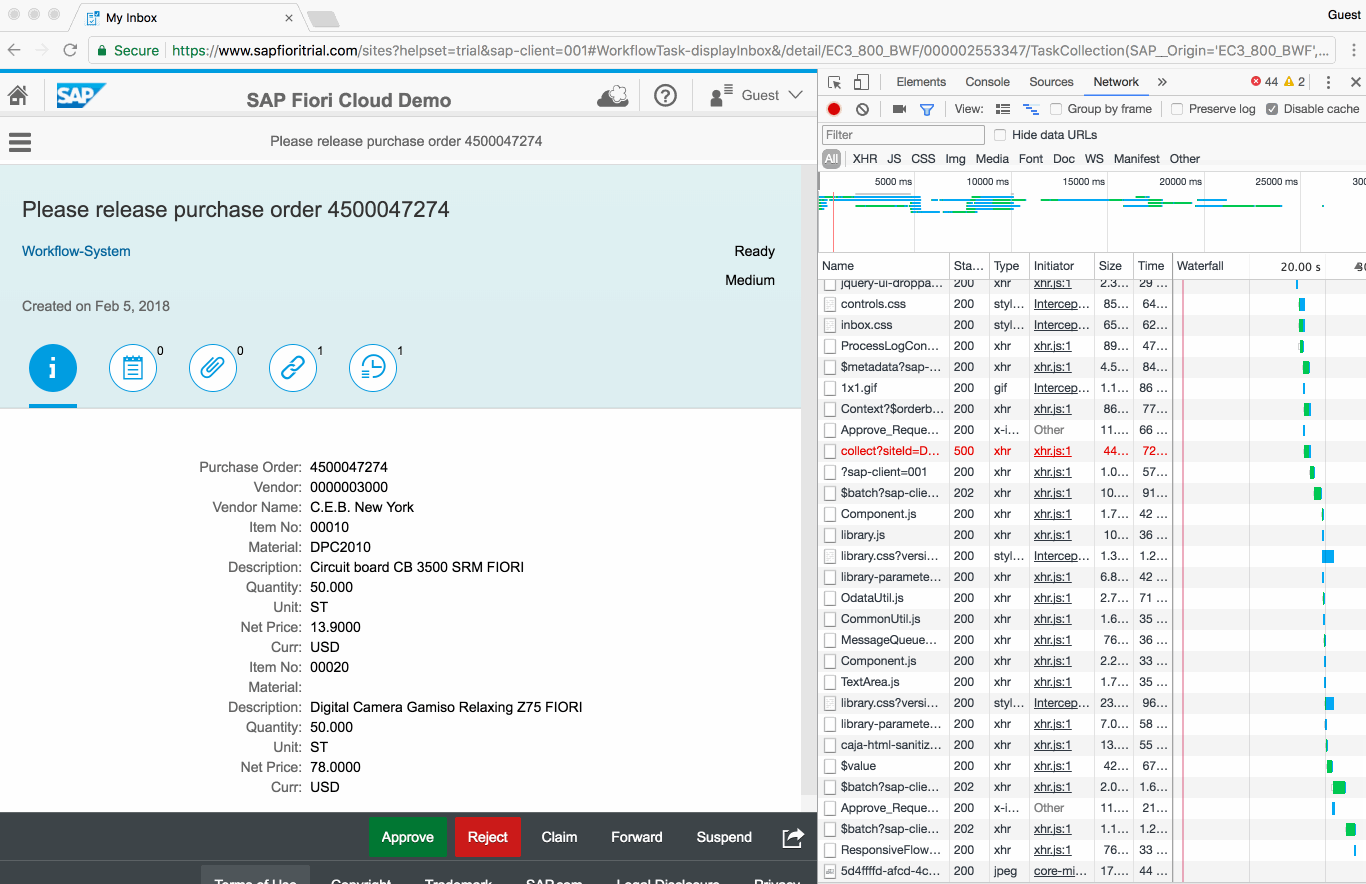
    For a more business-focused example, consider the SAP Fiori demo app. Assume we want to load test two simple actions: navigating to a page and then clicking on the “My Inbox” icon. This actually generates more than 120 HTTP requests at the protocol level.

    When you start building your load test simulation model, this will quickly translate into thousands of protocol-level requests that you need to faithfully record and then manipulate into a working script. You must review the request and response data, perform some cleanup and extract relevant information to realistically simulate user interactions at a business level. You can’t just think like a user; you also must think like the browser.

    You need to consider all the other functions that the browser is automatically handling for you, and figure out how you’re going to compensate for that in your load test script. Session handling, cookie header management, authentication, caching, dynamic script parsing and execution, taking information from a response and using it in future requests … all of this needs to be handled by your workload model and script if you want to successfully generate realistic load. Basically, you become responsible for doing whatever is needed to fill the gap between the technical and business level. This requires both time and technical specialization.

    You might be thinking, “Okay, we’ll use ‘record and playback’ tools, then.” Theoretically, you could just place a proxy between your browser and the server, record all the traffic going through and be set. Unfortunately, it’s not quite that simple. Even though you’re interacting at the UI level, the testing is still based on the protocol level. Assume we were looking at the traffic associated with one user performing the simple “click the inbox” action described above. When we record the same action for the same user two different times, there are tens if not hundreds of differences  in the request payload that we’d need to account for.

    Of course, you can resolve those differences with some effort. Unfortunately, when the application changes again, you’re back to square one. The more frequently your application changes, the more painful and frustrating this becomes.

    Taking a Browser-Based Approach

    To sum up the challenge here: modern web applications are increasingly difficult to simulate at the protocol level. This raises the question: Why not shift from the protocol level to the browser level—especially if the user’s experience via the browser is what you ultimately want to measure and improve?

    When you’re working at the browser level, one business action translates to maybe two automation commands in a browser as compared to tens, if not hundreds, of requests at the protocol level. Browser-level functions such as cache, cookie and authentication/session management work without intervention. There are a number of ways to simulate traffic at the browser-level: Selenium is clearly the most popular, but there are a number of cross-browser tools available—some of which let you test without getting into scripting.

    However, historically, it just wasn’t feasible to run these tools at the scale needed for load testing. In 2011, if you wanted to launch 50,000 browsers with Selenium, you would have needed something on the order of 25,000 servers to provide the infrastructure. Moreover, it would have been prohibitively expensive and time-consuming to provision the necessary infrastructure.

    Today, with the prominent availability of cloud-based technology, the concept of browser-based load testing is feasible. At the same time, projects Google Chrome and other projects are offering fast automation and better memory profiles with headless or UI-less variants of the browser. In fact, tests with headless Chrome show that it’s possible to go far beyond the industry standard benchmark of two to five browsers per machine and achieve around 50 browsers per machine.

    Suddenly, generating a load of 50,0000 browsers is a lot more achievable—especially when the cloud can now give you access to thousands of load generators that can be launched from any web browser and can be up and running in minutes. Instead of having to wait for expensive performance test labs to get approved and set up, you can get going instantly at an infrastructure cost of just cents per hour. Fast feedback on performance is no longer just a pipe dream.

    At Flood IO, we’ve captured our browser-level user (BLU) research and development in Flood Chrome: a browser-based load generation approach that builds upon APIs from Google for headless Chrome automation. This approach reduces the complexity of writing and maintaining tests while maintaining a viable level of concurrency and performance per machine. It creates scripts at a higher level of abstraction—the user level—then distributes those tests via the cloud for better economies of scale.

    Why consider this new approach to load testing?

    1. Simple scripting—or no scripting at all
    2. Reduced test complexity
    3. Test entire stack in one shot from the user perspective
    4. Capable of testing any user behavior
    5. Record network and user interaction times for front-end optimization
    6. Easier to test earlier and often
    7. Easier to maintain
    8. 10X faster than other Selenium load testing

    Or, in just one line: because it’s purpose-built for DevOps.

    There’s Still a Time and a Place for Protocol-Level Load Testing

    Of course, no single load testing approach is not going to solve everyone’s load testing needs all the time. For example, if you’re trying to test an application that’s not accessible from a browser, the BLU approach isn’t going to work for you.

    Moreover, there are still some situations where you’d be remiss to overlook protocol-level testing with tools like JMeter, Gatling, or API-based test cases. For example, if you want to simulate load against APIs, I’d still recommend running tests that exercise them directly at the protocol level.

    Ultimately, though, it’s important to remember that protocol-level tests can be higher maintenance and use them accordingly. If you have a single click that makes 20 background requests, would you rather wrestle with all the technicalities of scripting that at the protocol level, or have one line of a BLU script that achieves the same business functionality?

    Final Thoughts

    By reducing the complexity traditionally associated with load testing, BLU load testing gives developers and testers a fast, feasible way to get immediate feedback on how code changes impact performance. It’s geared to help people who are not professional performance testers quickly get started with load testing and create load tests that can be run continuously within a CI/CD process—with minimal maintenance. With this new “lean” approach to load testing, any developer or tester can get started with load testing.

    — Tim Koopmans

  • Why your Company Should Load Test

    Why your Company Should Load Test

    The main reason your company should load test its websites and mobile applications is to learn how the site performs so you can improve the user experience and make smart web infrastructure decisions. Sounds obvious, doesn’t it? Above all else, load testing is a learning experience that provides a wealth of insight into how your website performs from both a user experience and technical perspective.

    How can it be done? Running a load test involves creating a small or large number of virtual users via programming script, running a simulation in which those virtual users access your site, and gathering information about how well the website performs under the traffic load.

    How Your Website Operates and Why it Matters

    If you are curious to learn more about how your website operates, contact a specialized load test company that offers load tests with up to 50 users for free over a 30-day period. Such a smaller test will provide insight into how well your company’s site performs for a typical user during light traffic situations. Free application monitoring tools often can be downloaded if your business does not already have one.

    Longer load times hurt conversion rates: According to Amazon, every 100ms of page load time latency reduces sales by 1 percent. So your business could be losing out on 10  percent of sales because your pages take a second longer to load. Testers can learn all sorts of interesting things about how a site operates with varying virtual traffic loads.

    Primarily, the load test tells you how long it takes a page to load on your site for users at different traffic levels. You can find out how quick load times are during normal, peak, spike and overwhelming use rates.

    The load time data helps identify not only problems in your website code that could be slowing down individual pages, but also problems with the infrastructure itself. Load testing lets your business know exactly how much load times increase when the site gets busy relative to normal use. The tests also can determine how much traffic a site’s infrastructure can handle before load times get outrageously high—and when the site will crash.

    Proximity Performance

    A load test provider can offer testing from server locations all over the globe. A guest in Chicago visiting a site that is hosted in New York City may have fast load times, but Los Angeles-based visitors may have to wait an extra second for pages to load. This data can help your company make an educated decision when purchasing a content delivery network (CDN) service that mirrors content, so site guests farther away from the original host server have a better experience with your site. Look for a load test provider that can offer synthetic load traffic of up to 500 Gbps bandwidth and a million concurrent virtual users. Loads should be generated to your breaking point, and fast!

    Get the Ideal Amount of Power and Learn How to Scale

    Once your business is able to see how your site performs under various traffic loads, that information can help determine where the infrastructure needs upgrades at various traffic levels. This helps with capacity planning—the ability to scale different infrastructure elements to meet demand without wasting money on power that is not going to be used.

    Running load tests on your company’s site will teach you invaluable information about how your site works so your customers can have a better experience with your platform. Improved website performance equals improved business.

    About the Author / Sven Hammar, CEO, Apica

    SvenHSven Hammar is co-founder and CEO of Apica, a provider of powerful, best-in-class technology for testing, monitoring, and optimizing the performance of cloud and mobile applications. Mr. Hammar he has decade-long experience and expertise in web performance and web optimization, e-commerce, cloud services, IT entrepreneurship and the Internet. He is also a serial entrepreneur who has founded several successful IT companies over the years.


  • SaaS: Building Tools for the DevOps-Minded

    SaaS: Building Tools for the DevOps-Minded

    DevOps, Continuous Delivery, Continuous Integration and Continuous Testing are no longer just methodologies and development strategies — they’re all a part of a growing economy within the tech industry.

    Great Software-as-a-Service (SaaS) companies such as Chef, Docker and New Relic have done an amazing job of spotting the trends early and building their tools and services around a new wave of development processes. Chef and Docker alone have reportedly raised nearly $250 million, and New Relic went public in 2014.

    In fact, this very website is another example of how impactful these new development practices are — as several specialized news outlets have been born out of these revolutionary development strategies. So, not only has the DevOps methodology helped developers create better products, faster; but the process has opened opportunities for technical experts to share their experiences on sites like this, e-books, webinars, conferences and any other way people communicate.

    On staging-devopsy.kinsta.cloud, you’ll see the best articles on the web discussing how DevOps is defined in different organizations, why Fortune-500 companies are shifting old practices toward CD and the best practices of CI from industry experts.

    In the race to be the most DevOps-friendly solution — no matter the niche — hundreds of startups have been founded and funded, which has only enhanced the toolboxes of thousands of developers. You’d be hard-pressed to find a good SaaS company that doesn’t offer integration with Jenkins CI, TeamCity or Chef, and that’s because not only should a SaaS product solve an important problem, but it should have minimum disruption of your current development process.

    With all that in mind, Continuous Testing is one of the most exciting spaces in technology today. Continuous Testing is a process that aims to synchronize testing and QA with dev and ops, which ultimately yields better products more quickly.

    There are several factors that make Continuous Testing successful in a team’s software development lifecycle — such as open-source collaboration solutions, test automation APIs and tools to track the historic performance of applications .

    With the release of Load Impact Version 3.0, the global performance and load testing SaaS company has announced its latest feature that fits right in with the DevOps mindset: Performance trending.

    Performance trending allows users to plot runs of the same test over time. That gives companies a clear view into data that locates patterns of performance degradation or improvement in order to easily validate code and infrastructure changes.

    In the spirit of Continuous Testing, DevOps, CD and CI — performance trending improves users’ ability to gain both a low-level and high-level view into the performance of their systems. And with the increased number of tests run by DevOps professionals, performance trending yields valuable information for companies concerned with their application performance — which should be everyone.

    Between staging-devopsy.kinsta.cloud and plenty of great conferences and meetups around the world, it’s safe to say this economy of DevOps-minded tools will only continue to grow in the coming years.

  • The Business Value of Continuous Testing

    The Business Value of Continuous Testing

    ***This post is based on themes and ideas from the great e-book, “Continuous Testing,” by our friends at Parasoft.

    Enterprise software development models have presented many innovative solutions for IT to align development efforts with business goals.

    Adopting new software development lifecycle methodologies is as much a business decision as an IT decision. From an IT perspective, this means the ability to produce profitable products at lower cost without compromising quality.

    Maintaining quality through the code changes to add features and push new releases has been a struggle until the inception of the DevOps-driven Continuous Testing model, which transforms costly, time-consuming IT practices into profit centers.

    The DevOps Patch to Agile Pitfall

    Having already adopted lean Dev and Ops strategies, Agile enterprise IT seems to have unlocked unprecedented efficiency and productivity by delivering better business value at a rapid pace.

    But in all the mayhem and chaos in jumping on the bandwagon of the Agile development, IT teams ended up stockpiling a mass of false assumptions.

    Simply implementing Agile processes and iteratively adding functionalities doesn’t necessarily streamline development.

    With this approach, teams ultimately ignored the true Agile philosophy of adapting, collaborating and planning, and ended up following an accelerated and reinvented version of Waterfall in hopes to develop fast, deliver early and manage issues effectively.

    A change was needed somewhere between design and development, and release and production phases where IT teams were failing to identify software defects and perform fixes fast enough.

    The lack of early, adequate, parallel and continuous testing was transforming IT into a cost center by drawing unnecessary expenses and time investments in reworking software to meet desired quality standards.

    The DevOps approach aims to address this challenge by facilitating continuous testing as an ongoing effort to identify and fix software defects early and deliver the right quality at the right time at the right cost.

    Continuous testing presents the following value propositions to raise business bottom line and open doors to unprecedented revenue opportunities:

    Informed Decision Making

    Business expectations about the reliability and speed of application delivery vary throughout the SDLC.

    Continuous Testing creates a centralized system identifying failures and defects that present business risk to the organization.

    Continuous Testing as a consistent effort provides adequate visibility and useful, real-time data. This can be a huge advantage to businesses, especially when it comes to application performance monitoring and testing.

    The assessment of stability and validity of software builds enables Ops and business decision-makers to trade off decisions between risk and time of release, cost investments, functionality, scope and quality.

    Business Agility and Competitive Differentiation

    Enterprises across all industries have development shops delivering software applications as core components of their service offerings.

    These departments, often driven by DevOps, must focus on churning out new, stable and high-quality software and race to deliver a stream of features that complement primary service offerings.

    For instance, mobile check deposit was a leading driver for bank selection a few years ago and financial institutions offering this online service (while doing it well) early gained valuable competitive differentiation.

    In the DevOps world, Continuous Testing creates a safety net for DevOps teams to develop, test and release new features to the market faster without compromising quality. This safety net works as a trusted testing environment, suite and tool to assess the impact of code changes accurately and quickly.

    With these capabilities, organizations gain the agility to bring new products to market and compete on innovation and not on the scale of business operations and investments.

    All in all, great DevOps levels the playing field between the eight-person startup and the massive enterprise competing in the same space. Who releases faster with a better product is more dependant on the process, not the funding.

    Stronger Business Performance

    IT performance is business performance. It’s measured in terms of the quality, productivity and functionality of IT solutions delivered for internal business operations or as marketable products.

    The primary objective of Continuous Testing is to ensure high quality software products are delivered on time, cost and scope. To achieve these goals, IT teams need capabilities such as automation-driven, self-testing builds in a clone of production environments.

    QA is expected to leverage frameworks and automation tools that allow testing early during the lifecycle. That shrinks time spent on test setup and maintenance, using service virtualization to replicate unavailable testing environments and establishing a comprehensive quality validation process with continuous integration systems.

    These practices work as core elements of Continuous Testing to test faster, sooner, more often and continuously, thereby boosting IT and business performance.

    These business values not only generate unprecedented new revenue streams but also unlock cash trapped within the business IT.

    The resulting increase in revenue encourages organizations to change their game entirely and pursue new DevOps-driven business models in improving service delivery, scaling operations immediately and competing on fronts of business innovation.

  • Releasing your team from Release Thinking

    Releasing your team from Release Thinking

    How much time do you spend optimizing your delivery pipeline?  My guess is none. Many teams have figured out great ways to automate their releases, and some even automate testing and monitoring.  But they don’t often take the next step and learn from those results to refine the delivery processes.

    (more…)