Tag: variable speed it

  • Making Over the Mainframe for DevOps

    Making Over the Mainframe for DevOps

    Introduction

    As a discipline, DevOps emphasizes mitigating any and all constraints in order to roll out high-quality, high-performance software, faster. Constraints can be man-made – such as lack of communication between developers and IT operations teams – or technical in nature, such as an overcommitted testing environment. DevOps teams are only as strong as their weakest link. Ironically, the strongest computing platform available in the

    world – the mainframe – can be an Achilles heel in DevOps.

    Since the 1990s, the mainframe has been a target of many jokes, being far less “en vogue” than its modern, distributed architecture counterpart. But the reality is, no computing platform comes close to matching the speed, reliability, security and cost-efficiency of the mainframe. When managed properly, the mainframe can unleash tremendous competitive advantage as the transaction-processing engine at the heart of modern applications. But if it is not properly evolved and left to languish, the mainframe can quickly rear its head as an unwelcome bottleneck.

    This article will explore the current state of the mainframe; why mainframes have the potential to hamper even the most nimble DevOps teams; and how mainframes must continue to modernize in order to keep up with the pace of DevOps and today’s hyper-competitive application delivery landscape.

    Mobile Means The Mainframe Remains Firmly Embedded

    In contrast to many industry prognostications, the mainframe isn’t going anywhere, due to the unparalleled strength of the platform and the billions of lines of code that dictate much of an organization’s business processes. Consider this:

    • IBM’s new z13 mainframe is capable of handling 100 Cyber Mondays every day, 365 days a year.
    • The volume of CICS (mainframe-based) transactions on any given day dwarf the number of Google searches, Twitter tweets, YouTube views and Facebook Likes combined, according to IBM.
    • Mainframes currently process 30 billion business transactions per day, and enable $6 trillion dollars in card payments annually.

    Most organizations find that moving off the mainframe is too risky, too costly and too time-consuming – and with the technology advances in the platform, just plain unnecessary. Numerous instances have shown mainframes to be more cost-efficient than distributed commodity infrastructures, because reductions in commodity server pricing have not kept up with the growth in computing loads spurred by mobile.

    Mobile computing loads are growing at a dizzying pace. Recent research from the global payments industry shows that more than 27 percent of global online transactions are now conducted on mobile devices. And increasingly, these mobile transactions need to pass through mainframes. Consider a mobile banking application, where users snap a picture of a check in order to instigate a series of steps leading to a deposit. Ultimately, this transaction takes place on the mainframe and must connect through it.

    How Mainframes Can Pose a Challenge to DevOps

    Traditionally, mobile/distributed teams work in very different silos from mainframe teams. Each with their own distinct culture. Unfortunately, the characteristics of mainframe systems can cause an overall software development effort to encounter slowdowns, or even come to a screeching halt.

    As one example, consider a mobile developer working on a hybrid application needing test data that resides on a mainframe. Developers and testers must be able to access test data quickly and easily, in order to adhere to compressed go-live schedules. Any challenges to accessing this data – such as not understanding how and what data flows through the program – leads to unnecessary delays. At a micro-level, this negatively impacts the effectiveness of DevOps. But at a higher level, ongoing obstacles like this can quickly snowball, and in an era where “software defines the business,” the organization’s competitive position can be compromised.

    What’s more, mainframe experts (primarily baby boomers) are expected to retire en masse over the coming years. According to industry research, 55 percent of today’s enterprise apps still touch the mainframe, and more than five billion new lines of mainframe code are being added each year to a base already exceeding 230 billion code lines. A sudden loss in the expertise responsible for this intellectual property can expose a company to major risks, or even disasters, and managing it cannot be left to chance.

    Evolving the Mainframe to Keep Up with DevOps

    For organizations looking to distinguish themselves through cutting-edge mobile transactional applications, the mainframe can be a key competitive differentiator. But in order for this to happen, it must be continually nurtured and non-mainframe trained resources must be enabled to support it.

    Over the past year, mainframe ISVs have driven tremendous advances in this area. These ISVs are adopting Agile development processes themselves, in order to help their customers bring the mainframe into the DevOps fold; extend the value of their legacy investments and in the process, become more competitive in today’s fast-moving markets.

    These advances include:

    • Windows-like interfaces and functionalities (for example, copy and paste) on the mainframe: This allows modern developers to work in an environment they’re familiar with, while providing tools that enable them to easily and quickly complete such tasks as dragging and dropping mainframe data from one host to another. Mainframe-specific expertise is no longer required to complete simple tasks.
    • Program and data visualization on the mainframe: These capabilities enable developers – both mainframe and non-mainframe experts – to better understand program and data interdependencies; find and fix mainframe code issues and build the highest quality mainframe code possible.
    • Insights into the performance of code created with the world’s most common programming languages, such as Java: Java developers can truly “write once and run anywhere,” including the mainframe, and ensure the smooth connectivity of applications traversing numerous platform types.
    • Visibility into the often-complex interactions between mainframe programs: This makes it easier and faster for developers to understand, modify and troubleshoot even the oldest, most complex and/or poorly documented mainframe code. Developers can shave days or even weeks off mainframe software updates, while reducing unintended mistakes.

     Conclusion

    When barriers to enabling DevOps on the mainframe are removed, the positives benefits extend beyond creating a more agile DevOps team. Newer generations of developer talent become attracted to mainframe careers, drawn in by the prospect of working on the some of the most exciting, new mobile transactional applications that feed the world’s economy. And with everyone working in a common, visual, intuitive and modern environment, the knowledge transfer between newer developers and more experienced generations of mainframe experts becomes more fluid and seamless, protecting much of a company’s DNA – its mainframe code.

    The mainframe has a very real place in modern application delivery and DevOps. However, mainframe users require support in bringing fast and agile DevOps best practices to bear on their mainframe-resident applications. With new advances, the mainframe can successfully evolve from yesterday’s computer, to an innovation engine suited to modern DevOps teams.3

    About the Author/Chris O’Malley
    Chris OMalley2Chris O’Malley is CEO of Compuware. With nearly 30 years of IT experience, Chris is deeply committed to leading Compuware’s transformation into the “mainframe software partner for the next 50 years.” Chris’s past positions include CEO of VelociData, CEO of Nimsoft, EVP of CA’s Cloud Products & Solutions and EVP/GM of CA’s Mainframe business unit.

    Follow Chris on Twitter: https://twitter.com/chris_t_omalley and LinkedIn: https://www.linkedin.com/in/christophertomalley
  • The Art of DevOps

    The Art of DevOps

    This is the third in a series of posts on DevOps. The first written by my colleague Lee Reid was titled The Simple Math of DevOps. The second The Calculus of DevOps was written by IBM client, and my friend Carmen DeArdo of Nationwide. Lee introduced mathematically improving delivery throughput by leveraging DevOps to improve Trust. And Carmen used Calculus to imply that the business value of IT can be improved by adopting DevOps to increase the frequency of releases. In my post I would like to visit the art of DevOps , or the art of adopting DevOps by picking up right where Carmen left off – by looking at the culture side of adopting DevOps.

    Lee and Carmen have already alluded to some basic premises behind DevOps as an approach – reducing batch sizeand improving collaboration. These result in reducing complexity, increasing throughput, and improving trust. Let’s talk about how to get there.

    As I have worked with customers adopting DevOps, across company sizes, across industries and countries, there are four common threads that make DevOps adoption successful, leveraging all three aspects of DevOps adoption – culture, process and automation. These are:

    1. Reduce batch size: The most effective way to manage risk and quality, while increasing speed is to reduce the batch size in each iteration or ‘sprint’. This is a mind shift to release smaller, more frequent new versions. Where it is not possible to release new versions that frequently to customers, release small batches to a pre-production area. The deliverable in pre-production is tested and made customer-ready, and then released to the customer at formal release dates. As Lee and Carmen have both discussed, reducing batch size is a pre-requisite to improving both trust and business value.
    2. Shift-left Operational engagement: Get operations engaged right from the beginning of a project/initiative. This has been a core principle of DevOps. Do not leave Ops in a silo that one throws code over the wall to, but have them engaged in the development process, right from requirement inception stage. This allows Ops to have visibility into what is coming from Dev; allowing them to deliver the right production-like environments, as and when needed to Dev and Test teams. It also allows Ops to shift operational concerns left, left into the minds of developers, making them more Ops conscious and engaged in what happens after they hand-off to Ops.
    3. Continuous funding: This is a significant change in an organizations funding model to enable continuous availability and engagement of SMEs and business functions, previously not engaged on a continuous basis – like security, legal, marketing, etc. Carmen in his post mentioned several examples of ‘waiting for…’ work, someone else to do something and environments. Another ‘waiting for’ in enterprises is for funding. Funding is typically provided in a waterfall manner, with specific hard dates (Months, quarters, fiscal year) and gates, not suitable for a Continuous Delivery model. Funding too should be continuous.
    4. Create a ‘Product Management’ team: This team includes a Designer, Development lead, operations lead and an Architect at the minimum (4-in-box). They own the ‘product’ through its entire lifecycle, and beyond transient projects. They are responsible for long-term thinking, design thinking, evolutionary architectural thinking, and overall ownership of the product, from concept to end-of-life.
    5. Setting up a DevOps Center of Excellence (CoE): This center of excellence is not an administrative organization or a ‘tools/enablement group’, but a place where DevOps adoptees come to learn from each other and share expertise and lessons learnt. As organizations adopt and scale DevOps adoption, this CoE also becomes a source of DevOps coaches, helping teams and programs adopt DevOps, and own the organizations DevOps framework – their own flavor of DevOps.

    Adopting DevOps is an art. It is not as simple as hiring a consultant who can show how to improve processes; it is not just buying and adopting tools to automate manual tasks; and it is not going through ‘fall-back-into-the-arms-of-the-person-behind-you’ exercises to build trust. It is a combination of all three – process improvement, organizational and cultural change, and automation with tools to replace manual processes. Adopting these in any enterprise, outside of startups, requires overcoming organizational inertia. By changing culture not by edict, but by showing the need and value of change. By building trust, not through meetings, but with improved communication and transparency. By improving business value, not by measuring mandated KPIs, but by improving organizational agility and throughput. Overcoming organizational inertia, by delivering towards a common goal for the business, irrespective of where in the organization one is, and what role one has. By developing a culture where everyone takes responsibility of delivering value to the business.

    Watch the webcast series hosted by staging-devopsy.kinsta.cloud in partnership with IBM or download a copy of DevOps for Dummies book for more information.

    About the Author/ Sanjeev Sharma

    SanjeevSanjeev Sharma, CTO and Distinguished Engineer – DevOps Technical Sales and Adoption, IBM Cloud Unit, is a 20-year veteran of the software industry with expertise in DevOps, Mobile Development and UX, Lean and Agile Transformation, Application Lifecycle Management and Software Supply Chains. He is a DevOps Thought Leader at IBM and speaks regularly at conferences. He has written several papers and is the author of the DevOps for Dummies book.


    Contact Sanjeev on linkedintwitter

  • The Calculus of DevOps

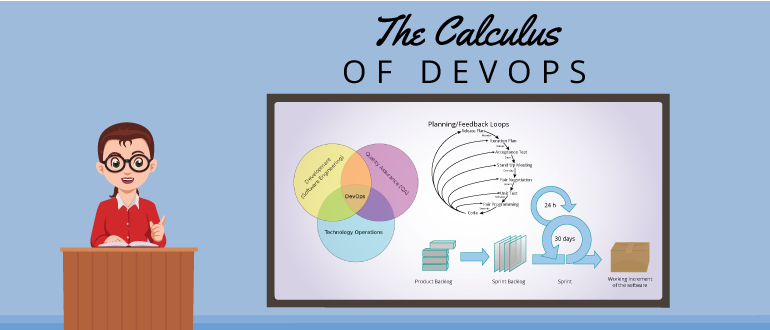
    The Calculus of DevOps

    This is the second in a series of blogs, partnering with Lee Reid, who wrote the first installment “The Simple Math of DevOps” and Sanjeev Sharma both of who are outstanding DevOps Thought Leaders from IBM.

    I am picking up on Lee’s mathematical DevOps model to apply a calculus perspective, a “calculus of DevOps” if you will, (OK, not quite core Big Bang Theory Calculus but rather approaching it from the aspects of engineering queuing theory).

    One of the cultural challenges that DevOps poses is, that some aspects of it run counter to engineering principles that many of us learned with respect to capacity and response time.   When I worked at Bell Labs, we would apply queuing theory to determine how to best package information to be sent across the network. A basic premise revolved around a tradeoff between throughput and response time. On one hand, the more messages that were packed into the packet, the more the payload would improve capacity because the overhead of processing the packet of information would be spread across the messages.   However, waiting to accumulate enough call processing information meant that the packets would be transmitted less frequently, increasing the response time.

    A simple example of this would be making trips to the grocery store. If one wanted to spend the least amount of resources (time, gas, car wear, etc.) on shopping, then one would make less frequent trips and then buy a larger amount of food. So if the Smith family made one trip a month and spent 2 hours, then their average time per week spent on shopping would be 30 minutes.   If the Jones family went every week and spent an hour, then they would be spending twice the time and four times the gas on grocery shopping. However if the Smith family run out of an item (say cereal), they would have to wait, on average 2 weeks before this was replenished. The Jones family average on any item that they ran out of would be 3.5 days in comparison.

    So when the 2014 DevOps report was published[1] which states that areas that deploy more frequently get customer feedback more quickly, that is to be expected. But what’s not expected is that these organizations also have higher productivity.   So exactly what is happening here that seems to be in a basic conflict to the principles of throughput and response time?

    Keeping up with the JONESES

    If we think of a pre- DevOps state for a medium to large enterprise, it may be typical for applications to only be released (deployed into production) a few times a year to provide business functionality. (I assume there are more frequent releases for “unplanned work” like defects and other changes or operational work). For the sake of this discussion, let’s call this the Smith Application. So from a business perspective, the business wants to pack as much work into the Smith releases as possible given they only have a few cracks a year at getting new business functionality into production.

    SMITH APPLICATION CHARACTERISTICS:

    • Deliver Business Value 3 times a year (every 4 months)
    • Cost is C1
    • Business Value (BV) delivered is V1
    • Average time from concept (e.g. Story) being ready to be pulled from the backlog to the time it is delivered to the customer is 2 months plus any additional wait times (e.g. prioritization)
    • BV delivered per year is 3*V1
    • Cost per year is 3*C1

    Now let’s transport over to the Jones Planet where the application is released into production with new business capabilities at the end of every 2 week iteration.   In this case the business is more concerned with providing a constant demand flow into IT than they are with debating over whether a given feature/story is going to be included in this particular release.   Instead there is a constant prioritization (or continuous planning) process that ensures the highest value work is being fed into the IT pipeline.

    JONES APPLICATION CHARACTERISTICS:

    • Deliver Business Value 26 times a year (every 2 weeks)
    • Cost is C2
    • BV delivered is V2
    • Average time from concept (e.g. Story) being ready to be pulled from the backlog to the time it is delivered to the customer is 1 week plus any additional wait times
    • BV delivered per year is 26*V2
    • Cost per year is 26*C2

    Based on the previous engineering analysis, we would expect the following:

    1. SMITH annual cost (3C1) < JONES Annual Cost (26C2)
    2. SMITH annual BV (3V1) > JONES annual BV (26V2)

    So the tradeoff (we would believe) JONES is making by delivering more frequently is that they are spending more money and are delivering less business value on an annual basis.

    However the data from the previously referenced DevOps report is just the opposite. In fact the findings are that enterprises that deploy smaller units of work more frequently have much higher quality and much higher productivity (Capacity). So what’s going on here?

    A NEW PARADIGM

    If you go up to any IT team (even an agile one) and ask them why they don’t deploy business value more frequently, they will generally refer to the following types of wait states of waste that they encounter:

    • Waiting for work (lack of consistent flow)
    • Waiting for somebody else to do something (dependencies from other teams)
    • Waiting for environments (contention)

    One major root cause of this is the dependencies that arise from large enterprises packing a lot of work into infrequent releases. From a planning perspective, the process is elongated due to prioritization discussions because being on the wrong side of the line can mean delay amounting to months, in delivering a product to a customer.   Ask a business portfolio leader what their highest priority is for IT and I am guessing they can tell you in a matter of seconds. However, most large organizations can spend several months a year planning their annual portfolio of work for IT. Some organizations spend more than 50% of their new project build time prior to a single story entering an agile development team’s backlog!

    From a development perspective, packing a lot of work into releases means many more dependencies that have to be managed across initiatives and impacted applications. From a testing perspective, downstream environments (ST, UAT) have to manage much more information in terms of application versions and especially test data that complicate and slow down the process. The complexity of test data increase is proportional to the number of pairwise relationships that exist within the datasets required for testing.   As such, the testing complexity will increase non-linearly (perhaps proportional to the square of the dependent systems) and from a release and change perspective; there is a lot of coordination necessary given how much is being changed at one time.

    All of this work to manage all of the dependencies found in medium to large enterprises completely eliminates any potential savings one might get from batching work into a single delivery. In addition, the possibility of having to pull some work out of a release (due to quality or business readiness or some other reason) sometimes leads to complicated source code management (feature branches in some cases) that further complicate the process of merging frequently into the trunk. These types of practices also serve to drive up technical debt. So looking at the problem from this angle shows why results we are seeing make perfect sense.

    Productivity is inversely proportional to the number of dependencies in a release

    As Lee related to in the initial blog, a lot of an organization’s success depends on trust. And one factor of trust is clarity which speaks to understanding the changes that each release is bringing to the IT and customer environments. So a factor that is working against trust is the notion of delivering more things less frequently and better controlling change somehow, is a good notion.

    Trust is inversely proportional to the number of dependencies in a release

    There is another hidden component of waste associated with “big bang” initiatives. Go back to our grocery example for a moment. Chances are that the Smith monthly excursion results in buying some stuff they end up not using. Perishable items are not spread out very well when they aren’t purchased more frequently. Likewise in IT planning, we tend to put a bunch of stuff in our IT Delivery basket that we don’t know for sure that we will need and we end up with a lot of wasted effort for features that are hardly used or not needed at all. Some enterprise estimates are that 50-65% of what they put into large releases does not actually result in true value to the business. Doing more frequent releases allows a constant discovery process to better guide the usage of IT resources on what is truly of value.

    Waste is proportional to the size of a release.  

    In other words:

    Yield (Value per IT investment) is proportional to the frequency of releases.

    REVISTING THE MATH OF DELIVERY TIME

    So if we revisit Lee’s model

    Lee Reid Blog equationand apply the “Calculus of Release” as we stated above, there are increased costs associated with having larger and less frequent releases in medium/large enterprises.

    • Planning cost TPLAN
    • Development complexity TDESIGN + TDEVELOP + TBUILD
    • Testing Complexity TTEST
    • Release and Change Management Complexity TRELEASE + TDEPLOY + TEVALUATE

    TRUST % – Even if everything was proportional between the JONES and SMITH models, the component of trust that impacts clarity, consistency and collaboration, is much lower for large (SMITH) releases.  Given that TRUST has a multiplicative impact, this alone can account for the results found in the studies.

    CULTURAL CHALLENGE

    While clearly one needs to be sensitive to the changes being introduced into the business, having the ability for the business stakeholders to pull capability when they want it and having it available more frequently is not only good for customers but also has extreme benefits from an IT perspective in terms of increased productivity and reduction of technical debt. The challenge is to convince leaders in both the business and IT areas on the merits of doing more continuous planning and frequent deliveries.   Unicorns may have led the way in this type of thinking but it is actually the horses that will benefit most from this type of culture shift because it is the horses[2] that have the most to gain in mitigating the dependency factor which can undermine quality, productivity and cycle times.

    Read more about the topic in the next blog of this series The Art of DevOps by Sanjeev Sharma.

    [1] “2014 State of DevOps Reports”, Puppet Labs, IT Revolution, https://puppetlabs.com/sites/default/files/2014-state-of-devops-report.pdf

    [2] “The Phoenix Project”, Gene Kim, Kevin Behr, George Spafford, http://www.amazon.com/The-Phoenix-Project-Helping-Business/dp/0988262592


    About the Author

    CarmenCarmen DeArdo is the Director of Application Development Tools and Technologies at Nationwide Insurance. Carmen is responsible for driving continuous delivery utilizing DevOps, Lean and Agile techniques across Mobile, Distributed and Mainframe and other technologies. This includes recommendations and implementation of technologies used across the development life cycle (e.g. IBM Rational tool suite, open source technologies).

  • The Simple Math of DevOps

    The Simple Math of DevOps

    We are living in an information- infused society, much dependent on various technological innovations taking place all around us. In such conditions, as consumers become more connected, they are empowered with more information and choices. They expect quick and consistent information available at all times. Likewise, our business leaders expect their IT teams to build relevant applications and stay ahead of their customers’ needs with an excellent customer experience.

    My IBM colleagues and I have been working very closely with major enterprise clients as they begin their DevOps transformational efforts. We’ve found few key points and messages that resonate very well with decision makers who need to set a new course for their teams in the wake of impact from mobile, big data, analytics, cloud, and the Internet of Things technologies.

    So what is it about DevOps that is so appealing? First and foremost is the notion that DevOps is all about attaining Speed to Value. Speed is king right now because so many of the business leaders we work with are under the gun to deliver value as quickly as possible. Yet, because of the high cost of technical debt they have come to a state where speed has to be sustainable. It’s no longer easiest to go outside their organizations for the high priority key projects as mobile applications were done recently. They need a holistic approach that builds on their existing capabilities.

    Well what does that have to do with math? Here’s the thing, everyone is trying to minimize the time it takes to deliver value and attain feedback.   We can think of the Time to delivery as the following equation.

    TDELIVERY = TPLAN + TDESIGN + TDEVELOP + TBUILD + TDEPLOY + TTEST + TFIX + TRELEASE + TEVALUATE

    In an optimal world or software factory that is fully automated the TDELIVERY is optimized by minimizing the time for each of the tasks required to complete the delivery. Most organizations follow a SDLC that is based on this simple math. They estimate the time to do each part and then the total project plan is the sum of the parts. Further, they tend to define work in relatively large chunks or big-up-front style of work definition which inherently increases the time for each task (TX). As a result, the industry has about a 50% (or worse) failure rate when it comes to completing a project within the estimated time. That causes a lot of hardship because the business can’t count on IT to deliver value to customers in the projected time frames let alone with speed.

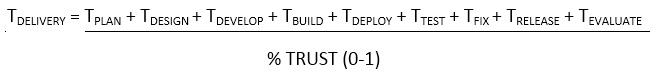
    Because application delivery is a set of very human oriented tasks, a key factor that will determine the speed to value is TRUST. It’s pretty obvious when you draw out the value stream mapping of how work gets done at a given customer site. As members of software delivery teams lose trust in the validity of the work as it flows through the lifecycle then a large amount of rework and waste is introduced. In mathematical terms our equation becomes:


    Lee Reid Blog equation

    That is, the Tasks we do in a delivery cycle are impacted by the degree of trust we have in the hand-offs from one to another. If we have zero trust then our TDELIVERY will be infinite (divide by zero). 100% trust and our TDELIVERY will be only limited by how fast each task can be performed.

    Check this scenario that represents what we’re hearing from our clients in the workshops:

    “On a given project team the plan has about a 50/50 chance of being right, and the design is about 85% right, and the developers will get about 90% of the implementation right, and the testers have about 90% of the test cases right, and the release team has about 95% reliability of having the right stuff together to release, then your trust factor is something like

    .5 x .85 x .9 x .9 x .95 = 32% Trust”   (and that’s much better than what we usually hear)

    Ouch! That’s a 3x multiplier of the time it’s going to take no matter how fast we do all the delivery tasks.   In other words, we’re always limited by our trust factor. That multiplier comes into play with additional tasks we have to add into the equation to counterbalance the lack of trust. Then our equation becomes something like this:

    TDELIVERY = TPLAN + TRESCOPE + TDESIGN + TARCH REVIEW + TDEVELOP + TTECH DEBT + TBUILD + TREBUILD + TDEPLOY + TREWORK + TTEST + TRETEST + TFIX + TREFIX + TRELEASE + TROLLBACK + TRE-RELEASE + TEVALUATE

    And that’s the issue our customers are facing today. There are a lot of wasteful tasks, checks, and balances that have crept into our delivery process due to lack of trust.

    So, how does DevOps help this problem? It’s simple really; the DevOps approach is to attack the TRUST issue head on while simultaneously reduce the task time (Tx) in order to shorten the overall time to delivery. For example, if we apply a DevOps practice of breaking work up into small chunks, getting it out to users early, and getting the feedback, we can immediately impact the overall TDELIVERY. That’s because we’re positively impacting the numerator and denominator with that practice. That is, by limiting the scope we make it easier to understand, less effort to transform to working code, test, and deploy, sooner to obtain feedback, and more likely to know if we’re on the right track.

    Likewise for other practices!

    The key is finding the balance of what practices to apply to maximize this equation for a given organization and their current bottlenecks & wastes.

    DevOps practices address with three main impact points:

    Speed to Value depends upon TRUST

    TRUST is enabled by:

    1. Clarity: A clear definition of desired outcome(s)
    2. Collaboration: Team-wide communication and visibility
    3. Consistency: Systematic and repeatable steps

    When a team can master these three elements the time to perform each task will shrink and degree of TRUST will increase. DevOps practices impact these trust building elements:

    Clarity:

    • Break work up into smaller chunks and iterate
    • Seek a minimum viable product (MVP)
    • Define clear outcomes, ‘sponsor’ users, and playback (Design Thinking)
    • Reduce dependencies with loosely coupled architectures (containers, micro services, SOA)

    Collaboration:

    • Form cross functional teams (end to end)
    • Use big visual radiators
    • Have a ‘single source of truth’ for all development assets – Requirements, Code, Deployable Assets, Infrastructure as Code, etc
    • Be transparent with metrics
    • Plan and reprioritize frequently
    • Actively seek user feedback

    Consistency

    • Automate, automate, automate
    • Continually improve by replacing manual tasks with automation


    Speed to Value will be enabled by eliminating those bottlenecks and waste that have developed due to lack of trust. The key for organizations is to recognize that the current practices are maxed out and not sustainable when trying to move at higher speed. There’s a perfect storm amassing with big data, analytics, cloud, mobile and IOT that will either drive customers to make a DevOps transformation quickly or be a victim of the storm. Try using this simple math to help organizations understand how to move ahead and how our IBM solutions can be applied to attain speed to value.

    This year I have had the great experience to work with our DevOps CTO Sanjeev Sharma, our customer thought leaders such as Carmen DeArdo of Nationwide, and our field teams around the world addressing DevOps transformations. Sanjeev, Carmen and I decided to summarize our experiences in a three part blog. This is the first of that three part series.

    To learn more about IBM’s DevOps approach, check out www.ibm.com/devops. Also, watch the replay of a recent webcast on Variable Speed DevOps, I had a chance to present on, with Sanjeev Sharma and Carmen DeArdo.


    About the Author/ Lee Reid

    Lee ReidLee Reid, Senior IT Specialist, IBM, is a senior solution architect with focus on practical adoption of software engineering tools, software delivery solutions, application life cycle management, and DevOps. He has over 25 years of experience in software engineering, design, programming, testing, development, tools & methodology, team leadership, and strategic planning.

  • Variable Speed DevOps: A Deep Dive

    Variable Speed DevOps: A Deep Dive

    About 2 months ago I wrote an article on “Variable Speed DevOps“.  To be clear I first heard the term used by Carmen DeArdo, Director of Application Development at Nationwide.  It was a response or play on the 2 Speed IT dilemma. In 2 Speed IT, emerging digital processes coexist with traditional ones. The implication is that the “traditional” processes can’t run at the speed of the emerging digital ones (even older digital can’t run at the speed of newer digital processes). But the question is do they have to?

    According to Carmen and other folks I have spoken to, the key is not making processes run faster than they are intended to. It is blending all of the different processes and the speeds they run at to mesh together into one finely tuned machine. Like the different size gears within a Swiss watch, perfectly tuned to keep the correct time down to the millisecond. Variable Speed DevOps is about the fine tuning of an organizations IT machine to make all of the different size and speed gears work flawlessly.

    Of course this could be much easier said than done. Carmen has spoken about Nationwide’s journey in this regard. I have also had the pleasure of participating in a Google Hangout with Carmen, Sanjeev Sharma and Rosalind Radcliffe of IBM where we discussed this concept as well.

    The notion of Variable Speed DevOps existing in Enterprises with traditional Systems of record, co-existing side by side with new Systems of engagement and code is destined to be as dominant in the world of DevOps within enterprises as Hybrid Cloud is going to be the dominant form of Cloud.

    I believe that the idea of Variable Speed DevOps deserves a deeper look. There is much that we can learn and share by delving deeper into the concept and hearing from experts who are on the front lines of Variable Speed DevOps.  To do this we are teaming up with our friends at IBM to peel back layers of Variable Speed DevOps and show you how you can bring it to your organization.

    We will be kicking of our deep dive into Variable Speed DevOps with a series of webinars, the first of which we are announcing today. I will personally be hosting these webinars. What better place to start our deep dive than with Carmen DeArdo and Sanjeev Sharma. We will feature other guests in future webcasts.

    Part 1: May 5 – How Nationwide Insurance is adopting DevOps for variable speed IT systems
    In the May 5th webinar, we will focus on the ongoing transformational journey at Nationwide Insurance and lessons learned. (Replay available)

    Part 2: May 19 – Canada Mortgage Housing Corporation breaks down IT silos and speeds up mainframe development
    In the May 19 webinar, we will focus on lessons learned at the Canada’s national housing agency in their DevOps and Agile transformation. (Replay available)

    Part 3: June 2 – Show Me Success Before I’ll Invest in DevOps – A HM Health Solutions Case Study
    On June 2 we will discuss the process for quantifying DevOps benefits for your business stakeholder. (Replay available)

    Part 4: June 25 – Build, test and deploy mobile apps with back-end mainframe services securely in a hybrid cloud
    On June 25 we will look into synchronizing mainframe, mobile and hybrid cloud to support end-to-end mobile development. (Replay available)

    Besides the webinars, we will also feature articles and other content related to the topic.  We will build up this new section of our site over the coming weeks, so stay tuned.  But wait there is more. We want to hear from you! What is your view on Variable Speed DevOps? Do you have any lessons or thoughts on the subject? If so you can write me personally at editor@devops.com.  I would love to hear from you. We can have you write your own post on this, we could interview you for a future article or maybe you could be a guest on a future webcast.

    Variable Speed DevOps is going to be important in your DevOps Journey.  Join us on May 5th to hear from Nationwide Insurance and stay tuned for additional client stories on this topic.