Author: Mike Vizard

  • Tabnine, GitLab Build Custom Apps Faster With AI

    Tabnine, GitLab Build Custom Apps Faster With AI

    Tabnine today revealed it has integrated its code completion tool with the GitLab continuous integration/continuous delivery (CI/CD) platform. Tabnine’s platform employs artificial intelligence (AI) to accelerate application development.

    Brandon Jung, vice president of ecosystems and business development at Tabnine, said the goal is to make it easier for developers to automatically write code based on custom models created using AI. Those models would reside in the CI/CD platform provided by GitLab. Developers can now create custom models of their private source code, he noted.

    The Tabnine AI assistant can then be trained on a customer’s private code, style and security best practices that have been defined by an internal DevOps team, added Jung. That assistant, accessible from within a developer’s integrated development environment (IDE), is conversant in 35 programming languages.

    The code completion tool doesn’t eliminate the need for developers to write code; instead, it completes code once developers start writing it based on the model stored in the CI/CD platform.

    Nima Badiey, vice president of global alliances for GitLab, said the overall goal is to increase developer productivity at a time when organizations are launching more application development initiatives than ever. Many of those applications are being constructed using multiple programming languages that each individual developer may not have equally mastered.

    In addition, an AI model will, over time, improve the quality of the code being created, noted Badiey. That should make it easier to review code that is more accurate because it was created with the aid of a machine, he added.

    In general, GitLab has been moving to incorporate AI within DevOps workflows. The company last year acquired UnReview, a provider of a tool that uses machine learning algorithms to identify which code reviewers to assign to a project based on both the quality of their previous efforts and their current workloads.

    It’s not clear to what degree AI will be pervasively embedded within DevOps workflows. However, it’s now just a matter of time before algorithms are more widely employed. Organizations that employ DevOps today devote significant resources to maintaining platforms that could be simpler to manage if more tasks and processes were automated. In theory, more resources could be then devoted to building applications versus maintaining DevOps platforms.

    One way or another, more organizations are moving to increase developer productivity. Developers are both hard to find and retain, so organizations have a vested interest in finding ways to increase the rate at which an existing pool of developers can build applications capable of driving a wider range of digital business transformation initiatives. Of course, an increase in the rate at which applications are developed also has significant implications for the rate at which they might need to be deployed.

    Not everyone in IT is, of course, entirely comfortable with AI. Nevertheless, most DevOps organizations are highly committed to automating as many processes as possible. The only thing that will be different going forward is determining to what degree those processes will be automated by humans versus a machine.

  • Linux Foundation Lists Top Open Source Libraries

    Linux Foundation Lists Top Open Source Libraries

    The Linux Foundation today published a report that provides access to eight lists of the top 500 open source libraries being used by organizations as part of an ongoing effort to help better secure software supply chains.

    The Census II of Free and Open Source Software—Application Libraries report is based on usage data from providers of software composition analysis (SCA) tools such as Snyk, the Synopsys Cybersecurity Research Center (CyRC) and FOSSA. The report itself was compiled by the Harvard Lab for Innovation Science.

    The eight lists are made up of four that include version numbers and four that are version agnostic. The lists are separated into npm and non-npm packages because npm packages would dominate any ranking created. The top non-npm packages being employed include maven, nugget, Go and cargo.

    Frank Nagle, assistant professor at Harvard Business School, said the report is intended to provide organizations with some guidance in terms of knowing what open source packages are used in the wake of recent vulnerabilities discovered in the widely employed Log4j software used to manage logs within Java applications.

    Many of the organizations impacted by that vulnerability were unaware of just how widely deployed Log4j was within their enterprise IT organizations. IT organizations should evaluate the sustainability of those projects in terms of the number of contributors and maintainers that are working to ensure the security of those libraries.

    One of the biggest challenges is to find a way to standardize naming schema for software components and the overall management of versions of different libraries, noted Nagle.

    Ultimately, the goal is to convince more enterprise IT organizations—and the vendors that support them—to make more resources available to secure those libraries, noted Nagle. Much of the most widely used open source software is developed and maintained by only a handful of contributors. Many of those contributors argue that, while they made that software available for free, it is the responsibility of the organizations employing it to secure it.

    The Linux Foundation is moving to become a conduit through which it will make available additional resources to help better secure open source software. The Open Source Security Foundation (OpenSSF), a consortium hosted at the Linux Foundation, earlier this week announced that 19 additional organizations have joined OpenSSF to help identify and fix security vulnerabilities in open source software and improve tooling, training, research, best practices and vulnerability disclosure practices.

    Brian Behlendorf, executive director at OpenSSF, said in addition to making resources available, it’s clear there is a need for some form of a third-party audit of open source software as organizations are more broadly employing that software across their software supply chains.

    New premier member commitments to OpenSSF are now coming from 1Password, Citi, Coinbase, Huawei Technologies, JFrog and Wipro. New general member commitments are being made by Accuknox, Alibaba Cloud, Block, Inc., Blockchain Technology Partners, Catena Cyber, Chainguard, DeployHub, Gravitational Inc., MongoDB, NCC Group, ReversingLabs, Spotify and Wingtecher Technology. New associate members include Institute of Software, the Chinese Academy of Science (ISCAS), MITRE and OpenUK.

    Other efforts led by the OpenSSF include an Alpha-Omega Project to better secure open source security posture, scorecards that identify risks of the dependencies within more than one million projects, multi-factor authentication tokens and a Project Sigstore initiative to sign, verify and protect open source code.

    It may be a while before open source software achieves the level of security the IT industry strives for. On the plus side, however, there have never been more resources allocated to achieving that goal.

  • Multi-Cloud Computing is a Major IT Headache

    Multi-Cloud Computing is a Major IT Headache

    A CloudBolt Software survey of 500 senior IT, DevOps, security and finance leaders found 79% are struggling under the weight of managing multiple cloud computing environments.

    The survey from CloudBolt Software, a provider of a cloud management platform, found specifically that more than three-quarters of respondents (78%) said they have too many cloud tools throughout their enterprise, and 80% struggled to achieve comprehensive visibility into cloud usage and spending. A total of 80% also noted that their current approach to cloud computing created new security vulnerabilities.

    A full 88% said they need a “manager of managers” that would enable them to unify the various silos that have multiplied across their IT environment.

    Nevertheless, 78% of respondents said that moving to the cloud enabled them to achieve cost savings compared to running applications in an on-premises IT environment.

    CloudBolt Software CEO Jeff Kukowski said the issue is not so much that IT organizations regret shifting workloads to the cloud; instead, the issue is finding a way to manage multiple clouds, each with their own set of tools and frameworks that need to be mastered.

    It’s not clear whether organizations are deliberately employing multiple clouds or if, because of simple inertia, they have found themselves managing multiple cloud platforms because of decisions made by various development teams. Some IT organizations, for example, employ multiple clouds because they are concerned about either becoming locked into a specific cloud computing service or whether an outage might take all their applications offline at the same time. Others are simply trying to take advantage of services that are better provided by one vendor than another.

    Regardless of how IT organizations found themselves managing multiple clouds, the total cost of IT rises as each new platform is added to an IT environment. CloudBolt Software is making a case for an IT framework that provides a layer of abstraction through which the management of multiple clouds and on-premises IT environments can be unified. It is more a question of time and degree to which IT organizations will eventually consolidate the management of disparate IT environments under a single control plane that provides the foundation for true hybrid cloud computing, said Kukowski.

    There are, of course, a few organizations that have standardized on a single cloud computing platform. The degree to which those organizations can maintain that standard will naturally vary as, for example, new workloads that may be optimized for a specific cloud environment are built or as companies acquire other organizations that are running workloads on other cloud platforms. In many of those cases, organizations discover that the cloud services invoked expose a range of proprietary application programming interfaces (APIs) and disparate virtual machines that make migrating workloads a major challenge.

    Like it or not, most organizations will be managing multiple IT environments for the foreseeable future. The only thing that is uncertain is the volume of workloads that might be running on any one of those platforms at any given time.

  • Tricentis Expands Scope of Cloud-Based Testing Tools

    Tricentis Expands Scope of Cloud-Based Testing Tools

    Tricentis this week extended a suite of cloud-based testing tools that promise to make it simpler to both develop cloud-native and mobile applications and migrate existing applications to the cloud.

    New capabilities added to the portfolio include integrations for cloud-based planning tools and a wider range of testing capabilities for mobile applications. DevOps teams can now, for example, deploy Tricentis qTest platform for managing the testing process within a Kubernetes cluster. Tricentis has also made it simpler to configure and update its Tosca suite of application testing tools.

    In addition, Tricentis added additional capabilities for testing SAP applications running in the cloud that previously were deployed in an on-premises IT environment.

    Martin Klaus, vice president of product marketing for Tricentis, said the goal is to make it simpler for DevOps teams to integrate continuous testing for various types of applications within their DevOps workflows. DevOps teams have the option of invoking the Tricentis suite of testing tools via a software-as-a-service (SaaS) platform or deploying them on a cloud platform themselves using templates provided by Tricentis.

    While developers are clearly getting more involved in testing, Klaus said it’s critical for testing capabilities to be integrated within a DevOps pipeline. Each developer is typically only working on a component of a larger application. Unless testing is conducted on an end-to-end basis, an organization won’t be able to determine the real quality of the application experience before deploying software in a production environment, he noted.

    As a result, the decision about what tools to use as part of a continuous testing process is now being made by DevOps team leaders rather than individual developers, added Klaus.

    Ultimately, the goal is to automate as much of the continuous testing process as possible. Achieving that goal will require increased reliance on artificial intelligence (AI) technologies, though to varying degrees, said Klaus. Those capabilities, however, are not likely to eliminate the need for dedicated testing professionals; instead, AI will enable those teams to more efficiently test increasingly complex application environments, he added.

    In fact, it’s becoming practically impossible for testers to manually inspect every element of an application without the help of, for example, algorithms that apply computer vision to analyze a user interface, noted Klaus. There will always be higher-level tasks that require a human, but AI technologies will play a significant role in enabling testing at scale as organizations start to build more applications, he added.

    In the meantime, it’s clear that there’s a lot more riding on testing as organizations continue to launch digital business transformation initiatives. In many cases, organizations only get one chance to convince end users that a new application being rolled out is better than the processes they previously employed. As such, the need to streamline testing within the context of a DevOps workflow has become critical—there is little tolerance for bottlenecks that slow down the rate at which applications now need to be built and deployed.

  • Merging Secrets Management and Configuration

    Merging Secrets Management and Configuration

    Fresh from picking up $5.25 million in funding, CloudTruth CEO Greg Arnette talks with Mike Vizard on this episode of the View With Vizard about why configuration and secrets management need to converge. The video is below, followed by a transcript of the conversation.

    Announcer: This is Digital Anarchist.

    Mike Vizard: Thanks for the throw. We’re here with Greg Arnette, who’s the CEO for CloudTruth, they just raised $5.25 million to help us with these configuration issues that seem to plague us. Greg, welcome to the show.

    Greg Arnette: Thank you. It’s great to be here, and thanks for the opportunity to tell your audience about CloudTruth.

    Mike Vizard: So, what is the configuration problem, and why does it not seem to wanna go away? It’s been around for a while, things appear to be getting worse, and what’s to be done about it?

    Greg Arnette: Exactly. So, that ties into the history of founding this company. Both myself and my Co-founder were prior CTOs and DevOps leaders for several cloud-based SaaS companies, and we saw that our DevOps teams were continuing to build internal tools to address issues around configuration sprawl and complexity. And these tools tend to be the weak links in terms of solid deployments, good up time, good security, and basically, slows teams down.

    So, the history of kind configuration sprawl and what we see as the challenges is sort of driven by a number of macro trends—first, the fast rise of Kubernetes; everyone wants to get on the Kubernetes bandwagon. That introduces new complexities around configuration management, new sets of tools that haven’t been sort of well adopted inside of DevOps shops. Another trend is the breakup of monoliths to microservices adds lots of new dimensions on configuration complexity. And then there are the traditional needs around provisioning infrastructure, configuring your apps, and managing secrets are the sort of legacy challenges around configuration management. And as the cloud gets more mature and with more capabilities, configuration is not getting easier, but getting more difficult.

    So, CloudTruth is here to address those concerns. We heard, during our product market fit research where I interviewed over 500 cloud and DevOps leaders on their challenges managing configuration, that this over reliance upon tribal knowledge in terms of how a system is configured and why it’s configured a certain way is just held in key team members’ heads, and that’s not a very durable strategy for going forward or for on boarding new folks. So, there’s an element of CloudTruth that provides collaboration and sharing around configuration settings and context to help reduce that need of, or that sort of burden of the cognitive load to keep track of how are things configured, where is the data, how can I change it, what changed recently—that type of thing.

    Mike Vizard: You guys also acquired a company in this process in the secrets management space, so where does configuration and secrets management converge and how do we think about that?

    Greg Arnette: That’s a great question. So, we acquired Tuono, we’re thrilled to bring in the Tuono team, including Jesse St. Laurent, who was the CTO, who joins us as our Chief Product Officer. Jim King, Mike Healey, Mike Stack all joined us, they were the founding engineers at Tuono.

    And what we did was, we took the Tuono secret management engine, which was cloud native and we’ve now included that in the CloudTruth platform which rounds out our offering. So, CloudTruth, while it is also a configuration data hub to synchronize your configuration settings from all these multiple tools is also itself a parameter store and secret store that customers can use if they don’t already have existing parameter stores or secret stores in their environment.

    Mike Vizard: And in that context, what does cloud native mean? Because some will people say, you know, it runs in the cloud; other people will say that it only runs on Kubernetes, it’s optimized for microservices and containers. Or is there some middle ground there and what do we think about cloud native—what context are we using that phrase?

    Greg Arnette: Yeah, when we use cloud native, we mean or refer to the capabilities that are provided as part of core services at Amazon, Azure, and Google. So, an example is, Amazon themselves provide a parameter store, they call it AWS Parameter Store. Google and Azure provide the same kind of internal capabilities. Customers can also bring their own parameter store, like run something like Console on top of the cloud or using Vault sometimes as a general-purpose parameter store.

    So, the cloud native offerings like AWS Parameter Store, Secret Manager, and the equivalent on the other clouds are things that customers can use, they have different price points. We provide a layer of management and visibility and observability to all that config data stored inside of all these different systems.

    Mike Vizard: And when you talk about unifying configuration, are we replacing Terraform and CloudFormation, or are we just finding some way to layer some form of abstraction around them that makes the whole process easier to manage? Walk me through that a little bit.

    Greg Arnette: Yeah, you know, we’re not replacing Terraform or CloudFormation. We’re designed to coexist with the customers’ existing investments and their configuration tooling. So, whether it’s provisioning tools like Terraform, CloudFormation, Pulumi, or app config tools like Ansible, Puppet, Chef, Saltstack, or secret tools like Vault or the cloud native versions of those capabilities. We coexist and become a metadata wrapper around those different tools.

    Now, if customers don’t have some of those capabilities, we have functionality in our platform that can fill the gap, but more and more customers already have these systems in place. They’re not looking to rip everything out and replace it, but they’re looking to address these issues around configuration sprawl that leads to a misconfiguration causing unplanned down time or a security incident.

    Mike Vizard: We have been talking about DevOps and DevSecOps forever, and the idea has always been that we’re shifting more responsibility for the IT environment to the left of the developer. Sometimes they like that, sometimes they don’t.

    But I wonder, are we not approaching some sort of concern or maybe a backlash where folks are saying, “Hey, you know what? This isn’t really working. We have all this misconfiguration out there, we’re maybe running faster, but things are less secure, and we have more risk than ever.” So, is there a balance to be struck, or what’s your sense of where are we on this journey?

    Greg Arnette: That’s a very interesting question. This is something that we hear all the time in our outreach to our customer audience is what their journey looks like for adopting shift left or GitOps types of operating principles. We’ve seen a number of patterns emerge over our hundreds of interviews. Specifically, most teams do want to give developers more capabilities to do things themselves and reduce that burden on the Ops team, but they still want Ops or DevOps teams to have the overall sort of judgment and enforce the guardrails that were put in place by the security and compliance teams and by the other teams that are sort of deciding what are the best practices.

    So, with CloudTruth, we’re kinda serving both audiences in a purposeful way. You have centralized control and visibility that DevOps wants. They wanna build and enforce lockdowns, enforce default settings that can only be overridden with a permission or an override that’s allowed as part of a workflow. But you also provide capabilities for core developers to manage the config for their own environments and to suggest configuration changes that then can be adopted more system wide.

    So, we’re serving that duality that exists today. We’re gonna let the customer decide on where they ultimately land about developing shift left principles and moving that direction. But we see a lot of interest in that, and it helps to reduce that—you know, again, that cognitive load and that context switching on the DevOps professionals. Because so many times, they’re being bothered by other folks and other developer teams, like, “What’s the setting for this Redis cluster? Why is our Mongo configured this way? How do I tune my elastic search test cluster to match production?”

    That information will all be self-serviceable and findable inside the CloudTruth platform. And our role based access control permissioning system allows view only, read only, read/write access to the appropriate areas, and then DevOps teams can sort of wall off the production systems from other people having chances of changing those settings.

    Mike Vizard: Mm-hmm. What is the role of the security team as we go forward? It feels like, if we shift everything left to the developers, what are those guys doing?

    Greg Arnette: They still need to be involved in terms of ensuring that no bad information gets in and no good information gets out. So, we provide a number of views into configuration data that are helpful to security teams. First is, what changed most recently in terms of your compliance management reports for SOC 2 and other requirements and keeping track of changes. That’s really hard in a dynamic environment, especially cloud-based where you have microservices firing left and right, coming up and down. The old traditional CMDBs that were popular in the on prem world don’t really fit well in the new way that we’re using the cloud.

    And so, CloudTruth is a self-documenting change management control system that is, behind the scenes, keeping track of all the version settings of every configuration value that we’re monitoring, and then we provide views into that data that can be consumed by the security or compliance teams to get better insights for their needs without having to bother the DevOps teams.

    Mike Vizard: Do you feel like the bad people, otherwise known as cyber criminals, are getting better at scanning for misconfigurations and looking for these vulnerabilities to exploit? And we hear a lot about software supply chains these days—it seems like, in a lot of cases, the root cause of the problem is just misconfigurations.

    Greg Arnette: It’s true. We’ve found, in our own research, that 75 percent of unplanned down time or security incident was caused by a misconfiguration when you ultimately read the root cause analysis and do all the internal tracing.

    So, what we wanna provide are the best practices as early as possible in the software development life cycle process to implement good config hygiene. And then secondary to that is, once config is out there in the wild, provide monitoring and insight into how it could affect security vulnerabilities or security posture. Since everything these days is defined as infrastructure as code, it’s all about analyzing all the different locations where config values are stored, making sure those are secure and locked down, and then being able to use any kind of pattern recognition to understand where certain areas can be vulnerable to being taken advantage of by the nefarious factors out there in the world.

    Mike Vizard: Do you think we’ll get to the point where we can use automation to kinda get ourselves out of this mess? We have APIs and CLIs and everything else that’s out there—shouldn’t we, at some point, have enough intelligence in the work flows to say, “Hey, this thing you’re about to deploy is misconfigured, so don’t do it”?

    Greg Arnette: That’s part of our goals down the road is, we have a very thoughtful strategy how we wanna launch CloudTruth as a full configuration data management platform. So, the first goal is to get inserted into a company’s work flows where we have access to the data and can provide value with reports and work flows. The second goal is then, once we’re now managing this data on behalf of the customer, to apply AI and ML, looking for patterns, recommending optimizations, best practices, vetting what we see from a customer perspective against best practices being published by other standards bodies that are looking at this from different perspectives.

    One goal of CloudTruth is to be that configuration data layer management system that we think most companies using the cloud need these days.

    Mike Vizard: We also hear a lot about artificial intelligence—will that get applied to this space? Is there any scenario where we’ll just have a bunch of machine learning algorithms running around, figuring out what’s going on?

    Greg Arnette: We firmly believe that that is definitely gonna be happening a few years down the road. I think the maturity model is just getting started. The first act in getting that up and running is getting access to the data for trending the models and analyzing the trending results, optimizing the model. So, a full observe-orientate-decide-act OODA loop is involved here in terms of making sure those models are accurate, but we think that’s gonna be a big benefit in what we can provide down the road.

    Mike Vizard: So, what’s your best advice to folks? What should they be focusing on today to get to that nirvana tomorrow? Is there same way I should be organized, is there some way I should be talking to my developers? What do you think?

    Greg Arnette: There’s a couple themes that come to mind. The first is—which sounds almost obvious these days—is make sure you are able to do infrastructure as code ideas at all levels that you can, and that’s tied into automation. So, it’s a big portion to continuous deployment, CI/CD pipelines. Once you start the development of those types of workflows that accelerate getting what developers are creating out in front of the customers, whether it’s an internal app or external SaaS or mobile app, accelerating that team velocity is really a key element in terms of making that possible.

    The other area is this notion that you wanna implement systems that reduce the amount of copy and paste. So, that’s what we call the Do Not Repeat Yourself, the DRY approach to infrastructure as code management. So, that’s a key theme behind CloudTruth is, we provide capabilities that let you manage your multiple environments with the faults, inheritances, and overrides from a centralized capability, but still allow flexibility in your environment tree to manage certain sub-environments in different ways as needed.

    So, different developers can have their own custom environment, but they’re gonna inherit default values that are sanctioned by the architecture team or the security team. And then the overrides have to be allowed by a permission basis.

    So, there’s a couple sort of themes that are coming together as we go through 2021 around automation, infrastructure as code, shift left, and the DRY approach to managing input values to all the IAC tools.

    Mike Vizard: Hey, Greg, thanks for being on the show.

    Greg Arnette: Thank you very much. Have a great day.

    Mike Vizard: Alright, awesome. Hey, guys, we learned a lot about security there and things we didn’t know and—hey, there’s hope for the future. Back to you guys in the studio.

    [End of Audio]
  • Netlify Leverages GraphQL to Simplify Access to Backend Services

    Netlify Leverages GraphQL to Simplify Access to Backend Services

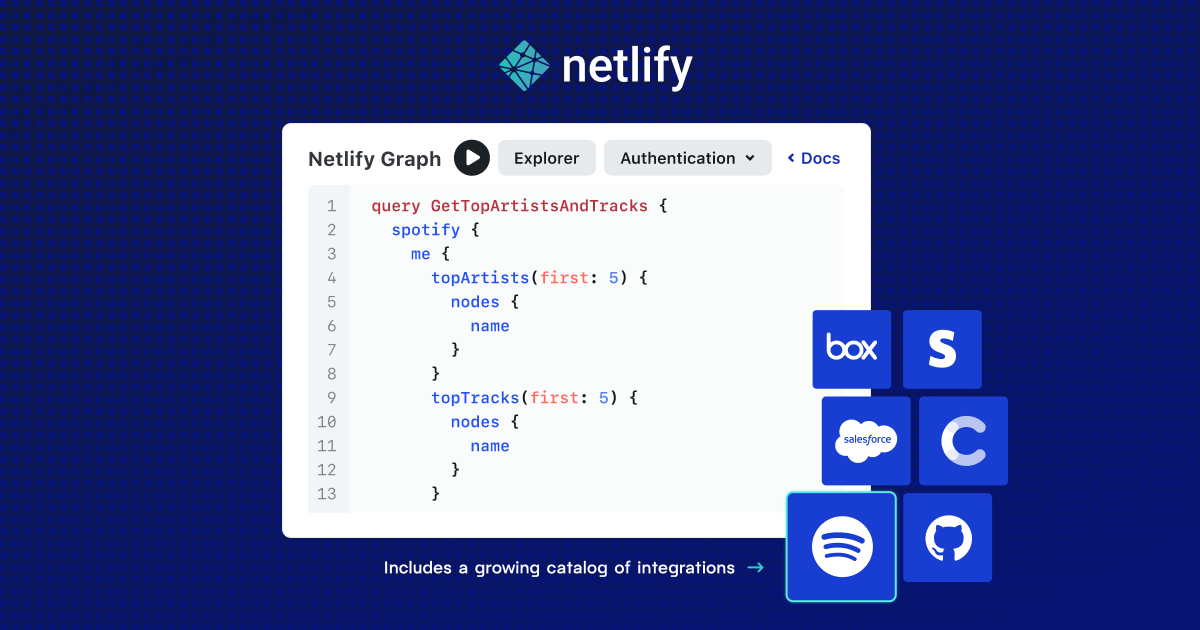
    Netlify this week added a Netlify Graph tool to its portfolio that makes backend services available to developers via a single click. The tool aims to simplify DevOps teams’ access to those services when building their applications.

    Netlify Graph is based on the GraphQL query language for application programming interfaces (APIs) and enables developers to integrate services such as GitHub, Salesforce and Stripe within frontend and web application development tools without any direct intervention required from a DevOps team.

    Netlify provides an application development framework based on JavaScript, application programming interfaces (APIs) and markup languages, otherwise known as a JAMstack, to isolate frontend and backend components of an application.

    Netlify CEO Matt Biilmann said Netlify Graph is based on the GraphQL technology the company gained when it acquired OneGraph. The overall goal is to make it simple for frontend developers to invoke backend services accessed via either GraphQL or REST APIs, he said. Services based on GraphQL can be especially complex for developers to invoke as they navigate the management of tokens and application secrets, Biilmann added.

    It’s not clear to what degree GraphQL APIs will supplant REST APIs. However, developers tend to prefer GraphQL APIs because they provide more granular control over what data is accessed. The challenge is the number of backend services that expose GraphQL APIs is still comparatively limited. As GraphQL becomes more widely adopted, the level of effort DevOps teams now need to expend to expose backend services should decline as tools such as Netlify Graph are employed by frontend developers.

    As a result, at least theoretically, the rate at which new applications are built and deployed to drive digital business transformation initiatives should increase. Most IT teams will not be replacing REST APIs with GraphQL-based APIs overnight, but the percentage of new applications that rely on GraphQL APIs will steadily increase. DevOps teams looking for easier ways to provide developers with simpler access to backend services now have an incentive to embrace GraphQL.

    Ultimately, Biilmann said, the goal is to enable developers to build applications without having to directly engage anyone on the IT team. Each backend service can be managed in isolation from the frontend of any application. It’s not clear how long it might take to achieve that goal, but as responsibility for the end-to-end management of the application experience continues to shift left toward developers, the need to surface backend systems-as-a-service becomes more pronounced. In fact, given the current focus on improving developer productivity, IT organizations might soon face a mandate to embrace GraphQL more broadly. After all, every minute that a developer spends on plumbing is time they’re not spending writing actual business logic.

    Naturally, it may take time for enterprise IT to be truly transformed into a set of services that developers can easily consume. But as progress continues to be made, that dream may finally be realized.

  • Snyk Acquires Fugue to Secure Cloud Infrastructure

    Snyk Acquires Fugue to Secure Cloud Infrastructure

    Snyk today announced it has acquired Fugue as part of an effort to embed security within an infrastructure-as-code (IaC) provisioning tool.

    The Fugue platform combines a unified policy engine with an implementation of the open source Open Policy Agent (OPA) software, dubbed Regula, to ensure security and compliance policies are consistently enforced. OPA provides IT teams with a tool for declaratively applying policies and is being advanced under the auspices of the Cloud Native Computing Foundation (CNCF).

    The Fugue IaC tool also provides pre-deployment security checks for Terraform, AWS CloudFormation, Kubernetes manifests and Dockerfiles. It enables IT teams to create and test custom policies using Rego, the programming language created for OPA. In addition, there are interactive visual maps of IaC templates and the ability to export IaC diagrams that IT teams can use for planning and approval processes.

    Josh Stella, the former CEO of Fugue who is now a chief architect for Snyk, said Regula is designed to make it possible to apply those policies to both cloud-native and legacy monolithic applications. Tighter integration with the cloud security posture management (CSPM) tools that Snyk provides will make it possible to provide developers with an instant feedback loop as they provision infrastructure, he added. Armed with that intelligence, it becomes less likely that mistakes will be made and that cybercriminals can take advantage of those, noted Stella.

    DevOps teams should also expect to see Fugue integrated with the artificial intelligence capabilities Snyk gained with the acquisition of DeepCode, a provider of an interpretable machine learning semantic code analysis tool that scans code anywhere from 10 to 50 times faster than existing approaches. In total, Snyk has acquired five companies in the last 18 months, including CloudSkiff, FossID, Manifold and DeepCode.

    Misconfigurations of IT infrastructure have emerged as a major issue in the cloud era. Developers often have little to no cybersecurity expertise, and using application programming interfaces (APIs) to provision IT infrastructure themselves increases the chance that mistakes will be made. The acquisition of Fugue creates an opportunity to address that issue at a time when the management of infrastructure and applications is converging, said Stella.

    The amount of focus on cloud security also is increasing as part of a larger discussion involving software supply chains that increasingly becoming targets of attack. Cybercriminals are becoming more adept at scanning for vulnerabilities created when developers, for example, inadvertently leave open a port on a cloud service through which data can be exfiltrated.

    It’s not clear just how far responsibility for cybersecurity will shift left toward developers in the months and years ahead. However, as more intelligence is incorporated into the tools that developers use, the easier it will become to automate DevSecOps best practices. In fact, the goal should be to make it easier to build more secure applications faster rather than forcing organizations to slow down to deal with security issues that should never happened in the first place.

  • Cloudify Integrates DevOps Automation Platform With Terraform

    Cloudify Integrates DevOps Automation Platform With Terraform

    Cloudify this week announced a free user interface (UI) module that extends its infrastructure provisioning platform and enables DevOps professionals to integrate unlimited Terraform modules.

    Nati Shalom, Cloudify CTO, said Terraform UI provides a familiar construct for DevOps teams using the open source DevOps automation platform to provision infrastructure-as-code (IaC). The module enables DevOps professionals to seamlessly import Terraform modules to Cloudify without writing blueprints or any additional glue code, he said.

    Cloudify now automatically generates the wrapper required for each Terraform template to enable DevOps teams to collaboratively manage secrets, execute concurrent deployments, store states remotely and monitor deployments, users and versions via any Git repository. Those Terraform modules can then be integrated with application programming interfaces (APIs) and continuous integration/continuous delivery (CI/CD) platforms as DevOps teams require.

    DevOps teams can also import existing automation modules and scripts into Cloudify. Those modules and scripts can be automatically converted to environments that can be centrally managed via the Cloudify console or via export to ServiceNow’s IT service management (ITSM) platform as a software-as-a-service (SaaS) application.

    That approach provides the added benefit of enabling DevOps teams to centrally manage all Terraform modules and versions via a single console as part of an effort to reduce misconfigurations that lead to security breaches, he added.

    Cloudify enables DevOps teams to create a self-service catalog and portal through which infrastructure can be managed. Many DevOps teams have built their own portals to manage this process. However, Shalom noted those DevOps teams then need to devote resources to maintaining that portal when those resources could be allocated to other critical tasks.

    DevOps teams can not only use Cloudify to apply patches, change topologies, add security features, make configuration changes or make additional resources available, Shalom added, they can also now integrate Terraform tooling with platforms such as Kubernetes or other automation frameworks such as Ansible. Cloudify also makes available an enterprise-grade version of the platform with these integrations.

    It’s not clear how much time and effort IT organizations are investing in building and maintaining DevOps environments. In many cases, however, organizations should probably revisit decisions about building capabilities that, at the time, didn’t exist. That doesn’t necessarily mean that replacing custom DevOps tools makes sense across the board, but it is likely that, in the intervening years, the range of tooling made available via DevOps platforms has greatly expanded. Relative newcomers to DevOps, meanwhile, are enjoying the benefit of platforms they did not have to construct themselves.

    In fact, Shalom noted that, in terms of DevOps adoption, an inflection point has been reached as more organizations launch digital business transformation initiatives that require applications to be both built and deployed faster than ever. The challenge, of course, is enabling that to occur both safely and at a reasonable cost.

  • CircleCI Adds CI/CD Service for macOS Development

    CircleCI Adds CI/CD Service for macOS Development

    CircleCI today added a dedicated continuous integration/continuous delivery (CI/CD) edition of its namesake platform for developers building applications on the macOS platform.

    Jim Rose, CircleCI CEO, said this offering is aimed at developers that either want dedicated resources to speed up their build processes or have to address compliance and security requirements that prevent them from using shared infrastructure via the existing CircleCI cloud service.

    Most of the developers building applications on macOS platforms are creating applications that will ultimately be deployed on Apple iOS devices, noted Rose. Given the popularity of those devices, the number of organizations using CI/CD platforms to accelerate creation and updates of those applications has increased, Rose added. CircleCI estimated there are now more than 30 million developers building applications on the macOS platform that would benefit from a CI/CD platform running on dedicated bare-metal infrastructure accessed via the Amazon Web Services (AWS) cloud. CircleCI’s dedicated host provides secure access to 50% more cores and more than twice the storage capacity than is available via a CI/CD platform running on top of virtual machines.

    Other capabilities provided by CircleCI include the ability to monitor the performance of apps being developed for multiple platforms in the same pipeline. Many applications deployed on iOS are also deployed on other platforms such as Android, Windows or Linux, noted Rose.

    CircleCI also provides access to testing tools that the company recently added to its portfolio of DevOps tools. Those testing tools are especially critical given the stringent requirements developers face when trying to get approval to make their iOS applications available via the Apple Store, said Rose.

    Developer productivity is, of course, a major issue for organizations trying to strike a balance between automating software development tasks and the art that goes into building applications. While developers appreciate automation, they don’t necessarily want to feel they are working in a factory. Given the demand for their expertise, many developers will simply jump ship when they feel software development processes have become overly onerous. While many managers tend to believe they have a handle on measuring developer productivity, there is often too much focus on, for example, how many lines of code are written versus the business outcomes achieved.

    A recent CircleCI survey also found that more than half (52%) of respondents don’t allow their software developers to choose their own tools. While there is a clear need for a consistent approach to building and deploying applications, organizations will find it challenging to attract and retain the best developers if they don’t allow them to experiment with different tools.

    One way or another, however, the rate at which developers can build and deploy applications is rising as DevOps best practices are adopted. It’s not clear that organizations are going to be able to absorb all that software but, in the wake of the COVID-19 pandemic, the appetite for mobile applications that drive digital business transformation initiatives has never been greater.

  • How the Cybersecurity EO Impacts DevOps Teams

    How the Cybersecurity EO Impacts DevOps Teams

    Eric Greenwald, general counsel for Finite State, talks with Mike Vizard about how the executive order for securing software supply chains issued by president Biden will impact DevOps teams. The video is below, followed by a transcript of the conversation.

    Announcer: This is Digital Anarchist.

    Mike Vizard: Hey, guys. Thanks for the throw again. We’re here with Eric Greenwald who is the General Counsel for Finite State, which specializes in cybersecurity around embedded systems. Eric, welcome to the show.

    Eric Greenwald: Thanks very much. Very happy to be here.

    Vizard: The Biden administration is going to save us all from ourselves. We’ve got this whole effort around software supply chain going on. NIST is now trying to define what a critical component of a software supply chain exactly is. That has been a mystery to many of us for a long time. So maybe you could sort this out for us a little bit. What exactly do they mean and what are they looking for?

    Greenwald: Sure. Well it’s a little bit complicated because I think the conventional understanding of what is critical software is a potentially very broad and malleable concept. What NIST is trying to do is narrow the focus a little bit mostly so that it can phase the implementation of the executive order. I think if you look at some other efforts at imposing standards for software security or security in general that there’s been a rollout and the standards weren’t necessarily drafted in a way that made sense or was easy or low cost to implement, and so what they’re trying to do is avoid those pitfalls and do a rollout that starts with a narrower scope but then eventually expands I suspect eventually to pretty much the majority of the universe of software products that the government buys.

    Now where is it going to stand when the executive order actually begins implementation? That’s what this initial definition is meant to establish. But if you look through what NIST has put out so far, it’s not 100 percent clear, and I think we’re going to get some additional guidance both from NIST and also the executive direct some other departments and agencies to put out some additional guidance. The NIST definition that they put out back on the 25th of June includes a proposed set of categories of software that would be defined as critical under the executive order, but it’s not a definitive list.

    I believe it’s CISA from DHS that’s charged with putting out a definitive list somewhere down the line in the implementation of the executive order. I can’t remember the exact date. But in another 30 or 60 days we’ll see a definitive list of those categories from CISA.

    Vizard: Well, are they doing this out of their concern for us all or are we going to get in trouble at some point? Is somebody going to call me up as a developer and say, “Hey, you’re not protecting these critical components and you’re about to be fined or something bad is going to happen”? So what’s the stick that goes with the carrot.

    Greenwald: So the first stick that gets wheeled in is by the Office of Management and Budget, that is going to use it to compel the departments and agencies that are buying software from vendors out there in the private market that they can only buy software that meets the definition of critical software if it has passed the technical requirements that will eventually be promulgated under the executive order. So the first line of people potentially getting in trouble are the departments and agencies for failure to actually implement the EO’s requirements. Now indirectly, what’s going to happen is as the departments and agencies attempt to enforce the standards under the executive order is that they will select software vendors based upon whether those vendors are meeting the technical requirements. So there’s this trickle-down effect that again it’s going to go through those vendors that are selling directly to the government, but then it will also impact all the various companies out there that are providing components to those vendors that sell to the government.

    So it’s not just going to impact vendors who sell directly to the government. What’s more, it’s going to go even further beyond that because I think especially if people start to think that the standards promulgated under the EO are sensible, are a good way to actually impose tighter security requirements, you’re going to see them adopted more broadly and made mandatory not just for those companies that are selling to the government. But you might see industry groups adopting them, you might see a lot of companies as they are buying software telling their vendors, “Hey, we want you to meet these requirements that have been promulgated under the EO. They’re not required by law to, but we’re requiring you under our contract to meet them.” And you might even see insurance companies start requiring them as a prerequisite for obtaining cyber insurance coverage.

    Vizard: I’m not a lawyer, but sometimes when I do look at these regulations I do notice there’s a common theme between them, almost to the point where I feel like somebody kind of copy and pasted something from one into the other. Is that how things work? People kind of look at one agency and say, “Well thanks for taking the lead on this,” but then they just implement it into their regulatory framework?

    Greenwald: So the best analog to offer on that is if outside of the cybersecurity realm is environmental standards, particularly auto emissions standards. You look at California that leads the way in auto emission standards that it imposes on automobiles sold in California. You see a lot of other states adopting those standards as the model. Not all states, by any measure. But the interesting thing is that car manufacturers can’t just meet those standards to sell automobiles in California.

    They’re going to meet those standards for all automobiles sold in the United States and probably other parts of the world too. Switching to an analog from the security world, you look at the NIST framework. The NIST framework, all voluntary. Nothing about it is mandatory. It’s also not specific technical requirements. So it’s a rough analog.

    But if you look at what happened with the NIST framework you see all sorts of contracts that require compliance with the NIST framework. You see other industry groups or even – and again, in the insurance industry, a lot of insurance companies want to know before providing you with cybersecurity insurance coverage do you meet the basic requirements or the guidelines promulgated under the NIST framework. So I think to your copy and paste point, I think yes, it definitely does happen. And my first hope is that the technical standards promulgated under the EO will be sensible and actually promote better security. My second hope is that if they do they get adopted beyond just procurement for the federal government.

    Vizard: Do you think that the compliance process can be automated as we go forward or is this going to be a lot of manual reviews of code? We’re all hoping or looking for – compliance-as-code is kind of the buzzword of the day in the DevOps space. Do you think we can code our way through this?

    Greenwald: So I’m going to avoid getting too deep into technical issues because I’m a lawyer first and a technology guy second, but I’m more technology policy than engineering, for example. My feeling is that the only way we’re going to be able to implement the technical requirements under the EO in a manner that is efficient and effective, and not too costly I should add, is by automating the process. I will note that part of the approach that Finite State takes to this is automating those software reviews, the scanning for vulnerabilities and assessments of what is actually in the software because that is – number one, doing it once manually is labor intensive. Under the EO, my expectation is that you’re going to see requirements to do it repeatedly, and I think the ideal is doing it with every update or at least even if the updates have a long periodicity doing it more frequently than the updates.

    Or let me just say this – I think that the companies that are able to run their security checks on their software regularly are going to be at a competitive advantage as they approach procurement officers in the federal government to buy their software. And the same thing I think is going to apply more broadly across the industry, that the more frequently you can do these security scans the greater your competitive advantage. And there’s just no way to do it frequently without automating it.

    Vizard: We talk a lot about DevSecOps in our world these days. I wonder if this is just going to force that issue where I might as well start biting this bullet now because one way or another the government’s going to kind of drive me towards it whether I like it or not, so maybe now’s the time.

    Greenwald: Yes. Absolutely in two things. The first is that the EO specifically calls for the promulgation of technical standards for secure development of software. The second is, to your point, my view, what I advocate for companies that are looking at the EO and saying, “Hm, where’s this going, who is this going to apply to?” that if you sit around and wait for it to become mandatory for your company and/or your products, that you’re going to be way behind the power curve and that these companies that are looking at this need to start developing a plan, an aggressive plan, to develop securer software development ops, to implement a software bill of materials – and again, we’re going to see very soon where the technical standards for the software bill of materials will land.

    So people I think will be able to start jumping on that soon. And third, having transparency about your security measures, whether it’s software development or testing, that are accessible to anybody buying your software or using your software. And just to add a last point on there, that being able to do that on a repeated basis where the test results can be validated is going to be very important for companies who, again, want to maintain a competitive advantage in the marketplace.

    Vizard: And I suspect that just because I wrote my code before the rules were actually implemented won’t be much of a benefit to me because they’ll expect me to go back and fix stuff that’s in production.

    Greenwald: That’s absolutely right. So number one is that for any software that the federal government procures following the date that the EO is promulgated, which was I forgot now, like early May, any software procured after that date forward has to meet the EO’s requirements, again, if it falls under the critical software definition. I’ll say something about that in a moment. But the other is that eventually the EO expects OMB to impose those same requirements on critical software that is legacy, that predates the promulgation of the EO.

    As a reference, quick note on if your product meets the definition of critical software. As I noted initially, the definition is being drawn somewhat narrowly. Frankly, I think it’s fairly broad as put out by NIST just a week ago. But again, it’s the initial phase and the definition, the scope, is going to get broader, and I would expect it to end up being quite broad at the end of the day. What day that is, is hard to say. But a key to note is that in the frequently asked questions in the NIST definition that they issued last Friday, they specifically say if a procurement officer wants to apply the EO’s requirements to something that doesn’t meet the definition of EO critical software, they can go ahead.

    There’s nothing that prohibits them from doing so. And if I’m a procurement officer and I’m thinking, okay, I’m buying software today. I know that eventually it’s going to have to meet the EO’s requirements. Why am I going to buy something where I’m worried about it meeting the EO requirements? I’m going to buy something today that is going to give me no headaches down the road in terms of whether it actually meets those requirements.

    And what’s more, if you’re buying software, you’re looking at 10 different products and three of them meet the EO’s requirements, to me that’s an indication that those products are safer. And so I think that you’re going to see procurement officers for a number of reasons gravitating towards those companies whose products meet the EO’s technical requirements.

    Vizard: Yeah. I guess I’m a little more worried about how granular it might get, because we have all these libraries and microservices that people build and then they deploy, and the definition of how that thing may become critical could change over time and what I thought was inconsequential suddenly is critical.

    Greenwald: Well again, and as I said at the top, to me if you’re trying to establish a conventional definition of what’s critical, it’s really hard to circumscribe that narrowly. Anything that has access to a system that you might consider critical, should be considered a critical component. If you’re thinking about what’s the conventional understanding of critical, yes, it’s enormously broad. Again, NIST is trying to start a little bit more narrow and expand later, but I don’t think anyone can feel confident if they have a product, unless it’s something that where there’s just no argument that it could ever be construed as critical, that they should be looking at the EO requirements and figuring out a way to comply with them – well I was going to say comply with them now – we don’t have the requirements yet.

    The technical requirements haven’t been promulgated. But as we start to see which way the wind is blowing, where these are likely to land, companies should be looking to develop a plan to meet those requirements where we expect them to land. And again, not just those companies that sell software to the federal government. So the granularity of the definition, to me I don’t want to go so far as to say as it’s irrelevant, but I think that software vendors of all stripes, whether it is the obviously most critical component of an operating system or something that’s not so obvious, that they should all be thinking about how they’re going to comply. There’s a separate question about granularity, and that is how granular are the technical requirements themselves?

    That remains to be seen. I don’t have a good sense as to how specific and how technical NIST and the other agencies are going to get. But I have a lot of confidence in NIST because they have very good experts in house and they also have spent a lot of time developing relationships with the private sector, making sure they understand what the private sector needs, what really hurts the private sector – and I should say hurts them unnecessary, because there’s no way we get to a more secure software landscape, whether for the federal government or more broadly, without enduring some pain and some cost. You can’t wish your way into better security.

    Vizard: Cool. What’s your best advice to folks then right now? What should they be thinking about, what should they be doing, and how do I get ready?

    Greenwald: So the first thing I would say is if you don’t already have a software bill of materials for your products, that you should start moving in that direction and quickly. As I said, I think it’s just in another week or so that we’re going to see the standards for an SBOM promulgated. When that happens, it’ll give you a very specific target to go for. But there’s no reason not to start now in moving towards that. So that’s something that I think people can start working on today. I think it’ll be a little farther in the future before we start seeing again the specific technical standards being promulgated.

    But I would be, number one, keeping an eye on what’s happening with the various bits of guidance and rules and regulations that are coming out of the EO implementation process, so tracking it closely. Second, if you’re looking to what you can do right now, start looking at generally accepted practices, for example, for secure software development. Because I strongly suspect that where NIST lands is going to be pretty close to what are generally accepted best or very good practices with respect to secure software development, and the same thing for security testing. So we’re a little early in the process to be able to say do A, B, and C specifically.

    Again, within a week or two we should have a little bit of that specific A, B, or C with respect to the software bill of materials. It’s going to take a little bit longer before we get those technical specifics for software development and testing. But again, I think that we can expect NIST to hue to what are already generally accepted as good or best practices in those arenas.

    Vizard: Alright. Like it or not, secure software is on the way. Eric, thanks for being on the show.

    Greenwald: You bet. Thank you for having me.

    Vizard: Alright. Back to you guys in the studio.

    [End of Audio]