Category: Application Performance Management/Monitoring

  • Meta Income Down by Half | Will Apple Make it Worse? | Linux Secure Boot Fix

    Meta Income Down by Half | Will Apple Make it Worse? | Linux Secure Boot Fix

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Meta’s latest results are very bad, Apple wants its cut of Facebook ads, and Lennart Poettering proposes a new Secure Boot for Linux. (more…)

  • Fire at Data Center Causes Chaos | 20% Costlier Cloud

    Fire at Data Center Causes Chaos | 20% Costlier Cloud

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: A South Korean conflagration leads to a ridiculously long outage, and the price of public cloud is skyrocketing. (more…)

  • Cisco Unveils 800G Networking Platform to Advance DataOps

    Cisco Unveils 800G Networking Platform to Advance DataOps

    At the Open Compute Project (OCP) Global Summit conference, Cisco announced it developed an 800-gigabit switch that consumes significantly less power than the previous generation of its networking equipment.

    Thomas Scheibe, vice president of product management for cloud networking for Cisco’s Nexus and ACI product line, said the throughput provided by the latest 7-nanometer iteration of Cisco One ASIC processors is primarily needed by organizations processing massive amounts of data to train artificial intelligence (AI) models either in a local data center or in the cloud. The challenge is that many of the organizations are looking to build AI models that process massive amounts of data while simultaneously reducing their IT infrastructure’s carbon footprint, he noted.

    Cisco has been able to achieve that goal by continuing to invest in proprietary ASIC processors; they are at the core of its networking portfolio to improve data operations (DataOps), said Scheibe. Many IT teams are also looking to replace legacy network routers and switches that consume more power and reduce energy costs by as much as 77%, added Scheibe. In terms of climate impact, Cisco claimed its 8111-32EH switch can now provide 25.6Tbps at 15% of the power requirement. Cisco projected that switch will save about 10,000 kg CO2e per year compared to a 12.8Tbps switch. That equates to the greenhouse gas emissions generated by an average gasoline-powered passenger vehicle driving 26,155 miles, according to Cisco.

    IT teams also have the option of deploying either Cisco’s network operating system or SONiC—Software for Open Networking in the Cloud—network operating system (NOS).

    Cisco is also providing IT organizations with the option to configure its latest routers and switches to run at either 800, 400 or 100 Gigabits with an eye toward upgrading throughput sometime in the future.

    In general, DataOps as an IT discipline is maturing as organizations realize they need to implement best practices to optimize data flows across their organization. Cisco is giving IT teams the option of employing a standard Ethernet fabric or an alternative fabric that increases throughput by predicting which packets need to be delivered to a specific location based on their attributes and the behavior of previous network traffic. As the volume of data that needs to be accessed by low-latency applications continues to expand, DataOps will become a more critical IT discipline. Historically, storage administrators tended to be responsible for data management, but as these applications continue to proliferate, a new class of DataOps engineers is emerging to optimize the flow of data across distributed computing environments.

    In the longer term, it’s not clear how much carbon dioxide emissions are factoring into IT decisions these days, but there are organizations that have begun to track it as part of an effort to lower their carbon emissions. Most cloud service providers have also committed to being carbon neutral. Cisco is betting achieving that goal will require IT infrastructure upgrades at a time when the amount of data that needs to be processed will only continue to exponentially increase.

  • Of Max and Min: The Non-Interference Prime Directive (for Visibility)

    Of Max and Min: The Non-Interference Prime Directive (for Visibility)

    Last issue, I cited CPU utilization as an example of a metric that is often misused to describe/explain/infer system performance and asserted that improved visibility can help to overcome such misuse. In this issue, I will expand on what improved visibility means and present two case studies that illustrate a recent antipattern that I’ve noticed in visibility: Interference caused by visibility interfaces.

    I will describe some properties of ideal visibility interfaces with some real-world analogies. Together with two case studies of performance problems stemming from interfering monitoring interfaces, I will explain why interference can be so damaging to observability efforts. Because so few libraries and applications provide visibility through ideal interfaces, I also continue to argue for better visibility primitives from our operating systems.

    Clarifying Visibility

    Observability is a big deal in the DevOps and SRE communities. We cannot know how well our systems are doing without visibility into their state. Unlike Scotty on Star Trek, we absolutely should not rely on gut feeling to intuit the health of the engines that drive our enterprise systems. We have to build our systems to make their internal state visible to the outside world.

    But what is not often discussed is the degree of visibility and the associated cost. A system’s visibility is not a binary “yes/no” attribute. Just as in the physical world, there are qualities to visibility that impact how observable a system actually is:

    • Is the visibility continuous or is it discrete (in either time or space)?
    • Does the act of observing perturb the system?
    • Can everyone observe or can only a few agents observe and report to everyone else?
      • Can everyone observe at the same time or is it one at a time?

    Let’s ground these attributes of visibility by looking at some examples in the physical world. In the first article of this series, I mentioned that there is a lack of standardized language used in performance engineering. As far as I know, there is no standardized language around the attributes of visibility, so the adjectives that I am using are by no means “standard”–but the distinctions they identify are important.

    Continuous Vs. Discrete Visibility

    When in London, if I can see one of Big Ben’s1 four faces, I can always know what time it is just by looking up. My access to the time of day is continuously available. But if I can’t see any of the faces, I can still rely on the chimes—except that the bells only chime once every 15 minutes. This means that if I can’t see any of Big Ben’s four faces, my access to the time of day will be discrete.

    If I witness an accident, the continuous access to time allows me to precisely note the time of the accident. If I have to fall back to relying on the chimes, the time that I attribute to the accident becomes less precise.

    Likewise, in our cars we often need to know what our current speed is (e.g., as we approach speed traps or enter school zones). It would be absolutely useless if our speedometer reported our speed in five-minute snapshots. I do not want to know how fast I was going three minutes ago. I need to know how fast I am going now!

    All other things being equal, continuous visibility is preferable. Being able to examine a system’s state on demand is far preferable to having to wait for some arbitrary interval to pass before that information becomes available—unless there is an excessive cost to examining the system state in real-time.

    Overhead, Interference and Multiple Viewer Contention

    Measurement overhead is likely the type of cost that most people are familiar with—and the type of measurement cost that many of us focus on. The time to place down a ruler to measure the dimensions of a sheet of paper or the time that it takes to make inter-process communication calls to obtain a service’s state are costs associated with taking a measurement. Of course, we want this measurement overhead to be as low as possible, but we can sometimes live with overhead because the cost is mostly borne by the observer.

    Then there are measurements that interfere with the operation of the system being measured. For example, take the annual physical exams that our doctors recommend. The purpose of these exams is to take measurements of the state of our bodies to detect health regressions. Pretty important stuff. But these exams are intrusive. We have to take time off from work, break our daily routine and trek over to the doctor’s office to get poked and prodded. Some people even skip their annuals because it is so disruptive to their lives. Many of the exciting advances in consumer medical devices essentially facilitate more continuous monitoring of vitals so we can rely less and less on these intrusive annual physicals. Again, continuous visibility is preferred!

    In computer systems, it is virtually impossible to take software-based measurements that don’t contend with the target software for hardware resources. So, implementing visibility in software means that some interference is unavoidable. But, contending for software resources like software locks and critical regions is another matter entirely. As such, we must be cognizant of contention for software resources when designing our systems for visibility. This is the essence of the Non-Interference Prime Directive for Visibility.


    A Non-Interference Prime Directive From the PMWG

    The participants in the Performance Management Working Group (PMWG) had different goals and priorities. My priorities lay in establishing a minimally intrusive low-level visibility interface for operating system and process metrics. This became the Data Capture Interface (DCI) layer in the Universal Measurement Architecture specification.

    A key part of the DCI included this statement about the performance impact of monitoring:

    1.2.2 Performance

    The addition of any metrics acquisition subsystem should not noticeably affect the performance of the measured system. (Many performance tool builders assert that system performance should not be altered by more than 5% when there is measurement activity.) Although it is beyond this specification to stipulate a performance degradation figure, that figure belongs in an implementation’s design specification, the performance goal does impose a requirement that the programming interfaces specified in this document be capable of being implemented in the most efficient manner possible on the target operating system.

    I actually wanted something stronger than a generic statement about performance impact in the specification and thought we should provide a reference implementation that would embody the key principles of low overhead, low interference and low contention. To that end, I prototyped a version of UNIX SVR4 where the kernel sysinfo data structure used by the sar/sadc utilities was placed on a page-aligned area of kernel address space. I also made sure that the rest of the page was not occupied by any other data (to address security concerns) and arranged for that page in kernel address space, which is normally protected against reads and writes from user space, to be readable (but still not writable) by all user processes at a fixed address in the user address space (it was a prototype to demonstrate how “things could be”).

    Sadc (the data collection component of sar) normally accessed the sysinfo data structure via /dev/kmem (a special file that gives file access semantics to the kernel virtual address space). On my prototype system, I modified sadc to simply dereference the fixed virtual memory that I placed sysinfo into. No open, lseek and read—just memory dereference. On the 3B2/400 system on which my prototype ran, running sadc once a second normally took almost 5% of a single CPU. On my prototype system, I was able to run sadc 100 times a second with almost no measurable CPU usage. Additionally, in my prototype, EVERY process had read-only access to the sysinfo data via simple memory dereference. The system became super visible—with virtually no overhead. Everyone could look at sysinfo at any time at the cost of memory access. Visibility Nirvana!

    Alas, Nirvana nixed; paradise lost. PMWG participants did not wish to put the requirements of a reference implementation on their kernel developers. Instead, we opted for the weaker statement about performance you see above.


    Just as with annual physical exams, a computer system measurement implementation that results in the slowing down of the system presents a tremendous disincentive to taking that measurement.2 Measurement interference is something that we need to design out of our implementations—not design into them.

    For example, if a system maintains a linked list of objects that are actively being added and removed, and traversal and manipulation of this linked list is protected by read and write locks, an implementation of a monitoring interface that needs to traverse this collection of objects in read-only fashion should not participate in this locking protocol. This statement might rankle some software engineers who are used to “data integrity at all costs,” but this highlights some of the differences in priorities between general software engineering and the practical needs of performance engineering.3 Implementing monitoring interfaces that cause software interference is counterproductive—they won’t be usable when they are most needed.

    So far, we have only considered a single observer of our systems. When there are multiple observers, we also have to ask whether the observers interfere with each other. There are plenty of examples in real life where this happens. For example, if ten people are trying to measure the dimensions of a piece of paper, physical constraints probably allow only for two or four measurements (at most) to be taken at a time (i.e., assuming an organized pipeline of participants measuring width and then height). An even more realistic example of serialized observer access might be the portholes in the lower decks of a cruise ship. Some of the smaller portholes only allow one person to view the outside at a time. So, when a pod of whales swims by, viewers have to queue and take turns to gain access to observe them.

    With computer systems, measurement contention between multiple observers also tends to discourage observation—not because everyone is so polite but because no one wants to get stuck in a line.

    Fragmented Vs. Holistic Visibility

    A final dimension of visibility is related to the field of vision. In the physical world, this is illustrated by comparing the porthole view from inside a cruise ship with the wide open, unobstructed view from the top deck.4 Compared to the top deck, portholes only provide a partial view of the ocean. One sometimes needs to stitch together the views from multiple portholes to get a more complete view of the outside world. The importance of the more complete view is the inherent bigger picture—where each fragment provides context for and about neighboring fragments.

    In computer systems, visibility is inherently fragmented. Each component provides a visibility portal (or not) into its own state. Like the portholes on the lower decks of cruise ships, we can approximate a holistic view if we are able to query the state of each component in a reasonably timely fashion. Again, this is only possible if each component supports continuous visibility. Unfortunately:

    • Many key low-level components do not provide any visibility.
    • Many other components only provide discrete visibility.
    • Some limit visibility even further by providing discrete visibility through network sockets with endpoints that are off-host. As a result, co-located components are unable to examine each other’s visibility interfaces in any practical manner.

    In turn, the opaque, fragmented views that result from the discrete visibility in many components results in a fragmented mentality among developers. Engineers develop a mindset that they are implementing visibility only for themselves and their components, rather than thinking about their visibility as part of a whole—which provides a circular argument for justifying the discrete view they fall back on.

    Rather than thinking of passengers on a cruise ship and portholes, think of the components co-executing on a host as workers in a factory—with data moving through and between them. The current fragmented view places each worker in their own room, where they are unable to see the state of the other workers. With a holistic view supported by continuous visibility into one’s neighbors, workers can make better plans and decisions. And “factory monitors” can get a more holistic view of events and better correlate different components’ states. Being able to build useful context around observations is a key attribute of observability.

    In contrast, modern UNIX and Linux systems support continuous visibility for operating system and process metrics through the /proc interface. We can query /proc for a supported metric at any time. The utility (and success) of the /proc interface is unquestioned–being able to access process and system metrics through the filesystem namespace is a fantastic idea.5

    Applications and libraries have grown accustomed to the ability to query standard system metrics at will. If this mode of continuous visibility were to spread to the full stack, it stands to reason that the ecosystem would evolve to benefit from this enhanced observability. This should provide an impetus for the operating system to provide primitives to facilitate continuous visibility for the entire stack.

    But while we wait for visibility nirvana, there are some practical problems that need to be addressed. Some important visibility interfaces that currently exist are violating the prime directive in a big way.

    Prime Directive Violations

    I delivered a talk at SRECon 2021 entitled Latency Distributions and Micro-benchmarking to Identify and Characterize Kernel Hotspots, in which two of the hotspot case studies are examples of standard, commonly-used visibility interfaces that violate the Non-Interference Prime Directive. Let’s examine those two cases.

    When the Cost of Running Netstat is Too Dang High

    We recently discovered that netstat can seriously delay the creation and destruction of UNIX domain subsystem (UDS) sockets on Solaris. More specifically, in Solaris, the kstat mechanism to query for the list of all active UDS sockets (an ioctl call) can take seconds of CPU time, especially when there are tens of thousands of the sockets in the system. By itself, this makes logical sense and is not a problem since more sockets means more data transferred from the kernel to the user space. But the impact of a long netstat run time on actual UDS socket creation and destruction is surprising (and disappointing).

    Here is the output of a program I wrote which collects a logarithmic histogram of the socket() and close() times for creating and destroying UDS sockets 100K times on a Solaris 11.3 system:

    <1us

    <10us

    <100us

    <1ms

    <10ms

    <100ms

    <1sec

    >1sec

    max

    socket

    0

    0

    72556

    27433

    11

    0

    0

    0

    1967055ns

    close

    0

    98262

    907

    815

    16

    0

    0

    0

    1364475ns

    Now, here are the results from the same program, but this time I’ve concurrently run a single instance of netstat -f unix:

    <1us

    <10us

    <100us

    <1ms

    <10ms

    <100ms

    <1sec

    >1sec

    max

    socket

    0

    0

    39006

    60976

    18

    0

    0

    0

    2137995ns

    close

    0

    96837

    1388

    1757

    15

    2

    1

    0

    308073600ns

    Look at how the single netstat call has pushed the maximum close time from about 1ms to over three seconds!6 And it looks like the distribution of socket() times that was clustered in the 10-100usec range has increased to be more clustered in the .1-1msec range. The act of running netstat has a huge impact on the time to create and close UDS sockets.

    Disabling netstat is not the right long-term solution, as doing so would eliminate key visibility. Artificial throttling of netstat usage is also not the right long-term solution, as this compromises the timeliness of visibility (i.e., continuous visibility). The right thing to do is to eliminate this tight coupling between netstat monitoring and the UDS.

    When PS Stands for “Pretty Slow”

    Before Linux aficionados smugly dismiss monitoring interference as only a Solaris problem, there is potentially an even bigger problem on Linux. There, the monitoring contention is seen by accessing /proc itself and is of the “contending observers” type.

    Let’s look at running concurrent instances of “ps auxww” on one of our Linux development boxes with 36 cores and 72 hardware threads (RHEL 7.6):

    Concurrency

    Wall time (avg)

    User time

    Sys time

    1

    .984

    .081

    .902

    2

    1.269

    .071

    1.013

    4

    3.043

    .066

    1.429

    8

    4.106

    .070

    1.396

    As we can see, with increasing concurrency, the average wall time for ps completion goes up (along with system CPU time). The ps instances compete with one another!7 This is even more surprising since ps is essentially a read-only operation.

    Further tests showed that /proc traversal for processes and threads not only contend with each other, but also that they contend with access to other, non-process related special files under /proc (e.g., /proc/vmstat). This is significant because so many libraries and applications depend on non-process data available through /proc to make runtime decisions.

    My colleague Gary Liku will be presenting additional findings around this /proc contention problem at SRECon22 EMEA in late October.

    What Happened?

    In the old days, tools like ps and netstat would obtain their data by opening the special file /dev/kmem – a file-based interface to the kernel virtual address space. If we knew the virtual address for an object and its size, we could simply seek to the virtual address in that file and read() the object. The decoupled nature of this read meant that it was impossible to do any synchronization or coordination with actual code that operated on the object. An object could change in the middle of a read.8 As mentioned earlier, the expectations around monitoring data consistency can be looser than the standard data flows that most software engineers deal with. This decoupled data access adhered to the Non-Interference Prime Directive and suited the monitoring use case very well.

    In modern UNIX systems, the use of /dev/kmem has fallen out of favor–and for good reason. In addition to the performance overhead of seek/read to access kernel objects, /dev/kmem gave all-or-nothing access to the full kernel virtual address space. This meant that applications that did monitoring via /dev/kmem had to also be trusted with elevated privileges.

    The general purpose decoupled access through /dev/kmem has been replaced with (potentially) coupled access to kernel objects through interfaces like /proc on many UNIX and Linux systems. But, as we have concluded, just because coupled access is allowed does not mean that it should be exercised without consideration of the interference cost.

    Assuming that a visibility interface will be used sparingly or sporadically often turns out to be a bad assumption. The more useful a visibility interface, the more often it will be used.

    Visibility in User Space

    As mentioned earlier, while the operating system provides continuous visibility interfaces (e.g., /proc) for accessing well-known system and process metrics, application code generally does not. It can be argued that, in avoiding continuous visibility interfaces, applications are also able to avoid the problem of interference and observer contention–and that would be a valid argument. But, I feel that the ideal of holistic views of the co-located components of a system is so compelling that applications should either (1) lobby for the operating system to provide proper continuous visibility primitives for applications (/proc provides an excellent framework for building such primitives) or (2) implement their own continuous visibility interfaces.9

    Java and the JVM provide examples of how continuous visibility interfaces can work in user space. Very early on, Java’s designers saw the benefit of continuous visibility into JVMs and came up with the Java Management Extensions (JMX) framework. Through this framework, the JVM, Java libraries, and Java applications are able to expose metrics through getters on management beans. These getters can be discovered through a common namespace. JMX also allows external clients to invoke these getters through a standardized remote procedure call mechanism.

    Getters can be implemented as simply as returning the current value of an object that summarizes code state, or implemented with arbitrarily complex code–including invoking getters on other management beans or querying remote databases. But, the overhead and non-interference concerns outlined earlier should apply to getters implemented for performance visibility.

    Finally, it is interesting to note that Oracle (and perhaps other) JVMs also implement a lower-level metric exposure mechanism that leverages a memory-mapped file to provide a shared memory interface to JVM metadata and some low-level metrics.10 Even with the continuous visibility provided by JMX, JVMs also recognize the advantages of lower overhead, more decoupled, coordination-free visibility utilizing shared memory.

    We should all keep the prime directive in mind and design our visibility mechanisms in the least intrusive, most decoupled manner that is practical.  Or as users, require that the visibility mechanisms that we use adhere to the prime directive.


     1Yes, I know; Big Ben is not actually the name of the tower with the clock faces: https://en.wikipedia.org/wiki/Big_Ben

     2These implementations are not useless. But they are generally relegated to being used for performance debugging – often in non-production environments.

    3Similar compromises are taken when building loosely coupled distributed systems—especially in extremely large systems where eventual consistency is an acceptable norm. We need to think of the design of monitoring systems as loosely coupled with the system being observed.

    4Although recent insights from cognitive neuroscience suggests that this complete visual view is actually an illusion created by our brains: https://www.science.org/doi/10.1126/sciadv.abk2480. But the concept of an accurate holistic view of the state of systems remains an ideal goal.

    5Unfortunately, no one has chosen (yet) to implement a low cost, low interference, low contention mechanism like the one I prototyped for UNIX SVR4.

    6The amount of impact of netstat on UDS socket creation and close turns out to be a function of the number of UDS sockets on the system. The more UDS sockets, the greater the impact.

    7This behavior gets more pronounced as the number of lightweight processes/threads in the system increases because the overhead appears to grow quadratically.

    8My memory access prototype, which was orders of magnitude less expensive than a read of /dev/kmem, was also decoupled in a similar manner.

    9Everywhere I go, I re-implement my libmetrix C library—metric registration and exposure through memory mapped files which approximates what I believe would be ideal metrics primitives based on /proc. An ideal metrics registration and exposure interface for user-level libraries and applications should be implemented under /proc itself.

    10Similar in spirit to my aforementioned libmetrix library.

    Thanks

    Thanks again to everyone who provided feedback on earlier drafts of this installment. And again, special thanks to Peter Wainwright for helping to get my thoughts better organized for this installment.

  • Four Causes of Technical Debt in DevOps

    Four Causes of Technical Debt in DevOps

    Ideally, DevOps should retain a lean footprint, but avoiding technical debt is easier said than done. As such, over half of IT leaders report technical debt is a big or critical problem. Without routinely addressing technical debt, DevOps teams can easily face inconsistencies during deployments. Versioning can get out of hand without consistent upgrades and aging legacy components can be a roadblock to development fluidity.

    Simply put, letting too much technical debt pile up isn’t all that great.

    I recently met with Kurt Andersen, SRE architect at Blameless, and Matt Davis, SRE advocate, to gather insights on the sources of technical debt in the field of DevOps. According to Davis, “Tech debt is something that you really want to keep chipping away at.” Below, we’ll highlight some common causes of technical debt and suggest ongoing practices to help tame it.

    1. UI-Based Deployment Patterns

    UIs are great for quickly configuring DevOps, but if your deploys aren’t codified, this reliance on UIs could come back to haunt you in the form of technical debt. A lot of the time, explained Davis, infrastructure teams have a tendency to just use the GUI of their given cloud provider to initiate deployments. Perhaps the team is wrapped up in feature velocity or a deadline to release.

    For example, you could use a UI to quickly create a database, but this is likely not a repeatable and robust process. Especially as an organization scales its cloud adoption and uses multiple clouds, you start to produce “snowflake” deployment patterns across teams, says Andersen. This could lead to inconsistencies around different deployment options per region.

    It’s not easy to catalog a configuration if it’s not written in code, and the more undocumented UI-based deployment patterns are used, the more silos of knowledge you create. “If not codified with Terraform, you have to document what you did—code gives you that documentation,” said Davis.

    Solution: Rely less on the GUI and codify your deployment patterns with infrastructure-as-code (IaC).

    2. No End-of-Service Life Cycle

    Development is typically more concerned with feature velocity than planning for service deprecation. Yet not envisioning the entire life cycle or setting an off-ramp from the start can produce more technical debt later on. “No one pays attention to planning for retirement, and at the end-of-life, services are hard to retire,” described Andersen.

    What you end up with are these “senile services” that aren’t doing that much but remain critical to the business’s operations. These services may be challenging to migrate. Or, they may be the product of unknown shadow or zombie APIs. For example, a marquee customer may depend upon a certain legacy endpoint, making the service difficult to evolve.

    Not planning for the end of the service lifecycle can hold up your development from more efficient ways to work. For example, if one “senile service” has never used a particular commit strategy before, it could stall agility when revamping the deployment pipelines, says Andersen. Thus, it’s best practice to set clear deprecation timelines and plan for the future.

    Solution: Plan the end-of-service life cycle from the upstart.

    3. Lengthy Dual-Track IT

    Another area that can produce technical debt in DevOps is dual-track IT. This is when engineering teams maintain one core stack in addition to an experimental structure and shift toward adopting the experimental structure over time. Development is constantly overseeing migrations to new technologies, yet they rarely plan for the coexistence of both stacks.

    While splitting an old and new stack into distinct units sounds like a temporary measure, some of these large transitions simply take longer than you think. For example, SoundCloud’s journey to refactor its monolith into microservices was an eight-year process.

    Solution: Realize dual-track IT might take longer than you think and plan accordingly.

    4. Intermittent Version Upgrades

    Third-party software is constantly upgrading to new versions. Especially if you’re integrating many open source dependencies into your stack, you’ll find the cadence of version upgrades to be quite fast. These upgrades are often imperative to plug new vulnerabilities as they emerge in the software supply chain.

    But upgrading versions and base images and having a patch management scheme that works from environment to environment requires a lot of work, Davis cautioned. Kubernetes version upgrades, for example, can take a lot of time. Yet, if your upgrades are not matching the pace of change, added Andersen, they can quickly pile up and leave you left behind with a mountain of work. “If you’re not upgrading monthly, you’re in danger.”

    Solution: Have a continual upgrade process in place.

    Technical Debt: Keep Paying, Cleaning, and Pruning

    Technical debt is something you need to grapple with before it gets out of control. But it’s not always apparent where it lives. Looking toward the future, automated tech debt scanning could help discover where technical debt is and provide remediation points as part of ongoing software stack auditing.

    You don’t want to get to the point where you accumulate and accumulate technical debt, only to burn it all to the ground in one disastrous fell swoop, said Davis. Similar to the way you slowly pay off a mortgage each month, technical debt is something you must continually keep an eye on and make reducing part of your team’s continuous workflow.

    Or, consider the old camping mantra of always leaving the campground cleaner than you found it. You pick up a little bit of extra trash and take it out with you, making the environment better for everyone. Or, consider how a gardener must prune the branches of a fruit tree to help it grow. Pick the analogy that works for you and see if you can apply it to continually reduce tech debt in your DevOps processes!

  • Datadog Extends Reach of Integrated DevOps Platform

    Datadog Extends Reach of Integrated DevOps Platform

    At its Dash 2022 conference, Datadog announced today it is extending the reach of its namesake cloud-delivered monitoring and observability platform to address continuous testing, application security and cost management.

    In addition, Datadog has made available in beta a Data Streams Monitoring tool that makes it simpler to identify upstream issues that are likely to impact DevOps workflows. Also in beta is a Dynamic Instrumentation tool that makes it possible to employ Datadog agent software to collect data on the fly from specific source code to investigate performance issues. Datadog is also making available in beta a Resource Catalog to make it easier to navigate cloud resources that IT teams are employing and has added a Datadog Workflows tool to create blueprints to for automating repeatable processes.

    Datadog is also expanding the reach of its Watchdog telemetry analysis service infused with machine learning algorithms to add beta support for containers. There is also now a beta of an Event Management tool that DevOps teams can employ to more easily investigate a stream of related alerts using the Watchdog service.

    The Datadog Continuous Testing service, now generally available, provides DevOps teams with a workbench for generating and maintaining tests that can be integrated within continuous integration (CI) workflows. Datadog has also added an Intelligent Test Runner tool, in beta, to enable DevOps teams to only run tests that need to run when a change is made by analyzing code execution paths to increase developer productivity.

    Renaud Boutet, senior vice president of product at Datadog, said the goal is to make it possible for DevOps teams to create and run tests from within the Datadog user interface in parallel using a set of no-code tools without having to employ scripts. The capability will make it possible to automatically generate tests using data collected by the Datadog platform as part of an infinite DevOps workflow loop, he added.

    At the same time, Datadog is making generally available a cloud security management service that combines its existing cloud security posture management (CSPM) service and the cloud workload security (CWS) service to provide an integrated cloud-native application platform (CNAP) at no additional cost. In addition, Datadog is making it possible to block access to application components that are under attack or might be attacked in real-time based on the known vulnerabilities detected using tools that are currently in beta.

    That approach reduces the total cost of cybersecurity by providing IT teams with a single service through which they can manage application security using a platform Datadog gained last year with the acquisition of Sqreen.

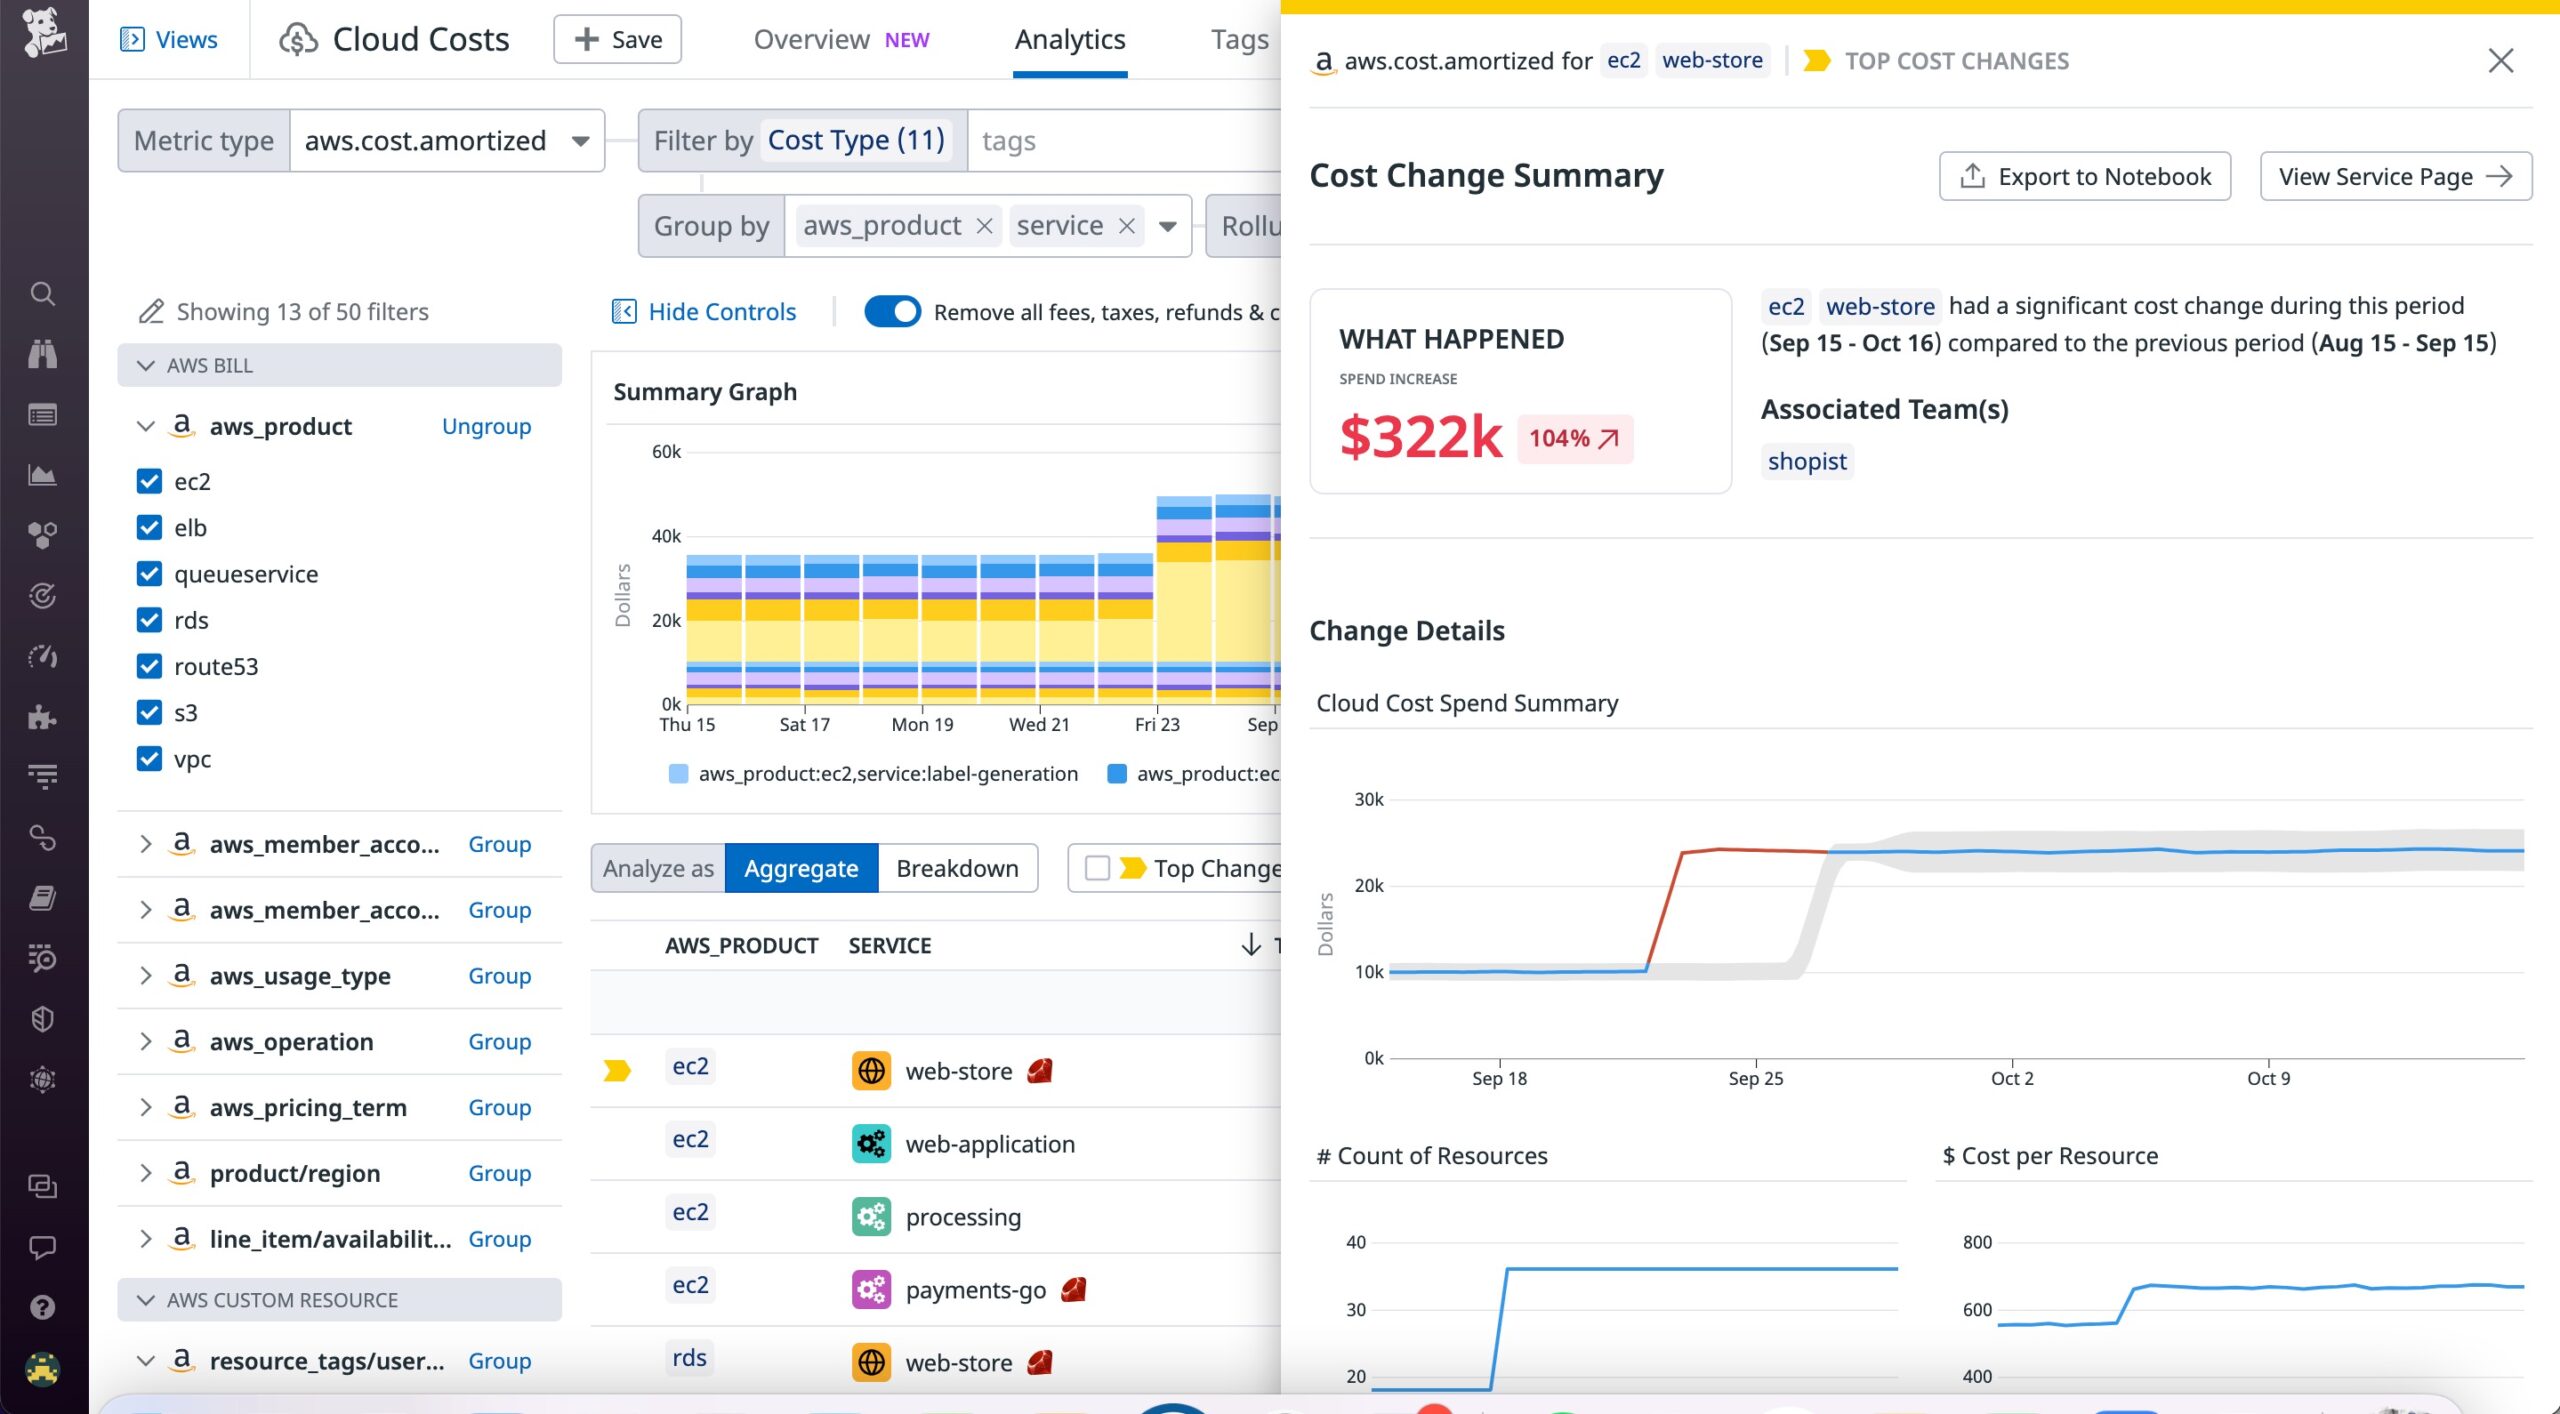
    Finally, Datadog is making generally available a cloud cost management tool that leverages its monitoring capabilities to enable organizations to automatically attribute spend to applications, services and individual teams. Changes to spending patterns that impact costs are surfaced alongside the same tools IT teams are already using to monitor their cloud computing environment. That unified visibility increases awareness of costs in a way that encourages DevOps teams to optimize the utilization of multiple classes of cloud resources.

    The services being added are extensions of a Datadog platform that employs a single set of agents it provides. The Datadog platform also supports the open source OpenTelemetry agent to deliver a wide range of services. That approach eliminates the need for IT teams to deploy multiple agents each time they add an additional monitoring, security, testing or cost management tool.

    Datadog has been making a case for an integrated platform that reduces the level of integration effort DevOps teams would otherwise need to expend when deploying separate point products to address monitoring, observability, security and cost management issues. That approach makes it easier for DevOps teams to collaborate and reduces the total cost of DevOps. In contrast, each time a DevOps teams adds a point product to address a specific issue, they need to deploy and maintain a separate set of agents.

    In the longer term, it’s not clear how problematic that agent issue will be once open source OpenTelemetry agent software is more widely employed. However, it may still be years before open source software provides the same capabilities that are available today using proprietary agent software.

    It may take some time before every application is as fully instrumented as it should be, but as monitoring and observability platforms continue to evolve, it is possible to more proactively manage application environments.

  • New Relic Reports Major Spike in Volume of Log Data

    New Relic Reports Major Spike in Volume of Log Data

    New Relic today shared a report based on anonymized data it collects that showed a 35% increase in the volume of logging data collected by its observability platform.

    The report also identified logs generated by NGINX proxy software (38%) as being the most common type of log, followed by Syslog (25%) and Amazon Load Balancer (20%).

    In addition, Fluent Bit is the most commonly used open source processor and forwarder tool (38%) among IT teams that have adopted the New Relic platform. Another 16% are using New Relic infrastructure agent, followed by 14% that send log data directly to New Relic via an HTTP endpoint.

    The report also found 50% of all logs ingested by language agents come from Java applications, followed by .Net (26%), Ruby (22%) and Node.js (2%).

    Jemiah Sius, director of developer relations at New Relic, said as more cloud-native applications are deployed, the volume of log data that is collected is only going to increase as open source OpenTelemetry tools are more widely adopted. In addition, IT teams will also be collecting metrics, traces and events to better pinpoint the root cause of issues using observability platforms such as New Relic One, he added.

    Amazon Web Services (AWS) is now, of course, one of the biggest sources of log data. The New Relic report noted that the serverless AWS Lambda service is the most widely employed source of log data among AWS customers that employ the New Relic One platform. However, use of the AWS Firehose service for extracting, transforming and loading (ETL) data has grown sharply in the last year, noted Sius.

    The New Relic report found while only 32% of New Relic accounts that use AWS have adopted Firehose, there has been a 62% increase in adoption year-over-year.

    Log data is usually the first thing any IT team consults whenever there is an issue, but as the volume of log data increases it’s becoming more difficult to associate log data with specific IT events. The issue that each IT team will have to come to terms with is how much log data to store alongside metrics, traces and other data formats to help them proactively identify the root cause of an IT issue.

    Observability platforms, in the meantime, promise to make it possible to query that log data to identify relationships between events. The goal is to enable IT teams to investigate issues before they can disrupt IT services rather than merely reacting to events after they have unfolded, said Sius.

    The hope, of course, is that machine learning algorithms will soon automatically identify issues before most IT teams even know there is a problem. Given the overall complexity of modern IT environments, it’s unlikely most IT teams even know what queries to launch to identify the root cause of an issue. Instead, as machine learning algorithms become more familiar with what constitutes normal IT events, it will become simpler for those algorithms to surface the issues that are actually worth IT’s attention.

  • Of Max and Min: When Performance Engineering Plans Go Awry

    Of Max and Min: When Performance Engineering Plans Go Awry

    Modern software developers have access to powerful tools and services which allow them to quickly develop, demo and deploy fully functional applications. But what happens when the single-user prototype satisfies all required functionality but the user says the system seems slow? Or if the initial implementation turns out fine for one user, but multiple users start to experience delays? Or if users are happy, but the cost of auto-scaling grows prohibitive?

    The Problem with Performance Engineering

    Concern over non-functional aspects of computing systems—response times, resource utilization and costs—falls under the domain of computer systems performance engineering (CSPE). Unfortunately, the practice of CSPE has evolved into something more akin to art than engineering—with few standardized principles and practices. Because software is constantly evolving its languages and abstractions, CSPE practitioners appear obligated to evolve and change their abstractions and languages, too.1 As a result, part of our jobs as performance engineers is to understand what the heck other performance engineers really intend or mean.

    There are many reasons for this state of affairs, but ultimately this lack of a common language and engineering standards for CSPE is a deficiency in the education and training of software engineers. There is very little in the typical university software engineering curriculum that prepares software engineers for doing CSPE. This sometimes leads to practices that are not backed by scientific or engineering principles. As a result, practitioners are forced to “wing it”—creating their own art or hitching their wagons to someone else’s star and learning (or not) through trial and error.


    The PMWG – A POSIX for Performance?

    The Performance Management Working Group (PMWG) was started in the late 1980s during the “UNIX wars,” when computer vendors were feuding over claims to the UNIX leadership mantle and had formed two factions: UNIX International and the Open Software Foundation. The group was unique in that its members included computer systems vendors on both sides of the “war.” Its members put aside those differences to try to come up with performance management standards and practices that would put UNIX on par (at least) with the performance management tools found on mainframes.

    In retrospect, the PMWG was probably the best chance UNIX had for establishing, promoting and enshrining some basic performance engineering principles—a kind of POSIX for performance. Unfortunately, the group failed—in large part, in my opinion, because it put too much priority on the latter stages of the performance management data pipeline and did not spend enough effort toward establishing key primitives. Today, in the absence of established rules and practices for performance engineering, history is repeating itself. Current efforts in observability continue to focus mainly on data presentation and data transport and storage, without much focus on the right metrics and data quality based on basic performance engineering principles. Presentation, transport and storage are important, but the efforts around metrics, logging and tracing coverage and data quality are sporadic at best.


    Inertia, Expediency and Superstition

    Why are more formal, engineering-based practices around CSPE needed? Consider the use of CPU utilization as a key performance indicator (KPI) of system performance. I’m a member of Bloomberg’s Trading Solutions SRE team, which manages hundreds of machines on which the company’s Trading Solutions software runs. We often see or hear statements like “This host’s CPU is too busy,” or “That host is out of CPU resources.” I’ve found that these observations are not actually very helpful and sometimes divert our attention from the real problem(s). When misused as a system KPI, focusing solely on CPU utilization can lead us down the wrong path and draw incorrect conclusions. To understand why, let’s first look at how we assess the performance of real-world, non-computing systems.

    Take fast-food restaurants. One of the most important attributes of fast-food restaurants (besides their health inspection rating) is that they are fast. But we’ve all been to fast food restaurants that are anything but fast. Without actually standing in line and waiting, we can often tell that we will have a slow experience at a fast food joint if there is a long line. The line length gives us a lot of information. Our assessment of the situation is different whether there are 100 customers versus 10 customers versus a single customer waiting in line.

    In the real world, this line length (or queue length) assessment is almost universal. Supermarket checkouts, ATMs, airport security screening, toll booths, elevators and COVID-19 testing are all areas where we apply this semi-conscious assessment. In contrast, we almost never use “cashier utilization” or “self-serve soda fountain utilization” as a way of assessing how slow a fast-food restaurant is. We always say “the lines are long” or, if we actually choose to wait in line, we’ll make the more direct statement that “service is slow.”

    Which brings us back to our computing systems. Why do we reflexively look to CPU utilization when computing systems are slow while, in the physical world, we rely on queue lengths? The question is even more relevant when we consider that the concept of CPU is less well-defined today. Are we measuring the CPU, its cores or hardware threads?2 I believe the contributing factors to this misuse include inertia, expediency and superstition.

    In the early days of computing, CPUs were perhaps the most expensive component of the large monolithic computer systems of the time. Measuring how much these expensive components were being used was an important part of maximizing the financial investment in these large machines. Fortunately, measures of CPU utilization were relatively easy to estimate. Ease of implementation meant that CPU utilization measures were almost universally available.

    The universal availability of this simple metric, combined with some correlation (sometimes weak) between high CPU utilization and system slowness made it a default indicator of systems performance. When a belief becomes ingrained to the point of superstition, even weak correlations are enough to validate and perpetuate it. Better metrics—for example, run queue lengths at the CPU(s)3—can help us shed our superstitions to better understand our systems and lead us in the right direction in identifying and correcting problems.

    Dispelling Superstition and Other Irrational Practices

    Which brings us to the title and purpose of this series. As a title, “Of Max and Min” is meant to evoke John Steinbeck’s classic novella “Of Mice and Men,” which in turn got its title from the famous line in Robert Burns’ poem “To a Mouse”: The best-laid plans of mice and men oft go awry. The two main characters in “Of Mice and Men” fail in their efforts to better their lives during the Great Depression because they are tragically ill-equipped to do so. Similarly, we should not be surprised if plans go awry when software engineers are tasked with doing performance engineering without the proper training in performance engineering principles.

    “Max and Min” also highlights the importance of data analysis and statistics in understanding systems behavior. Effective CSPE requires us to be familiar with concepts in statistics, numerical analysis, and even operations research—in addition to the more standard computer science areas of algorithmic complexity and computer architecture.

    With “Of Max and Min,” in addition to calling out superstitions, I will be pointing out some common mistakes we make and blind spots that we have.4 Through case studies, I’ll illustrate how our blind spots can lead to mistakes that can persist for years. I will also try to cover some basic CSPE principles that I believe are skipped in most software engineering training. Like everyone else, I’ve been winging it for 40+ years. And I’m still learning. If you disagree with any of my points or have further insights into the topics that I am presenting, please let me know.


    1But, as in the application of the principles behind algorithmic complexity, there are some performance engineering principles that can and should be adhered to regardless of the system and language du jour.

    2There are in fact some bizarre implementations of “CPU utilization”. Here’s an example of how AIX “broke” the meaning of CPU utilization on their multiprocessor systems running in hyper-threading mode.

    3UNIX and Linux do in fact have metrics that could be used as CPU queue length indicators.  In a future installment, I will go into the quirks of some of the CPU queue length implementations and further argue for more consistent mathematical bases for queue length metric implementations.

    4For example, have you ever wondered why, after so many outages caused by logging, malloc, DNS and other low-level services, we still don’t have good, out-of-the-box visibility into these and other low-level components? We are accepting key blind spots as a fact of life when we really shouldn’t.

    About Me

    Like many software engineers, I started off studying a different field (Physics). Unlike most software engineers, I’ve always wanted to be a performance engineer. When I started taking computer classes as an undergraduate in Columbia College’s Physics program, I did not wish for a career writing programs in Fortran (yes, it was that long ago). But I did envision myself making systems run better and faster.

    To that end, when I added a Computer Science major to my undergraduate studies, I also added a minor in Industrial Engineering and Operations Research. For those unfamiliar with IEOR, it is a multidisciplinary engineering field that leverages mathematical and analytical methods to address complex system problems like resource allocation, supply chains, wait times, fairness, etc. Tools and methodologies from IEOR are invaluable to CSPE.

    At the start of my career, I joined the Bell Labs Computer Center as a computer systems performance engineer, where I made the somewhat contrarian decision (for 1980) to work in the group supporting their in-house, low-key UNIX systems (as opposed to their commercially popular MVS mainframes). I didn’t realize it at the time, but having access to the source code of the system you support/study can be a boon to understanding. At Bell Labs, I had the opportunity to contribute to the UNIX System V kernel, where I co-developed the first general-purpose kernel and user-land tracing system for UNIX and made significant performance enhancements to the virtual memory subsystem, and participated in the PMWG.

    Since then, I’ve spent the bulk of my professional career working on financial software systems—ranging from market data to messaging to transaction management. I’ve worked on monitoring systems on an enterprise level. I’ve made and witnessed many CSPE mistakes. In my current role as an SRE on the Trading Solutions team at Bloomberg, I’m seeing and helping remedy lots of operating system issues that stem from our runtime scale.


    Thanks

    Thanks to everyone who reviewed this document and provided constructive feedback. Special thanks to Nate McNamara and Peter Wainwright for suggesting substantive organizational and structural improvements. Peter also reined in my default stream of consciousness, run-on style. None of them had any hand in the writing of this paragraph.


  • Implementing Data-Driven DevSecOps

    Implementing Data-Driven DevSecOps

    Right now, the way DevSecOps is typically implemented doesn’t fit with the rapid and agile DevOps CI/CD pipeline at all. It’s like applying 19th-century firefighting methods to a modern forest fire.

    Back then, firefighters employed a “bucket brigade,” where they would form a queue and pass buckets from one hand to another to put out a blaze. No doubt, it’s a lot of work, but much of the effort is wasted. Water inevitably spills out of the buckets as they are handed from one person to the next and by the time the bucket is emptied into the fire, half the water is gone. And not only is so much effort wasted, it’s far too slow and ineffectual to combat the kind of wildfires we face today.

    Likewise, the largely manual methods of current DevSecOps initiatives are ineffectual in fighting the fires of digital threats and cyberattacks modern mobile apps face. Like a modern megafire, these threats and attacks are growing and changing every second, seeking new vectors to spark new attacks elsewhere. Traditional DevSecOps tools like code scanning and penetration testing identify vulnerabilities and then the security teams start the manual “bucket brigade” to add as much protection as they can against them before the app has to be released. But neither the threats nor the CI/CD process has paused. New features have been added that have created new vulnerabilities, and the threat landscape has evolved. It’s inefficient because pentesting can’t provide the kind of real-time data about attacks and threats that developers need to provide protection against current threats. The result is the release of vulnerable mobile apps. 

    A Data-Driven Process

    In business, the C-suite is working hard to transform their companies into data-driven organizations where decisions are made not on the basis of gut feelings or expert opinion, but rather on analysis of hard data. That same approach needs to be brought to security implementation for mobile applications.

    Additionally, the implementation of security into a mobile app needs to be automated. With so much of the CI/CD process already automated, security cannot lag behind.

    These two elements combined create data-driven DevSecOps. In this method, the development and security teams have a system of record that provides real-time cyberattack and cyberthreat information about apps in the field, which drives decisions the team makes about the protections that are most urgent and that must be included in the next build. 

    It’s now well within the realm of possibility for mobile app developers to gather near-real-time information on exactly the kinds of threats and vulnerabilities that their mobile apps are facing in the field. When combined with location, network and other kinds of data, developers can gain a granular understanding not only of the most common threats their apps experience, but also which threats are most prevalent in specific geographic regions. They can also proactively identify the rapidly mounting threats that will become an enormous problem in the near future.

    With this data in hand, development teams can make informed decisions about which protections they should prioritize in the next build to make the best use of their time and resources to provide maximum protection to their end users. 

    The Need for Automation

    But having data isn’t enough. Development teams need the ability to act quickly on the insights provided, and manual implementation methods are too slow and cumbersome to keep up with the rapidly changing threat landscape for mobile apps. Once the decision is made, a system must also exist to automate the incorporation of mobile app security, anti-fraud and anti-cheat protections from within the CI/CD pipeline, so that security implementation runs as smoothly as feature creation.

    The advantages of data-driven DevSecOps are many. First, publishers, developers and security teams can understand exactly what cybercriminals are doing against their own apps with real users. With this data and the wealth of other data that organizations can collect from their apps, they can determine which threats are the most pressing, which are rapidly emerging and even how they are distributed among different geographic regions—all of which is extremely valuable information when deciding which protections to build into the next release.

    Finally, once the app is released, teams can use the data they receive about threats and attacks to prove the effectiveness and value of each protection that was included. It’s important information not only for continuous improvement, but also to justify the value of data-driven DevSecOps to management and the C-suite.

    With data-driven DevSecOps, organizations can provide data, transparency and visibility around security to all stakeholders in the CI/CD process—all while making the incorporation of security far more efficient and effective, along with the real-time data to prove it.

  • 5 Ways to Transform DataOps With Human-in-the-Loop Automation

    5 Ways to Transform DataOps With Human-in-the-Loop Automation

    We are in the middle of a data renaissance. Today, it’s not just about data instrumentation but also learning how to make DataOps a real business advantage for the entire organization. Data has become an inextricable part of products, used to enhance the quality of user experiences. Reliable access to data and the integrity of that data is imperative to drive innovation and business success.

    But just like any process, problems will arise. There will be pipelines that break or data that isn’t instrumented properly. The question then becomes, how can teams more quickly identify problems and continually improve? How can the journey toward data integrity become one of iteration and improvement?

    DataOps teams are by no means strangers to automation—automated CI/CD pipelines and infrastructure-as-code (IaC) are a huge part of their skill set. But there are some components of automation that are less pervasive throughout DataOps, ones that can help promote data integrity and encourage a culture of improvement. 

    It all starts with a different approach to automation—a human-in-the-loop (HITL) approach. Human-in-the-loop automation enables parts of a process to be fully automated while enabling humans to step in at critical points to take action, make decisions and decide the path forward.

    Here are five ways to use human-in-the-loop automation to drive continuous improvement and achieve optimal data integrity.

    Create Better, Earlier Interruption of Problems

    As is life, inevitably things break, issues arise and teams need to step in to remediate. The goal should be to enable better interruption of these problems when they do occur—identifying issues earlier and bringing the right stakeholders together more easily and swiftly.

    HITL automation can help teams not just identify issues earlier but kickstart the incident response and coordinate across teams and stakeholders. Ideally, automated workflows can be triggered from an incoming signal; for instance, from an observability tool like DataDog or BigPanda. An incident response could be started automatically, triggering further automation—like creating tickets, starting a Zoom meeting, creating a Slack channel and bringing together the right team members. 

    By instantly bringing the right people together, the team can investigate collaboratively and more quickly understand the state of the issue. HITL automation should then enable teams to run further scripts to take action and remediate as needed.

    Bake Improvement Into the Process Through Self-Documenting Workflow

    Many companies today are asking, “How do we make sure that we have that full integrated loop, down to the collection point?” Communication between teams is critical to this endeavor. But even before teams can collaborate on improvements, they need to understand the current state of their data so that if, for instance, a team finds that a report isn’t providing what’s needed, there’s a really clean way to get that communication back to the DataOps team to improve the instrumentation in the first place.

    HITL automation can bake improvement into DataOps workflows by automatically documenting every human and machine action throughout a process. Because it’s connected through APIs to all a team’s tools and services, a self-documenting workflow slurps up every action and creates an audit trail. This audit trail is the basis by which teams can more accurately understand not just the integrity of their data, but also how teams are implementing and running processes.

    Bring Human Data to the Forefront of Improvement

    DataOps teams play a big role in making sure the right data is being collected. However, a lot of people are still using systems that are very manual. They may have a good understanding of their log and monitoring data but still don’t have a good sense of the human data around their organization—what processes and workflows people are running.

    Understanding how humans run processes is just as important as understanding technology problems. The self-documenting workflow described above should include documentation of human data, from manually-run scripts to Slack or Teams conversations and, ideally, even auto-update tickets so even maintaining a system of record becomes less manual. Only by looking at the full picture—of human and machine data together—can teams find areas of improvement in their automation, communication and workflows.

    Take an Incremental Approach

    Don’t let “perfect” be the enemy of “done”. Every great transformation I’ve seen started with a small team, a great mandate, and strong support from the executive team. Adding tons of new technology and hiring more people may not be the silver bullet teams need.

    Instead, teams should look at the expertise they have in-house first—the people, technology and processes. Then, begin by taking an incremental approach. HITL promotes incremental, approachable automation by enabling teams to first codify institutional knowledge, analyze, learn and then begin to automate pieces in small batches.

    Diving head-first into a fully automated approach can leave teams in a worse state than nothing at all. Automation is a journey—we learn by doing, by recording human and machine data and then, using insights as our guide, begin to find real value in small doses of automation. These small steps can make a huge impact and, over time, add up to substantial business value.

    Buy for Industry Standards and Build for the Gaps

    As I mentioned above, teams should first start by evaluating their current resources. What skill sets and technology do they already have and how can they use those resources to achieve their data goals? At the same time, many teams starting their automation journey face challenges—lack of development resources, scripts that live on one person’s machine, difficulty bringing all the human and machine data together into a recorded timeline.

    To help data teams effectively and reliably implement HITL automation, investment into an off-the-shelf platform can help bridge the gaps teams and organizations have. Platforms should enable automation through low-code interfaces while providing code-level customization. This combination enables teams to buy for industry standards while building for the gaps—not managing the platform means development resources can be focused on expanding and improving automation.

    Platforms should enable teams to easily connect to APIs and adapt to custom APIs. The continuous change of DevOps processes and tooling coexist with rapidly changing APIs. Therefore, the most promising automation platforms must manage the complexity of APIs, enabling users to focus on the intent, not the mechanics of custom APIs. Automation technologies should seamlessly handle identity, authentication, pagination and caching. 

    Find Leverage With HITL Automation and Drive Business Impact

    As data becomes increasingly ingrained in product life cycles and user experience, automation holds the key to faster innovation, product quality and enhanced reliability. Creating a culture of continuous improvement and implementing technology like HITL automation that promotes data integrity throughout the product life cycle is where I’ve seen the greatest leverage for organizations. 


    To hear more about cloud-native topics, join the Cloud Native Computing Foundation and the cloud-native community at KubeCon+CloudNativeCon North America 2022 – October 24-28, 2022.