Category: Features

  • Collaborate more effectively with AppDynamics DevOps Virtual War Room

    Collaborate more effectively with AppDynamics DevOps Virtual War Room

    DevOps enables companies to move faster—but moving faster is not a worthy goal in and of itself. Organizations have to be able to develop and deploy solutions that are effective as well as expedient. It’s important to be able to monitor and respond to events in real time to ensure everything is running optimally, and to be able to create and implement fixes as quickly as possible when it’s not.

    At its AppSphere 2014 conference held in Las Vegas earlier this month, AppDynamics announced the latest release of the AppDynamics Application Intelligence platform—which is designed to help make application intelligence available so businesses can run faster, leaner, and more efficient. One unique element of the latest release is a new DevOps Virtual War Room.

    An AppDynamics press release describes the DevOps Virtual War Room. “It enables IT operations, development teams and business users to see and resolve problems together in a shared virtual space. The new release also enables scheduled, auto-delivered reports, and adds a new iOS app that sends push notifications to team members when system alerts are triggered.”

    Unless you can get all parties in one room, reviewing the same information, and discussing the issues and potential solutions, troubleshooting can easily devolve into chaos. Mixing various forms of communication—phone calls, emails, instant messaging, face-to-face, etc.—results in a modern day business form of the children’s game “telephone”. Statements get twisted, and bits and pieces of information get lost in translation as various parties attempt to work together.

    The DevOps Virtual War Room strives to change that dynamic by giving teams—even geographically separated teams—a single virtual space where all parties can come together to collaborate. Everyone sees the same data, and the individuals can discuss options and make changes to application settings and configurations together in real-time.

    Another benefit of the DevOps Virtual War Room is that it maintains a log of the communications and the changes that have been made. Valuable information about the root cause of the issue, the troubleshooting process, and the changes made to implement an effective solution are captured so that there is an audit trail to refer to if additional problems arise, as well as a historical archive that can server as a reference for future issues. The data collected from the DevOps Virtual War Room can be captured and indexed in knowledge management systems in order to streamline access in the future.

    “We’ve all seen the tremendously positive impact the DevOps phenomenon has had. With our new Virtual War Room and the other tools introduced today, we are catalyzing DevOps collaboration for troubleshooting, as well as application development, in ways that no other APM platform can do,” explained AppDynamics CEO Jyoti Bansal. “Performance isn’t just about technology, as critical as that is—it’s also very much about people working together closely to get things done faster and more effectively.”

    To be fair, there are a variety of other ways to accomplish a similar goal. Any number of Web conferencing or virtual whiteboard tools—including things like Skype for Business or Google Hangouts—could serve as a virtual meeting places where developers, operations, business stakeholders, and others could “meet” virtually to get things done. One aspect that makes the AppDynamics DevOps Virtual War Room different—if not better—is that it also brings the relevant data and information to the table, and presents it in a way that enables the individuals to analyze the problem and devise a solution.

  • Nationwide banks on DevOps to drive towards Continuous Delivery

    Nationwide banks on DevOps to drive towards Continuous Delivery

    The Financial Services industry is fast moving, highly regulated and customer-centric. The general perception in our industry is that any change in processes implies risk and delay, neither of which we can afford. But at the same time, we are faced by the mammoth task of needing to continually introduce new products and services to stay competitive and cater to the growing needs of our customers. This is unthinkable without a fast software delivery lifecycle, as our business is highly dependent on technology. The best way to accelerate software delivery in a complex, fast moving environment like ours is to adopt a DevOps approach.

    As a speaker at a number of events, I have discussed the ongoing transformational journey at Nationwide and shared our approach with other enterprises who want to understand how they can follow suit. I recently had the opportunity to co-present with Hayden Lindsey from IBM at the DevOps Enterprise Summit (Oct 21 – 23) hosted by Gene Kim. You can watch a replay of our joint session Patterns for Enterprise Success: The DevOps Journey at Nationwide below.

    From humble beginnings as a small auto insurer serving the farming community, Nationwide has grown into one of the world’s largest insurance and financial services companies. Like many businesses today, we saw that we needed a better way to respond to changing market requirements and regulations, to increase speed to market, and to support new channels for customer interaction. Mobile, cloud and big data technologies were further raising the pressure on us to facilitate rapid digital innovation. What we required was not just a solution, but a change in culture (the way we look at things), processes (the way we do things) and tools (the technology we use). DevOps gives us the capability to achieve all of this—and more.

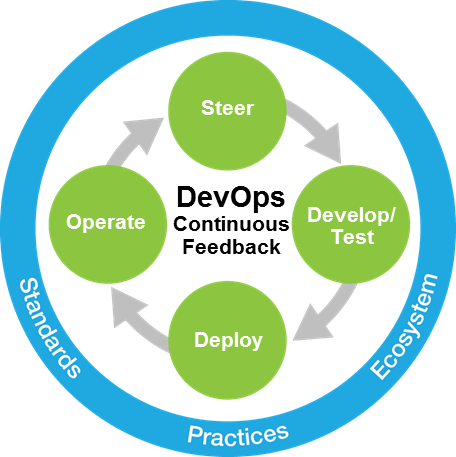
    The immediate challenge was to achieve these changes by leveraging our existing heterogeneous tool suite. We partnered with IBM DevOps, which has played a significant role in our success. We were already working towards agile transformation. With IBM’s support, we were able to use the DevOps approach to application development and delivery across our distributed and mainframe environments. While a DevOps approach as supported by IBM enables organizations to start anywhere based on their specific needs, we at Nationwide decided to address all four adoption paths across the software delivery lifecycle: Steer, Develop/Test, Deploy and Operate.

    devopspic

    DevOps enabled our IT department to perform continuous integration of its code and continuous deployment into its development environment several times a day. Teams can also perform acceptance testing of customer requirements within the same iteration as development. IT managers can show their internal customers, in near-real time, what developers are producing. This capability became a game-changer as we became more agile as a business and more responsive to customers. We achieved a 50% improvement in code quality, a 70% reduction in system downtime and were able to move 58% of our teams into the top quartile in key productivity measures. I believe that, the more agile we can be from an IT perspective, the more agile the business can be in terms of going from the development of an idea to the deployment of a customer-facing product.?

    The next step in our DevOps journey is to build on the gains generated by the adoption of Agile and Lean practices across the entire SDLC. This is where technologies such as TaskTop and UrbanCode come to the fore by providing the integrated continuous flow and visibility needed for a continuous delivery infrastructure. By creating this delivery highway, we are giving Business Areas the ability to deliver as fast as they need to based on their own determination of cost, risk and value. Time-consuming manual processes based on out-of-date information are replaced with automated deployment policies that use real-time information synched from systems of record. The combination of dashboard and dials gives the business the visibility and control to drive at a much faster pace than is currently possible. Lack of trust in development outcomes has historically been an impediment to speed. Our new automated approach is giving us the confidence to move faster to serve the business without compromising the quality of our deliveries.

    IBM was a great partner for us here as they share our support of the open standards approach, which gives us the ability to work with a heterogeneous set of tools, across the full lifecycle, allowing us to determine holistically the best tools, the best architecture and the best approach to meet our goals of high quality, high productivity and faster delivery for our customers.

    By balancing speed, cost, quality and risk, DevOps is helping us increase our capacity to innovate. That in turn helps us get to market faster and be more competitive. I mentioned during DevOps Enterprise Summit that the phrase “time is the new currency” resonated with our goals of optimizing the path from “concept to customer value”. We need to ensure we don’t let it slip through our fingers. We have long been dependent on manual processes, but in this new digital age they are only going to slow us down. This is the time to be agile, competitive and pragmatic. It’s time for all of us to break the age-old shackles and embrace the opportunity for change that DevOps represents.


    About the Author

    Carmen DeArdo is the Director of Application Development Tools and Technologies at Nationwide Insurance. Carmen is responsible for driving continuous delivery utilizing DevOps, Lean and Agile techniques across Mobile, Distributed and Mainframe and other technologies. This includes recommendations and implementation of technologies used across the development life cycle (e.g. IBM Rational tool suite, open source technologies).

  • Why “Enterprise DevOps” Doesn’t Make Sense

    Why “Enterprise DevOps” Doesn’t Make Sense

    Recently, some folks have been suggesting that we need a new form of DevOps, something called “Enterprise DevOps” or “Big DevOps.”

    DevOps is great, the argument goes, but large enterprises don’t operate the same way as the agile web startups where DevOps was birthed, and thus they can’t implement the same DevOps methodologies as those startups. Large enterprises have bigger teams, more inherent operational complexity, and greater governance controls (both self-imposed and externally-imposed); therefore, they need a different type of DevOps that caters to their sensibilities and not those of agile web startups.

    While it’s true that large enterprises do operate in a different environment than agile web startups, none of that makes a difference from the point of view of adopting DevOps.

    In short, if you’re advocating for Enterprise DevOps as something different than Plain Ol’ DevOps, then you’re missing the fundamental essence of DevOps.

    Here’s why.

    Early Thinking: DevOps = Tools + Culture

    To best understand DevOps, we need to understand where it came from.

    DevOps started as a bottom-up collection of best practices with few formal underpinnings. System administrators and developers were looking at the successes of agile development practices and trying to apply some of the same ideas to the whole development-to-operations process. Practitioners in the trenches stepped forward and said, “This is what we’re doing and it seems to work for us.”

    One of the earliest and most visible examples of that was John Allspaw’s and Paul Hammond’s presentation at Velocity in 2009, titled “10+ Deploys Per Day: Dev and Ops Cooperation at Flickr.”

    [youtube http://www.youtube.com/watch?v=LdOe18KhtT4]The video is well worth your time, as is the presentation on Slideshare:

    [slideshare id=1628368&doc=allspawhammondvelocity2009-090623161942-phpapp01]

    Note that this presentation predates the actual creation of the name “DevOps.” Allspaw and Hammond talk about how Dev and Ops teams can work productively together, but they never say “DevOps.” Patrick DeBois would coin the term later that year when he created the first DevOpsDays.

    In the presentation, Allspaw and Hammond discussed the success they were able to achieve at Flickr and provided a set of recommendations that they think are important, separated into two buckets:

    1. Tools
    2. Culture

    In the Tools category, they provided six recommendations:

    1. Automated infrastructure
    2. Shared version control
    3. One step build and deploy
    4. Feature flags
    5. Shared metrics
    6. IRC and IM robots

    Along the way, they mentioned that Flickr used:

    • Chef, Puppet, CFEngine, and other automation tools
    • SVN for version control
    • Hudson for builds
    • Ganglia for monitoring

    Finally, in the Culture category, they listed four additional recommendations:

    1. Respect
    2. Trust
    3. Healthy attitude about failure
    4. Avoiding blame

    Unfortunately, most people missed Hammond’s remark ahead of the Tools section of the presentation (timecode 7:40):

    These are some of the tools that work for us. They are not necessarily going to work for everyone, and throughout we’re going to give examples of the specific tools that we use, but the important thing that we’re trying to get across is the concepts that are important.

    In the years following, many self-proclaimed “DevOps engineers” (a bit of an nonsensical title if you understand that DevOps is about bringing Dev and Ops engineers together, not creating new types of engineers focused on nothing but DevOps) insisted that if you were automating your releases using Jenkins and Chef and treating the other members of your team with respect, you were “doing DevOps.”

    While Allspaw’s and Hammond’s presentation was excellent (seriously, spend the time watching it) and the advice was practical and valuable, many people walked away with only a vague notion of what would later be called DevOps.

    For instance, in the “One step build and deploy” recommendation, Allspaw and Hammond describe their automated system that moves code into production. Developers can click a single button to make a build live. The button is jokingly labeled “I’m feeling lucky” (in homage to Google, I’m sure).

    If you’re an agile web startup, that’s par for the course.

    But if you’re a large financial services company, you’re likely to think, “No! Our governance folks will never let developers push code straight to production with a single click, never mind the ‘I’m feeling lucky’ labeling. No way. Not gonna happen.”

    When people suggest that we need “Enterprise DevOps,” they’re typically reacting negatively to the choices that others have made. They recognize that those solutions won’t work for them for any number of reasons, and they say, “I can’t use that. I need something different.”

    But here’s the thing — DevOps isn’t about the specific implementation choices. Those are all optional. You can make a completely different set of choices than Allspaw and Hammond and still be “doing DevOps.”

    Unfortunately, subsequent conferences were filled with DevOps presentations that just reiterated the “DevOps = Tools + Culture” mantra and provided similar sets of recommendations that were often drawn from agile startups rather than from large enterprises.

    So, does that mean Tools and Culture aren’t important for DevOps?

    No, not at all. Both Tools and Culture are critical for DevOps in the long run.

    The problem that DevOps seeks to solve, however, is not a Tools problem or a Culture problem but rather something more fundamental.

    In order to understand DevOps, you need to focus on the ultimate goal.

    The Firm Foundation: The Toyota Production System and Lean Manufacturing
    The Phoenix ProjectIn 2013, Gene Kim, Kevin Behr, and George Spafford wrote The Phoenix Project: A Novel About IT, DevOps, and Helping Your Business Win.

    The trio’s contribution to the DevOps movement was in recognizing that enterprises had confronted a similar set of issues previously, but in a different domain — manufacturing — and that similar solutions could be applied to software engineering and application operations. (The group took another cue from the manufacturing world, copying the novelization technique from Goldratt’s The Goal to create a fictional case study where the characters were allowed to wrestle with the fundamental DevOps truths being discussed.)

    The key takeaway from The Phoenix Project is that DevOps seeks to create a smooth and increasingly speedy flow of change from development into production, with as little waste along the way as possible.
    The GoalThe models here were the Toyota Production System (TPS), Lean Manufacturing, and Goldratt’s Theory of Constraints.

    In the world of manufacturing, we have a physical product that moves through a factory, either on a formal assembly line, or from processing step to processing step, as part of a value stream. Each step along the path is supposed to “add value” to the product until it completes its journey and exits the factory to be shipped to customers.

    If you’re a manufacturing engineer, you need to do everything possible to create a smooth flow through the value stream by identifying constraints in the system and eliminating waste of time or resources.

    In the software world, application artifacts and changes move through the software development and operations value stream, with each step designed to “add value” and get the changes into production.

    If you’re a development or ops engineer, you need to do everything possible to smooth the flow through to production. The techniques you use are similar to a manufacturing engineer — you identify constraints in the system and go about eliminating waste of time and resources.

    The Kata is the Key

    Following Toyota’s success, the TPS and Lean Manufacturing were all the rage in the manufacturing world.

    Consequently, many western manufacturing engineers studied Toyota’s systems in great detail. They noticed a variety of tools and solutions that Toyota used to optimize manufacturing flow, and they recommended their use to their employers and clients. Toyota’s Kanban, for instance, was heavily promoted in the manufacturing world, and later made the jump to software engineering.

    Interestingly, the manufacturing world has suffered much of the same confusion that’s now happening in the DevOps world. When they tried to employ the tools and techniques they had learned from studying Toyota, things didn’t work as expected.
    Toyota KataMike Rother, author of Toyota Kata: Managing People for Improvement, Adaptiveness, and Superior Results, described the situation in the manufacturing world this way:

    Looking back, we naturally put Toyota’s visible tools in focus first. That is where we started— the “door” through which we entered the Toyota topic. It was a step in the learning process (which will also, of course, continue after this book). Since then I went back to the research lab–several factories–to experiment further, and present what I learned in this book. The visible elements, tools, techniques, and even the principles of Toyota’s production system have been benchmarked and described many times in great detail. But just copying these visible elements does not seem to work. Why? What is missing?

    Later, Rother continues:

    Toyota opens its factory doors to us again and again, but I imagine Toyota’s leaders may also be shaking their heads and thinking, “Sure, come have a look. But why are you so interested in the solutions we develop for our specific problems? Why do you never study how we go about developing those solutions?” Since the future lies beyond what we can see, the solutions we employ today may not continue to be effective. The competitive advantage of an organization lies not so much in the solutions themselves—whether lean techniques, today’s profitable product, or any other— but in the ability of the organization to understand conditions and create fitting, smart solutions.

    Focusing on solutions does not make an organization adaptive. For example, several years ago a friend of mine visited a Toyota factory in Japan and observed that parts were presented to production-line operators in “flow racks.” Wherever possible the different part configurations for different vehicle types were all in the flow racks. This way an operator could simply pick the appropriate part to fit the particular vehicle passing down the assembly line in front of him or her, which allows mixed-model assembly without the necessity of changing parts in the racks. Many of us have been copying this idea for several years now.

    When my friend recently returned to the same factory, he found that many of the flow racks along that Toyota assembly line were gone and had been replaced with a different approach. Many of the parts for a vehicle are now put into a “kit” that travels along with the vehicle as it moves down the assembly line. When the vehicle is in an operator’s workstation, the operator only sees those parts , and she always reaches to the same position to get the part.

    My friend was a little upset and asked his Toyota hosts, “So tell me, what is the right approach? Which is better , flow racks or kitting?” The Toyota hosts did not understand his question, and their response was, “When you were in our factory a few years ago we produced four different models on this assembly line. Today we produce eight different models on the same line, and keeping all those different part variations in the flow racks was no longer workable. Besides, we try to keep moving closer to a one-by-one flow. Whenever you visit us, you are simply looking at a solution we developed for a particular situation at a particular point in time.”

    As we conducted benchmarking studies in the 1980’s and 90’s and tried to explain the reasons for the manufacturing performance gap between Toyota and other automobile companies, we saw at Toyota the now familiar “lean” techniques such as kanban, cellular manufacturing, short changeovers, andon lights, and so on. Many concluded— and I initially did too— that these new production techniques and the fact that Western industry was still relying on old techniques were the primary reasons for Toyota’s superior performance.

    Rother concludes that the secret to the Toyota Production System and Toyota’s success was not any one particular tool or technique, but rather the Toyota Improvement Kata, which focused on continuous improvement of everything at Toyota, seeking to establish flow and eliminate waste.

    Toyota Kata is a great book and if you want to understand DevOps, I encourage you to get a copy and read it for yourself. Kevin Behr recommended it to me and I was pleased to see Jez Humble reference Rother’s story, above, in his recent QCon talk on DevOps.

    What is DevOps?

    So, after all that, what are we left with?

    What is DevOps?

    Cue the trumpet fanfare…

    Fundamentally, DevOps is the activity of optimizing the development-to-operations value stream by creating an increasingly smooth, fast flow of application changes from development into operations, with little waste. Optimization of the value stream takes place continuously using various continuous improvement techniques like the Toyota Kata.

    “Is that it?!” I hear you cry.

    Yes, that’s it.

    “No way!”

    Way.

    “But what about Tools and Culture?! What about continuous delivery and Jenkins?! What about automation? What about mutual respect?!”

    Yes, those are all in there, too. But those are the equivalents of Rother’s “kanban, cellular manufacturing, short changeovers, andon lights, and so on.” They are solutions to particular problems that you might be faced with.

    If, during the course of trying to optimize your value stream, you’re faced with the problems that those tools and techniques solve, then you might try them out as solutions. Or you might not, if your situation dictates differently.

    The key is to understand that simply deploying a tool or even a broad solution without thinking through your unique situation and the current state of your value stream and its current constraints is foolish. After all, the specific solutions that are applicable to an agile web startup have a high likelihood of being inapplicable to a large enterprise. And vice-versa.

    Why “Enterprise DevOps” Doesn’t Make Sense

    So, that brings us right back to where we started.

    Enterprise DevOps doesn’t make sense because it confuses the forest for the trees. Those advocating for Enterprise DevOps make the mistake of focusing on specific tools and solutions (Jenkins, Kanban, etc.), then find them wanting for various (extremely valid) reasons in an enterprise context, and then reject DevOps in favor of Enterprise DevOps, which they suggest is somehow different.

    But DevOps is about flow and continuous improvement, not about specific solutions. Flow and continuous improvement are equally applicable to a large enterprise as they are to an agile web startup. And if you miss that, you’re lost, regardless of the tools and solutions you choose.

    To implement DevOps, you need to learn how to map your value stream, identify the constraints in it, and then use a continuous improvement kata to develop specific solutions for your particular problems at this point in time in your particular organization.

    If you’re a large enterprise, the problems and constraints that you face will undoubtedly be different than those of an agile web startup. So, you’ll necessarily need to select different solutions.

    That doesn’t mean you “aren’t doing DevOps!”

    Rather, it means that you’re doing DevOps correctly.

    And remember that whatever solutions you come up with to your particular problems and bottlenecks, they are likely to be temporary. As Toyota said to Rother’s colleague, solutions are only applicable to a particular problem at a particular point in time.

    Epilogue: A Bitter Irony

    Some of the earliest work on what would become DevOps grew out of some ideas that Andrew Shafer was kicking around in late 2008.

    At the Agile 2008 Conference in Toronto, Shafer proposed a birds-of-a-feather session about “Agile Infrastructure.” Only a single person showed up — Patrick DeBois. He found an empty room. It turned out that Shafer skipped his own session because he received such poor feedback about it and thought nobody was interested. Shafer and DeBois later discussed Agile Infrastructure and many ideas that would later become DevOps in the hallways at the Agile 2008 Conference.

    Shafer also presented on Agile Infrastructure at Velocity 2009:

    [slideshare id=1637386&doc=velo09-agile-inf-090625020850-phpapp01]

    Note slides 92 through 97. The key points from this sequence are:

    • Dogma Sucks
    • “Do not seek to follow in the footsteps of the wise. Seek what they sought.” This is a quote from Japanese poet, Matsuo Bashō.
    • The Tao that can be spoken is not the eternal Tao.
    • You are a special snowflake, just like everybody else.

    Even from the start, Shafer was on to the point that a binding set of rules is self-defeating. DevOps cannot be codified in a set of rules. Because it’s bigger than that.

    Note the Matsuo Bashō quote:

    Do not seek to follow in the footsteps of the wise. Seek what they sought.

    The wise DevOps practitioners do not seek to implement any given tool or technique out of adherence to DevOps dogma. Rather, they seek to create a smooth, quick flow of changes through the value stream. Do not try to follow in their footsteps using the exact same set of tools or techniques, but rather seek the same thing that they seek and find your own way to the same destination.

    So, the bitter irony here is that we’ve been warned all along, by Shafer, Allspaw, Hammond, and others, to focus on the foundational problems, not the specific solutions they have employed. Yes, we can learn something from their experiences, but every situation is unique.

    (Unfortunately, I haven’t been able to find video of Shafer’s Velocity 2009 presentation. If you find it, let me know. But you can see a later version of Shafer’s ideas, mixed with those of Paul Nasrat, in a presentation from Agile 2009, made available on InfoQ.)

    Other Resources

    I’ve hopefully salted this post with enough links to key presentations and resources, but there’s one more that should be included. If you’re at all interested in the history of DevOps, and you should be if you really want to understand it better, then you need to view Damon Edwards’ “The (Short) History of DevOps”on YouTube:
    [youtube http://www.youtube.com/watch?v=o7-IuYS0iSE]

    Connect With Me

    Think I’ve left something out or put too much in, got it totally wrong or completely nailed it? Let me know! Continue the conversation by commenting on this post and following me on Twitter.

    About the Author

    dave-roberts-headshot_400x400Dave Roberts brings 25 years of technology experience to his role of Executive Advisor at BMC Software. A thought leader in agile IT and digital transformation, Dave routinely speaks at conferences around the world. Dave is a member of the Twitter #clouderati and blogs at BMC.com and Leverhawk.com. He holds nine patents and has written three books on computer programming and data communications technology.
  • Survey: DevOps gaining mainstream traction in IT today

    Survey: DevOps gaining mainstream traction in IT today

    New survey results released last week shows just how thoroughly DevOps has captured the mindshare of enterprises. Commissioned by Rackspace, the global Vanson Bourne survey showed that more than three-quarters of IT decision-makers are now familiar with the term DevOps and well over half of them have already implemented DevOps practices to some degree or another. And by 2017, that figure could go up by another 31 percent according to survey respondents’ plans.

    “This survey shows a real appetite for the kind of development and operational processes today’s digitally-focused businesses need,” said Chris Jackson, CTO of DevOps Services at Rackspace.

    Among those who have chosen the DevOps route, nearly half have already fully integrated their development team with their operations team and 38 percent say that integration is in effect for all of their applications. For the most part, the ops team has been the primary champions for these projects. Approximately 43 percent of respondents with DevOps programs in place report that IT operations have driven them and 32 percent say either the CIO or the CTO have driven the program. Just 16 percent say developers have been behind their DevOps transformation.

    As expected, among respondents who have deployed DevOps, 57 percent have already experienced faster delivery of new features and 46 percent have a more stable operating environment. Additionally, 43 percent reported increased innovation and 32 percent have even reduced their IT costs.

    However, it is the business upsides of respondents’ DevOps adoption that are really eye-opening. The speed and innovation seems to have directly translated to improvements in the business as a whole. Over half of companies that have implemented DevOps report an increase in customer conversion and satisfaction and 43 percent say they’ve seen an improvement in customer engagement. As a result, DevOps is stimulating topline revenue growth, with 38 percent of respondents reporting an increase in sales as a result of their revised IT approach.

    “DevOps is empowering IT functions to make a real impact on the business,” Jackson said. “It is also finally an opportunity for IT to be recognized for having a central part to play in delivering great customer experiences and ultimately increasing sales.”

    However, deploying DevOps has not always been easy for these organizations. Approximately 37 percent of respondents who’d embraced DevOps reported internal resistance from ops teams and 32 percent said developer resistance posed problems. Fortunately, less than a quarter of wider business stakeholders  stood in the way of DevOps adoption. Nevertheless, among all IT decision-makers, 41 percent still said they had other more urgent IT priorities that kept them from the DevOps journey.

    “DevOps is all about encouraging innovation and streamlining processes to help ensure development and operations are working hand in hand to deliver business objectives,” Jackson said. “While, the findings suggest that the DevOps journey is already becoming well established in many organizations, there is still a job to do in articulating the benefits to all groups involved for them to accept and drive through this change.”

  • Automating Away the Regulatory Compliance Myth

    Automating Away the Regulatory Compliance Myth

    At the recent DevOps Enterprise Summit, we had a chance to sit down with Justin Arbuckle and discuss his concept of “compliance as code” and why it’s so important that security and compliance tests be built into DevOps practices at large enterprises. Recently, Arbuckle was chief architect at GE Capital where he introduced and sponsored DevOps at that organization – so he certainly knows about what it takes to “do DevOps” in large, highly regulated environments.

    Currently, Arbuckle is the vice president of EMEA at CHEF and also chief enterprise architect there. If you watch his talk from the DevOps Enterprise Summit, Hunting the DevOps Whale, you’ll see that he is passionate about the transformative potential of DevOps in large enterprises.

    At CHEF, Arbuckle is in helping large enterprises understand how to “de-risk” their migration to cloud with automation. We caught up with him at the DevOps Enterprise Summit to ask why that is so important. Here’s what he had to say.

    staging-devopsy.kinsta.cloud: When it comes to DevOps and regulatory and security concerns, many people say, “Well, just automate those tests.” What does that mean, to you? How do you “automate in” security and compliance?

    Arbuckle: I think, in terms of the specific issue of regulatory compliance, a lot of what we think of as the being compliant process today is a complete myth. There is just so much detail that needs to be checked that the organization is always in a position where they have to trade off against, “It’s good enough, we’re ready to go” versus, “We’re not going to go anywhere until we’ve literally crossed every T and dotted every I.”

    The reality is that a lot of the regulations, Dodd-Frank is a good example, are getting to a level of detail where they’re beginning to talk about process. They’re beginning to talk about how you design product. They’re getting very deep indeed.

    So the organization that has to govern that, can’t do it based on just this idea of oversight at particular points in the life cycle. Because if you’re going to do it properly you literally slow your velocity to zero, and so you’re making a trade-off between compliance and competitiveness.

    The way to break that cycle is to, and this is a big paradigm shift for regulators, a big paradigm shift for compliance people inside organizations, you have to start being able to express those compliance requirements in a form that’s codable. Using something like Chef for instance what we’re able to do is we’re able to specify a particular policy in a way that is automatable. In a way that we know is always going to be implemented every single time.

    staging-devopsy.kinsta.cloud: Would that include input from security people, compliance teams, design teams, system architects?

    Arbuckle: Absolutely. Honestly, in my experience I think the number of organizations that can count fully detailed, fully implementable — and that’s the key word — security policy by their infrastructure people is countable on one hand.

    Generally speaking, there are many obvious guidelines that are standards-based. But as the security organization tries to keep up with security threats, they’re obviously learning as they go. In this way policy always lags. And the only way for the organization to catch it is through this process of documentation, policy, and checks. And through it all they know that the standard is nonsense because it’s out of date by definition. So they have to create a point-in-time review. And these point in time reviews bring velocity to a halt.

    staging-devopsy.kinsta.cloud: Yes. Especially when something is wrong. They hit a red button and everything stops coming off the assembly line.

    Arbuckle: That’s right. The approach that we have to get to is the idea of policy as code. But you are not going to be able to, on the first go, be able to codify everything. Very often with automation, based on my experience, is that the difficulty at large enterprises has actually less to do with the tools and more to do with knowing what you want to automate. Knowing what you actually want to put in infrastructure as code.

    It’s the same thing with security teams. Ask them to go through the most important things that need to be tested in automation, and getting them to go through that process. It’s often difficult because they are not development people typically. They’re not infrastructure people, And they’re not operations people.

    They’ve kind of created their own “securocracy” if you like.

    What security teams have to do is understand their work is subject to source control as well. Their work is subject to variation and evolution over time and we should write tests to ensure that the following policies are being applied consistently.

    DevOps: And I assume these tests are designed over time, as one goes along? For example, if there’s a new malware or regulatory beast that you haven’t seen before, you can design a test and then implement that as part of the life cycle?

    Arbuckle: That’s exactly right. And the great thing about tests is they are additive. You’ve got a test that tests for the range of ports that are open on the operating system and then you add another test, maybe testing for the types of applications that are installed on the box. They are two separate tests and they are additive. So as you continue, you build up your library of tests.

    And for most organizations going through the adoption of test driven development, as an example, they have to do it that way. A large application that is beginning to develop in an agile way is going to have a lot of tests. If you take a typical large core banking application, for instance, it will probably have something in the region of about 5,000 use cases. That’s thousands and thousands of tests. Let’s just agree that in no short period of time are you going to write those tests.

    staging-devopsy.kinsta.cloud: That’s an enormous catalog of tests. How do you keep them up to date and fresh? I imagine as security changes, regulatory compliance changes, you may have to tweak these tests as you go along. How do enterprises keep up?

    Arbuckle: Like any requirement you have stakeholders that are responsible for those requirements. In just the same way, if you had for instance a mobile application and you have a product owner for that mobile application and that product owner is prioritizing feature sets you should also have a product owner for compliance.

    And the product owner should be detailing what the set of compliance requirements are for the product.

    Essentially compliance is embodied in the tests that are run against the appropriate applications. And so to manage automation and compliance as code, you need to have a product owner for compliance. And compliance as code, or automation, is the way it has to be in order for compliance to actually be true and consistent, as opposed to a myth.

  • Microsoft determined not to get left behind by DevOps

    Microsoft determined not to get left behind by DevOps

    Microsoft is a massive company—a behemoth with a lot of inertia, and a lot of bureaucracy in place that make it difficult to adapt quickly. Under Satya Nadella, however, Microsoft is striving to re-invent itself, and—to the extent that it is possible—become more agile. For evidence of Microsoft’s new philosophy, look at how Microsoft is aggressively embracing concepts like open source and DevOps that used to be viewed as pariahs.

    I wrote recently about the partnership between Microsoft and Docker. Microsoft added support for Docker containers in the Azure cloud platform within Linux virtual machines earlier this year, but then it upped the ante by announcing that it will support Docker natively in the next version of Windows Server, and that it is working closely with Docker on an open source project to drive development of the Windows engine for Docker.

    “An important aspect of this announcement is the noticeable speed we are observing Microsoft move to implement open source technologies,” explained Al Gillen, an analyst with IDC, in a report about the relationship between Microsoft and Docker. “The company appears to be determined not to be left behind as the velocity of open source developer technologies accelerates. The company appears to be willing to integrate competing technologies, or technologies from competing ecosystems at a faster pace and with less hesitation.”

    Docker isn’t the only piece of the puzzle, either. Earlier this year Microsoft joined forces with Chef and Puppet Labs, and integrated both of those popular DevOps platforms into Azure as well. Incorporating Chef and Puppet Labs gives IT admins more flexibility to deploy, configure, automate, and manage VMs in Azure.

    What the new philosophy really represents is a realization. Nadella’s Microsoft sees the writing on the wall, and understands that it’s a new world. Technologies have changed, and the way companies and individuals use technology has changed, and the days of dominating the tech universe as a virtual monopoly are gone. The two choices facing Microsoft were to either stubbornly cling to its former glory and die a slow, painful death, or adapt and embrace change in order to remain relevant, and continue to play a vital role. Thankfully, it seems Microsoft has chosen the latter path.

    What does embracing change look like? Microsoft appears to be taking a two-pronged approach. On the one hand, Microsoft is changing internally to shed some of its entrenched bureaucracy and enable it to function with more agility. It is also striving to keep up with new technologies itself—buying Nokia to bring smartphone manufacturing in house, developing the Surface tablets, rolling out the Microsoft Band wearable health tech, and other initiatives demonstrate that Microsoft is working hard to break free from the shackles of its own past, and find ways to keep up with the changing tech landscape.

    The second—and arguably more important—prong is how Microsoft is addressing the new multi-vendor, cross-platform world we live in. Microsoft recognizes that it is not the only game in town, but it has a vested interest in ensuring that customers continue to rely on Microsoft tools no matter what platform they choose. To that end, Microsoft is doing a much better job of offering its own products and services across a wider range of devices and platforms.

    The new Microsoft represents a win-win-win scenario. It’s a win for Microsoft because it enables the company to shift and evolve to stay relevant with a rapidly-changing tech landscape. It’s a win for open source and DevOps because companies of all sizes are built around Microsoft operating systems and applications, so incorporating support for open source and DevOps tools exponentially increases the potential customer base. Finally, it’s a win for the customers themselves because they get to maintain their existing investments in a Microsoft infrastructure, while also gaining access to new tools that enable greater automation and efficiency.

  • How to Enhance DevOps by Supporting the Work of the Build-Release Engineer

    How to Enhance DevOps by Supporting the Work of the Build-Release Engineer

    Support Through Freedom

    As we’ll see, supporting the work of the build-release engineer enhances DevOps by adding consistency, easing minds, and freeing DevOps teams to do more. To support the work of the release engineer, the enterprise must set them free as well, by letting them automate everything, treat manual interventions as process failures, and configure the target deployment machine and its monitoring context.

    Enable the Release Engineer to Automate Everything & Treat Manual Interventions as Process Failures

    One of the best ways to support the work of the build-release engineer is to encourage them to become actively hostile to manual interventions, says Robert Fischer, VP of Engineering, Webonise Lab www.webonise.com. Release engineers should shoulder the responsibility for putting manual interventions out of reach.

    An enterprise’s internal DevOps community should empower the release engineer to automate as many steps as possible, which may require the enterprise to give them programmatic access to environment credentials, says Fischer. “For the internal DevOps community, the reward for permitting this risk is that they will have a cleaner environment that everyone understands better. This will make it easier for them to respond correctly in stressful situations,” says Fischer.

    “So, let’s say you have some Linux VMs spinning up as part of the release. The release engineers could be tempted to use some kind of global SSH key for accessing these VMs, which they would install nicely on their laptops or workstations,” starts Fischer. Unfortunately, this will make it easy to add undesirable and unnecessary manual steps such as “‘Log in and set this IPTables value’ or ‘Log in and manually determine this hostname’”, says Fischer.

    And while it would be easier to enable and apply these changes in the short run, it would leave a monkey wrench under the hood of automation and discombobulate the efforts of DevOps true believers in the long run. And it would all start simply by enabling the global SSH key and making these manual steps possible.

    These kinds of manual processes also crop up in branches in the release logic: ‘Login to the server and see if packages X, Y, or Z are up-to-date in the image. IF they aren’t, THEN…’ All of that needs to be automated. “If the release engineers make it hard to implement manual steps, then they are more likely to A) notice and B) avoid these manual dependencies,” clarifies Fischer.

    Instead of making manual steps possible, the release engineer should create active blocks for manual intervention, such as putting virtual machines within a virtual private cloud or making them only accessible using the automation tools’ SSH keys, says Fischer. This will actively impede manual interventions like those first cited herein and force the release engineer to think. “The result is that you are more likely to build the appropriate automation steps and error handling instead of creating a dependency on manual intervention,” says Fischer.

    Empower the Release Engineer to Configure the Target Deployment Machine and It’s Monitoring Context

    Another way to undergird the work of the release engineer is to open up the target deployment machine and monitoring context configurations to them. To enable the release engineer to configure the target deployment machine, make tools like Docker www.docker.com available. To enable them to configure the monitoring context, automate the configuration of the virtual machine platform (e.g.: AWS http://aws.amazon.com security groups, load balancers, etc.). “This allows for tuning to be a part of the release planning,” says Fischer.

    The enterprise DevOps folks can still make manual adjustments if they must, but they should resist the impulse to use that option, except when handling anomalies. “Leaders in enterprise DevOps approaches can audit these deployment instructions for sanity and compliance, of course,” says Fischer.

    As is the case with automating otherwise manual processes, the enterprise DevOps team should have a lot less to worry about once they set the release engineer free to configure these things. “This should give them more time to tackle the hard and interesting problems instead of performing repetitious and error-prone manual interventions by letting the computer handle the brain-dead computational and rote part of DevOps, which is what computers are good at,” says Fischer.

  • Capacity planning isn’t dead, but it’s not about supply any more

    Capacity planning isn’t dead, but it’s not about supply any more

    DevOps, flexible cloud architectures and continuous delivery have all simplified a lot of equations in IT today, but there is one element that’s grown infinitely more complex: capacity planning. With the ability to spin up new environments on a dime through services like Amazon and Rackspace, the bucket of potential IT supply has grown infinitely more flexible. Meanwhile, as DevOps practices helps organizations speed up the continuous delivery cycle of designing, building and running new application instances, the demand for computer power and storage space is constantly changing. This week at Camp DevOps Houston (link), Steve Wilson with VMTurbo will explore what this means for capacity planning in his talk “Is Capacity Planning Dead?”

    “In this cloud day and age, it really isn’t about capacity anymore, because capacity becomes a figurative thing with IT borders and the data center really just melting away,” Wilson says. “I can rent if I need to. Really this idea of capacity goes away, and what you really want to understand is where’s the cutoff where I stop buying and I start renting?”

    Wilson believes that while capacity planning isn’t necessarily DOA in today’s DevOps world, it does need to be completely turned on its head. Rather than focusing on supply-side issues, planners need to concern themselves much more with demand.

    “For eons and eons, we have been really good at managing supply—because it never changed. It was finite. It was like ‘OK, I’m going to put alerts, and I’m going to put thresholds, and I’m going to set the bar, because I know that when my supply runs out, that’s bad,’” Wilson says, explaining that capacity planning was all about moving thresholds to ensure IT never ran out of supply. “But now, if it’s a truly software-defined data center, it’s no longer defined by your infrastructure. So what if I could actually manage demand — not supply.”

    The idea, he explains, is to gather a deep and continuous understanding of what demand is in order to buy infrastructure for the average demand and then ‘rent’ cloud infrastructure to soak up the peaks of demand when they present themselves.

    “If I understand demand, I can buy for my 50th percentile plus maybe one or two standard deviations, and then rent above that and scale out,” he says. ” then all I really want to do is collapse that line of getting a good understanding of where that financial line is where it is economical for me to extend CapEx internally, and then that tipping point where it’s actually cheaper for me to extend OpEx to handle the peaks.”

    With DevOps, he believes it may be easier for organizations to truly understand the demand profile of different applications, due to greater collaboration between developers and operations staff. The trick is to ensure that capacity planners are roped into the design, build, run cycle from the beginning, as they are currently operating in the fringes, frequently using spreadsheets that are outdated as quickly as they are made when an organization is delivering continuously.

    “Suddenly, every time you try to make a change, you try to deploy, you’re playing whack a mole, and then you start to break down. One place you’re hot, the other place you’re cold, and you don’t understand the demand workload and you can’t move it around and you’re just managing supply,” he says. “If I can always understand and map demand properly, I can automate the crap out of that, because now I’m basically creating just-in-time compute. If I can run computes super lean, then at peak I can just rent.”

  • Separation Anxiety & the Leap from Dated IT Approaches to DevOps

    Separation Anxiety & the Leap from Dated IT Approaches to DevOps

    Never ASSUME!

    I assumed that the drag on moving from IT as we knew it to a DevOps approach (with its continuous software deployment and other advantages) was due to the separation anxiety and fears of loss or change on the part of enterprises on the whole. As you may know from the 70’s TV show, The Odd Couple and its character Felix Unger, played by Tony Randall, you should “Never ASSUME, because when you ASSUME, you make an ASS of U and ME.” *

    And so I was mistaken, but not far off from the truth. “I don’t think that enterprises as a whole fear change so much; what I think happens is that individuals fear change and erect a number of barriers to change,” says Alan Baker, President and Chief Consultant, Spitfire Innovations (link), a business process optimization consultancy. Let’s investigate some of those fear-based barriers.

    Barriers to DevOps, Based in Fear

    The first barrier is resistance due to a loss of knowledge. “There are individuals within IT who have built their careers around the current practices and approaches,” says Baker. These IT professionals have developed reputations as subject matter experts, which they truly are. This enhances their value, but only so long as the current subject matter retains its value. By moving to DevOps and making material changes to the way developers and IT operations accomplish their work, the enterprise will diminish their knowledge as well as perhaps their status and their usefulness to the company. They have a vested interest in the status quo. They would have to have more to gain by joining DevOps than by opposing it in order to move to a more progressive approach to change management, according to Baker.

    The second barrier is political; it’s the loss of control. IT professionals who shoulder accountability for operations day in and day out are typically averse to loosening their grip on how change is introduced into their environment. “That’s understandable, because once something is productionized it’s their responsibility; they want to be completely sure that the deliverables are defect-free,” says Baker. For this reason, these individuals are going to need assurances that the new processes will maintain the integrity of the deliverables, says Baker.

    The third barrier is structural. In an environment where some form of management by objectives is practiced there is typically little alignment of objectives between different groups. “Day-to-day operations typically have objectives relating to efficiency (such as throughput), whereas development objectives are driven by dates and cost,” says Baker.

    Reaching for Change

    If the enterprise is going to break down these barriers and change its practices, all the stakeholders need to come together and agree on a plan of action. The stakeholders, including anyone tempted to resist DevOps, need to fully and collectively develop the future state of the enterprise, focusing on shared objectives. “All groups that are concerned need to have a set of common goals to work towards that satisfy all stakeholders,” says Baker.

    There also need to be necessary supports. A DevOps approach requires increased integration and communication between all of the stakeholders. The walls need to come down. “This openness doesn’t necessarily come naturally to all IT staff; the organization will need to invest in the appropriate education and expert guidance (as well as some patience) to ensure that the cultural change has a chance to take root,” says Baker.

    The final item consists of two value propositions. These value propositions give the organization the opportunity to demonstrate its vision, transparency, and resolve. The first concerns the need of the organization for someone to take an approach that answers the who, what, when, where, why, and how questions surrounding DevOps activities and responsibilities, and then to clearly articulate all aspects of the change to everyone. It’s a necessary step in order to get the buy-in. The second value proposition is directed at the individuals impacted by the change. Help answer the question ‘What’s in it for me?’, particularly for those individuals working themselves out of a role.

    *It was one of the show’s funniest and most memorable lines and is repeated to this day. Though proper attribution for the original comment may ultimately be out of reach, see http://en.wikipedia.org/wiki/Jerry_Belson for the Television Writer who placed it in the Odd Couple episode.

  • Eight critical DevOps practices:  innovate, deliver, repeat

    Eight critical DevOps practices: innovate, deliver, repeat

    DevOps has been garnering a lot of interest for some time. Discussions and debates on forums like staging-devopsy.kinsta.cloud are improving our collective understanding of the right approach and now we are seeing concrete proof points of fast-movers applying DevOps practices to disrupt entire industries with rapid-fire, digital-innovation based on Cloud, Big Data and Mobile technologies. I have personally been part of this transformation at IBM for several years and would like to reflect on what we have learned, and also share with you results of a recent study from Forrester Research.

    DevOps helps organizations address a critical business challenge – that of continuously capturing and responding to feedback (both internal and external) so we can rapidly and repeatedly turn innovative ideas into highly relevant, and desirable, products and services.  This involves not only development and operations, but all aspects of the organization, as it entails the collaboration across the entire organization including business and supply chain. Compared to single-direction,  traditional models, DevOps is bi-directional and is based on not just pushing something out to the customer but also on getting their feedback to make improvements.

    In a recent webcast, I discussed eight DevOps practices that speed up software delivery with Kurt Bittner, Principal Analyst at Forrester and a leading expert on agile and iterative software development. This webcast highlighted a recent Forrester survey on DevOps practices, cycle times and where enterprises are in terms of the maturity of DevOps practices adoption. 
    You can watch the webcast replay here to know more –
    ibm.biz/Forrester-talk

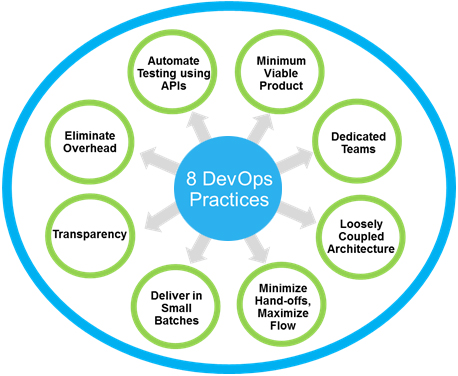
    Their survey of 600 IT professionals with application development responsibilities found that about a third of teams consistently deliver at cadences of one to three weeks and that the fastest teams generated higher business satisfaction than slower teams, an indication they don’t sacrifice quality to deliver fast. The study reveals how these teams did it: by adopting the following eight DevOps practices:

    8_DevOps_practices


    1. Minimum Viable Product – Deliver the smallest viable product or application and then improve it in subsequent rapid releases, based on feedback, and delivering value incrementally.
    2. Dedicated Teams – Form dedicated, cross-functional teams, avoid over-specialization and ensure they are not interrupted by side projects.
    3. Loosely Coupled Architecture – Use loose architectural coupling within and between applications to reduce complexity and enable delivery in small increments.
    4. Minimize Hand-offs, Maximize Flow – Eliminate unnecessary steps, delays and friction between steps to increase the flow of work.
    5. Deliver in Small Batches – Deliver in smaller batches helps to expose the most uncertain issues first and enables feedback on the most valuable usage models earlier.
    6. Transparency – Transparency into progress helps everybody to see where you are at any point in time and also visibility into risk without decreasing productivity.
    7. Eliminate Overhead –Eliminate the overhead of periodic and manual status reports and status meetings which absorbs valuable time and distracts focus from delivering value.
    8. Automate Testing using APIs – Shift away from heavy manual testing to improve delivery speed, quality, and testing accuracy, and dramatically reduce cost.


    The study refutes the myth that releasing fast requires you to sacrifice quality and accept higher risk. Adopting these eight DevOps practices, especially automated testing and delivering in small batches, does exactly the opposite:  small incremental releases are more thoroughly tested, more stable and lower risk.

    The best part about DevOps adoption is the flexibility to choose which practices to adopt first, based on each organization’s priorities, and then to incrementally adopt the rest of the practices as needed to optimize the software delivery lifecycle and accelerate innovation.

    To learn more about the survey and the eight DevOps practices, download the Forrester study along with the approach that you can follow to adopt these as per your organization’s current state of delivery cycles.

    About the Author

    ashokAshok Reddy is responsible for Product Management & Strategy, product Design/user experience and Business Development for Rational Software Division of IBM Software Group and for the IBM DevOps portfolio.  He is based in Raleigh, NC, USA.  Ashok’s role involves all aspects of global product delivery including setting product strategy and for product line management, establishing product roadmaps and partnerships for IBM DevOps portfolio.