Category: Blogs

  • Don’t let automation be the tail wagging the dog

    Don’t let automation be the tail wagging the dog

    There is quite a bit of talk right now about DevOps and how important automation is.  This could be compared to GM in the 1980s when the company tried to transform the way they built cars through automation and robot.  In the early 1980’s GM spent $90B dollars in an attempt to speed up the way cars were delivered to the market.  This failed with famous stories of robots painting each other and others welding doors shut.  Ultimately this project failed and the robots were scraped.  It was later reported that the money lost on the project could have been spent to acquire both Toyota and Nissan at the time.

    Automation dominates the conversation when it comes to DevOps.  If you do not learn how to build cookbooks you are not doing DevOps.  I fear this is going to set companies trying to transform IT off on the wrong track, focused on the outcome and not on the scientific process to get there.    Alan Sharp-Paul recently wrote that you cannot automate what you don’t understand.  The best way to understand it is in two key ways, change and performance.

    Let Science set you free

    This was the secret that Toyota used to dominate the automobile industry.  They were able to transform all of their employees into little scientist.  Constantly tinkering to squeeze our inefficiencies in the system.  Every worker was empowered to think how things could be done better.

    At the heart of the agile and DevOps processes is the practical application of the scientific method.  Think back to your 8th grade science fairs.  No not the volcanos but the ones that won best of show.  These had a clear hypothesis that stated what they were going to try and prove.  They were able to understand what they were going to change and measure the difference between the before and after.  They could clearly state what changed and if it was a successful experiment or a failure.

    This thinking is key for companies trying to transform to a DevOps IT organization.  If a company does not understand the experiments that are running and what the outcomes should be then automation will just make the problem worse. That is why change management and performance management are foundational for transforming to a DevOps culture.

    Tracking your experiments

    Any good scientist knows exactly what he is working on.  He knows every experiment that is running anticipating the outcome.  He knows all the details about each change that has been made to see how they impact the outcome.  This is the same way that IT should be tracking every change happening.

    Every change done in IT is a scientific experiment running. Tracking every change allows for understanding of the outcome of changes within the application.  Developers and Operations will be more informed about the cause and effect of their changes.  There are multiple different ways that you can track changes but the key is that you are doing it very well before you start to apply automation.

    Measuring the outcome

    There is no need to track the experiments if there are not being measured.  A scientist is very deliberate in how they measure the outcomes.  Good enough just does not get this done.  This is beyond just monitoring.  Monitoring in a lot of cases is after the fact, in production.  This is about measuring the difference for every experiment regardless of where it is being tests.  This creates the need to test changes all the way to when the first functional tests are done, measuring the changes of every code update.  Following it through all of testing and to production.  Understanding how each experiment impacts the system as a whole.

    Efficiency through automation  

    Once there is good understanding of all the experiments and a standard platform for measuring the outcome then automation starts to return exponential benefit.  Because every experiment it known the lower priority ones can be identified and automated.  Risk is better assessed.  Processes can start to speed up because there is visibility and accountability.  Applications are no longer classified as high risk or low risk only change is classified that way.  Determining what can be automated just becomes another experiment that is tried and measured for success and and failure.  Automation becomes just another outcome of DevOps to the business and not the route to achieve it.
  • Is DevOps a Title?

    Is DevOps a Title?

    So, I’ve wanted to write on this topic for a while as I think it deserves a little attention! I’ve heard numerous times that you shouldn’t have DevOps in your title or that job reqs shouldn’t be “DevOps Engineers”. This came up again at the DevOps State of the Union event that we hosted in Boston recently. There were definitely some very vocal folks saying that it just didn’t make sense to look for a DevOps engineer or hire a DevOps engineer. These folks make the following points:

    –          DevOps is a methodology not a job description – we don’t call our developers Agile engineers, they are just developers. They happen to follow the Agile methodology but they their job description isn’t to do Agile, it’s to create awesome products.

    –          DevOps should permeate an organization – having a DevOps group sort of missed the point of DevOps. DevOps should be embedded into the fabric of the company, not an adjunct to the development process. If it isn’t embedded how can you actually practice DevOps?

    –          DevOps does not equal tools – asking for a DevOps engineer with 5 years of experience in Chef or Puppet is sort of an oxymoron. Very few people have long-term experience with new, up-and-coming toolsets. So asking for that doesn’t make sense and again, it’s a methodology, not a toolset.

    It was an interesting discussion and I’m curious to hear what other people think about this perspective. We see a number of job descriptions and cards that say DevOps engineer on them. I can completely understand why people would do that, but I also understand the criticism of that approach as well.

    Before I sign-off, I’ll weigh in with my thoughts and hopefully we can add some discussion in the comments. As a proponent of DevOps, I’d like to see as many people adopt DevOps as possible. Strategically for businesses, I think it will make a significant difference in their operations. They will move faster, understand customers better, and be more efficient with the resources that they have. If it takes assigning a group or a title to bring DevOps into an organization, I think that they should do it. It’s a way to get started and work at embedding DevOps into their culture. I fully agree with the statements that DevOps isn’t a title or a tool, but I guess I’m practical about it too – some organizations will take different views on how to bring it into their company and have it take hold. In the end, I’m pro-DevOps, so if that’s how you need to make it happen, go for it! My guess is that over time, you’ll end up building DevOps into the fabric of the company and you won’t necessarily think of it as a job description or title, but just as a part of everybody’s job.

    What are your thoughts – is DevOps a title? If so, why? If not, why not? I’m looking forward to hearing your thoughts in the comments!

  • DevOps Board of Advisors and other DevOps blog musings

    DevOps Board of Advisors and other DevOps blog musings

    Well it looks like putting big names on Board of Advisors is having a good week in the DevOps world. Our friend Steve Hall over at ScriptRock announced on their blog yesterday that DevOps luminary, Kevin Behr (@kevinbehr) has joined the company’s board of advisors.  ScriptRock has also been putting some great content up on their blog as well. If you don’t already you should follow it. Also stay tuned for some ScriptRock folks posting here on staging-devopsy.kinsta.cloud.

    dreamteamSpeaking of Board of Advisors, here at staging-devopsy.kinsta.cloud we announced our own Dream Team board yesterday. With Brad Feld, David Cohen, Sean Charnock, Dean Mann, Gene Kim, Rich Mogull and regular staging-devopsy.kinsta.cloud journalists George Hulme, Tony Bradley and Ericka Chickowski, it is a great group that should help a ton with all of the many plans for staging-devopsy.kinsta.cloud. Rajat Bhargava, CEO of JumpCloud is one of the members of the board here and JumpCloud put up a nice post about it too.

    What do you think about boards of advisors? Helpful or not?

    It was a busy day with in other DevOps blog news, but two posts I wanted to call out were:

    1. Back to the future with Old School Devops on the Logentries Blog. First of all you have to love the Motorola beeper.  I remember those, in fact I had one. It is an old chocolate meets peanut butter story where the lead dev happens to be having a beer with the Ops dude. Luckily that is when the crap hits the fan and together they can solve the world’s problems almost. Of course it doesn’t always work like that does it?  I suppose what makes it old school is that today the Dev is the Ops 😉 Either way the point of the article is sometimes simple works is best.

    2. How to measure DevOps success: Ok put on your thinking caps for something really important. Helen Beal over on the AppDynamics blog has a really great article up on measuring your DevOps success. This is an issue we hear about often. How do I know if this DevOps stuff is really working? We have all seen numbers like a 20% productivity spike with DevOps, but how do we really measure it? What do we measure? Do we measure tools, culture, revenue something else?  This is as good a stab at it as I have seen put out there and worth your time.

    What DevOps blogs are your reading? Drop a line and let us know here in comments or at parker@devops.com.

    Also stay tuned tomorrow for our first Frequent Friday list of DevOps people to follow.

  • Can you appreciate DevOps, if you can’t exactly say what it is?

    I recently had a conversation with some SOX IT auditors and was asked what I meant when I said we were a DevOps shop. I stumbled a little, torn somewhere between an overly simplistic answer and a desire to baptize the unholy. I started by talking about collaboration between the developers and the admins. Mentioning that many of our developers are on call and have sudo access raised some eyebrows. Using Puppet made them pretty happy.

    Thinking back on it, what I realize is that for me devops isn’t a strictly defined thing, it’s a mix of operational changes that draw on the best of any tool, without prejudice. We do what works. We do not do what does not work. If we are doing something, and it ceases to work, we stop doing it. I don’t know if that’s devops, but it’s what we do. And it works. So we’re going to keep doing it.

    Configuration as code

    This is not news, central and key to successful devops is controlling system configuration and change management with code, not with disparate manually managed text files. Here’s the thing, you cannot operate at scale without it. You also cannot change direction, or iterate through rapid change without it. You can rapidly, accurately, and verifiably push changes, stand up environments, or demonstrate a fact to an auditor with just a few keystrokes.

    To be sure, it’s a helluva lot easier to start a business on these principles than to migrate after your business is a real thing. However it’s worth the effort.

    Sysadmins are our friends, Developers are on call

    Most places I’ve worked, neither of those statements were strictly true. At Craftsy, both are. The relationship we foster is one of open collaboration. I’ve never been somewhere where the sysadmins were jerks enough to really justify the animosity they received from dev, and I’ve never met a developer so hopelessly irresponsible to really justify the vitriolic mistrust dealt out by the SA team.

    Give your developers sudo and get them in the oncall rotation. Now, they share a burden with your SA group, and a responsibility to the systems their code runs on. Figure out a sensible rotation and escalation, but without that shared responsibility you will always struggle with trust between your dev and your ops.

    SaaS, Paas, IaaS, CotS, Cloud, OnPrem, Whatev

    The punchline is “all of the above”. Never let yourself get married to a particular way of doing things. We run stuff in the cloud. We run stuff locally. We buy software. We rent software. We rent services. We borrow code. We cloud. And whatever comes up next, we’ll try it one way, whichever way seems to make the most sense. If it works, we’ll keep doing it that way.

    I’ve heard some reasonable objections to Cloud/*aaS based on security concerns. Safely extending the trust relationship of your LAN isn’t easy. It isn’t impossible either. Tools like the AWS VPC offering, or SSO/IAM systems offer some very flexible approaches to open your environment and leverage the best tool, regardless of how it’s made available.

    Do what works

    I’m not sure exactly what the SOX guys thought of my ideas around devops. IT, much like accounting, is an area that traditionally is slow to adopt new approaches. It’s a counterintuitive truth that an industry so deeply engaged with technology is simultaneously so awkwardly regimented in its ways. The standard answer, that change has to come slowly to maintain stability is unsatisfying. Indeed, it belies the fundamental failings of the old methods.

    DevOps sets the table for you to achieve stability in any environment precisely by engaging deeply the technology around you.

  • Organizational Dysfunction: The original vulnerability

    Organizational Dysfunction: The original vulnerability

    During your teenage years, you may have figured out a way to get a ‘yes’ from your parents by playing off of the responsibility and knowledge gap between them…walking up to your mom and saying something like, “Hey Mom, Dad said he would drive me, can I go out tonight?” and then proceed to your dad and say something like, “Hey Dad, Mom said I can go out tonight and you need to drive me.” There is nothing cleverer than a determined teenager wanting to get his or her way. Such is the case of targeted attackers and the way they play one IT department’s responsibilities off another. This is the grey area where the organizational chart and separation of duty can introduce weaknesses exploited by the more advanced threats we face today.

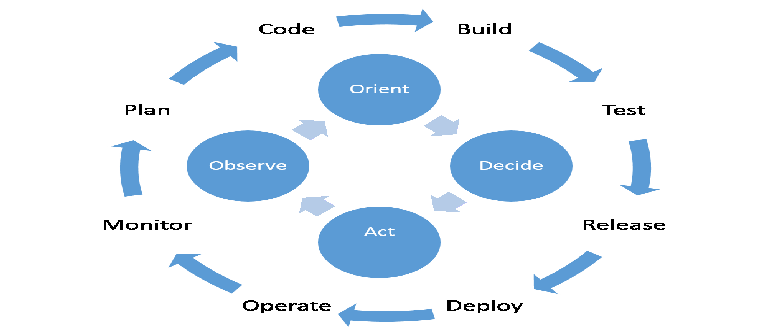
    You don’t have to look far into your organization to see this at work. The security team does its thing, networking engineers do their thing, and IT operations teams in general all have administrative realms that define functional boundaries as to what they can see and do. To borrow from Colonel John Boyd’s OODA loop, each team has its observation and orientation (OO) process for gaining operational visibility and making decisions, as well as specific decisions and actions (DA) they can execute within their administrative realm or set of capabilities to bring change to their organization. The weakness I’m highlighting in this post is when the decision and action appropriate for a set of observations, and the observations themselves, exist in two separate departments and can be exploited by the attacker.

    To exemplify the problem, let’s begin with the question: Is a distributed denial-of-service (DDoS) attack a security or a network engineering issue? The problem I see most often is that one department will have a precise view into network telemetry for early threat detection, but will not yet have the ability to mitigate or remediate the threat.

    Or how about the situation where credentials for one of your executives are harvested, and now the attacker need not trigger any security events at all in order to carry out an attack. In this situation, the attacker merely needs to log in and plan the next stage of the attack, roaming freely and without suspicion across your network because they are only generating networking traffic. The network team does not act because everything is still available, and the security team does not act because there is nothing being denied in access logs, no firewall violations, and nothing triggered on the IDS/IPS.

    Let me be clear in that I am not saying that everyone has to become an expert in everything; specialization is healthy, but only when it does not compromise communication! In the example of Mom and Dad being played by the teenager, if Mom and Dad had a better communication protocol, the teenager’s tactics would be thwarted. If you look at some of your operational procedures, and start to think like an attacker (or teenager again), I’m sure you will find at least half a dozen communication gaps that a clever attacker could exploit.

    This organizational dysfunction is going to require change that may appear to be radical because the systems that support it are so ingrained. Big analyst firms have defined their technology categories as law and they police them as if you were breaking the law if you dare to create something different – something more cross functional. Some best practices out there are, in my opinion, worst practices because they are so focused on the operational effectiveness of the department, and they leave out other departments or the active threat entirely. Lastly, even some prescriptive compliance requirements force organizations into strict separation of duties, but when implemented, create a broken OODA loop where the ‘OO’ does not connect with the ‘DA.’

    There is an opportunity for DevOps to completely recalibrate how we deliver a cross functional operational unit which is why I took the time to write this article for staging-devopsy.kinsta.cloud.  Through the lens of Boyd’s OODA loop, you can already see the security ramifications because the tempo of DevOps allows the defense to loop at a faster rate than the adversary – the dominant strategy of the OODA Loop.

    I hope this post is a call to action for all you big thinkers. Get creative, get innovative, and do not be afraid to erase some lines and boundaries within your IT organization if it fosters a higher level of communication amongst your teams. Think of your organization like a great band playing live music. All of the performers play different instruments, yet they are listening to one another just as hard if not harder than they are producing sound. They improvise and adapt to one another; monitoring systems are put in place so they can have just enough of each sound in their own ear. This is what effective, cross-functional teams look like.  I’m just going to say it: DevOps is Rock and Roll!

    Oh, and hey, follow me on twitter: @tkeanini

  • Closing the Deltas Between Development and Production

    Who hasn’t heard the classic statements “It works on my machine!” or, “Man that would have been easier with real data!”?  In either case, had the development happened in production, problems would have been avoided!  Fortunately, in a DevOps world, the walls between production and non-production get broken down making the reality of developing and testing in production more tangible.  In no particular order, here are some of the things I’ve done to breakdown those walls.

    Develop on and deploy from a single code line.

    Many times we find ourselves in complex processes around deployments and production bug fixes.  For example, the code is branched for release candidates and deployments are done from the branches.  Branching before release by itself isn’t complicated, however, when there is a production bug, engineers find themselves repeating or merging the fix into at least two, if not several, different places.  Repeat that a few times over and, uh oh, now there is a problem because there are many moving parts and questions about what exactly is in production.  Unfortunately, the differences are most likely unintentional.

    Instead, simplify the process and have everyone work off the same code line and have that same code line deployed directly to production.  Now there is only one code base, therefore no question about what code is running in production.  Production isn’t static, so change will still happen after deployment.   Notation is required indicating what version was deployed, so you can still reproduce production.

     Let testing happen on the production database.

    Ok, even I’m not that crazy, but let developers use a copy of the production database.  There are two very important aspects to this.  First, refresh it often.  I suggest daily.  I have had very good luck using EBS snapshots to get a copy of the database on a different server, but if your database is small, good old SQL dumps also will work.  Second, make it safe.  Put some safe guards in place to make sure a change doesn’t accidently get made to the real production database.  Keep your ACLs tight, change the passwords and practice proper database user management.  Lastly, a bonus outcome is that you are constantly testing your database backups and recovery procedures.

    Minimize the steps between development and production.

    Each step, especially the manual ones, between the developer’s machine and production is another point where unexpected changes can be introduced.  It sounds obvious, but the gates code must pass through before entering production must be purposeful and prove their usefulness.  For example, if code must go through a regression, but no regressions are being found, then that step is not useful and just increases the probability of unintended change.  I have been a part of a process where code had to be deployed to “staging” where it was then hooked up to the live production database, but was only to be exercised in a read-only manner.  After doing that for many, many releases and very rarely finding defects before production, we decided to just get better at deploying to production and eliminated the deployment to staging.  In the end, we got faster and with no impacts to quality.  Less can be more.

    Depending on your situation, database size, regulatory compliance, etc. you might to be able to do all of them, but breaking down those walls will yield better code, fewer bugs, happier engineers and fewer sleepless nights to name a few.  So, grab that wrecking ball and break down a few walls.

  • PEBKAC Avoidance

    PEBKAC Avoidance

    We’ve all said it. We’ve all done it. We’ve all shook our heads at it. PEBKAC. Problem exists between keyboard and chair.

    User error.

    While generally applied to the end-user community – those folks who are considered technical neophytes by IT professionals – it can and should also be applied to those of us who have, at least once (admit it, come on, I know you’ve done it) fat fingered a configuration on a web server, a switch, a router, or some other network or application service.

    It’s okay. We’ve all been there – head down on the keyboard, a litany of words we wouldn’t use in front of our mothers streaming from our lips between enumerations of how long we’ve sat at our desk looking for the problem. Mine was a misconfiguration of route metrics in the now long gone Network Computing lab that sent traffic from one side of the lab over a simulated T1 and back over the 100 Mbps link. When you’re trying to simulate a WAN environment and put WAN optimization solutions on either end, this is highly problematic and tends to, well, not work. Not work at all. If it wasn’t for the astute observation of my lab partner,  I’d probably still be at my desk hunting for the problem.

    The point is, we’ve all had our PEBKAC moments. We know they happen, and avoiding them is a very real goal of devops in general. We want consistent, repeatable and successful deployment processes in part to avoid the time and effort it takes to troubleshoot some minute configuration error in the lengthy and often complicated data path over which application traffic must traverse in our domain.

    And it’s no longer just about downtime, which is costly and frustrating for everyone involved. It’s also about security; security of the network, the applications, and data.

    Tufin Technologies, in a 2010 survey of 100 registered DEF CON 18 attendees, found that “73 percent of hackers came across a misconfigured network more than three quarters of the time – which, according to 76 percent of the sample, was the easiest IT resource to exploit.” [1]

    With more and more layers of complexity added to the network in an attempt to simplify the network (yes, how’s THAT for irony?), there are more and more opportunities to experience the unique pain of PEBKAC every time a new service is provisioned. Consider the math:

    A typical data center has over 500 servers, each running a hypervisor. Each hypervisor carries an average of 20 virtual workloads. Each workload requires at least 5 separate network attributes to be configured. That’s a total of 250,000 opportunities to make a mistake. At even an error rate of less than 1 percent, that’s still 250 problems you’ll need to track down.

    This is, in part, why Devops exists. To enable the development and use of reliable processes and methods for provisioning services. That means configuration is happening under the covers, unless you’re already living in rainbow unicorn land where services configure themselves automatically. I didn’t think so.

    There’s a reason why typists are measured based not just on speed but on the number of errors made while typing. It’s not just about the speed, it’s about the accuracy because eventually, you’re going to miss the mistake you made and it’s going to be sent out in a corporate wide e-mail and … well, you can peruse the Internet at your leisure to see how well those turn out. The same is true for deployments and provisioning. It’s not just about how fast you can get a service up and running, it’s about how fast you can get that service up and running correctly.

    Devops should focus as much on accuracy as it does speed. You’ll save more time avoiding misconfiguration and the associated long hours of troubleshooting by simply slowing down a few MPH (or WPM) and ensuring that you’ve got it right the first time.


    [1] http://www.continuitycentral.com/news05331.html, http://www.darkreading.com/perimeter/misconfigured-networks-are-easiest-prey/227200159

  • The Dawning of Continuous Support

    The Dawning of Continuous Support

    Development teams have a tendency to think that once they push the deploy button, the release is done. But with Devops, it’s quite the opposite now. More software changes, and more deploys, make every production release a new piece of code with unique idiosyncrasies. This has turned what has historically been a more static production environment now highly dynamic.

    Teams have responded by layering in a lot of monitoring and performance technologies, which has caused even more information overload. Continuous Deployment makes it easier than ever to push code to production but it has also created an additional priority within the company – the need to provide Continuous Support.

    Continuous support addresses the human side of how to harness your team in more effective ways, using new methodologies to adapt to a much different world, and extends out to include other areas of the business besides IT. Sales, marketing and customer support are all going to be affected by this way of doing business.

    Imagine that it’s 5 a.m and there’s an intense firefight with all the right Dev and Ops guys working to get the system back up. It’s quickly approaching prime time for the users of your app. How will you get Support up to speed so they can intelligently talk to the issues? Where is Marketing to manage the Twitter-storm and blog post? Or Sales, who is about to demo to a big East Coast prospect? Continuous support aims to help answer those questions.

    If we’re going to break down the silos with DevOps, we have to extend that out to *all* silos in the company in order for our end-users to benefit. The ability to solve smaller problems faster means quicker turnaround and quicker fixes. There’s talk about getting customer features out faster but all conversations virtually ignore the support team…even though they’re the ones talking to customers on the front line, listening to feature requests and helping to resolve user issues.

    When you extend situational awareness across the company, it becomes easier to see patterns and solve for them. Here are five tenets of customer support:

    1. The team is always-on. This means that people are not just alerted when problems are happening but rather, get updated all the time. VictorOps has a Salesforce integration that provides the perfect example. If you’re a company promising 24/7 support, the old-school way to go about doing that is to hire eight people, which is the bare minimum to insure you are single threaded on most shifts. Now, we’re making it work with just a few people and the SF integration. There are tools available that enable your support team, reduce its size and make it more likely that you’ll get to the right person faster. You don’t need to overstaff, or have someone actually sitting there, in order to be situationally aware of your customer experience and efficiently solve their issues.

    2. Collaboration is king. Getting different members of the team involved in quickly solving a firefight is a necessary but difficult task in the world of Continuous Support. If you can reduce the spool-up time for looping new participants in, then you’re on your way to finding the right answers. Allowing for scalable “lean-in” means that you have more eyes on the problem and can resolve that critical alert faster.

    3. The feedback loop is crucial. All the different departments in the company need to be involved in completing the product feedback loop. This means that when scheduling postmortems, in addition to inviting the Support and Marketing teams to join in these discussions, Product, Development and Operations should all be involved. There’s always something to be learned by internal failures and those lessons should be shared with everyone in the company who might benefit from them. The feedback loop is essential for getting customer feedback all the way back up the chain for Product.

    4. Automate, automate, automate. The single biggest driver of high performance, automation increases the overall speed & quality of code. But don’t stop there when talking about automating. You can also automate systems to help detect potential user issues, which is important if you don’t want your customer to be the first one to find the problem. Automating components of the support chain is a vital part of making Continuous Support work because it isn’t about removing the humans but instead making them more efficient through automation.

    5. Company culture is inherent to success. If all employees in the business know what the company goals are and how continuous support can help to achieve them, then it becomes an easier sell to get everyone on board. Leadership is essential in making the culture of the company a priority and keeping it there. When Continuous Support is done right, it provides the entire product chain with the proper information and empowers your employees to make better decisions.

  • Zen and The Art Of Infrastructure Maintenance

    Zen and The Art Of Infrastructure Maintenance

    There’s a famous passage I’ve quoted from time to time when I see someone “stuck” with a problem, flailing potential fixes and solutions wildly in hope that one of them does the trick.

    “Assembly of Japanese bicycle require great peace of mind.”

    Just like that. Improper grammar and all, quoted verbatim from Robert Pirsig’s philosophical classic Zen and the Art of Motorcycle Maintenance. The quote is in reference to the first printed words on a set of technical instructions, which the narrator discusses with friends and colleagues on a long-distance motorcycle trip.

    And the response I get is the same every time, likely the same response you’re having right now…

    What in the world are you talking about?

    Well good, now I have your attention. And I’d be willing to bet that attention is on 1) the ludicrous loss of translation from Japanese to English and 2) debating whether or not something as seemingly superficial as “peace of mind” is really required to assemble a bicycle.

    Language barrier aside, let’s abstract away from modes of bipedal transport into a more generic “machine”. Do we really require “peace of mind” to assemble or create a machine?

    cory2

    Reliable? Maintainable? Usable?

    We certainly all want to receive peace of mind from our machines. We want them to do the job they were created to do without fail so we can move our attention onto other things.

    What words do we use to describe such machines that give us this peace of mind? Reliable? Maintainable? Usable? When we think of the reliability, maintainability or usability of a machine, we’re really just describing a machine that can produce peace of mind. I’d argue if we want that machine to produce peace of mind, then it must be created under peace of mind.

    Why is that? If we, the creators of machines, are in a state of peace of mind when we start our endeavor, we’re highly motivated to do that which will continue our state of peace of mind. We don’t want to lose this state. Since if the machine does break, we the creators will be forced to lose our peace of mind and fix it, we’re motivated to create a machine that’s resilient against failure and resilient against our loss of peace of mind.

    Without this key precondition to creation, we’re likely to build our existing personal problems right into the machine itself! Under time pressure? We’ll cut corners to make deadlines. Dealing with a different machine breaking? Likely to gloss over a key failure condition in the machine we’re actively building so we can fight a fire elsewhere. Worried about the problems of today? Then I can guarantee there’s no thought going into a machine that will be resilient to the problems of tomorrow.

    Quality creations produce serene creators as much as serene creators produce quality creations.

    Those in a state of serenity will continue to create that which maintains the state of serenity or peace of mind; those that are not in a state of serenity are unable to escape a vicious cycle of build-fix-build-fix, never achieving peace of mind. Ultimately, the serenity of the creator is the key test for the quality of creation.

    And ultimately, this passion for peace of mind from our machines is what you’ll find when you meet the folks in the DevOps community. We’re guided by a desire to maintain our peace of mind — for ourselves, for our families and for the folks that count on us the most: our customers.

    If the machine produces tranquility, it’s right. If it disturbs you, it’s wrong until either the machine or your mind is changed.

    The material object of observation, the bicycle or [in this case, the global infrastructure], can’t be right or wrong. Molecules are molecules. They don’t have any ethical codes to follow except those people give them. The test of the machine is the satisfaction it gives you. There isn’t any other test. If the machine produces tranquility it’s right. If it disturbs you it’s wrong until either the machine or your mind is changed. The test of the machine is always your own mind. There isn’t any other test.
    – Robert Pirsig

    So the next time you find yourself struggling with a problem, take a lesson from Robert Pirsig: step back, achieve peace of mind, combat that which threatens peace of mind and strive to maintain peace of mind.

    You’ll be a better (and happier) creator for it.

  • Docker as a framework for your DevOps culture

    Docker as a framework for your DevOps culture

    If you’re like me and spend a lot of time evaluating new technologies with the goal of “doing more faster” with your engineering organization, then you’re certainly aware of the many choices of DevOps tools like Puppet, Chef, Ansible, Salt, etc. In my opinion each of these tools is amazing at one piece of the DevOps puzzle – configuration management, and some are OK at other DevOps tasks. Each of the tools has a slightly different approach to configuration management but after comparing them I find that you’re usually picking a tool based on stylistic reasons like the DSL, existing recipes/playbooks, or existing familiarity. While I have my opinion on which of the above tools is “the best”, each tool only solves the configuration management piece of the puzzle.

    If DevOps is truly a culture change and not just the codification of operational tasks then we need tools that help foster that culture and I think Docker goes a long way towards doing that.

    Coming from the perspective of a developer looking at development tools, I see the above tools as APIs for DevOps, where Docker is more of a framework for DevOps. This is because Docker is both a runtime environment and a configuration management tool in one. Best of all Docker eliminates many common tasks in your development cycle and creates a tighter feedback loop between your development and operational tasks. I believe creating fast effective feedback loops between development and operations is critical weather development and operations are entire departments or simply tasks in within your organization.

    In my experience developing software as a service platforms, one of the most problematic parts of the process is the management of the environments, how many times have you heard “works for me” or “works on our test servers”? Generally issues like this arise from subtle dependency changes between the environments introduced by both developers, QA and operations throughout the deployment lifecycle. To fix this problem I’ve seen, and attempted, several approaches. For example I’ve tried having a base VM and using Vagrant with Puppet or Chef to create local environments that were the same as test and production environments. This seems to work at first but it proved to be cumbersome to manage the differences between development and test environments as time went on. I found that this mostly because the DevOps (configuration management) tools are geared towards maintaining a perfect operational state based on strict server roles defined in the tool. While this approach was better than manual management of development and test environments it was still quite easy to have the configurations between environments drift apart over time and end up with the same issues mentioned above.

    So how does Docker help and what makes it better?

    • Uses a layered approach to dependency management, making the configuration of environments easier to maintain.
    • Provides various runtime options allowing the same image to be run in multiple ways without extra configuration.
    • Can use any or no DevOps tools to build up your Docker images reducing the learning curve across engineering.
    • Lightweight runtime makes running multiple Docker images on a single machine more feasible than with VMs.
    • Decoupled network and storage layers allows a single Docker image to be run on a single system or multiple systems easily.

    These features allow developers to run complex multi-service architectures on their laptops and with the same runtime images operations can support any number of load or availability scenarios with as many or as few systems as necessary. This combination of predictable dependency management and runtime flexibility is like having all the ease of a Heroku environment with the flexibility of AWS or Softlayer.

    Docker has many other impressive features, and few shortcomings, but in my opinion it’s a great framework to build your DevOps culture around as it makes maintaining a predictable production environment and a flexible development environment easy with one tool. Over my next few posts I’ll cover more specific examples of using Docker in development, test, and production environments. In the mean time visit the links below to read more about Docker and it’s growing ecosystem.

    Docker, Deis, Shipyard