
Tag: codebase
-

5 Reasons DevOps Teams Need Code Mapping
Before we delve into the benefits and importance of code mapping, it’s essential to understand what it is. Code mapping is a visual representation of the structure and flow of your code. It’s like a roadmap, laying out the entire landscape of your code, showing all the paths, intersections and dead-ends.
Just like a physical map gives you a bird’s eye view of a geographical area, a code map gives you a high-level view of your code. It helps you understand the dependencies, connections and interactions between different parts of your code. This high-level overview is crucial for understanding how your code works and identifying any potential issues or bottlenecks.
Code mapping is not a new concept. However, with the advent of DevOps and Agile methodologies, its importance has grown. We’ll discuss why code mapping can be a powerful tool for DevOps teams and how to best use it.
5 Reasons DevOps Teams Need Code Mapping
Let’s explore the top five reasons why DevOps teams need code mapping.
Enhanced Collaboration
In a DevOps environment, collaboration is key. Developers, operations teams and quality assurance all need to work together seamlessly for the smooth execution of projects. Code mapping facilitates this collaboration by providing a clear, visual representation of the code. Everyone on the team can look at the map and understand the structure and flow of the code, regardless of their technical expertise.
Code mapping can also act as a communication tool. Team members can use it to explain their ideas, discuss problems, and propose solutions. It’s like a common language that everyone on the team can understand and use.
Efficient Troubleshooting and Debugging
Troubleshooting and debugging are an integral part of software development. However, they can also be time-consuming and frustrating, especially when dealing with complex codebases. Code mapping can significantly simplify this process by visually highlighting the problematic areas and dependencies in your code.
With a clear map of your code, you can easily trace the flow and identify where things are going wrong. You can see how different parts of your code interact with each other and where potential bottlenecks or issues might be. This makes troubleshooting and debugging much more efficient and less stressful.
Simplified Onboarding Process
Onboarding new team members can be a challenging task, especially when dealing with complex codebases. It can take weeks, if not months, for a new developer to fully understand the code and start contributing effectively. Code mapping can significantly speed up this process.
With a clear code map, new team members can quickly get a high-level understanding of the code structure and flow. They can see how different parts interact with each other, where the dependencies are, and how everything fits together. This gives them a solid foundation to start diving deeper into the code and start contributing sooner.
Improved Code Quality and Maintainability
Maintaining high code quality is crucial for the long-term success of any software project. Poorly written or structured code can lead to numerous problems down the line, from performance issues to security vulnerabilities. Code mapping can help prevent these problems by improving the quality and maintainability of your code.
By visualizing your code, you can easily spot areas of complexity or redundancy that might impact the quality or maintainability of your code. You can identify parts of the code that need refactoring or optimization and make informed decisions about code improvements. This leads to cleaner, more efficient, and more maintainable code.
Efficient Release and Deployment Management
In a DevOps environment, frequent and reliable releases are critical. However, managing these releases can be a complex task, especially when dealing with large, interconnected codebases. Code mapping can simplify this process by providing a clear view of the code structure and dependencies.
With a clear map of your code, you can easily see how changes in one part of the code might impact other parts. This helps you plan your releases more effectively and prevent potential deployment issues. It also makes it easier to track changes and roll back if needed, making your release and deployment process much more efficient and reliable.
Best Practices for DevOps Teams
Here are a few best practices that can help DevOps teams make the most of tools like Microsoft Ignite and CodeSee.
Prioritize Clarity
Clarity should be a priority when it comes to code mapping. A clear, well-structured code map can make it much easier for developers to understand the codebase and how its various components interact with each other. Conversely, a cluttered or confusing map can make the task of understanding and working with the codebase significantly more difficult.
With a clear map, developers can easily identify the parts of the code they need to work on, understand how these parts relate to the rest of the codebase, and avoid potential errors or issues that might arise from a lack of understanding.
To prioritize clarity, it is important to adopt a consistent style and structure for the map. This might involve using a specific naming convention for the different parts of the code or adopting a specific color scheme to differentiate between different types of code.
Version Control
Just like with the code itself, implementing version control for your code maps is highly beneficial. Version control enables developers to keep track of changes made over time. This is important because it allows for easy rollback to previous versions if a newly introduced change leads to unforeseen issues or complexities.
Moreover, version control provides a historical record of the evolution of your codebase. By looking back at previous versions of the code map, developers can gain insights into how the codebase has evolved and grown over time. They can identify patterns and trends and use this information to make informed decisions about the future development of the codebase.
Use Interactivity
Modern code mapping tools offer a variety of interactive features that can greatly enhance the usefulness and usability of your code maps. For instance, some tools allow you to zoom in and out of different parts of the map, enabling you to focus on specific areas of the codebase. Others offer the ability to add notes or comments, making it easier to share insights and observations with the rest of the DevOps team.
Interactivity can make code maps more engaging and intuitive. It can transform them from static, one-dimensional diagrams into dynamic, interactive tools that offer a wealth of information and insights.
Integrate With Documentation
Finally, integrating code maps with documentation can greatly enhance their usefulness. Documentation provides detailed information about the codebase, including the purpose of different parts of the code, how they function and how they interact with each other. By linking this information with the visual representation, developers can gain a more complete and in-depth understanding of the codebase.
Integrating code maps with documentation also makes it easier for new members of the DevOps team to get up to speed. They can use the code map to visually understand the structure of the codebase and then refer to the documentation for more detailed information. This can significantly shorten the learning curve and help new team members to become productive more quickly.
Conclusion
In conclusion, code mapping is a powerful practice that can greatly enhance the effectiveness and efficiency of DevOps teams. By adopting best practices such as integrating feedback loops, prioritizing clarity, implementing version control, leveraging interactivity and integrating with documentation, teams can optimize their code mapping processes and reap the many benefits that this practice has to offer.
-
CodeSee Unveils Enterprise Codebase Visualization Platform
CodeSee this week launched an enterprise platform based on its codebase visualization and mapping tools that makes it easier for developers to navigate and learn how an application was developed.
CodeSee CEO Shanea Leven said this capability makes it simpler to understand how a codebase is constructed, including the application programming interfaces (APIs), without having to read each line of code. Organizations can use the CodeSee Enterprise platform to review code in addition to making it easier to add new developers to a project, she said.
The CodeSee Enterprise platform makes it possible to automatically detect, visualize and link to the code used to create every connection between the services that make up an application. That capability is especially useful for any security review of an application before or after an application is deployed.
A code automation feature codifies and automates the code knowledge that previously could only be passed from one developer to another, Leven noted.

It takes a significant amount of time for developers to pore over a codebase to understand where they might contribute. The larger a codebase is the more challenging it becomes to make meaningful contributions.
By definition, application development in the era of microservices is now a group effort. The days when a lone developer cared for an entire application are long over. The issue is finding a way for teams of developers to more easily collaborate when most of them may have never actually met in person.
The amount of focus on developer productivity has increased substantially since the start of COVID-19 pandemic spurred organizations to accelerate a wide range of digital business transformation initiatives. Developers are generally challenging to recruit and retain, especially individuals familiar with the latest cloud-native platforms for building and deploying applications. Making it possible for developers to more easily contribute to multiple application development projects has never been more critical.
Of course, most developers would rather spend more time writing code rather than studying it. The amount of time devoted to understanding codebases and maintaining development environments far exceeds the amount of time spent writing code. Many developers are not always going to be able to take advantage of advances in application development without the aid of a DevOps team to provision new tools and platforms.
One way or another, the rate at which applications are being developed and deployed needs to accelerate. An uncertain economic outlook is increasing the pressure on business leaders to digitally transform processes in a way that increases both revenue and profitability. The application experience is especially critical because customers are not inclined to patiently wait for organizations to finetune their digital processes over an extended amount of time.
Less clear, however, is the level of stress individual developers might be willing to tolerate. There’s no doubt most of them are sympathetic to the needs of the organizations that have hired them but that does not necessarily mean they’re willing to continuously work overtime to achieve goals that might not be attainable using the tools they have at hand.
-
Accelerating Software Testing
Yves Junqueira is the CEO of YourBase, a software testing accelerator for large codebases. He talks with Alan Shimel about the company, accelerating software testing and the impact on developer productivity. The video is below, followed by a transcript of the conversation.
Alan Shimel: Hey, everyone. Thanks for joining us here on another segment for our TechStrong TV. My guest this segment is a new company, first-time guest on our TechStrong TV, Yves – and I’m gonna really mispronounce his last name, Junqueira. I’m supposed to have that rolling R, and I just don’t do rolling R’s. Yves, I’m sorry, man. Welcome to TechStrong TV.
Yves Junqueira: Thank you, Alan. It’s great to be here. You did it good.
Shimel: Not so good. You know what? In case your mom or your family’s watching, say your name correctly for ’em.
Junqueira: Yves Junqueira.
Shimel: Junqueira. Okay. We’re gonna call you Yves, and we go from there.
Junqueira: Sounds perfect.
Shimel: So, looking from your background, are you up in Seattle, Toronto? Toronto?
Junqueira: That’s Seattle.
Shimel: Seattle. Yes, the mountains. And you know what? Welcome. I’m gonna let you give a little introduction to your company, and you’re a cofounder of it, but go ahead.
Junqueira: Gladly, yeah. Our company’s called YourBase. We build developer tools for very large code bases. Specifically, we are a software-testing accelerator for large code bases. I used to work at Google for almost ten years, and my cofounder, John, was a principal engineer at Amazon, at AWS. And, yeah, we’re excited to – I’m very excited to be here, Alan.
Shimel: Absolutely. Well, I’m excited to hear about what you’re doing. So you’re a code accelerator?
Junqueira: We are a software-test accelerator, yeah.
Shimel: Software-testing accelerator, excuse me. What exactly is that?
Junqueira: Yeah, so it’s very important when you’re building software that you actually know that the software is working. You usually have very large teams that’re creating code, and you don’t want one developer to be stepping on each other – on the other’s toes. And so you need a lot of testing to make sure that when you make changes to the software, it’s still working. But as you’re adding new features, you’re adding new tests, and you add new features, and you add new tests, and over time the number of tests in your code base can grow very, very quickly, and it can become a very big problem for developer productivity and developer happiness, because it can take a very long time to actually test code. If you’re making even a small change sometimes in a large code base, it can take hours to ensure that that change works, to run all the tests. So that’s what we help with.
Shimel: So you’re automating testing. Is that fair?
Junqueira: We automate the test selection of testing. So, yeah, we help run the tests, but most importantly we help select what are the right tests that are safe but that have to be run for each change. Without having to test the entire world, we use a process called – we use tracing of code to build a dependency graph to then select the right test to run and then just make things more productive for developers.
Shimel: Sure. Of course, our audience is a very technical audience, familiar with QA and testing and developing. So you’re running a trace route on the code as it’s entered into Git or – because it’s pre-deployment code, right?
Junqueira: That’s right. It’s pre-deployment code, yeah.
Shimel: So as the code is put into Git or some other sorta repository, you select what’re the right tests to run and run it on the code. So this all takes place within the repository like a Git-ops kind of thing?
Junqueira: Yeah. It can take place in the repository connected with a CI, with a continuous-integration tool, or it can also happen during local development. You can have multiple developers working at the same time on the same code base but perhaps making slight – different code changes. And with your base, they are testing their code but also using their colleagues’ testing to – so that they don’t have to repeat the test that their colleagues already ran for the same code base. So they only have to test exact the small changes that they made on their code.
Shimel: I love it. Sounds great. And then I don’t wanna use the buzzwords, but is it some sort of AI/ML that is picking what’s the right code – what’s the right test to run for this particular code for these particular changes?
Junqueira: That’s an important question. It’s not AI. We use just simple data structure and algorithms that we collect when doing tracing. And this is actually important, because if we were using just AI or any sort of statistical approach, we would only get a limited confidence that we are testing the right things. So imagine that you’re a financial institution, right, or a hedge fund, where tests are very important. If you don’t catch certain bug, it can cause millions of dollars in losses, right, in lost revenue, for example. So it’s very important that you actually detect the correct regressions in your code, and if we were using just a simple AI approach, we would only, let’s say, have 90 percent confidence that we were running the right tests in your code. That is not enough. So our customers need assurance. They need full confidence, so we use an approach that is a little bit more intrusive, let’s say, because it’s detecting every single function called that is happening during the tests. So it has a little bit of a performance impact during the initial test. But on the other hand, it just provides full confidence rather than being 90 percent confidence that an AI approach would have.
Shimel: Got it. I mean, big companies using this, small companies, anyone? Who’s the target user here?
Junqueira:Fortunately, we can scale from small to very large code bases. So we have customers that are very small, just small startups that are getting started but that really want to have the fastest possible development process. But we also have very large code bases of very large companies, public companies, Fortune 500s, that want to keep moving fast. It’s difficult. Imagine if you have a software product that really needs to evolve quickly. Customers these days demand that software developers – that software companies evolve their products quickly. The customer needs are changing fast, and so they need to be able to make software changes very quickly and do it at – have high velocity with the most productivity possible. So what we allow those companies to have is even though they have a very large code base, the larger companies, they can be almost as productive or as productive as if they had a small code base, and this is really magical. This is something that we’re very proud of providing to these companies.
Shimel: Absolutely. You know what? People always wanna know this, and I realize it might be coming outta left field. Interesting. You worked at Google ten years. Your cofounder’s an AWS guy. How did that come together?
Junqueira: Yeah. It’s actually a funny story. We met at a random coffee shop. After I had left Google, I was working at random coffee shops here in the outskirts of Seattle, and I had my laptop with me with a bunch of developer stickers there like Linux and Python and GOAL like developers often have. And John had the same, and so we just looked at each other’s laptop. We were at this coffee shop here, and we – okay, we should chat, ’cause we us a lot of the same technologies. So we started talking, and over time I invited John to come to my weekly table games at my house. I host a game night every week, and John started coming, and I started talking about my project, and he was fascinated by it, and he said that software testing and developer productivity are a huge thing for him. And over time, he decided to join. I’m very lucky that he joined me at YourBase.
Shimel: Love it. And then talk a little bit here about going to market. How’s it been so far?
Junqueira: Yeah. We spent a long time perfecting the technology. This is a very tricky software. If you get things wrong, you may end up – your customers may end up shipping bugs. My customer’s gonna end up shipping bugs that should have been caught by the tests. But if I don’t decide to run a test or if I don’t give them right insights, they might actually introduce bugs and be less reliable than they were before. But we started just last month. We launched our first public beta now, and we’re very happy about that. So we have a number of design partners that are working with us on this initial release, and people – customers are very happy. The feedback has been fantastic. So last month we launched it to the outside world, and we made a public beta. Now people can just download it from just going to the website, yourbase.io. Anyone can download and test it. We currently support Python as – for code bases. Our technology has to be implemented on a language-by-language basis. So for now we support Python, but we’re going to support Ruby sometime soon. And we’re very excited. The reception from people has been amazing. It’s really fun to be at this stage of the company, where we actually are ready to talk about it to the outside world.
Shimel: Excellent, man. It is. Having founded more than one company, more than four companies, five companies, it is an exciting time, and I wish you nothing but great luck and success with this. I want to get into the kinds of testing you’re doing, functional testing, unit testing. Is it selenium kinda stuff? What are the kinds of tests you’re doing there?
Junqueira: That’s a great question. We are very good at tests that don’t cross process boundaries for now. This can be sometimes unit tests and functional tests. We don’t currently support UI tests yet, in part because there are good companies out there that’re already serving this market, and there was just nobody that was focused on the backend and in unit testing and functional testing. But this is a big space, and we’re just getting started. We have feedback from folks that we – they want support for more things, so that’s something that we’re excited to work on.
Shimel: Excellent, man. Yves, I wanna thank you for coming on and telling folks about YourBase here on TechStrong TV. Come back. Keep us posted on your progress, and best of luck.
Junqueira: Thank you so much, Alan. It was great to be here, and, yes, absolutely, I would love to come back.
Shimel: My pleasure. Say your name for us one more time so I don’t – just after I mangle it, at least they got it right.
Junqueira: Yves Junqueira.
Shimel: Junqueira. Yves, thank you, man.
Junqueira: Thank you, Alan.
Shimel: Oh, the website, yourbase.com?
Junqueira: Yourbase.io.
Shimel: IO, yourbase.io, Y-O-U-R-B-A-S-E-dot-I-O. This is Alan. We’re gonna take a break. We’ll be right back with our next guest.
[End of Audio]
-
Feature Branching vs. Feature Flags: What’s the Right Tool for the Job?
A dev team’s branch management strategy can have a significant impact on the rate at which it can release high-quality software. In this article we’ll explore the pros and cons of several different approaches for enabling multiple concurrent streams of dev work in the same codebase. We’ll see that two major factors—the cost of merge conflicts and the ability to release streams of work independently—are often in tension, but that Feature Flags provide a way to resolve that tension.
Merge Conflicts
New products start off as a small codebase, usually only being worked on by a handful of developers. This situation doesn’t call for much formal process. However, even when a team consists of just two devs, it’s still preferable to avoid working on the same files at the same time to avoid merge conflicts.
Unfortunately, even when we’re trying to avoid stepping on each other’s toes, it’s still pretty common for work streams that seem unrelated to end up touching the same files. Sometimes it’s these unexpected merge conflicts that can cause the most pain—any iOS developer who’s been around the block a few times probably has acquired some scar tissue from an epic three-way XIB merge in their past. In this article we’ll explore some different ways to deal with the challenge of merge conflicts when multiple developers are working on the same codebase.
Some people might argue that merge conflicts aren’t that big a deal these days and mostly are solved if you just use modern tools such as Git. This is unfortunately not true. Git certainly makes creating branches trivial, but it does not always make merging parallel changes within those branches trivial. It has some powerful features to automatically merge changes when possible. These automatic merge heuristics can feel almost magical at times, but they are not actually magical. If you make parallel changes that affect a large XML file—for example, a XIB or an IDE project file—Git likely will not be able to merge those without human assistance.
Most importantly, Git cannot automatically resolve semantic conflicts. For example, imagine that in one branch Alice renames a method and in another branch Bob adds a new usage of that method. When those two branches are merged, Git will do nothing to help resolve the fact that Bob’s branch is calling a method using the old name. Bob’s code is calling a method that no longer exists. In fact, Git will not give Alice or Bob any clue that there is a conflict, since these semantic conflicts aren’t detectable by our current set of tools.
We’ll only find semantic conflicts when we try to compile our merged codebase, and even then only a subset of them. If the codebase is in a dynamically typed language such as javascript, we might not find out until our users start reporting app crashes in production.
Beyond the productivity hit of having to manually resolve these inevitable merge conflicts, the spectre of introducing a conflict can have a more pernicious, long-term effect on a codebase. A developer who sees an opportunity to incrementally improve the quality of the codebase is slightly disincentivized to do so if they sense that it could lead to a merge conflict.
The calculus for whether the effort of making a small improvement is worth the investment gets shifted as the cost of that change becomes higher. This introduces a subtle drag working against the internal quality of a codebase over time. What’s more, the type of small but broad refactorings that can gradually improve a codebase—or stop it gradually degrading—are exactly the type of changes that often lead to a merge conflict. In my opinion, this is the true hidden cost of branch-based development—it disincentivizes the sort of “boy scout rule” improvements that can prevent areas of a codebase from gradually degrading into no-go zones.
So, having established that merge conflicts are a Bad Thing, let’s look at how we might avoid them.
Working Directly on Master
A small team starting out on a new app might initially try to mitigate the risk of a big unexpected merge conflict by having all devs push frequently to a shared master branch—one of the central tenets of continuous integration. When everyone is frequently synchronizing their changes in a shared master branch, an unexpected merge conflict is revealed earlier and is easier to deal with.
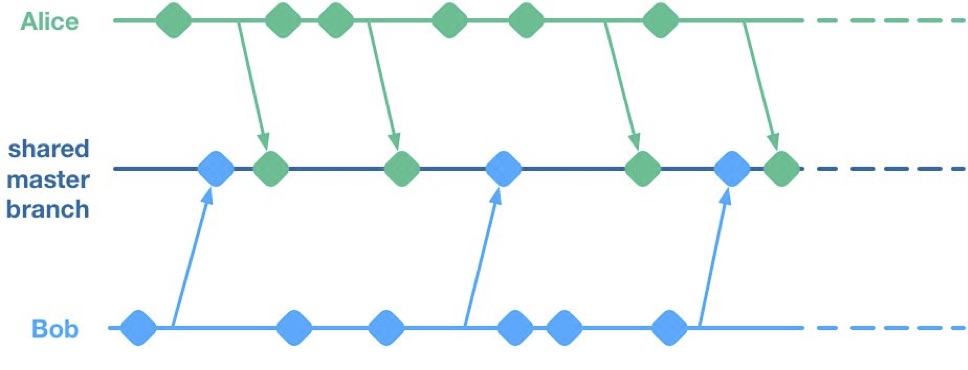 Unfortunately, having multiple streams of work landing on a shared master branch comes with a big drawback: If any of the streams of work are not ready for release, then nothing on the shared branch can be released. Let’s see why using a hypothetical example.
Alice and Bob are a two-dev team working on a mobile app. They have two streams of work in progress. Bob is working on a big overhaul of how user preferences work, while Alice is finishing off a critical new feature for the app which the big bosses have decreed must be pushed to the app store by the end of the week. This team is trying to avoid big merge conflicts by frequently pushing their code changes to a shared master branch as they go.
On Thursday, Alice is wrapping up her changes and doing some testing. While giving the app a general run-through she notices that the user preferences section is crashing. She asks Bob if he knows why. Bob explains that he’s in the middle of overhauling that area of the code. It’s taken a little longer than he expected and it might be buggy for a while. Alice gives Bob a look. She explains to him that her feature has to get to the app store this week. Bob gulps. Over the course of two long days Bob and Alice are able to roll back Bob’s changes, some of which had gotten tangled up with changes that Alice had been making as part of her new feature. They manage to ship to the app store by Saturday, and a crisis is averted.
We see here that because Alice and Bob were both committing to a shared branch, their independent streams of work became entangled. Alice could not release her changes without Bob’s and vice versa. This is the huge drawback of working on a shared branch—although we will discover later on that there are ways to mitigate this.
Feature Branches
To avoid this issue of coupled work streams, dev teams very often will move away from pushing in-progress code onto a shared branch. Some teams will opt to continue working on master on their local machines but only push to the team’s shared repo once the work is complete. Other teams will opt to use Feature Branches, maintaining separate streams of work on isolated branches and only merging them into master once they’re complete.
As an aside, it’s interesting to note that when using a distributed source control system like Git, these two approaches are essentially equivalent; the only difference is whether the unmerged in-progress changes are visible in a remote feature branch or hidden on a dev’s local master. As such, I’ll talk about both variants as Feature Branching.
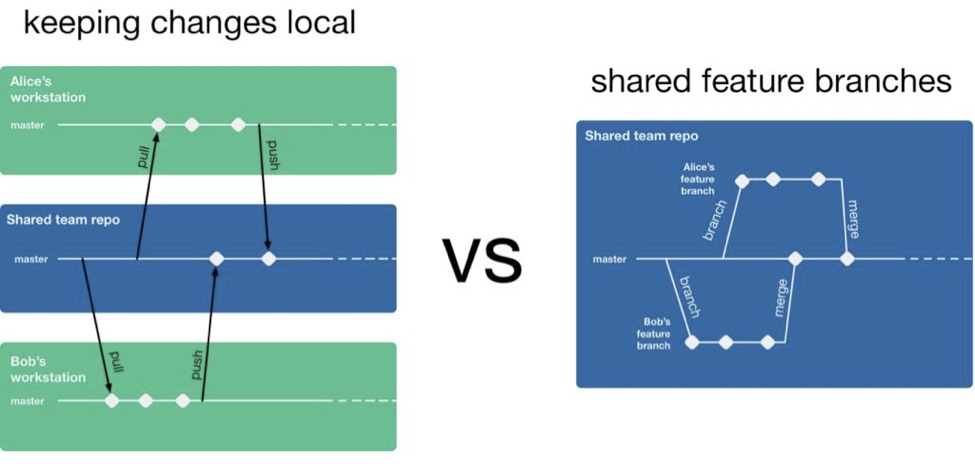 So, if a team is using feature branching, then all their problems are solved, right? Unfortunately not. We’ve now re-introduced the risk of painful merges. Work that is being done on a feature branch is not integrated with other changes until it is merged to a shared master branch. Whenever two streams of work both touch the same files, either inadvertently or intentionally, there is a latent merge conflict which continues to grow in size until one of those stream’s branch lands on master. Some teams will try to mitigate this issue by frequently merging changes from master back into in-flight feature branches.
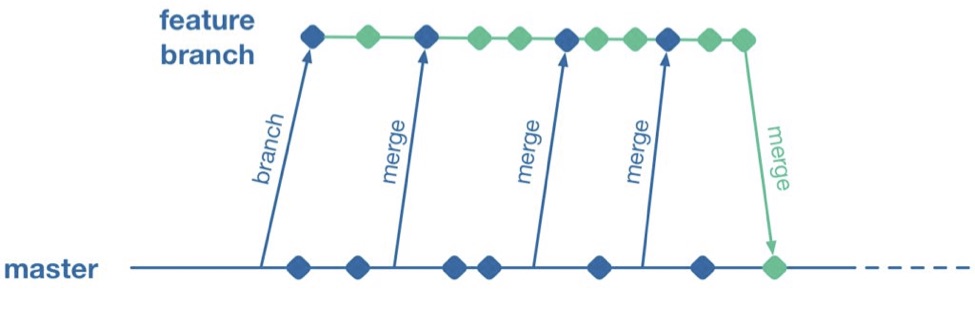 However, this does not help when parallel changes are occurring on isolated branches. Alice’s branch will only see Bob’s changes when his feature branch lands on master. The latent merge conflict between these parallel changes is now waiting for Alice the next time she merges from master.
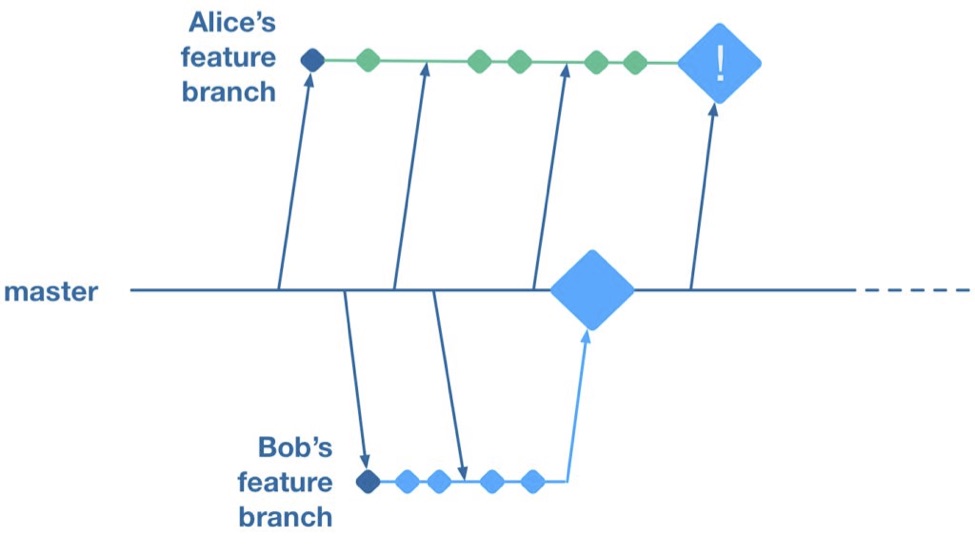 (Thanks to Martin Fowler’s feature branch writeup for inspiring the above illustration)
Some teams attempt to solve this problem by “cross-merging”—pulling work on one feature branch across into another feature branch to break down the size of latent merge conflicts between those branches.
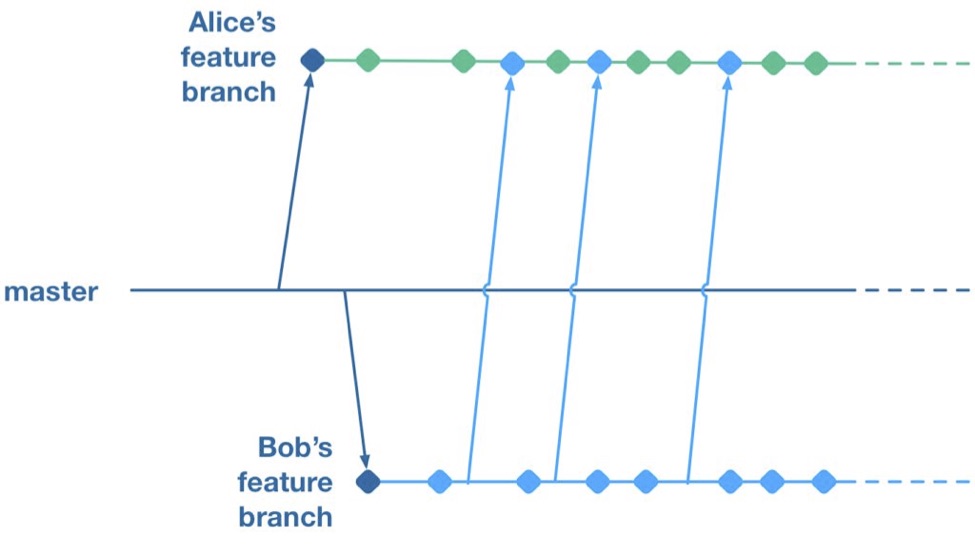 However, as soon as you merge two feature branches together you’ve essentially created a shared branch of in-progress work, and are back to the same problem as teams who are pushing in-progress changes to a shared master: Code changes from both work streams are now intermingled. Your features are now coupled together and cannot be released independently.
To summarize, feature branches allow teams to decouple streams of work such that they can be released independently. However, they introduce a risk of large merge conflicts when parallel feature branches contain large sets of changes. Remerging from master into feature branches only helps once parallel work has already landed, and cross-merging between branches couples features together in the same way as working on a shared master.
Feature Flags
What alternative does a team have if they want to avoid the merge conflict risks Feature Branches introduce? They could go back to frequently integrating changes on trunk, but we established that this has the major drawback that formerly independent streams of work are now coupled together and cannot be released independently. This is where a technique called feature flags (aka feature toggle, bits or flippers) can help.
A feature flag is a way to isolate work-in-progress code by placing it behind a “flag” or “toggle.” The work-in-progress code will only be exercised if the flag is flipped on. Otherwise, it will sit within the codebase as “latent code.” Here’s a sketch of how a basic feature flag might be used:
if( featureFlags.isOn(“my-new-feature”) ){
showNewFeatureInUI();
}Unless the my-new-feature flag has been configured as “on,” the new feature will not be exposed within the app’s UI. This means the app can be released even if the code implementing new feature is totally bug-ridden, as long as that feature’s flag is flipped off.
By using feature flags, in-progress changes can be pushed into a shared branch without blocking release from that branch. If Bob is halfway through his feature and Alice wants to push a release of her feature, the team can do that by creating a release where Alice’s completed feature is flipped on while Bob’s half-finished feature is flipped off. We get the benefit of continuous integration of developer work streams (reduced risk from merge conflicts) while still keeping release of those work streams decoupled.
This technique is not particularly new. It is part of a family of techniques sometimes referred to as trunk-based development (you can tell the technique is not new because the name uses trunk rather than the mastermoniker, which is more common today due to git’s predominance). Flickr, Etsy, Github and Facebook are some better-known proponents of the technique. Facebook’s use of feature flags is one of the key enablers for its famous ability to deploy facebook.com from a shared branch twice daily.
Drawbacks of Feature Flags
As with the other approaches discussed so far, feature flags have their share of drawbacks. They introduce a fair amount of noise into a codebase as we now need to explicitly implement some sort of branching logic for any incomplete feature. This noise can lead to some messy code over time unless care is taken to retire old feature flags once they are no longer necessary. Testers can take a while to get comfortable with feature-flagged apps—the idea of shipping unfinished, untested code to the app store takes a while to get used to. If the flags can be controlled remotely at run time, then teams need to understand that the new configuration of flags must be tested before being applied to apps deployed to end users.
Finally, certain types of changes are particularly hard to protect via feature flags—broad but shallow changes that touch a lot of files can be a challenge. Happily, feature flagging is not an all-or-nothing approach; feature branches can still be used for a change that would be particularly fiddly to implement behind a flag.
Succeeding with Feature Flags
When a team starts to adopt feature flagging they will usually run afoul of some of the challenges discussed above, and eventually figure out ways to mitigate them. Here are some of those techniques for working successfully in a feature-flagged codebase.
Expire Your Flags
A lot of teams get a bit flag-happy when they first start using the approach. They tend to introduce a lot of flags, but not take the time to retire the flags once they not longer need to control whether a feature is on or off. Make sure to take the time to retire old flags—they introduce design drag in your codebase and confusion when managing flags. Some teams take quite aggressive approaches ensure old flags are expired, such as setting “timebombs” when they create a flag, or having it throw an exception if it’s still in use after a certain period of time. Other techniques include adding a flag removal task to the team’s backlog at the time the flag is created as a reminder.
Flags Aren’t a Silver Bullet
It doesn’t always make sense to use a feature flag for a new stream of work. Flags lend themselves best to a new feature or alternative feature where access to the feature can be controlled from a single point in the code—often by showing or hiding a button or changing what happens when you tap some part of the UI. Other types of work, such as internal refactoring, is hard to protect behind a flag. For that type of work, consider using a feature branch, ideally breaking the work down into smaller chunks that can be implemented incrementally in a series of branches rather than one long-lived branch. This will reduce the risk of a large merge conflict growing over time.
Summary
Feature flagging and feature branches are both ways to decouple parallel code changes and allow teams to release changes with less coordination overhead. Feature branches are easy to get started with, but can lead to painful merge conflicts. This risk of merge conflicts tends to disincentivize making incremental improvements to a codebase, and can lead to areas of the codebase becoming “no go” zones. Feature flags allow teams to practice true continuous integration and totally decouple code changes from feature release, at the cost of some complexity in implementing each flag.
Feature flags are not a silver bullet and aren’t always the right choice, but it’s easy for a team to experiment with the approach. You can get started simply with a single hard-coded if/else statement, see how it goes and take it from there.
About the Author / Pete Hodgson
 Pete Hodgson is a consultant to Rollout.io, a software engineer and an architect. His clients range from early-stage San Francisco startups to Fortune 50 enterprises, focused on enabling continuous delivery of software at a sustainable pace via practices like test automation, feature flags, trunk-based development and DevOps. Pete is a frequent podcast panelist, regular conference speaker in the US and Europe, and a contributing author.