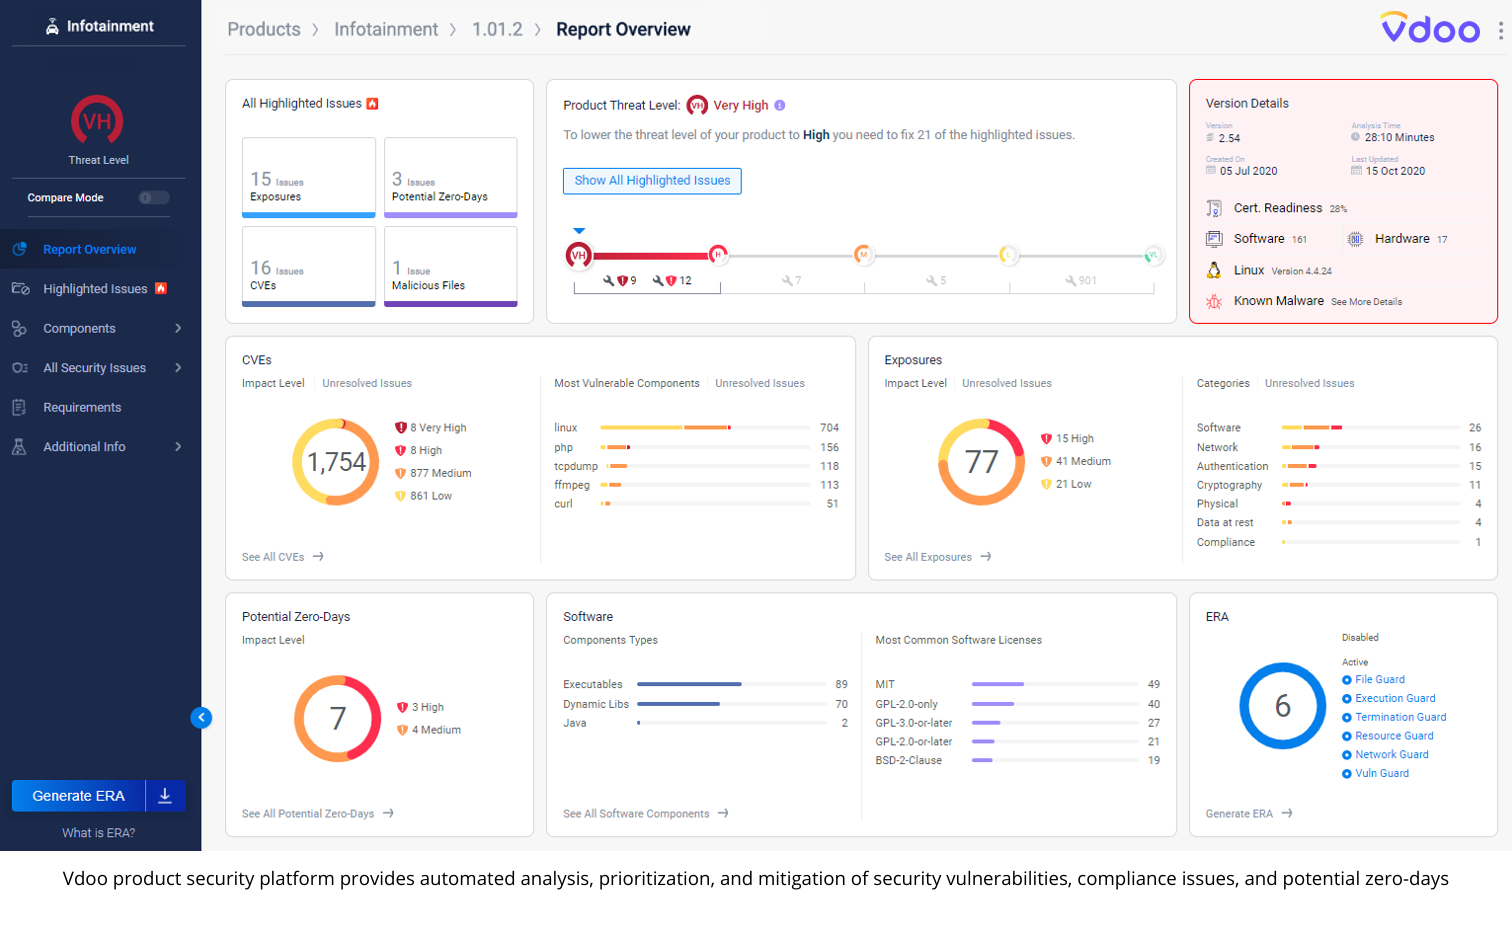
JFrog today announced it has agreed to acquire Vdoo for $300 million in cash to gain a set of analytics tools that discover vulnerabilities in application binaries.
Vdoo’s scanning tools, infused with machine learning algorithms, will be fully integrated with the JFrog Xray vulnerability detection tools along with the rest of the JFrog continuous integration/continuous delivery (CI/CD) platform in 2022. In the meantime, the Vdoo scanning tool will continue to be made available via a software-as-a-service (SaaS) platform that Vdoo built.
The Vdoo platform is already integrated with the JFrog Artifactory repository and JFrog Pipelines. Vdoo’s platform also is integrated with DockerHub, Jenkins, GitHub, GitLab and Azure Pipelines via REST application programming interfaces (APIs) that make the Vdoo scanning tools accessible via a command line interface (CLI).
JFrog CTO Yoav Landman said acquiring Vdoo is critical because when it comes to implementing DevSecOps best practices, the only meaningful place to discover and remediate vulnerabilities is in the binaries deployed in production environments. As such, the Vdoo platform provides a superior alternative to both static application security testing (SAST) and dynamic application security testing (DAST) tools that scan for vulnerabilities in source code, added Landman.
Developers require accurate intelligence that can be quickly acted upon to secure applications running in production. They can quickly take action once they know how a specific vulnerability impacts a binary, versus being told to update source code that could take days or weeks to complete, noted Landman. The Vdoo platform also makes it possible to leverage machine learning algorithms to detect zero-day vulnerabilities, malware, exploits, backdoors, supply chain risks and other threats before they become commonly known. Those vulnerabilities can be detected in everything from application binaries to firmware running on embedded devices. Vdoo is also recognized by the Mitre Corp. that oversees the Common Vulnerabilities and Exposures (CVE) database as a CVE Numbering Authority (CNA) for discovering vulnerabilities.
As responsibility for application security continues to shift left toward developers, many organizations are finding the tools that cybersecurity teams employed to discover threats don’t lend themselves to the workflows that developers have created to build applications. As a result, many of these tools are being replaced by developer-friendly alternatives that developers can invoke via a CLI as part of DevOps workflow. The goal, now, needs to be reducing the level of noise created by security tools to enable developers to focus on the vulnerabilities that specifically impact their code, noted Landman. Otherwise, developers are simply overwhelmed by a massive number of alerts generated by security tools that often don’t appear to be especially relevant, Landman added.
It’s not clear how quickly responsibility for application security is shifting left. However, in the wake of a series of high-profile software supply chain breaches, the urgency surrounding adoption of DevSecOps best practices has increased considerably. The challenge, as always, is getting the right tools into the hands of developers at the right time.
Modern applications are mobile first and are built around cloud-native distributed microservices architectures. These architectures have become the basic building blocks for complex and reliable distributed web and mobile applications. Many of these distributed APIs expose the business logic directly over the web; hence the attack surface and attack vectors are very different for these next generation applications. These next-generation applications demand next-generation application security solutions that need to stitch together a distributed application’s activity using techniques such as distributed tracing and then use next generation ML techniques to solve important application security problems.
Proactive anomaly detection
Anomaly detection approaches are a practical way to discover unseen strategies of attackers. However, these approaches are prone to very high false positive rates, thereby defeating their very purpose. Most anomaly detection systems flood analysts with false alarms resulting in a cognitive fatigue. Traditionally, the pitfalls of anomaly detection approaches have been addressed via false-positive workflows, better user interfaces and user experience tools. Analyst feedback is taken as a reinforcement on the algorithm and the algorithm tunes itself. However, the engineering cost of such an approach is very high and the product gets very complex leading to reliability and flexibility issues. Secondly, it still requires analysts in the loop to tune the back-end algorithms. Most practitioners think the issue lies with the anomaly detection algorithms, but in reality there is nothing much that the underlying mathematics powering these algorithms can really do in a cyber security setting. These very algorithms have been proven in domains other than cyber security. At Traceable, we believe that the problem lies elsewhere. Our understanding of the nature of data shows that we need to support anomaly detection algorithms with something else. We need to marry specific application security nuances with the mathematics powering these anomaly detection algorithms. This understanding led us to build TraceAI.
TraceAI and API
TraceAI is the core engine that powers the application security functions of the Traceable Security Portfolio. The foundational principles behind TraceAI are:
To be able to dissect the AppSec requirement into the constituent entities that are root causes for application vulnerability
To be able to holistically observe the interaction behavior among these entities
To be able to discover anomalous patterns in this behavior
Using these guiding principles TraceAI implements a complex behavioral anomaly detector. To power this behavioral anomaly detector, we have identified five entities that interact with one another to result in security vulnerabilities. They are:
APIs – the basic building blocks of the distributed applications
API interaction – how these APIs are wired in order to provide the intended functionality
Actors – users, IP addresses or client-side applications such as mobile apps that use APIs to benefit from the intended functionality or in a malicious case, subvert the intended functionality. The actors may be assigned different roles such as admins, clients, managers etc…
API Data – inputs from actors required for the APIs to come to life. Outputs from APIs in response to the input.
Resources – back-end data or compute functionality requested by actors by calling APIs
TraceAI combines APIs, API interaction, API data, resources and actors holistically to build an actor-centric and API-centric behavioral anomaly product. As a result, common behaviors, outlier behaviors, automaton behaviors (bots), and attack behaviors are discovered from trace data. These behaviors are API-centric as well as Actor-centric.
False positives are eliminated by introducing additional security concepts commonly referred to as Trust-and-Risk models. TraceAI automatically identifies API risk and Actor-trust by observing data relative to a baseline which is again automatically built. The baseline in itself is not a piecemeal integration of various unconnected baselines, but is a holistic combination of various observations modeled using modern machine learning tools. We do not need teams of data scientists and security engineers to support the system as the underlying algorithms automatically learn from data. Once in production, the algorithms run in a self-drive mode, automatically building baselines and generating ML models.
Machine learning algorithms under the hood
The foundation of any machine learning is the depth and breadth of the dataset relative to the number of features used for detection purposes. Traceable agents, deployed inside your application, API gateways, and Kubernetes cluster, automatically collect all the necessary data and build distributed traces that form the data-layer foundation for TraceAI. Traces are continuously collected to become a learning set on logic and data flow from Edge APIs, to internal APIs to backends and third party services and thus generate the features that represent the application context. Having addressed the data challenge via the tracing platform our next challenge was to choose appropriate machine learning technology.
The biggest challenge for machine learning in cybersecurity is having to deal with high-dimensional categorical data of sequential nature, combined with the need for explainability, causality, and attribution. Because the attackers’ strategy constantly changes, supervised learning has its limitations. Most popular ML algorithms fail miserably while simultaneously dealing with these two requirements. Taking these factors into account, we have engineered ML-based solutions by building algorithms ground-up (instead of fully relying on libraries) and adopting a self-supervised learning framework. Our unique way of representing multidimensional categorical information allows us to perform ML-based detection even on certain forms of encrypted data as well.
A key component of the ML-based solution is the ability to discover the API endpoints, and to automatically generate the API spec via data analysis. As a result the expected request/response headers, body parameters and query parameters are not only identified, but are also characterized. This helps build the API spec, violations to which are flagged as anomalies. This completely automated process without the need for manually annotated data is feasible owing to the richness of data captured by the core distributed tracing platform.
Complementing the ability to detect API data anomalies, TraceAI also detects anomalies in API interaction, and anomalies in users accessing these APIs. The User Behavior and Business Logic representation modules capture, represent and build baselines for regular user behavior and expected business logic. Unsupervised ML techniques are employed because these techniques are the only scalable alternatives. Once the baseline models are built, business logic abuse and behavior deviations are captured and surfaced as alerts.
Extending behavioral anomaly detection to predictive threat detection, TraceAI introduces a novel exploratory learning paradigm for API security. This approach harnesses the fundamental principles behind reinforcement learning, adapted uniquely to application and user behavior representation. Using such an approach, we are able to generate potential anomalous patterns even before they occur. By comparing users’ activities against these generated patterns, we can identify users who are beginning to tread on a dangerous path. Hence, we can flag these users even before a full-blown attack is launched. As a byproduct, we are also able to quantify known and risky behaviors without manual intervention. Some of the machine learning techniques that we have used in order to power TraceAI are MinHash based embeddings, hierarchical user behavior clustering using LSH and OLAP-style sub-clustering, Bi-Directional RNN variants for time-series anomaly detection, and use of random walks with evolutionary algorithms for explorative learning.
Anomalies in user behavior in the context of business logic
Understanding application behavior and user behavior helps in:
Identifying violations to known user behaviors
Discovering novel behaviors
Grouping users based on their behaviors to create user cohorts
Determining how exactly APIs are being used in order to build a web application
One can represent user cohort behavior as a summarized flow-graph as shown below.
Sample application flow.
Each node in the graph represents an API that was called during an active user’s session. Two nodes are connected if there is a transition from one API to another, and the flow between two nodes represents various statistics such as how many users exhibit such a transition or how often such a transition occurs across user sessions and so on.
In the above figure, there are around 26 different nodes, each representing an API, and the flows connecting these nodes indicate paths of API access based on monitoring users’ API call graphs. For a human analyst, this map is very difficult to comprehend and more so to detect that a particular user’s behavior has changed compared to other users’ behavior or to detect that a particular user’s behavior has changed compared to a baseline. Only machine learning algorithms can automatically interpret these kinds of representations and that too at the scale that we have to deal with.
Behavioral clusters
The figure above shows how TraceAI was able to create user behavior groups based on the pattern of API access. In essence TraceAI has peered into the complex flow graph shown above and then identified groups of users based on their respective API call flow behavior. The gray circles represent users who fall under commonly occurring behavior groups. These groups are low priority for an analyst as they are population characteristics. The red circle-A represents a user whose behavior is very similar to the gray circle-B. This means the user in circle-A is accessing the same APIs as users in circle-B but managed to attack one or more APIs. This further implies that the user in circle-A is following the same business logic as many other users but has managed to compromise one or more APIs. This is interesting information for an analyst, because one can now understand what led to the compromise in addition to knowing what was compromised.
Tracking user behavior to detect API attacks
Here, the figure above shows the user’s behavior and where exactly the attacks took place. There were authorization bypasses detected in two of the APIs (nodes) colored in red. The analyst now knows where the attack took place and how they got to this stage. The APIs leading up to the attacked API can now be analyzed for security vulnerabilities and code design flaws. In essence TraceAI has isolated and surfaced interesting behaviors from many possible behaviors so that security analysts can investigate further. By cutting down on possible candidates, TraceAI has reduced cognitive load and investigation fatigue by many orders of magnitude. TraceAI can also detect outlier behavior to flag groups of users who are not explicitly responsible for a known attacks, but are exhibiting suspicious behavior and not being like the rest of the users. Analysts can also dig into the outlier groups shown as “blue” circles, analyze few of these users, and then as a batch put all these users under a watch list. By working at the level of a group, multiple users can be tagged/flagged/watched without having to deal with each user separately.
Summary
Traceable combines the power of Distributed Tracing and TraceAI technologies to protect next generation attacks on Web Applications and APIs. By choosing the right machine learning technology, and focusing on addressing API security issues Traceable is pushing the boundaries of API security.
We would love to talk to you further and demonstrate how our technology addresses API security issues in your environments.
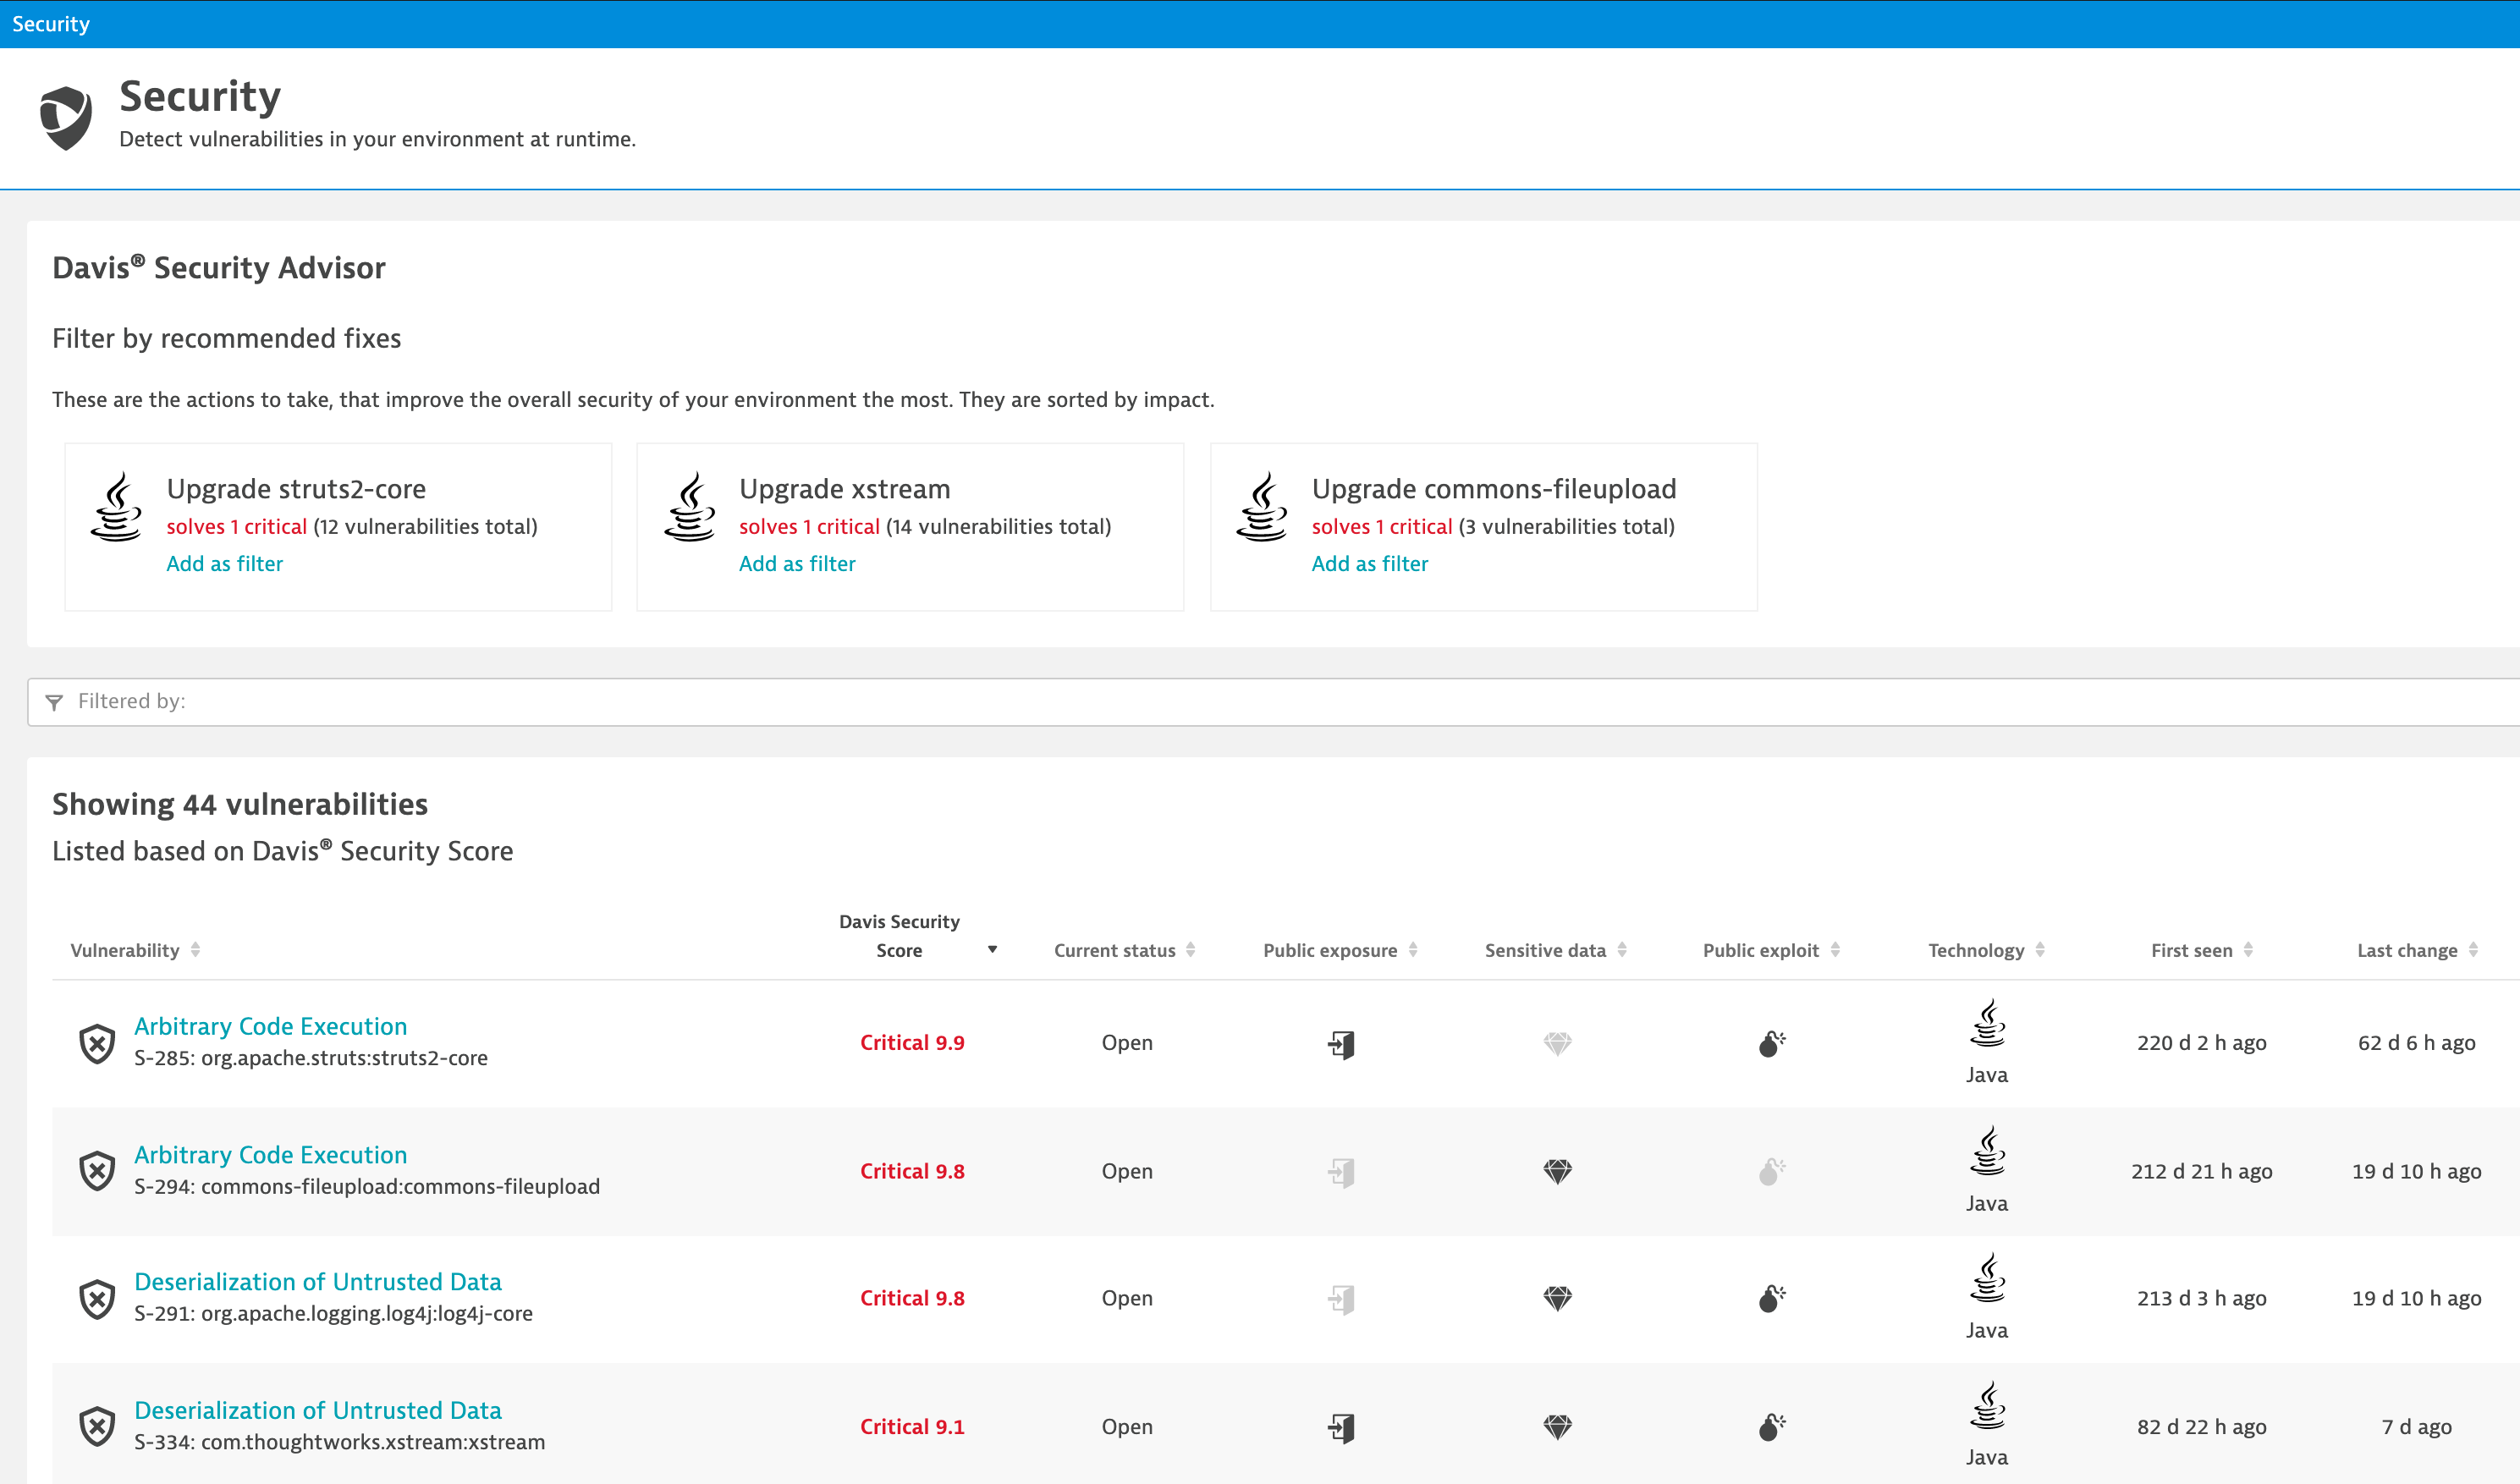
Dynatrace has enhanced the security module to its observability platform that leverages its Davis artificial intelligence (AI) engine to automatically identify the software libraries and open source packages that represent the greatest security risk.
Ajay Gandhi, vice president of product marketing for Dynatrace, said the Davis Security Advisor, being added to the Dynatrace Application Security Module, makes it easier for IT teams to understand which vulnerabilities need to be remediated first.
Davis Security Advisor aggregates vulnerability data in real-time and prioritizes remediation based on the number of vulnerabilities, severity, impact to sensitive data, public exposure, how widely known the vulnerability is, and whether the code impacted is facing the internet. That approach enables Davis Security Advisor to monitor all software libraries used in preproduction and production environments in a way that sharply reduces the number of false positives that would otherwise be generated, noted Gandhi.
As application environments become more complex—in part due to increased adoption of microservices that have lots of dependencies—it’s become impossible for IT teams to implement DevSecOps best practices in workflows without some form of AI augmentation, added Gandhi.
In fact, a recent Dynatrace survey found 89% of chief information security officers (CISOs) noted cloud-native architectures and container runtime environments, used primarily to construct microservices, have made it more difficult to detect and manage software vulnerabilities.
In theory, application developers are taking more responsibility for remediating security vulnerabilities within their applications. The challenge is they often inadvertently use an older version of a library that has known vulnerabilities. Hopefully, that issue gets addressed before an application gets deployed. There are, however, plenty of cases where, for one reason or another, a library with known vulnerabilities gets deployed anyway.
Making matters more challenging, many vulnerabilities are discovered after an application has been deployed. Developers don’t always have access to a software bill of materials that would make it easier to determine what libraries have been employed in what application or, for that matter, which libraries are dependent upon one another.
Gandhi said the Davis Security Advisor resolves that issue via continuous topology mapping of dependencies to identify those potential security issues. Once identified, the updates that need to be made can then be slipstreamed into a DevOps workflow.
Analyzing code for vulnerabilities is, of course, not a new idea. Training an AI model to perform that task on behalf of DevOps teams does promise to greatly accelerate the process at a time when organizations are under more pressure than ever to secure their software supply chains in the wake of a series of high-profile breaches.
It’s just not clear yet who inside organizations might drive adoption for AI platforms capable of identifying vulnerabilities in a way that helps prioritize remediation efforts. In some cases, cybersecurity teams have a vested interest in reducing the number of potential security incidents.
The one thing that is apparent is shipping insecure code faster only leads to more negative outcomes. There may not be such a thing as a ‘great’ application that happens to be insecure. Instead, the assumption will be that any applications with known vulnerabilities, no matter how great, are too flawed to be deployed given all the security risks most businesses currently face.
A while back, I had a conversation with a friend I went to school with (currently a senior member of the engineering team at a large retail chain) who was tasked with the job of identifying potential application security partners (he addressed vendors as partners, which I personally liked) to collaborate with on various areas as part of their product security initiative. The following piece emerged as an extension of my immediate thoughts when he shared his views of what could have made his experience of interacting with front-line sales and marketing folks better.
In the context of DevSecOps, much has been said about the need for engineering to speak security, security to speak code, DevOps to speak security, etc. But as a technology service provider (TSP) riding the current wave of application security, it’s almost mandatory for the sales and marketing teams to also speak relevant tech!
Application Security Is Not One-Size-Fits-All
Application security, as a practice area, is dynamic. No two applications are the same, even if they belong in the same market domain, presumably operating on identical business use cases. Some (of the many) factors that cause this variance include technology stack of choice, the programming style of developers, the culture of the product engineering team, priority of the business, platforms used etc. This, consequently, results in a wide spectrum of unique customer needs.
Take penetration testing as an example. This is a practice area that is, presumably, well-entrenched both as a need and as an offering in the application security market. However, in today’s age, even a singular requirement such as this could make or break an initial conversation. While for one prospect, the need could be to conduct the test from a compliance-only perspective, another’s need could stem from a proactive software security initiative. There are many others who have internal assessment teams and often look outside for a third-party view. Others who are further along the maturity curve could be looking to up their game through a hybrid approach of tool automation with a complementary method of manual assessments. I’m not even considering the added complexity involved in the nomenclature of such a service—is it called penetration testing, security testing, vulnerability testing, VAPT (which actually is a combination of two independent practices) etc.?
Each of these unique needs emerges from buyer personas which emerge from varying degrees of informed decision making. TSP’s would need to retrofit their positioning accordingly. They often run the risk of underwhelming a mature buyer or overwhelming an early practitioner, especially in high variance offerings such as security tooling, security regression and threat modeling, for example. While some might argue that losing an overwhelmed prospect could be the result of their accurate customer segmentation, there are other reasons for this.
Scoping questions, such as the ones below, can significantly help technology marketers strike the right chord with their prospects and elevate the experience of the initial interaction.
What is the motivation for the penetration test? Is it compliance regulation, internal validation, business drivers, their customers’ needs, etc.?
What are they specifically looking from a third-party partner? Is it external certification, a specialized approach, uncovering logic flaws, etc.?
What is the current appetite (measured in resource bandwidth, commerce) to take on your advanced offering? (Such as automation, regression etc.?)
How security aware are the developers? Can they take the findings to their logical conclusion through successful remediation?
DevSecOps Is About the Journey, Not the Destination
Ever since the surge of DevSecOps, marketers and practitioners have been vocal about the possibilities and advantages that smart automation brings with it. Think tanks, too, have statistically alluded to its benefits in terms of cost savings and bandwidth efficiency, among others. Though recent marketing campaigns have rather effectively communicated the ‘what of DevSecOps and AppSec automation, more awareness of the ‘how’ of DevSecOps is needed. TSP marketers need to design and propagate content on use cases focusing on the implementation challenges and suggested how-tos. Such content not only helps build trust and credibility but also allows segues for tech marketing to collaborate with security engineering. Some of these include practical guides on open source tool automation and sample automation scripts and libraries, data sheets on resource optimization through automation and handbooks on vulnerability remediation, just to name a few.
This collaboration between marketing and sales and security would provide an opportunity for the former to get themselves well entrenched in the practical workings of the service or solution that they are responsible for positioning. Ironically, this also allows them to appreciate constraints that would prevent them from over- or under-committing business value to their prospects through their messaging. This is especially more relevant with the numerous myths that surround application automation and DevSecOps in general.
The DevSecOps Rolodex
In 2012, I had the opportunity to meet with one of the senior CISOs in the industry. After some initial small talk, I was introducing what we did and how we thought we could help his team. I was 70 seconds into what was my planned 180-second pitch when he respectfully stopped me, pulled out a rather impressive Rolodex from his desk and said, “I could point you to 15 companies in a 20-mile radius who could help me with exactly what you’ve offered me. I wonder if there’s any secret sauce?”
Startled, embarrassed, I managed to gather my thoughts and moved to the final 30 seconds of the pitch, though with much hesitation. As luck would have it, he found little bits of the secret sauce. The meeting obviously did not go exactly as I had planned, but it didn’t go badly, either. However, it made me realize that our customers and prospects often know just as much—or even more—about our competition than we do. Everybody is selling, all the time. So, someone else has already made their 70-second pitch. Not everyone gets lucky enough to be given an opportunity for a pause! It’s up to us to find the secret sauce and make that close in the final 30 seconds.
We are riding a very healthy wave of application security focus right now, and it’s paramount that technologists and marketers collaborate to identify and nurture their own secret sauce in their messaging and positioning. After all, this is what is going to keep the person at the other end of the table from reaching out to others in their DevSecOps Rolodex!
Google is proposing organizations adopt a framework for securing the integrity of software artifacts across a software supply chain.
Kim Lewandowski, a product manager for open source software security at Google, said the Supply Chain Levels for Software Artifacts (SLSA) is based on an internal framework, known as binary authorization for Borg, that the company has been employing now for more than eight years to secure its software. Borg is the name Google attached to the platform for building and deploying applications upon which Kubernetes is based.
In its current form, SLSA is a set of guidelines that identifies how to attain four different levels of application security. The goal, however, is to create a framework that will automatically generate auditable metadata that can be fed into policy engines to create a SLSA certification.
The lowest level of SLSA requires that the build process be fully scripted or automated and generates metadata that enables provenance to be created. At the highest level, SLSA requires a two-person review of all changes made during a hermetic, reproducible build process. At the highest SLSA security level, organizations should be able to assure others that their software supply chain has not been compromised, said Lewandowski.
In the wake of a recent series of high-profile breaches of software supply chains, the level of scrutiny being applied to how software is constructed has increased significantly. In theory, at least, developers have assumed more responsibility for application security as part of an overall shift left that provided them with more programmatic control over IT environments. As a result, cybercriminals are now focused on compromising either the credentials of developers as part of an effort to insert malware into application as it is developed, or they are trying to exploit vulnerabilities that developers have inadvertently created by programmatically misconfiguring infrastructure.
DevSecOps best practices are, of course, being adopted to teach developers how to better secure their application environments. The issue is that not enough developers are learning how to secure applications fast enough. The volume of attacks against the software supply chain continues to grow at a rate that is now much faster than organizations can thwart simply by educating developers. In some cases, organizations are once again empowering cybersecurity teams to make sure software supply chains are secure regardless of the potential impact on the rate at which applications are being developed.
Google is trying to promote adoption of SLSA as a framework for securing both open source and proprietary application code, said Lewandowski. There’s no silver bullet for securing software, but a framework that ultimately automates as many of the security processes as possible within the context of a DevOps workflow would go a long way toward hardening the software supply chain, noted Lewandowski.
SLSA is being put forward as a response to a cybersecurity executive order issued by President Biden that, among other things, tasks the National Institute for Standards and Technology (NIST), an arm of the U.S. Department of Commerce, to consult with federal agencies, the private sector, academia and other stakeholders in identifying standards, tools, best practices and other guidelines to enhance software supply chain security. Given the level of dependencies that exist across those software supply chains, that executive order, to varying degrees, now applies to almost any entity that builds software for an organization that, on some level, interacts with the Federal government.
Accurics today announced it has integrated its tool for discovering violations of security policies that occur when developers provision infrastructure as code with both the continuous integration and continuous delivery (CI/CD) platform and the static application security assessment testing (SAST) tools from GitLab.
Om Moolchandani, chief information and security officer (CISO) and CTO for Accurics, said both integrations make it easier for developers to discover security issues earlier as part of a DevSecOps workflow using the company’s Terrascan tools.
The integration with GitLab makes it easier to incorporate Terrascan into a DevOps workflow in a way that also aggregates data collected from both SAST and dynamic application security testing (DAST) tools, said Moolchandani. That approach effectively unifies what today are two separate cloud infrastructure and application development pipelines by enabling DevOps teams to employ threat scores to enforce security policies as code that are deemed too risky to deploy with block builds, he added.
At the same time, the integration with SAST and DAST tools provides the context developers need to prioritize remediation efforts before applications are deployed in a production environment, noted Moolchandani.
Organizations of all sizes are now trying to strike a balance between two conflicting agendas. On the one hand, infrastructure-as-code (IaC) tools such as Terraform have played a critical role in enabling developers to build and deploy applications faster. The issue is that developers lack the security expertise required to ensure infrastructure is secured properly at a time when cybercriminals are more aggressively seeking to compromise software supply chains. Organizations most likely won’t slow down the rate at which applications are being deployed to make sure software supply chains are not compromised. However, in the absence of best DevSecOps practices—which still are not widely implemented—there may be a backlash against shifting application responsibility left toward developers.
The challenge that creates is most organizations don’t have enough security expertise available to review applications in a timely manner before they are deployed, which results in them hoping security issues will be discovered and remediated during the application update cycle before cybercriminals find a way to exploit a vulnerability.
Of course, hope does not make for an application security strategy. Organizations will need to find ways to enable developers to better secure applications while simultaneously making it easier for cybersecurity teams to maintain a zero-trust IT environment that reduces the chances organizations will be breached via, for example, a phishing attack to steal developer credentials.
Regardless of how DevSecOps workflows and zero-trust IT architectures are implemented, it’s clear organizations have run out of time to resolve longstanding security issues that are now making the kinds of headlines no one wants to see.
Today’s blend of third-party application dependencies and polyglot software development often makes assessing risk difficult. With many new cloud-native deployment models, it can be tricky to discover potential vulnerabilities. These threats take the form of insecure default settings in Kubernetes, over-permissive states, CVEs that threaten container integrity, and other vulnerable conditions.
Plugging gaps throughout the cloud-native strata is now crucial to avoid exposing data and breaking privacy regulations. Yet, gaining visibility into these holdings is challenging, and traditional application security practices may not cut it within a cloud-native context.
A new 2021 CISO Report released by Dynatrace, “Precise, automatic risk and impact assessment is key for DevSecOps,” demonstrates increased false positives and a general lack of real-time container runtime vulnerability scanning among enterprise IT departments worldwide. Of the 700 CISOs surveyed, most report that microservices, containers and Kubernetes have caused security blind spots across their organizations.
Below, we’ll cover the major takeaways from the study to see why new cloud-native development models are leaving security gaps. We’ll consider how CISOs can increase security throughout the cloud-native IT stack while still reaping the rewards of container-based delivery models.
Cloud-Native Security Blindspots
Adopting new container-based technologies may introduce multiple nuanced security implications. Of the tech leaders surveyed, 89% report that microservices, containers and Kubernetes have created new vulnerabilities within their organizations.
Engineers are shipping code to maintain release velocity and to meet the demand for digital innovation. In the process, 28% of CISOs say application teams sometimes bypass vulnerability scans to speed up software delivery. Due to these realities, it’s no surprise that 71% of CISOs admit they are not fully confident code is free of vulnerabilities before going live in production.
As some teams bypass security pre-production, it follows that more aren’t applying holistic security scanning during production. As a result, nearly all organizations (97%) lack real-time visibility into runtime vulnerabilities, found the report.
Adding to the number of cloud-native blindspots is information overload. The report calculated that, on average, an organization receives a staggering 2,169 new alerts of potential application security vulnerabilities each month. Out of this high volume of alerts, 77% of CISOs say they are mostly false positives and not actual exposures.
Due to minimal testing and a high number of false positives, organizations are likely to leave many vulnerabilities unpatched. To make matters worse, developers, pressed for time, may lack the bandwidth to resolve known issues.
Faster Delivery, Harder Detection
Much of the setbacks in vulnerability detection may lie in a general shift toward new ways of working and faster delivery cycles. For example, 63% of CISOs reported that DevOps and agile methodologies are making it harder to detect and manage vulnerabilities.
In addition, 74% of CISOs say traditional security controls such as vulnerability scanners no longer fit today’s cloud-native world, and 77% of CISOs agree that automation could help. This could involve replacing manual deployment, configuration and management with more automated approaches. Others agree that security-as-code is required to ensure high container security best practices.
Another result of more frequent delivery is increased over-reporting. Of the total security vulnerability alerts received per month, CISOs report that only 42% of these alerts require action. More rapid release cycles could thus exacerbate already crowded vulnerability detection systems.
Who Owns Vulnerability Management?
Only 3% of organizations have real-time visibility into runtime vulnerabilities in containerized production environments, the study found. In reality, vulnerability scanning in production is only happening once a month or less within 68% of organizations.
To compensate for this gap, most CISOs believe the onus is not on the security team but the application and DevOps teams to manage and respond to vulnerabilities—85% of CISOs believe these groups should hold responsibility for vulnerability management. These findings come to light as other stakeholders advocate for increased full-cycle developer control and encourage the DevOps mindset across roles.
Handing more control to developers sounds good, yet, 64% of respondents say developers don’t always have time to resolve vulnerabilities before code goes into production. As a result, over one-quarter of application teams bypass vulnerability scanning entirely. Often, engineering teams may not frequently sync with security groups, and DevSecOps principles are not yet pervasive throughout all organizations.
The report also highlighted the fact that existing security tools are often ineffective; 69% of CISOs say security tools slow down DevOps because they only focus on one state of the software delivery cycle.
Cloud Use Requires Security Repositioning
As cloud architectures rise in prominence, organizations are adopting cloud-native tools like microservices, containers and Kubernetes. There is also the chance of multi-tool conditions further complicating the vulnerability scanning process. With more systems to protect than ever before, teams may have to reposition their approach to vulnerability detection.
“The increased use of cloud-native architectures has fundamentally broken traditional approaches to application security,” said Bernd Greifeneder, founder and chief technology officer at Dynatrace. “This research confirms what we’ve long anticipated: manual vulnerability scans and impact assessments are no longer able to keep up with the pace of change in today’s dynamic cloud environments and rapid innovation cycles.”
The Global CISO report, “Precise, automatic risk and impact assessment is key for DevSecOps,” from Dynatrace, queried 700 chief information security officers (CISOs) on their monitoring practices concerning vulnerabilities. To review the report’s full findings, you can download it here.
Today, more than 300 vendors and various platforms offer different flavors of low-code solutions. However, the majority of these low-code tools are really no-code tools that benefit individuals or groups trying to solve a specific program. The list of benefits of low-code tools in your environment is long and compelling; however, there are security risks that businesses should be aware of when working with these powerful tools.
When evaluating or using a low-code tool, it’s important to remember that while low-code tools abstract the process of writing code, code is still being written. Applications created with low-code tools are susceptible to the same attacks as any other web application. However, companies don’t have control over the code generated by a low-code tool, so the burden of developing secure applications is largely shifted to the low-code tool vendor. Therefore, the best way to minimize risk when using a low-code vendor is to properly evaluate that vendor’s security practices and test applications created using these tools as vigorously as you would any application developed using a traditional/pro-code approach.
Risks to consider include access control and authentication (permissions, multifactor authentication), data security (encryption in transit and at rest) and application security from vulnerabilities and attacks (network security and intrusion detection). Other risks to consider are risk mitigation covering areas such as DDOS (distributed denial of service) attacks, backup and disaster recovery, and security incident handling. Responsibility for management of these risks belongs to the low-code vendor, the hosting provider and the company using the low-code tool.
The following tips should be considered when bringing new low-code tools into your environment to minimize security risk. Remember, it’s critical to perform due diligence of the vendor. Items to consider include:
Hosting Platform: Be sure the vendor is using a reputable hosting provider, ideally Amazon Web Services (AWS), Google Cloud Platform, Salesforce or Microsoft Azure. Leading players will offer secure, highly available platforms that address the aforementioned risks and will have completed third-party audits and certifications demonstrating their commitment to security.
Vendor Infrastructure Management: Low-code vendors typically have some level of responsibility for management of the upper tiers of the overall stack; this is generally referred to as the shared security model. Review the vendor to ensure they have solid controls and processes in place to properly manage and secure the infrastructure. Ideally, the vendor regularly submits to some form of recognized audit, such as a SOC 2 Type 2 or ISO-27001. This helps ensure controls and processes are in place in areas such as security, availability, confidentiality, privacy and processing integrity to address the aforementioned risks in the area of the hosting platform the vendor is responsible for.
Formal SDLC: The vendor should follow a documented software development life cycle (SDLC) and change management process used for the development of their low-code tool. A good SDLC process includes using a source code management system, dependency checking process, static code analysis, automated unit and regression tests, peer code review, secure coding practices training, application vulnerability scanning, quality assurance testing process and third-party penetration testing.
Policies and Processes: Documented policies and processes covering information security, business continuity, disaster recovery, security incident handling, infrastructure hardening and more should be in place at the vendor. This helps demonstrate that the vendor is committed to providing a secure, highly available and high-quality offering.
The company adopting the low-code tool itself should also consider internal processes and how it’s using the low-code tools. Items to consider include:
Formal SDLC: Even though the company uses a low-code tool, there’s still the need to follow a formalized SDLC. It’s important for the company to emphasize and embrace secure programming practices, even for low-code developers. Low-code tools have the ability to implement customer-developed code snippets or components and it is recommended companies follow programming standards and secure programming practices as outlined by the Open Web Application Security Project (OWASP) foundation. Another area of emphasis that can sometimes be overlooked is the need for testing, including functional and security-oriented testing.
Security Testing: Consider performing a penetration test of the completed low-code application. While ideally, the vendor has performed these tests on the tools itself, it’s a good idea to also perform one on the completed low-code application.
Access Control and Authentication: Configure access and permissions according to the least privilege model. Leverage advanced authentication mechanisms like multifactor authentication and single sign-on where possible. Ensure an access removal process is in place to remove access for terminated employees.
Data Security: Verify the application is configured to use HTTPS and that all databases are encrypted. Low-code vendors may or may not provide a database, and either way, the company likely has some level of responsibility for securing the data, regardless of who is hosting it.
Policies and Processes: Documented policies, processes and related training for team members helps mitigate risk. Some level of formality is recommended for documentation and training for the SDLC, business continuity planning, disaster recovery and security incident handling. For example, the team responsible for the low-code application needs to know how to handle a security incident if one occurs, whether it’s due to an issue in the low-code application, the low-code tool or the hosting infrastructure.
The benefits of low-code tools far outweigh the risks of introducing these tools into your environment, but with a little effort up front, you can save a lot of headaches down the road.
It is no secret that web APIs have become increasingly important to the operation of modern businesses. According to RapidAPI’s Developer Survey and Insights report, 61% of developers used more APIs in 2020 than 2019, with 71% planning to use even more in 2021. We are no longer tied to a small number of monolithic service providers. Businesses tend to gravitate toward specialized managed services, such as billing and authentication, which are backed by APIs. Business models for new products and services are constructed based on APIs. Trust has become a necessity for APIs. APIs that perform consistently and with high quality earn trust, and those that do not are abandoned for a competitor.
Why Does Quality Matter?
If a market exists for an API, it’s a given that there will be competition. To remain competitive, APIs must build and maintain trust with their consumers; sales and marketing can only go so far. The highest quality APIs will inevitably capture the largest slice of market share. Quality isn’t a destination, either—it is a collection of goals that require continuous investment.
What Does Quality Mean for an API?
Just like the code that drives an API, the quality of an API itself is quantifiable. The following facets describe some broad categories used to measure API quality. The weight of each facet will vary depending on how business-critical the API will be when in production.
Resilient. An API is resilient when it continues to operate in the face of adverse conditions. Can an API continue to operate (even at reduced capacity) if the database is down? How does it handle network traffic spikes?
Robust. A robust API is liberal in what it accepts, but conservative in what it sends. Will it crash when presented with a poorly formatted request, or respond with instructions on how the caller can fix the problem themselves? Can the code be restructured without breaking the API contract?
Secure. API security is vital in most deployments. Are efforts made to check for OWASP Top 10 Web App security risks? Are open source vulnerabilities known and addressed in a timely manner? Are secure endpoints gated with authentication?
Discoverable. APIs that are well documented and well structured are much easier to consume and integrate with other services.
Consistent. A consistent API is one that changes without negatively impacting existing consumers. Changes are backward compatible or versioned as new features are introduced. API consumers should know far in advance if a breaking change will be coming if it cannot be avoided.
How Do I Get There?
Processes, tools and, most importantly, culture, are the key to high-quality APIs. Let’s explore how we can approach each API quality facet.
Resilient. Processes such as chaos engineering, load testing and manual quality assurance can uncover situations where an API is failing to handle unexpected situations. Deploying your API to a cloud provider with a compelling SLA instead of your own hardware and network shifts the burden of infrastructure resiliency to a service, freeing your time to build features for your customers.
Robust. A comprehensive suite of automated tests isn’t always sufficient to provide a robust API. Edge cases, unexpected code branches and other unplanned behavior may be triggered by requests that were not considered when writing the test suite. Traditional automated tests should be complimented by fuzz testing to help uncover hidden execution paths. Canary and blue-green deployments can further expose your API to the real world in a limited manner and prepare for when even more unexpected requests will hit.
Secure. API security is a moving target. It is expected that most APIs are built on layers of open source libraries and frameworks. Software composition analysis is a necessity to stay on top of zero-day vulnerabilities by identifying vulnerable dependencies as soon as they are discovered. OWASP guidance is a must-have—directing API developers to implement attack mitigation strategies such as CORS and CSRF protection. Application logic must be well tested for authorization and authentication.
Discoverable. For REST APIs, the OpenAPI initiative provides a consistent language for describing the API. Many frameworks, such as Spring Boot, can even generate OpenAPI documentation directly from your code. gRPC-based APIs offer similar benefits by providing both instructions for accessing the API and building the clients to communicate with it. Adding support for GraphQL allows developers to connect multiple APIs together with consistent tooling. Whichever direction you choose, it is vital to keep API documentation up to date and accessible.
Consistent. To be consistent, the API development process should make incompatible changes obvious. Code reviews can catch many breaking changes right at the source. API contract testing and integration testing can be used to discover API changes as part of the build. When working in a microservices environment, staging environments may alert engineers if an API change will cause problems before production.
Quality Builds Trust
According to the RapidAPI survey, 58% of executives said participating in the API economy was a top priority for their organization. The figure was even higher in certain industries such as telecommunications, where the number is 89%. Whether you are building APIs for internal use or for public consumption, your goal should be to earn the trust of API consumers. Investing in the culture, tools and processes to build quality APIs will pave the way to building and maintaining that trust.
Meghan Liese, senior director of product marketing for HashiCorp, said in both cases HashiCorp is moving to enable organizations to better secure and govern IT infrastructure-as-code provisioned using open source Terraform tools.
Version 1.0 of HashiCorp Terraform provides access to a stable application programming interface (API) that will foster interoperability and simplify future upgrades.
The Terraform Cloud service, which eliminates the need for IT teams to set up and manage a Terraform platform, adds workflows enhancements to the Terraform Cloud that include the ability to publish curated modules to a private registry, enhancements that make it easier to visualize elements of a workspace and a preview of an ability to check with third-party tools related to a Terraform run.
Overall, the goal is to make it simpler for organizations to compose, collaborate and reuse infrastructure-as-code using modules and the public and private registry options, said Liese. The public registry already has more than 5,000 modules. Terraform Cloud now offers a native workflow to publish modules from the public registry directly into an organization’s private registry.
Terraform, of course, has been widely employed since it first debuted in 2014. There have been 15 major updates prior to the release of Terraform 1.0, which is intended to provide a foundation that ensures backward compatibility between releases going forward.
In some instances, Terraform can be too much of good thing. It has considerably accelerated the rate at which IT infrastructure can be provisioned within the context of a DevOps workflow. The challenge, though, is developers often lack the security expertise required to prevent infrastructure from being misconfigured at a time when cybercriminals have become more adept at scanning for those vulnerabilities. To enable IT teams to prevent those misconfigurations, HashiCorp makes available both an enterprise edition of Terraform as well as its Terraform Cloud service. Terraform Enterprise is used by more than 1,200 enterprises, while Terraform Cloud has more than 120,000 users that execute more than 30,000 runs per day.
It’s not clear if security concerns might one day lead to a backlash against the concept of shifting more responsibility left toward developers to improve productivity. In some cases, developers are simply deploying more insecure applications faster. HashiCorp is making a case for Terraform platforms that allow centralized IT teams to exercise more control over how infrastructure is provisioned as code. The need for that approach is becoming more pronounced, as organizations not only employ Terraform to provision cloud infrastructure but also on-premises IT environments.
Regardless of how infrastructure is provisioned by developers, security of infrastructure, both inside and outside of the cloud, remains a priority as more workloads than ever are deployed. In effect, the attack surface that needs to be defended has dramatically expanded. Of course, the best security issue of all is the one that never happened because infrastructure is being provisioned right the first time and every time thereafter.




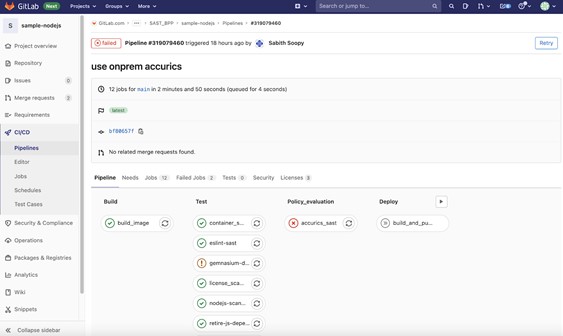 The integration with GitLab makes it easier to incorporate Terrascan into a DevOps workflow in a way that also aggregates data collected from both SAST and dynamic application security testing (DAST) tools, said Moolchandani. That approach effectively unifies what today are two separate cloud infrastructure and application development pipelines by enabling DevOps teams to employ threat scores to enforce security policies as code that are deemed too risky to deploy with block builds, he added.