Tag: github

  • Google Allies With GitHub to Secure Software Supply Chains

    Google Allies With GitHub to Secure Software Supply Chains

    Google today revealed it has been working with GitHub to create a forgery-proof method for signing source code as part of an ongoing effort to better secure software supply chains.

    Bob Callaway, technology lead for open source software supply chain security at Google, said a prototype of this method, written in the Go programming language, generates non-forgeable provenance using GitHub Actions workflows for isolation and code signing tools for authenticity provided by Sigstore. Projects that make use of GitHub runners to run jobs can now achieve the third level of security as defined by the supply chain levels for software artifacts (SLSA) framework to assure software artifacts are authentic and trustworthy, he said.

    The reusable workflow also protects against possible interference from maintainers who could otherwise try to define the workflow in a way that interferes with the builder. The only way to interact with a reusable workflow is through the input parameters it exposes to the calling workflow, which prevents maintainers from altering information via variables, steps, services and defaults.

    The goal is not only to ensure the provenance of individual software artifacts but also make it possible to identify which build system was employed to create that artifact, said Callaway. In addition to working with GitHub, Callaway added that Google expects to apply this method to securing other build systems that organizations used to construct applications.

    Overall, Callaway said, Google is also working toward embedding security functions with DevOps platforms to ensure the integrity of software supply chains, in addition to educating developers on how to build more secure software.

    To protect against the possibility of one job tampering with artifacts used by another job, Google’s method creates a trusted channel. Job outputs send hashes that are then used to verify the binary received via the untrusted artifact registry. The OpenID Connect (OIDC) protocol, which GitHub just opted to support, is then used to prove the identity of the workflow to an external service, such as Sigstore, by attaching a unique JSON web token (JWT) to each runner. The token contains verifiable information about workflow identity such as the caller repository, commit hash, trigger and the current workflow path and reference.

    That makes it possible for the workflow to prove its identity to the  Fulcio root certificate authority provided by Sigstore. Fulcio signs a short-lived certificate attesting to an ephemeral signing key generated in the runner. A record of that signing is kept in Sigstore’s transparency log Rekor. Users can then rely on the signing certificates to verify provenance in a way that is authenticated and non-forgeable. That approach means maintainers don’t need to manage or distribute cryptographic keys for signing, which until now have made it challenging to manage code signing at scale, Callaway noted.

    In the wake of a series of high-profile security breaches involving open source software, Google and others have significantly increased the resources being applied to securing both open source and proprietary software within the context of a set of DevSecOps best practices. It may be a while before the benefits of that effort are pervasively employed by developers, but it’s clear that substantial progress is being made involving everything from the tools developers use to the build systems managed by DevOps teams.

  • Researchers Find Privilege Escalation Vulnerability in GitHub Repos

    Researchers Find Privilege Escalation Vulnerability in GitHub Repos

    Legit Security today revealed that it discovered a privilege escalation vulnerability in GitHub repositories that has since been remediated.

    Liav Caspi, Legit Security CTO, said the company worked with GitHub to remediate the issue prior to disclosure. Legit Security researchers reported they found hundreds of GitHub instances rated with over 1,000 stars each that could be subject to the vulnerability.

    Caspi said the company also reached out directly to most of those affected sites, including an instance of GitHub that is used to develop the open source Nginx web server that is employed across hundreds of millions of websites.

    Cybercriminals could exploit a vulnerable build script to modify code or built artifacts that would result in software being shipped with code controlled by some other entity. The vulnerability could also enable access to sensitive secrets, such as keys, that are used to access cloud services or simply create a malicious pull request.

    Legit Security researchers employed a set of risk assessment tools that are part of a larger software-as-a-service (SaaS) platform that enables them to apply security policies across their entire software development life cycle. Earlier this year, the company made available a free Rapid Risk Assessment tool to provide organizations with more insights into their software supply chains. Security research findings, along with other security best practices, are embedded within the policies that can be enforced via the Legit Security platform.

    In the wake of a series of high-profile breaches, there is now more focus on the security of software supply chains than ever. Gartner estimated that 45% of organizations worldwide will have experienced attacks on their software supply chains by 2025, a threefold increase from 2021.

    Despite those concerns, however, the rate at which new applications are being deployed and updated doesn’t appear to be slowing. Organizations are too dependent on software to encourage customers to slow down the development and deployment rate of applications. It will, however, take years for organizations to properly train developers to correctly employ security tools within their application development processes, otherwise known as DevSecOps best practices, to reduce the number of vulnerabilities that now routinely manifest themselves in production environments. The only practical alternative is to embed more tools that automatically discover vulnerabilities in code during the application development process.

    Regardless of the DevSecOps approach, the ultimate goal remains to build more secure applications faster. That can only be achieved if there are more guardrails in place that prevent developers from inadvertently introducing vulnerabilities into an application. The more frequently applications are updated, the more likely it is that a vulnerability will be introduced. Each time those vulnerabilities are discovered after an application is deployed in a production environment, the more expensive they are to remediate. As the volume of vulnerabilities increases, it’s also only a matter of time before the sheer number of security issues that need to be addressed overwhelms both developers and security operations teams alike.

    Application security, of course, has not always received the attention it deserves, but demands for increased application security can no longer be ignored.

  • Best of 2021 – 11 Open Source DevOps Tools We Love For 2021

    Best of 2021 – 11 Open Source DevOps Tools We Love For 2021

    As we close out 2021, we at staging-devopsy.kinsta.cloud wanted to highlight the most popular articles of the year. Following is the eighth in our series of the Best of 2021.

    DevOps isn’t just a cultural shift — it requires great tools to come to fruition. Below, we’ve pulled together a list of some of the most well-loved DevOps tools available today. But, throwing loads of money into fancy SaaS solutions can quickly gobble up the cloud budget. These DevOps tools all are open source, and enable everything from container builds and orchestration to microservices networking, configuration management, CI/CD automation, full-stack monitoring and more. Here are some of our favorite open source DevOps tools for 2021.

    1. Kubernetes

    With the ubiquity of microservices and container-based software, it’s no surprise that Kubernetes tops this year’s list of open source DevOps tools. Kubernetes, adoption of which rose by 48% in 2020, is used to orchestrate containers. Instead of releasing microservices manually, Kubernetes can automate deployment, maintenance and scaling of groups of containers in production. Kubernetes, sometimes written as K8s, is hosted by the Cloud-Native Computing Foundation (CNCF).

    2. Docker

    Docker, the software, is a free and open source platform used to build, ship and run an application as a lightweight container. Containers package up the binaries, libraries, configuration files and dependencies required for a program to run. Over the past decade, containers have played a key role in agile development, and Docker containers led the revolution. At its core is the Docker Engine. Docker Hub is also an excellent resource for finding and sharing prepackaged functions as containers. Also, to plug container vulnerabilities, it may be helpful to use open source container auditing tools like Docker Bench or Anchore.

    3. Istio

    Microservices are a handy development style, yet they bring new development and architecture concerns. Namely, how do we apply networking policies like security, encryption, observability and telemetry elements consistently across all our services? Well, service mesh is one answer. Service mesh places a sidecar proxy next to each container and abstracts these networking capabilities to a control plane. Istio is one such open source service mesh that has seen widespread adoption. Istio is built on Envoy, opening it up to plugins and extensibility options. We should also mention Linkerd and Kuma as viable open source service mesh alternatives.

    4. GitHub Actions

    GitHub is arguably the most popular source control and software collaboration platform on the planet. The GitHub platform itself, based on Git, has seen some significant updates in the past few years. Most notable is the GitHub Actions capability. GitHub Actions enable software packages hosted on GitHub to accept inputs and trigger other processes. This could help automate some cool DevOps workflows within GitHub, such as code reviews, branch management or CI/CD processes — the combinations of possibilities here are endless. GitHub Actions are, essentially, YAML files hosted in GitHub repositories that leverage GitHub webhooks. Though this is more of a feature than an open-source tool, we feel it’s important to include here. Actions is free for public repositories with a limit of 100 actions.

    5. Jenkins

    A big part of the DevOps philosophy is finding ways to automate and deploy new iterations more efficiently. Part of this goal is creating a streamlined continuous integration and continuous delivery (CI/CD) pipeline. Jenkins is an open source automation server with hundreds of plugins to automate the building, deployment and testing of software projects. Although GitHub Actions could theoretically replace a CI server in the future, CI tools like Jenkins, CircleCI, TravisCI and GitLab Community Edition still are preferred by many DevOps teams.

    6. Prometheus

    Metrics and alerting systems are crucial for site reliability engineers to visualize applications and react to issues. Prometheus, a graduated CNCF project, is a well-loved open source monitoring solution. A Prometheus server collects time-series metrics by scraping HTTP endpoints and generates a system to interact with this data, offering deep querying, visualization, storage and other capabilities. Check out this Awesome Prometheus list for Prometheus introductions and additional resources.

    7. Ansible

    Ansible is all about automation. Ansible, an open source project sponsored by Red Hat, can be used to automate things like cloud provisioning, networking, deployment, configuration management and other tasks. Ansible has a simple yet effective architecture that is relatively easy to assemble — all you need is a text editor and command line. You describe your infrastructure in a text document and organize your desired states in a playbook. For an example in practice, see how OpenIO uses Ansible. “Ansible is our standard tool not only to deploy the OpenIO core, but also our WebUI, OIO-FS and all upcoming options,” writes Cédric Delgehier, Ops at OpenIO.

    8. Chef

    Chef is another infrastructure-as-code (IaC) solution for automating your configuration management. Chef uses Ruby to automate server configurations and works well with all major cloud service providers (CSPs). This can be very useful when creating and provisioning large quantities of machines. Like other automation tools on this list, the user describes their components and their states in a declarative format. In Chef, these are known as “recipes,” which can be grouped together into “cookbooks.” You can’t diss Chef for not being on-theme!

    9. Terraform

    Terraform is another IaC tool that can be used for initiation of building, versioning and further automation using configuration files. “Terraform is a tool for building, changing and versioning infrastructure safely and efficiently,” as it is described on GitHub. Terraform follows an “execution plan” that a user creates with high-level syntax. One unique aspect of Terraform is its emphasis on versioning — this allows you to version the blueprint of your service just as you would your software.

    10. JAMStack

    As I’ve covered before, JAMStack combines JavaScript, APIs and markdown for constructing web-based applications. While more of a “headless development” methodology than a single open source tool, JAMStack projects are often built using open source components. For example, JAMStack often leverages open source headless content management systems such as Ghost, Strapi and/or Netlify CMS.

    11. ELK Stack

    ELK Stack is the union of three open source projects maintained by Elastic: Elasticsearch, Logstash and Kibana. With these three components, developers can take in and log data from any source and create helpful visualizations. This centralized logging is enabled with a NoSQL database for storage with Elasticsearch, processing and data collection with Logstash and visualization with Kibana. Increased visibility is vital for data analysis and helps identify errors to reduce mean time to recovery (MTTR).

    Rounding Out The DevOps Toolchain for 2021

    Programming isn’t only about shipping quality code, it’s about efficient execution. This drive to improve operations across the board is truly putting Ops into everything. With awesome open source DevOps tooling, it means more and more architects can adopt a DevOps approach within their deployment models.

    DevOps as a practice, as well as its underlying technology, is always evolving. In 2021, a lot of effort is being placed on wrangling the effects of introducing a microservices development style. We’ve noticed the maturation of container orchestrators and service mesh, as a result. Blueprinting infrastructure-as-code and creating automated, repeatable configurations is another must-have for implementing automated build and release pipelines. Not to mention, many no-code and low-code platforms are opening up DevOps capabilities to non-programmers, albeit from a proprietary perspective.

    It’s also helpful to note that some popular open source DevOps tools have been acquired — like Docker and Chef — blurring the lines between their business and their open source roots. When it comes to open source tools, it’s a good practice to adopt vendor-neutral tools with solid community support representing diverse stakeholders. This will help future-proof your project. Even though open source is “free,” users must ensure the benefits outweigh the time-to-onboard as well as the operational overhead of self-hosting.

    DevOps tools are beneficial to automate software deployment. Here, we’ve attempted to list some of the most exciting tools to help automate that process. Of course, many new tools are emerging in the DevOps space, and we have hardly scratched the surface. Do you have a favorite DevOps tool that’s not mentioned above? Let us know in the comments below!

  • Why Do You Need GitHub Backup?

    Why Do You Need GitHub Backup?

    You’ve probably heard the joke that there are two types of people in IT: Those who do backups and those who will start. Though it’s still valid, this joke has become less relevant to businesses and professionals. The IT industry has been increasing expenditures on security for years, and backup is a critical area. However, despite the growing awareness of the need for backups and the wide availability of modern backup solutions, the problem still exists. The number of security breaches is growing, and the topic of data security looks like an endless arms race. So what can organizations do?

    First, let’s analyze some data and trends. Year over year, the number of cyberattacks, especially ransomware, is increasing. The year 2020 saw attacks intensifying due to the pandemic and the sudden shift to remote work, for which, unfortunately, not everyone was prepared. Once organizations got better at enabling effective work-from-home models, the hope was that everything could settle into a new normal. Unfortunately, the new norm became these increased attacks.

    It’s a bit like the metaphysical yin and yang—two opposing but complementary forces. One drives the other. Suffice it to say that the estimated cost of the global damage caused by ransomware in 2021 is as high as $20B! And a ransomware attack occurs, on average, every 11 seconds around the world.

    According to an Identity Theft Resource Center (ITRC) report, by the end of September 2021, there were more incidents of this type than during all of 2020. The authors of the report emphasized that they found 26 cases where cloud databases were unsecured. As a result, hackers were able to access confidential data belonging to 99 million people.

    Git Threats: Are my Bitbucket/GitLab/GitHub Repositories Secure? 

    Back in May 2019, ransomware attacks impacted hundreds of repositories on GitHub, GitLab and Bitbucket. The attack wiped away all the data and left only one piece of information: The amount of ransom demanded and a method of payment. Eventually, most of the data was recovered but the cost and the amount of time spent recovering from the attack was enormous.

    According to the Cisco Benchmark Study, approximately 40% of companies experienced downtime longer than eight hours due to a major failure. And 39% reported that at least half of their systems had been affected by a serious breach. According to IBM, the total average cost of a data protection breach on a global basis is as much as $3.86M, and the highest ransom demanded by cybercriminals in 2020 was $15 million. These numbers are scary. On the other hand, in most cases of successful ransomware attacks, the ransom is ultimately not paid; even if organizations do not pay the ransom, the mere fact that they fell victim and experienced failure or downtime can be very expensive.

    GitHub as Backup Tool

    GitHub provides many useful security tools. However, we must be aware of two things: What does GitHub backup really mean and what are its features? And what responsibility do cloud services providers have versus users’ responsibility for security? Let’s start with the latter.

    Most cloud service providers (including Amazon, Microsoft, Google, IBM, Salesforce, GitHub or Atlassian) operate on the basis of the so-called shared responsibility model. Users of cloud services most often assume that providers are fully responsible for their protection. However, providers are primarily responsible only for ensuring the security and availability of infrastructure, software and access, period. Users are responsible for the security of the business data stored as part of these services. So users themselves have to take care of backup and disaster recovery plans and solutions. In short: Providers are responsible for the security of the cloud itself and users are responsible for data security in the cloud. And at this point, it is worth pointing out that, according to data from the UK’s CybSafe, in 2019, 90% of data breaches were caused by user error.

    It can happen to any of us—a ransomware attack, phishing, loss of access to a GitHub account or an entire computer or simply overwriting another developer’s work in a repository. It affects both individual users and large corporations. In July of 2019, Ubuntu Security reported that the credentials for a company-owned GitHub account were compromised. Hackers used these compromised credentials to create repositories, issues, pull requests, etc. The attack did not cause a major crash, but repairing the damage took some work and restoring some repositories or issue trackers to the previous state was difficult.

    There are some common features any good backup should have:

    • Automation (i.e. daily backups)
    • AES encryption with its own encryption key
    • Versioning
    • Long-term data retention
    • Disaster recovery process
    • Easy monitoring (audit logs, email notifications)
    • Central management
    • Multi-tenancy (to manage admins, privileges and roles)
    • Scalability

    Based on these criteria, GitHub (and other similar hosting services) cannot be considered a proper backup tool. GitHub is a great open source project, but its purpose is completely different.

    How to Back Up Manually

    Since the cloud service itself is not enough, how can you take care of GitHub backup? Well, you could do it on your own. And often, especially in small businesses, this is the preferred method. It may seem like a good idea at first. Knowing Git well, we can create appropriate scripts that create backups for us that give us full control over what is happening without having to pay anyone for it. But this is very risk and not profitable in the long run. Disk space costs money; our employees’ time to create scripts and perform the backup is another cost. And the most important thing, in this case, is that these scripts must be maintained and updated all the time, so they constantly generate additional costs. Any change in such a script may cause an error and, as a result, deprive an organization of a working backup. Of course you could also create an appropriate mechanism to test it, but that’s an additional cost. Manual GitHub backups do not end with writing a single script.

    I’ve experienced this myself. In one project, backups were generated using such a script and then kept on our own servers. It was cheaper this way. But we did not have any validation of the created backup. One day, while updating the backup scripts, we did a manual test and it turned out that we had a serious problem—the backup was created correctly but its name did not change, so we kept overwriting the same archive constantly! The effect? It turned out that we didn’t have any copies older than one month! Luckily for us, they weren’t needed because the systems and databases were working properly at that time and there weren’t any incidents, but it makes me cringe just thinking about “What if …?”

    All in all, manually writing backup scripts is not a very good idea for many reasons. The low cost of this solution is only theoretical; with time, the cost of maintaining this mechanism increases and, in practice, often only one or two people are responsible for it, which creates additional risk. Okay, you might have more control, but overall you are wasting time and money. The backup itself is also not enough, because you need a proper restoration solution for systems or data in the event of an incident. There’s also the question of how to create a backup of the script that creates the backup? Are you sure you cannot make better use of your employees’ working time?

    How Much Does it Cost?

    It is difficult to accurately measure this; it all depends on the level of complexity of systems, the number of repositories, the skills of your team, etc. However, you can estimate how much the lack of access to services or programmers’ downtime will cost. You can also calculate the development and maintenance costs of writing, testing, maintaining and updating your own backup scripts. The history of GitHub attacks and crashes shows that the data is usually recoverable, which is good news. On the other hand, the time when services are unavailable or when teams are unable to work can be very costly.

    Third-Party GitHub Backup Tools

    Another solution—and, in my opinion, a better one—is to use third-party backup software.

    In fact, in the GitHub documentation, it is recommended:

     “Backing up a repository: You can use the API or a third-party tool to back up your repository.”

    If you can use the GitHub API, why do you need a third-party GitHub backup tool? Well, first of all, such applications are created by experts in a given field who have knowledge, experience and stay up-to-date on the current security trends. Second, these solutions are ready and available right away; you don’t have to spend time and money reinventing the wheel. Yes, there is a cost, but in the long run (taking into account the factors described earlier) the cost usually turns out to be much lower than a bespoke solution. Outsourcing backup management responsibilities may be incredibly beneficial and will allow us to focus on developing our business instead of managing GitHub repository backup all over again.

    When it comes to backup, be smart. If external third-party tools allow us to develop our products faster and more efficiently, then we should not hesitate to use them. And never forget to implement proper backups and disaster recovery plans. Taking care of it today will help ensure a more secure future.

  • WTH? We Wanna WFH | DoD Dual-Sources JWCC | More Nvidia ARM Woes

    WTH? We Wanna WFH | DoD Dual-Sources JWCC | More Nvidia ARM Woes

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Working from home is de rigueur, JEDI redux, and more about Nvidia/Arm.

    Survey Says: Devs Stay Out of Office

    First up this week: GitHub’s annual survey of developers has some fascinating data on the workplace (ahem) “new normal.” The pandemic has radically changed devs’ expectations of where they can do their jobs.

    Analysis: WFH is SOP

    As with other roles, Dev people want to continue to work from home. But does this pose a threat to your DevOps culture? Make sure you can do Ops with equal flexibility.

    Paul Krill: Dev productivity is back to pre-pandemic levels

    GitHub’s “2021 State of the Octoverse” research … sees signs that work rhythm is returning to pre-pandemic levels. GitHub also found that 46 percent of developers who worked co-located with teammates now expect to work fully remotely or in a hybrid environment.
    …
    Based on data culled from more than four million repositories and surveys of more than 12,000 developers … JavaScript and Python remain the top languages, followed by Java and TypeScript. [And] GitHub found that development team performance can increase as much as 87 percent when reusing code and as much as 43 percent when using … CI/CD.


    Zeroing in on the WFH angle, it’s Richard Speed:

    Respondents who were in the office either full or part-time dropped from 42 percent before the pandemic to a mere 10.7 percent now. … That’s a lot of empty desks.
    …
    Fans of the ctrl-c, ctrl-v combo will be delighted to note that GitHub found that when code reuse was made “frictionless” at work, developer’s performance increased by up to 87 percent. … It’s all splendid stuff.


    But beware of statistical fallacies, thinks Henrik Ingo—@h_ingo:

    #WorkFromHome may have been more common than anyone realized. [But] is the population of GitHub users/respondents somehow skewed toward pioneers/early adopters? … This might be a case of correlation is not causation.


    Defense Dept. Orders New Clouds

    The DoD issued its latest cloud contract opportunity notice, with the snappy title of “Joint Warfighting Cloud Capability” (JWCC). Reading between the lines of the notice, it all sounds very DevOps-cum-Agile.

    The Pentagon has backed away from its previous insistence on a single supplier, and now wants at least two cloud providers.

    Analysis: JEDI redux, because AWS wants a do-over

    JWCC is the follow-on from the aborted JEDI procurement. Amazon Web Services was “disappointed” to have been passed over in favor of Microsoft. Now it appears the DoD wants them to share.

    What can you learn from such a multi-vendor DevOps strategy?

    Jordan Novet: Pentagon asks Amazon, Google, Microsoft and Oracle for bids

    Amazon and Microsoft were the finalists for a single Joint Enterprise Defense Infrastructure. … Microsoft won it in 2019, Amazon filed a protest and the Pentagon canceled the contract in July.
    …
    The new effort [is] known as Joint Warfighting Cloud Capability. … JWCC differs from JEDI because it allows the Pentagon to rely on multiple cloud providers.
    …
    The U.S. General Services Administration … said only two U.S. cloud infrastructure providers, Amazon and Microsoft, appear able to comply with all of the Pentagon’s requirements. … The value of the new contracts is not known, but the Defense Department estimates it could run into the multiple billions of dollars.


    In summary, heed this Anonymous Coward:

    Competing suppliers will try harder than one non-competing supplier. The DoD has had a lot of problems with One-Ring-to-rule-them-all systems like the F-35. … JEDI would have been the same.
    …
    Smaller steps with upgrades while testing/using offers better returns. Done right they can get a better deal by making the companies compete against each other in making sure the products are actually useful.


    But look carefully at the DoD contract opportunity, says bustinbrains:

    They’ll all get contracts. Then DoD will simply use the one that they actually like the best. No one can complain because it’s open-ended with no guarantees.


    Arm/Nvidia Deal on FTC’s Radar

    Last week, we talked about Nvidia’s goal to acquire Arm Ltd from SoftBank, and the regulatory challenges it poses—notably in the UK, home of the chip architect. After we went to press, the other shoe dropped.

    Analysis: Just Give Up Already

    As we said last week, Nvidia can’t be allowed to do this. Not only are ARM chips found in 99% of smartphones, but they’re an increasing fixture in the datacenter—especially places that value “performance per Watt.”

    Richard Waters: What’s next for the tumultuous takeover of Arm?

    Nvidia’s acquisition of UK chip design company Arm from SoftBank has provoked serious opposition on both sides of the Atlantic. … The US Federal Trade Commission had its own worries. China, meanwhile, is waiting in the wings.
    …
    The deal has shone a spotlight on the unique position Arm plays in the chip industry. [Nvidia] offered a guarantee that it won’t block any other companies from licensing Arm’s designs. The offer has fallen on deaf ears, with both the EU and UK ruling it inadequate. … Post-Brexit politics have also come into play.
    …
    At what point might Nvidia and SoftBank call it a day? … A stock market listing [is] the most likely alternative, with the UK a favoured venue.


    How’s it viewed from the inside? Here’s a hint from fivemack:

    I was at ARM when Softbank bought them; it came as a surprise to everybody, because we were absolutely confident that we were unbuyable because anyone interested in us would want to use differential licensing as a weapon against their competitors, and we … were confident that regulators wouldn’t accept that.
    …
    Lots of people went home with a year’s pay check in free money. And not a few people … went home with a decade’s pay check in free money.


    More and more DevOps workloads are running on ARM silicon. Here’s Biophoton:

    The low power expertise of ARM has to be an advantage in the data centre (DC) market. … Plus Linux is available on ARM so architectural lock-in of Intel could be eroded in the DC market.


    The Moral of the Story: You are known by the company you keep


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk.

    Image: Lukas Mann (via Unsplash)

  • GitHub Expands Developer Productivity Tools Portfolio

    GitHub Expands Developer Productivity Tools Portfolio

    During the online GitHub Universe 2021 conference, GitHub today unveiled a bevy of updates intended to boost developer productivity by making it easier for developers to write code faster and collaborate more easily.

    The GitHub Copilot tool that GitHub developed in collaboration with OpenAI, a research and development lab, to help developers write better code faster is being extended via a technical preview to add support for Java and the integrated development environment (IDE) JetBrains.

    In addition, the Codespaces tools that GitHib makes available to pre-configure development environments is being extended to include support for devcontainer feature composition, the GitHub command line interface (CLI) and REST application programming interfaces (APIs) along with additional access controls.

    GitHub Actions has also been updated to add support for deployments using the OpenID Connect standard in addition to providing access to deployment environments to simplify approvals, improvements to reusable workflows and auto-scaling functionality for self-hosted runners.

    There is also now a Command palette tool in beta to help developers navigate GitHub along with a public beta of a GitHub Issues tool that makes it simpler for developers to filter, sort and group issues and pull requests. Additional features that have been added since GitHub Issues was first previewed include iteration support, reporting and data visualization tools and the ability to employ it across public projects.

    Finally, GitHub is adding, in beta, support for Ruby as a programming language that CodeQL analysis engine can now scan for vulnerabilities along with the ability to customize permissions for accessing GitHub Enterprise Cloud.

    Ryan Salva, vice president of product management for GitHub, said collectively GitHub is committed to making developers more productive by, for example, autocompleting code as developers write. Support for additional programming languages will also be forthcoming in the months ahead. The goal is not to leverage AI to replace developers but, rather, eliminate the drudgery that gets in the way of developers becoming more creative, noted Salva.

    There won’t come a day any time soon when developers won’t have to type to write code, but it is possible to leverage AI to provide a type-ahead capability that reduces coding errors, added Salva.

    The goal should be to enable developers to create more application experiences at a time when more organizations than ever are consuming applications that drive a wide range of digital business process transformation initiatives, said Salva.

    As part of that effort, Salva noted it’s also critical to reduce the amount of friction developers encounter writing code starting with setting up the development environment itself.

    It’s not clear yet what impact all the focus on developer productivity and collaboration will have on the rate at which applications are being built and deployed. However, as developers become more productive, the number of application development projects that can be launched simultaneously should increase. In fact, there may come a day when applications are being built faster than organizations can deploy them without adopting continuous delivery best practices that rely on higher levels of automation to install software.

    Regardless of that application delivery challenge, however, it’s a problem most organizations right now would consider themselves fortunate to have.

  • GitHub Updates CLI to Make Creating Extensions Easier

    GitHub Updates CLI to Make Creating Extensions Easier

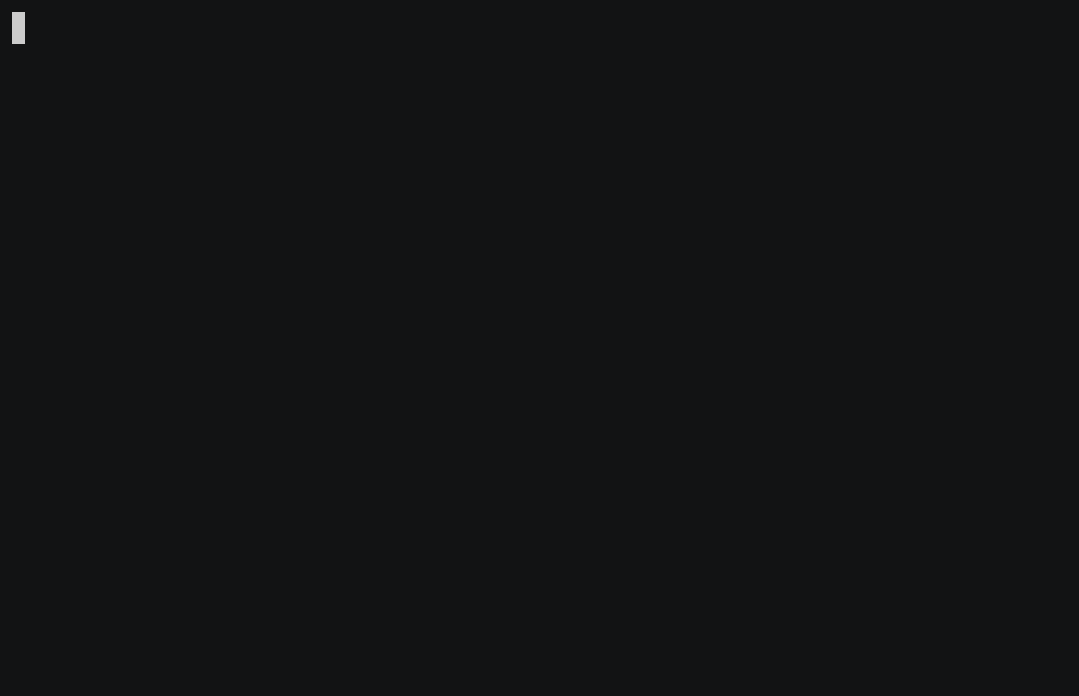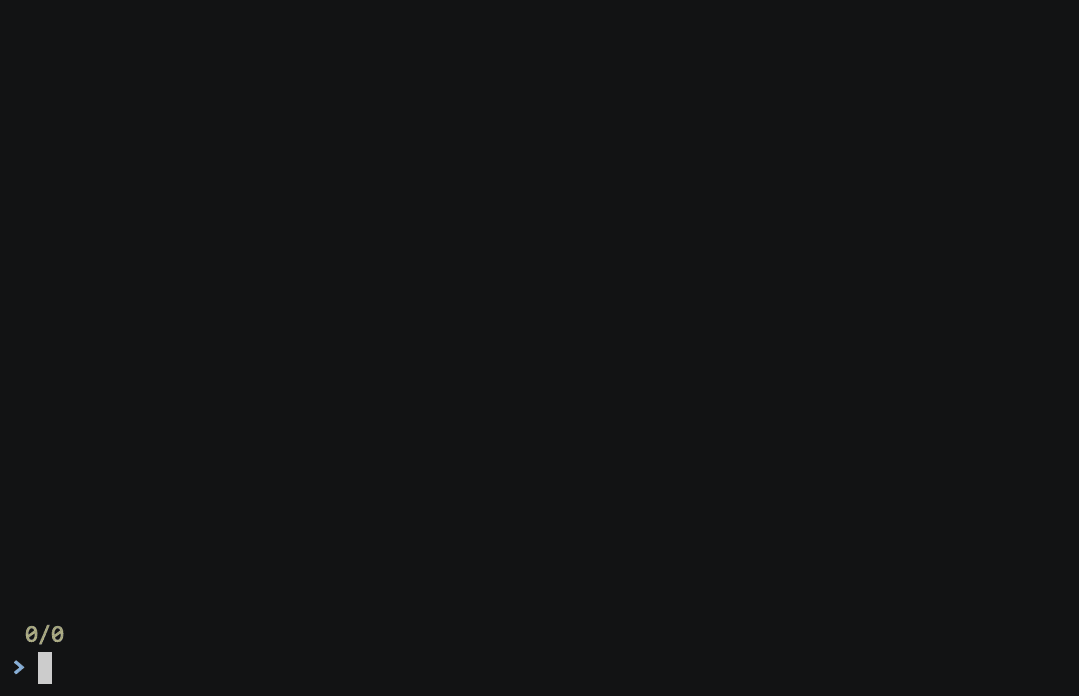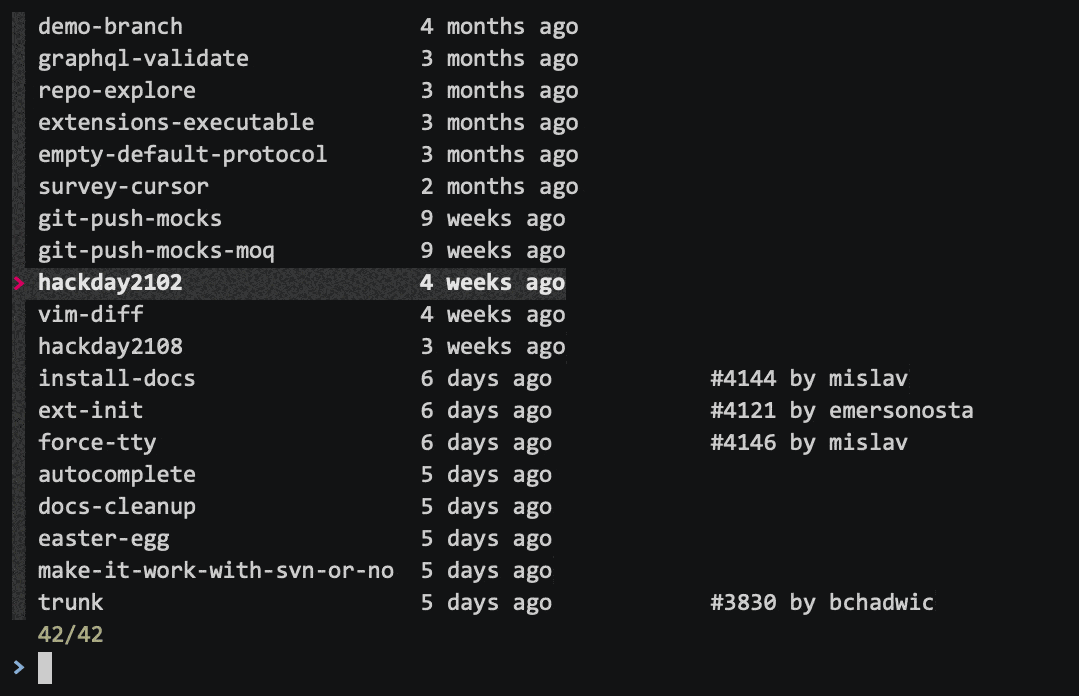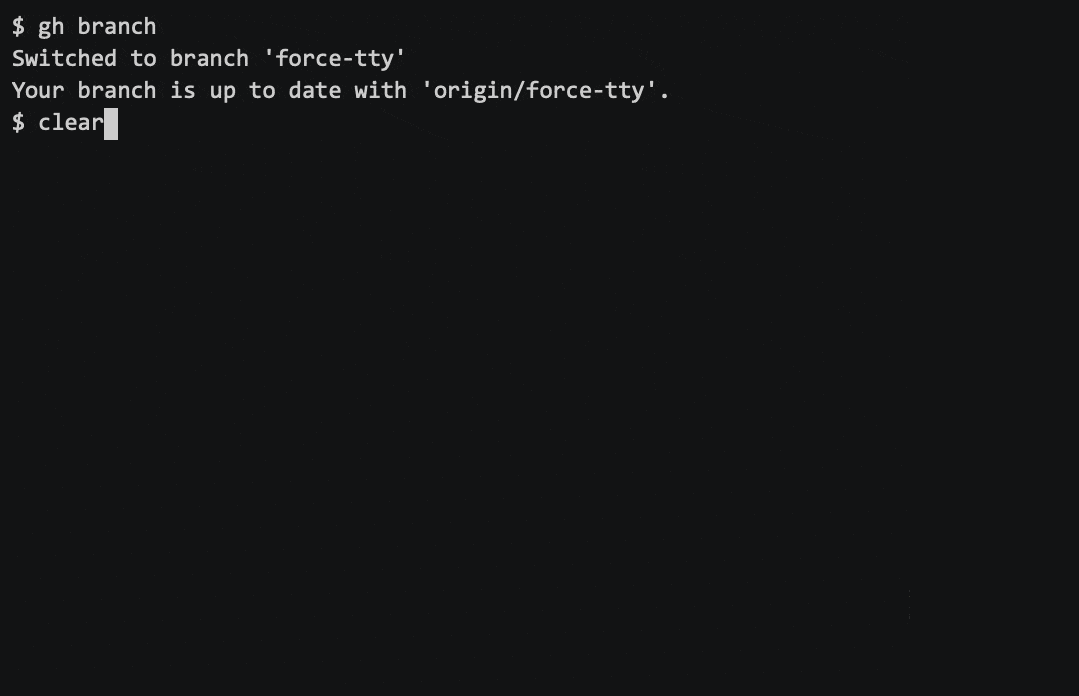
    GitHub this week made available an update to its command-line interface (CLI) that enables DevOps teams to add extensions to workflows.

    Billy Griffin, director of engineering for GitHub, said the company’s initial focus was providing DevOps teams with a set of workflows that could be invoked easily via a CLI. Now GitHub is encouraging developers to extend those workflows using version 2.0 of its CLI that hopefully will be shared with the larger community, he added.

    For example, extensions have already been created that order branches by how recently they were created and then display all associated pull requests.

    At the other end of the spectrum, developers are creating simple screensaver extensions for their own amusement.

    The level of interest in extensions varies widely across DevOps teams. Many of them simply want to employ an opinionated workflow that has been created on their behalf. Other DevOps teams want to be able to make modest modifications. Others prefer to customize workflows as much as possible to fit their specific purposes. Version 2.0 of the CLI provided by GitHub enables each DevOps team to decide how much to modify their workflows. However, as a DevOps team gains more experience, increasingly they tend to want to customize workflows.

    The number of workflows being created around the GitHub repository continues to increase steadily as more organizations embrace best GitOps practices. GitHub is the most widely employed repository for managing software artifacts, and the level of sophistication of workflows built using either scripts or GitHub actions is increasing steadily. Much of that effort is focused on streamlining processes that otherwise would get in the way of enabling developers to spend more time writing code.

    Of course, the pressure on developers to write more code faster has never been greater. As organizations embrace digital business transformation, they are discovering how dependent they are on software to create customer experiences that drive revenue. The challenge comes at a time when many developers are working from home to help combat the spread of the COVID-19 pandemic and many existing workflows need to be re-engineered. At the same time, development teams are becoming more distributed as organizations become more comfortable with hiring developers anywhere in the world.

    It’s not clear to what degree the changing application development landscape might drive organizations to re-evaluate what platforms they are employing to drive DevOps processes. Many on-premises development platforms have been replaced by cloud-based alternatives in the past year. However, because necessity is the mother of invention, the workflows relied on prior to the pandemic are not only now forever changed, but they will also likely be altered again as development teams work more intermittently in-office and from home once the pandemic subsides.

    Regardless of how those workflows evolve, the single-valued DevOps attribute is going to be flexibility. The challenge now is determining which platform does the most to enable that flexibility at a time when uncertainty continues to prevail.

  • Google Unveils Tool to Better Secure GitHub Repos

    Google Unveils Tool to Better Secure GitHub Repos

    Google today launched a GitHub app that provides automated continuous enforcement of security best practices for GitHub projects.

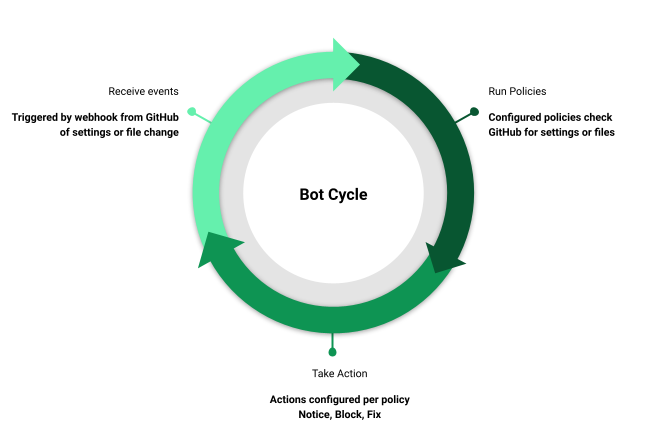
    Kim Lewandowski, a product manager for open source software security at Google, said the Allstar application enables IT teams to assess any project on GitHub to check for security policy adherence. In addition, Allstar sets desired enforcement actions and automatically applies those rules when triggered by a setting or file change in a repository.

    The goal is to provide the open source community with a tool that makes it possible for organizations to have more confidence in the open source software that is being employed within a software supply chain, said Lewandowski.

    Allstar is intended as a companion application for Security Scorecards, a tool that Google made available last year to assess whether, for example, an open source project employs branch protection to ensure that malware isn’t inadvertently committed to a project. Allstar continuously checks expected GitHub API states and repository file contents against security policies and the enforcement actions defined by an IT organization. After it detects a policy violation, the tool can be configured to simply send an alert or to automatically enforce a specific policy to remediate the issue, said Lewandoski. Specifically, she said the options available are to log the security policy violation without taking any additional action, open a GitHub issue or modify the GitHub setting to match the original Allstar configuration.

    At present, Allstar provides a limited number of security policy checks, but more will be made available over the coming months, said Lewandowski. Current security policy checks include branch protection, vulnerability disclosures, access controls and detection of binary artifacts that can’t be scanned. Additional checks that will be added include automatic dependency updates and frozen dependencies.

    Lewandowksi said Allstar and Security Scorecards are part of an ongoing Google effort to give back to the open source community that is being targeted by cybercriminals attempting to compromise software supply chains. Just about every application is now dependent on open source components, to some degree. The maintainers of those projects, however, don’t always have the tools or expertise required to check for malware that has been injected into a codebase, she noted.

    In general, Lewandoski noted that achieving DevSecOps best practices will require a lot more automation of application security. It’s not possible for each developer to become a world-class cybersecurity expert. The challenge is finding a way to introduce that automation into the application development process as early as possible, which, she noted, in many cases starts with open source components that are incorporated in applications.

    It may take a while for every maintainer of an open source project to revamp the processes through which code is added to their project. However, the easier it becomes to continuously review that software, the more confidence organizations that use it will have in its security. In fact, the maintainers of those projects should expect the downstream users of that software to be asking some pointed questions about how security is being managed in the wake of a series of recent high-profile breaches of software supply chains.

  • EP 11: Unburdening Developers

    EP 11: Unburdening Developers

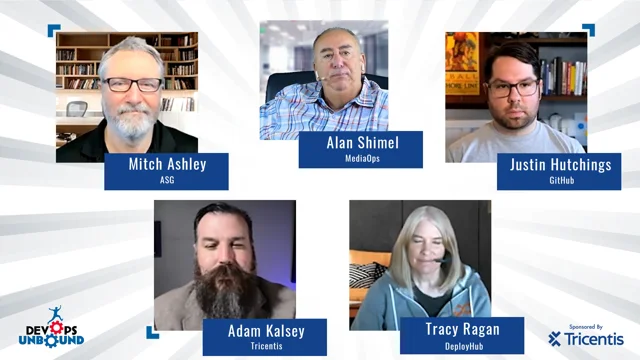
    Every app development need seems to ultimately fall to developers to fulfill. Build in security. Shift testing left. Provide users cooler, more customized experiences at cloud speed and scale. And do it all faster, of course. How do we accommodate the rising expectations without burning out developers? What can other team members do to lighten the load and allow developers to focus on the creative work they require to thrive? In this episode of DevOps Unbound, hosts Alan Shimel and Mitchell Ashley are joined by panelists Adam Kalsey of Tricentis, Tracy Ragan of DeployHub and Justin Hutchings of GitHub to talk about unburdening developers. The video is below, followed by the transcript.

    Alan Shimel: Hey, everyone. Welcome to another episode of “DevOps Unbound,” sponsored by our friends at Tricentis. We have a good, nice topic I want to talk to today, and you know, I refer to it as the straw on the camel’s back, but it’s about the ever-increasing load that developers seem to be taking on with technologies and frameworks such as DevOps and Agile and so forth that we’re seeing out here. And we’ve got a great panel to explore this. Let me introduce you to them before we go any further.

    Let me first of all introduce you to my friend Justin Hutchings. Justin is with GitHub and he’s gonna tell you a little bit about himself. Justin, welcome.

    Justin Hutchings: Thanks, Alan. Yeah, I’m Justin Hutchings. I’m a director of product here at GitHub. I work on some of our security features for developers, you know, whether that’s things like static analysis, security testing, or supply chain kind of features for developers in opensource and the enterprise. Glad to be here.

    Shimel: Nice to have you here, Justin. Welcome. Secondly, she’s a frequent guest here on “DevOps Unbound” and other MediaOps videos, my friend Tracy Ragan, CEO of DeployHub. Tracy, welcome, maybe a little bit about DeployHub and you for the audience.

    Tracy Ragan: Absolutely. Thank you, Alan, and thank you, Tricentis, for having these and always welcoming me on these panels. I like doing them. So yeah, I’m Tracy Ragan, CEO of DeployHub. DeployHub is a hub of metadata for deploying and configuring microservices. So we do automated configuration management so you know what your blast radius looks like for a microservice before you deploy. I’m also on the board of the CD Foundation, and you might see me oftentimes evangelizing around microservice usage.

    Shimel: Yes, we do. And then – welcome, Tracy. And then last but not least as a panel member today is Adam Kalsey. Is that pronounced right, Adam?

    Adam Kalsey: It is, absolutely, yes.

    Shimel: And Adam’s with Tricentis, but why don’t you tell us a little bit, Adam?

    Kalsey: Yeah, so I lead developer relations at Tricentis, and we make software to help people make better software, to test it and make sure they have higher-quality software. And my role is to help make developers more awesome by helping them make better software.

    Shimel: Thank you and welcome. And then last but certainly not least is my cohost for “DevOps Unbound,” Mitch Ashley, CEO of Accelerated Strategies Group, CTO here at MediaOps. Mitchell, welcome. Great to have you on.

    Mitch Ashley: Always good to be here, and having been part of many development teams, I’m excited to talk about this great topic.

    Shimel: Great. Let’s dive into it, guys. You know, when I started staging-devopsy.kinsta.cloud about eight years ago, there was this constant push and pull. Was DevOps too developer-centric? It was all about the developers, the ops said. This DevOps thing is just – it’s all about the developers; we’re not getting our fair share. And you spoke to developers and it was, “You know what? DevOps is too ops-centric. It’s not about the ops. It can’t be everything ops. It’s got to be about developers.” And so there was this, you know, friction about was it too developer-centric or not.

    Over the years, though, what I’ve seen is an increasing amount of responsibility seems to have shifted left, as we say, right? And we shift left, and when we shift it left, we’re primarily – we’re shifting it to the developers. So things like testing, for instance, right, have become – developers are probably more involved in testing, or at least kicking off testing and this stuff, than they ever were. Security – certainly the whole rise of the DevSecOps movement has been about shifting security left, and in fact many of the most successful security companies in the DevSecOps space have become successful by making security tools for developers. We’re making testing tools for developers. We’re making tools to look at your blast radius for microservices for developers. Developers are deploying, right, as part of their DevOps focus.

    When is enough? When do we break the developers’ back? Not to mention the developers are the highest-paid people in the food chain, right? So by giving them everything, are we giving them nothing, right? Are we stunting their productivity? Adam, being that you’re the new guy here and you actually are in charge of developer relations at Tricentis, we’re gonna ask you to kick it off. Are we putting too much on the backs of our developers?

    Kalsey: I don’t think so. I think that the promise here is that we make things easier for the developers. I mean, sure, you have more tasks. There’s more things that you’re responsible for. But the overall effort and the amount of work that has to be done ends up shrinking. If you don’t find out about a bug in your software or a security problem or such until you’re in production and customers are using it, now all of a sudden you’ve got way more work to do. It’s harder. It’s more expensive. It’s more difficult. There’s more involved in doing that. And so by moving a lot of these things forward, we’re letting the developers be more proactive in taking care of them. We’re helping them get things fixed sooner. We’re reducing the amount of toil that developers have to do. Yes, there’s more upfront work, but that long-term toil starts to fade away and disappear.

    Shimel: Fair enough. I don’t know if you – you know, I don’t know if I’ve ever heard someone say developers are – you know, it’s making it easier or less for them. Justin, what do you think?

    Hutchings: You know, I’ve talked to a lot of companies that are the early stages of their DevOps transformation, and I think one of the most common mistakes that these companies make is they fail to recognize that adopting DevOps requires both technical changes as well as cultural changes. You can’t just get rid of the testers and say engineering owns tests and expect the same velocity. You’ve got to build out the infrastructure to support that, you have to do the training, and you also have to recognize your throughput is going to be less while you’re paying down that sort of debt on getting that infrastructure and getting the automation and getting all of those things.

    Companies that fail at the DevOps transformation, they go through sort of the motions without understanding the culture and talking about it. You know, years ago when I worked at Microsoft, the Windows team sort of famously had a one-to-one ratio between engineers and – software development engineers and test. These were folks that wrote test automation. And there was a big layoff, thousands of testers got laid off, and they said, “We don’t need them anymore. We have observability tools. This will be great.” And that was the most naïve statement I had ever heard, and it took a year for the organization to fully rebound, to figure out what the right set of responsibilities were for engineering, and how to support those folks effectively on it.

    Shimel: Fair. Tracy, in your roles, both at DeployHub and CDF, you’re dealing with both constituencies here, right, the traditional DevOps teams. But let’s face it: You’ve got dev and you’ve got ops in there, and you deal with both. What’s your take from the battlefront?

    Ragan: Oh, my goodness. I could write like a 20-page blog on this. I guess that wouldn’t be a blog. It would be a research project. [Laughter]

     Shimel: Or a book.

    [Crosstalk]

    Ragan: Yes! So I think that in my discussions with folks over the last six months, eight months, I am seeing a lot of SREs really stressed out. So I don’t know if it’s the development teams that are really taking the brunt of this, but if we think about our history and how we got here, we’ve always had somebody really important on a development team who always worked in hand with the operations side of the house to find out what happened, to help with the deployments. Even if they’re sitting there watching the operation first and hit the button, they’re the person that’s always taken this responsibility. And I think the DevOps movement was an effort to push more operations tasks to that trusted partner on the development team, and now that role has turned into an SRE.

    I would say five years ago we wouldn’t have seen this kind of stress, but because we’re going through this massive tsunami moving from monolithic to microservices, and we’re in a transition phase, we are putting a lot – what I see is we’re putting a lot more stress on the SRE role. Developers are going to the SRE, operations are going to the SRE, and the SRE is just trying to keep up with the underlying technology that’s wobbling and moving. You know, they’re trying to figure out how to stand up environments easier. They’re trying to implement Terraform or Rancher. They’re doing everything that they can right now to try to keep up, but they may be underwater for a bit longer.

    So when we think about where the stress point is right now, I think that developers have pretty much automated a lot. You know, we have tools like Tricentis to really improve the testing, but now we’re int his weird phase where we have these SREs that are trying to straddle both worlds. And they’re struggling.

    Shimel: Justin, you know, in your role there – and, guys, I don’t mean to call. If you want to say something, feel free to obviously jump on. But, Justin, I’m wondering – you know, GitHub has sort of a unique view with this.

    Hutchings: We’ve been trying to push folks towards more automation, more DevOps, you know, DevSecOps with all the security features we have. You know, again I think culture is the key. I look at anytime you have an unfunded mandate, you know, it’s gonna fail. A lot of times organizations will say we’re going to microservices or they’ll say we’re gonna adopt all these security tools, and then they don’t think about how that actually gets done and they don’t recognize the sort of pain and training and all of the things that have to happen to get folks there.

    You know, and I think there’s been a lot of advancement here. You look at the state of observability. You look at the state of CI/CD. Things are getting better, but I think, you know, we in the industry that sort of work int his space sometimes paint such a rosy picture that our customers aren’t prepared for the hardness of the journey that lies in front of them. And they’re looking at how do I get to the magical garden of DevSecOps, and the magic garden is there, but it is not a free entry, you know?

    Ashley: You know, Justin, to what you were saying, I think along with culture, part of is a role change that’s happening across the whole organization, right? A couple things are happening. We’re doing not just automation that the developers are doing, clearly SREs. Other test automation, infrastructure as code, you know, those are all development that’s happening to support those. It doesn’t say that every person is an expert developer, but there’s some development, scripting, other kinds of skills that come with it.

    So I don’t know if we’re so much loading it on the developer as much as we’re elevating our level of automation and kind of interconnected of the process, and we’re helping people evolve and growing their strengths – let’s put it that way – to also include some software development, or more closely working with people that can. I think that’s part of that cultural change, too.

    [Crosstalk]

    Kalsey: One of the things that’s actually happening there is as things become more development-centric and, oh, now it’s Toad and now it’s – the teams are making exactly the wrong lesson out of this and they’re learning the wrong thing out of it. You know, one of the things that Justin said earlier is, “Well, we got rid of all the software testers because the developers are doing the testing now,” and that’s one of the dumbest things that you can do as an organization, is say, “Well, now that my developers can do this, let’s get rid of all the experts.” And instead of saying, “What is the new role of this expert and how does their role change?” whether, okay, now they learn to code so that they can expose more of this as code, or do they become consultants to the developers and help them do this right and help them understand how to do this right? Could I remove a lot of those pieces of toil and a lot of that extra stuff from them and let them focus on the things that they’re good at – writing the code, building the code, thinking through the problems – and let me focus on the things that I’m good at – thinking about the infrastructure, designing the infrastructure, designing test plans, thinking about the non-happy path?

    And so companies – I talk to companies all the time that say, “Well, we’ve moved – all our developers are doing the testing now, so we got rid of our QA department!” And that is – that’s just frankly dumb. Don’t do that.

    Ragan: I think it was an outcome of the Agile movement, right? Because we started preaching this idea of bringing everybody into the same room together to do these tasks. So we broke up our testing departments and we spread them out across all of the teams, as well as some of the operations, which is how the SRE title came about. So, you know, first we siloed and then we tried not to silo. But ultimately it is how do you come up with a strong automation standard across the organization? And how are you gonna implement it? If there’s a testing team that has a group of people and each one is assigned to an application team, or if you have a siloed testing team and a siloed operation team, ultimately we’re still pushing the same product through the lifecycle. So how well do we do that? And maybe Agile confused things for us for a while and kind of broke things up and disrupted what we were doing. So now the task is how do we move forward with where we’re at to make it continue to be easier to get things across the pipeline?

    And I have to say that one of the biggest challenges I hear from people is that continuous integration works well; continuous delivery from dev, test, through prod doesn’t work so well.

    Hutchings: Yeah, and I think, you know, what you hit on there, Tracy, is really important because, you know, when you have an organization where the engineers are the only thing and engineers are undifferentiated and treated as some sort of fungible resource, I think things fall apart. You know, what I’ve seen in successful organizations is they have some subject matter experts, whether that’s SRE or a data team or an infra team, that are building out things that make the rest of the organization able to scale. And that’s a really good, healthy blend where you’ve got experts that you can lean on, but then engineers are empowered to do sort of the last-mile delivery there.

    Kalsey: Yeah. When a company says they’re gonna create a cross-functional team and then they eliminate most of the functions, that’s a problem. I mean, you don’t say I’m gonna have a cross-functional team, so we’re going to bring product managers and designers in and, oh, by – now we just don’t need product managers and designers. So why do we do that with operations, with testing, with all of these other things that are important for software creation? You know, eliminating those and just saying, “Well, the developers will do it,” of course that makes for a lot more work for the developer. The way that this needs to work is keep those cross-functional teams and change their role and bring them further – bring them earlier into the developer cycle. Have them involved in design. Have them involved in figuring out what the product is going to do and how it’s going to do it, not just let’s get rid of them. The options aren’t they happen at the very end of the process or we don’t have them at all. It’s let’s bring them up further along in this process.

    Shimel: You know, part of it, though – and I don’t know if anyone wants to admit it – is that there’s sort of this bias that everyone else on the IT team aspires to be a developer ’cause that is the ultimate kind of thing. So, for instance, it was this way certainly in testing, that being a tester was a waystation on the way to being a full-blown developer, right? Or maybe a developer who wasn’t that good, well, he could do testing, right, and that testing in and of itself wasn’t a “profession.” It was really just like a junior developer did testing. And, you know, security people, well, they were always the rebels, right? Half of them didn’t have formal training. But you know, operations, the SRE folks, right, how much of a developer heritage or pedigree is there in what you need to be able to do from an SRE perspective? And so when we put together these “cross-functional” teams, it’s almost with the idea that, well, you’re all gonna be developers now, right? You’re gonna reach your lifelong ambition by being in this DevOps team as part of a developer. And we lose out on the professional tester, on the professional SRE, on the professional security person, right, in this rush to all be developers. What do you think about this?

    Ashley: Well, I think we did this to ourselves in the DevOps movement. You know, I remember when I first wrote my first article on staging-devopsy.kinsta.cloud about what is DevOps and I was sort of grappling with it myself, the mantra was, “We don’t need operations, we don’t need test, we just need developers. Code or developers writing code will eat the world.” And it wasn’t outsiders that said that; we said that, or subsets of us said that. And I think we recognized after we got into it, no, as Adam points out, those are exceptional skills. Frankly some of the worst testers I’ve worked with were developers. They were terrible at testing their own stuff. They were great developers, right? But some of it is elevating maybe too much the role of the developer to be the rockstar beyond the platform, if you will – and there are fantastic developers. I don’t mean there aren’t. But there are amazing, amazing test people.

    And so let me put it to you this way. When I was running product development at StillSecure with you, who did I listen to? The testers. I listened to them and I asked them, “What problems are we finding?” and I could tell if we were ready to ship, not just by the numbers but by their opinion. And that’s why I really relied on, because they saw it from a different perspective than a developer does. So that’s my opinion about it. Now feel free to disagree. Anybody can take me on and say I’m full of baloney.

    Hutchings: So I was gonna say, Mitch, you know, have folks heard the story about – what is it – the IBM Black Team that they developed back in the ’80s for testing where they – basically testing was a sort of poorly-regarded function in the organization? And they ended up creating sort of a hit squad that famously would go and just destroy people’s code. And they created a culture around that, and they created sort of an ethos of that being a special place to work. And I think that’s something we need to find with our developers. Like, if we only celebrate the developers that make the shiny features, we’re not gonna be in a good state. We’ve got to celebrate the developers that can destroy other people’s code with tests or can build something that scales really well or that build great observability things. Like, it can’t all be how many features did you ship; it has to be how much you contributed to the whole.

    Ragan: Yeah, and I – you know, I think, Justin, that the cultural discussion is one that any team that’s going through this experience right now that we’re describing, that the developers do feel burdened in some way, they should be looking at how they have built that team. And kind of each role should be a specialist role, and they all have to be an equal role. And if you don’t have that, you really haven’t created an Agile team and that team’s not gonna become a high-performance computing team, because it is about equality on the team and the ability for every single person to stand up – tester, the SRE, the junior developer – and be able to communicate problems as they see them in an equitable way and not feel that they are being judged.

    And I have learned that from working in an opensource community. I’m really amazed how well the opensource communities work together, ’cause you have people with all kinds of different backgrounds, and it fascinates me to see how much they can accomplish and how well they accomplish it when they’re not all working for the same company and they’re there because they want to be. So how do you create that opensource kind of nurturing culture within a particular team if it’s built especially around Agile, where we’ve taken operations and testing and developers and, you know, other specialists and put them on the team – documentation, requirements gathering – and how do you make it an equal team? That I think is the challenge to keep the burden off of the developers’ backs.

    Shimel: You know, and that – paradoxically, that’s also the big attraction to like cloud-native communities, to these opensource communities, because I think people recognize the – and I don’t mean it in a bad way – the kumbaya kind of spirit that these opensource communities foster. GitHub, quite frankly, Justin, right, if you look at the history of GitHub, that’s probably been one of the huge drivers of 52 or whatever it is million accounts on GitHub, is that sense of community, right? How do you build that sense of community interdisciplinary across your teams within an organization? Adam, you know, though the role says DevRel, it’s really TeamRel, right? And you know, it’s got to be part of your mantra there, part of your job description, isn’t it?

    Kalsey: Yeah. One of the things that is interesting about when you look at opensource is the person who wrote the documentation is a hero, because nobody wanted to write the documentation. The person who wrote the tests is a hero because, wow, they’re writing the tests, and that was a lot of work and I didn’t want to do that amount of work. But then when we go into a company we say, “Well, we’re gonna hire a couple of QA people to do the testing because they’re cheaper than the developers.” And, well, yeah, maybe if you’re hiring bad QA people they’re cheaper than the developers, but if you’re hiring good testers, they’re as expensive or more expensive than the developers.

    And so in the opensource world we look at it and we go, “These people are peers and equals,” and then we come into a company and we say, “They’re second-class citizens, and we’re gonna hire a couple of tech writers ’cause they’re a lot cheaper than having the developers write the documentation, or we’re gonna hire some testers, or we’re gonna hire some ops people ’cause the person to watch the dashboard is way cheaper than having a developer do it.” And we’ve seen it happen with the SRE role where, when we elevate that and that becomes part of the development team, the other – SREs are expensive and hard to find. That same sort of thing I think needs to happen in other roles on a development team in order for them to stop being that second-class – and also to stop having developers be the ones that have to do all of this work. If you look at it and say, “Well, the test writer or the doc writer is a cheaper person and we’ll just hire a couple of them,” it’s more likely to fall on the developer to do the hard work than to hire the good people and have them do the hard work.

    Shimel: Fair enough. Mitch, what do you think on that?

    Ashley: You know, it’s a really good point, and I think part of what you’re saying, Adam, is it’s a specialty. You think differently to be a fantastic tester, not just testing but the whole test strategy and how to do all the different kinds of testing that’s involved, and then of course how do you automate that and do you do that yourself? Do you work with part of the dev team to do that? Same thing for SRE, right? It takes a different – someone who thinks about it differently. And it’s sort of that cognitive diversity of teams that we value from a diversity standpoint. We value that also because those roles also require specialty skills. You know, someone who’s designing – and, Tracy, you could explain this better than I could, but someone who’s designing a cloud-native architecture and thinking about the microservices and what’s gonna constitute a microservice, how we’re gonna communicate between them and how we’re gonna secure them, that’s a different kind of thinker than how do I break all that stuff. That’s really nice that you did that, but watch how fast I can break that. That’s fun, and that’s where people really enjoy working together. But I think that’s part of where you’re elevating, too, Adam, is you’ve got to value all the skills, and they may be expensive, they may be not quite as much, but they’re needed. They’re part of the process.

    Shimel: Interesting. You know, Justin, we’re talking about testers. We’re talking about SREs. We’re talking about developers. Once again, no one’s talking security. Are we just sentenced to be forever the outsiders here? What’s it gonna take?

    Hutchings: Most of the security people that I talk to take that as a challenge, you know? We obviously want developers to go and embrace security as part of, you know, their everyday job descriptions, but folks in AppSec and especially in the security research community, they’ve always felt like kind of scrappy outsiders that are going to shine a light on things that other people didn’t notice. And so I think even when we have very security-minded, security-motivated engineering teams, security is a discipline that’s got to stand apart, because we want to have that sort of trusted auditor role or that, you know, lookout for – whether it’s bug bounty reports or stack analysis findings that no one looked at. Like, someone’s got to be watching those, ’cause developers, especially in the world of microservices, they might work on a thing, finish it, and then go somewhere else. But the security world changes all the time. If you walk away from that microservice and all of a sudden we learn about a new category of security problems and no one’s watching it, well, that’s a problem now. And so security has a really special role in terms of being the stewards of all the things, even when they’re not directly accountable for the functionality of it. And I think that’s a special thing that we should celebrate.

    Shimel: Okay, we’re special. But you know, as special as we are, yet we’re still seeing security tools for developers, right? That is a bona fide trend in our industry, and at the same time we’re also seeing – when we talk about the load on developers, we’re still seeing an extreme need for more security people, right? We just can’t produce enough qualified security folks, it seems. If that’s the facts, right, there’s no getting around it. What else is there to do but put this load on the developers? How else do we deal with it, automation? I don’t know.

    Hutchings: You’re absolutely right, and I think the key for tool spenders like GitHub is to figure out how to give developers enough information that they can be successful but not overwhelm them, because security tools, you know, there’s a risk of false positives. If you give them too many, they will ignore them. And so, like, as a tool vendor, I have to be extremely careful to make sure that I don’t burn out developers on the things I think are important, ’cause they might not find them as important as I do.

    Kalsey: The other thing those vendors have to do is make less work, eliminate work for the developer, not cause more, not give them more things to pay attention to, more work to do, more administration to do, but look for ways that you can remove that work through the tools.

    Ragan: Yeah, so we have a challenge facing us when it comes to automation right now, and the challenge has to do with these imperative pipelines that we’ve been running for the last ten years. Sometimes you have a Jenkinsfile that is pretty complicated, and we’ve been running them, we copy them, and we use them. It’s imperative.

    The problem with it is because it’s imperative. We are seeing a shift now to moving away from these imperative pipelines to where it’s more declarative and event-driven, which means that it should be easier then to take these older – if you had a purely declarative pipeline based on events, think about how easy it would be to say, “Okay, we’ve decided on this set of security requirements to add to sort of the workflow steps for the testing workflow, for the development workflow, and we’re gonna plug those events in.” The reason why we don’t do that now is because it’s too hard. [Laughter] It’s just hard, because we have to take these old imperative pipelines and try to modernize them. And without having that declarative framework, these kinds of tools, even adding continuous testing, even adding continuous deployments all the way to production, it’s hard and it takes a lot of work, and you have to change the tires as you’re going down the freeway in an imperative model. The faster we can get to an event-driven process in our CD pipeline where we can declare them and we can automatically generate what we need to do in a workflow, the sooner we’ll be alleviating some of the pain that the developers might be seeing, the sooner we can bring in better testing, the sooner we can bring in the DevSecOps conversation, and in our case automated configuration management.

    This has always been a problem for any of the tools in the CD pipeline to start being plugged in, because the imperative pipelines that we are dealing with on a daily basis, nobody wants to touch them. So we’re gonna have to disrupt that first, and when that gets disrupted and people start moving to something more declarative, we are gonna see an increase in adding all of this kind of automation into the CD pipeline.

    Ashley: I’m curious, Tracy. Is it the complexity of the pipelines that – the way they’re defined, is that why people don’t watch to touch them, or –

    Ragan: It’s the number.

    Ashley: The number, okay.

    Ragan: You’ve got – literally I’ve seen people with thousands and thousands of workflows ’cause they’re running one for every single application version. And to look in that and say, “Oh, we’re gonna change all of these,” because it’s not templated so you can’t just change it in one place and it’s just gonna trickle down, because they’re all these very statically scripted processes. And for whatever reason on the distributed side of the house – when I say distributed, I’m talking about everything except the mainframe – we have relied on heavily scripted processes, and we’ve scripted ourselves into a box that we cannot – we’re not Agile. We cannot easily update these pipelines to include security in them.

    We talk about it at the CD Foundation often, trying to elevate security as a first-class citizen in the CD pipeline. But that means that everybody’s got to start updating all those CD pipelines, and they’re not templated. They’re all statically scripted so you have to address one at a time. And as I think Justin might’ve said, you’ve got to plan to pay for that. So we’re in a box, we’re in a corner, and we have to somehow get ourselves out of that corner in order to alleviate these kinds of problems. And being Agile at the CD pipeline level means that we’re gonna have to dump these imperative processes.

    Hutchings: And I think you’re exactly right there, Tracy. One of the challenges we also see with security is this desire to start slow so that you don’t overwhelm people with too much, and if you don’t have a centralized control plane that everyone pulls from, you know, as you start to introduce these security tools, you can’t dial up the difficult level as you go. You have to hit those distributed CI pipelines every single time you want to go and update the difficulty, and that’s not tenable. I mean, you know, there are services out there – I think GitHub with Actions is doing a pretty okay job with allowing some centralized management, but it’s a spot that we all have to invest in because, you know, that control plane for specialists like security to go and help inject things is just not as mature as it needs to be.

    Ragan: And the CD Foundation has started an events working group to start having this discussion. Right now they’re talking about just vocabulary, but I believe that will grow into a bigger project in the future so that we can start thinking about how you can have that event-driven process so that you can dial it as you need to, right, as oppose to having them statically scripted in all of these imperative pipeline processes.

    Shimel: So, guys, we’re running low on time. Just one other topic I wanted to bring up. You know, in looking at this problem, though, I’m reminded of when I read The Goal, right, which is kind of the book upon which Gene Kim based his Phoenix Project on. The Goal is about more manufacturing; The Phoenix Project was IT. But really it talks about bottlenecks, resource constraints. And the story of The Goal – and I forgot if it was the first rule, the second rule, whatever it was – is as soon as you fix one or get rid of one problem, the next problem down the line shows itself that maybe you didn’t see because the problem in front of it was hiding it camouflaging it. In trying to make life easier for our developers or take the strain off of that point, are we really just going through this goal process of discovering the next bottleneck? And maybe that’s what – maybe that’s the secret to life. Life is just about going from one bottleneck to the next, right, and discovering what’s downstream from there. There’s something Zen about that. But is that what we are sentenced to for sure, or is there a way out of that?

    Kalsey: I like to say that when designing large-scale distributed systems you can’t remove your scalability or your failover problems; you just move them to a different part of the stack. And we do that a lot with development teams as well, is we don’t remove the problem; we just move it to a different part of the process and move it around.

    I think one of the ways out of that is one of the tenets of Agile is let the teams make the decisions. Hand them the problem and let them decide how to organize, how to do these things, how to make stuff work. You know, if management is pushing down on development and saying, “You’re now going to be the testers,” of course we’re causing more work and more problems and more things for them, and they’re going to become the bottleneck. But if we let the teams figure out – they’re the ones close to the work, doing the work. Let them make the decisions about how we’re gonna do this and what they need to make it happen.

    Shimel: Fair enough. All right –

    Hutchings: Yeah, I was gonna say I like the term incrementally correct. You know, Alan, your thinking about bottlenecks is absolutely true. I don’t think there’s ever a world where we will get to 100 percent panacea, but we can hope to get a little bit better all the time, and that’s the journey that we’re all on, right?

    Ragan: And failing fast.

    Shimel: _____ continuous improvement, and failing fast – like get to know –

    Ragan: And allow your developers to fail and not – or your testers or your security. It’s okay to fail, because then you learn what you need to do. Failing fast is part of the learning process.

    Shimel: Fantastic. All right, guys, we are out of time. I want to thank all three of you for joining Mitchell and I on this episode of ” DevOps Unbound.” Thanks to Tricentis for sponsoring ” DevOps Unbound,” as always. We will be back in – not next week, the week after with a new, fresh episode, as well as check out – we’ll have a new ” DevOps Unbound Roundtable” open to the public for questions, and you can find out about that at DevOpsUnbound.com or on our Digital Anarchist site or staging-devopsy.kinsta.cloud frankly. Look under – it’ll be under webinars and you’ll find the Roundtable there.

    Until then, though, Tracy Ragan, as always, it’s a pleasure to have you on. You bring such enlightenment to the whole discussion. Thank you.

    Ragan: Thank you, Alan.

    Shimel: Thank you. Justin, again, always nice to have you on one of our panels and discussions here. Many thanks for coming. And, Adam, thank you and good luck in – you know, I know you’re relatively new in your position there at Tricentis but it looks like they made a hell of a hire. Good luck, and come back and visit us again.

    Kalsey: Would love to. Thanks a lot.

    Shimel: All right. Mitch, you want to take us home?

    Ashley: I just wanted to thank our panel as well, and I love the incremental progress idea, and it’s always getting outside perspectives sometimes, too, that’s helpful. So I think we’re here to help each other in this process and not one of us has the answers.

    Shimel: Right on. All right, this Alan Shimel for “DevOps Unbound.” We’ll see you on the next show. Bye-bye, everyone.

    [Outro music playing]

  • Don’t Look at This! IT’S A SECRET!

    Don’t Look at This! IT’S A SECRET!

    To continue the discussion about secrets after perusing this excellent report by GitGuardian—last time I went a little nuts about the number of secrets exposed in IT folks’ personal repositories. And it is a lot. I mean a lot of secrets. But you know what is scarier than, “A lot of secrets are leaked in personal repositories of people rushing to get this week’s sprint in”? The fact that 30,000 secrets were leaked via corporate public repositories in 2020. That’s thirty thousand.

    This is not some poor DevOps person in a rush to meet deadlines and with no real security support for personal repositories who dropped some secrets into a public personal repository.

    This is a system set up by your organization that should have security awareness, should be getting scanned regularly and that should never be a source of information for hackers. Instead, it is a source of information, perhaps even critical information, that hackers can easily snag. Because there are secrets in this public repository.

    The first step to avoiding this problem is to acknowledge that IT can’t serve every need, and ask business units (BUs) to come forward with any apps they’ve developed behind your back so that (non-invasive) security can be applied to those apps.

    You’ll either get some apps, or people won’t trust you and you won’t get any. In the latter case, truthfully explain about secrets hiding in public repositories and ask them to validate their own. It’s the best you can do if people won’t share what they’ve done, and there are still people out there that think IT involvement is a huge impediment to their software. ::Shrug:: As long as you can get them to check their apps for vulnerabilities, it shouldn’t matter too much. But I’m more concerned about getting the secrets, so I won’t debate the centralized-versus-distributed-app philosophies in this blog beyond saying, For secrets, if you can get them to scan/clean them up, the question of who is managing the app and the process isn’t very important.

    I’m still shaking my head—30,000! That is more than 100 secrets checked into public, corporate repositories each day (on average, of course). Please, go through your org, make sure you are not contributing to this total. That is wild; even if you account for the fact that if an app has one secret out there, it probably has multiple; even assuming each vulnerable app had four, that’s still 7,500 apps exposing secrets in the most preventable way possible.

    So, if you’re not certain about your public repos, go get certain. The ROI on “a few minutes for a scan, or a couple hours for a person to search for them” versus “our AWS secret was compromised,” or, “our API key was discovered and abused,” is pretty high.

    And keep rocking it. The sheer volume of apps out there is part of the shared-secrets problem, as is the growth in use of secrets as automation and DevOps have taken over. But you’ve got the solution, just make sure they’re not hanging out there in a public repo. And then go back to doing what keeps the business alive.