Category: DevOps Toolbox

  • Languages and DevOps: Can’t be Contained

    Languages and DevOps: Can’t be Contained

    The evolution of platform is an interesting study. From physical to virtual to cloud to containers, the progression has been steady, and each successive platform has benefits for both Dev and Ops that make them appealing. In the case of containers, portability is the word.

    As easy to fold into your DevOps toolchain as cloud, yet able to be deployed wherever you need, containers have absolutely taken the industry by storm. While all cloud vendors offer container options these days, their “value add” capabilities are thinly veiled attempts at vendor lock-in, so most organizations have avoided them.

    Development languages are as diverse as they are for physical or cloud; you can pretty much find containers hosting every language imaginable. That makes perfect sense, since one use of containers is to keep an otherwise-obsolete environment alive. That’s certainly not the primary use of containers, but it is an important one. The catch with containers is that the primary languages depend greatly on usage. A container that is persistent and intended to last months or even years will tend toward a different set of languages than one that is ephemeral and intended to last only minutes.

    The big weaknesses of containers – security, persistent storage, and management – have been addressed more and more as container usage has grown. Complexity of environments is now the big issue, but that is not inherent to containers; merely enabled by the ease with which new machines can be spun up.

    For longer-term containers, Java and C# are still the languages of choice, though others are certainly making headway. A combination of how new container technology is, and the extra layer between applications and hardware in the current popular container solutions make C/C++ less popular than on physical machines. They are still used because like other targets, containers still have operating systems that are linked to more easily in these languages.

    Shorter-lived containers tend to use languages that grew up in the Agile environment – from Python to JavaScript to Go. The ability to quickly crank out the code and get to test is useful for Agile and DevOps environments.

    Hooking into DevOps toolchains is at least as easy as it is in a cloud environment. There are even a fairly large number of companies that have moved to spinning up a container to build, then destroying it, only to do it all again on the next build. This is not mainstream yet, but the ability to completely configure the container and its loaded toolset makes it an appealing option.

    The kicker – one that cannot be overstated – is that it is simple and easy to get developers running with a copy of a complex system that once would have required several physical boxes. I, personally, have worked on a seven-plus server client system that I had a complete copy of on my (admittedly beefy) development laptop. It wasn’t the most performant, but it was enough to do unit testing.

    The security weaknesses of cloud come along with containers too – there is a lot more than just configuring an IP to directing traffic, for example – but mitigating tools and processes are available.

    This pundit truly believes that containers are the future of DevOps. They have the best of previous iterations, while offering mobility that just didn’t exist in other solutions. The ability to move an entire infrastructure from one deployment target to another (data center to cloud, for example), or from one cloud vendor to another makes this option the king for organizations that require (for business objectives, compliance or finance reasons) the ability to move their applications quickly.

    Meanwhile, rock on.

    Containers are the cutting edge of wherever it is we are headed. They are more agile than any other solution, they do not limit programming or networking options, can be run wherever the organization needs them and can be modified or redeployed easily. There is more complexity, but most of it has been obfuscated; only when things go terribly wrong is the complexity really an issue. Development for containers, with a few exceptions, is development for the target OS. That makes it easy to keep the organization’s systems preferences while enabling developers. All good. And many (I daresay most) of you are already taking advantage of them. Keep rocking it. Use what the org needs, and don’t forget to check every once in a while to make certain what is in use is what needs to be in use.
  • Linux Foundation Takes Control Of AsyncAPI Specification

    Linux Foundation Takes Control Of AsyncAPI Specification

    The Linux Foundation announced today that it now plays host to an AsyncAPI Initiative that has developed a specification and a suite of open source tools for asynchronous application programming interfaces (APIs) and event-driven architectures.

    Founding sponsors of the AsyncAPI Initiative include Ably Realtime, Apideck, Bump, IQVIA Technologies, Slack, Solace and TIBCO. Most recently, Postman, a provider of API management tools, committed to providing engineering resources to the project as well.

    AsyncAPI provides a language for describing the interface of event-driven systems, regardless of the underlying technology, and supports the full development cycle of event-driven architecture. That approach helps unify documentation automation and code generation, as well as managing, testing and monitoring asynchronous APIs.

    Chris Aniszczyk, CTO and vice president for developer relations at the Linux Foundation, said the Linux Foundation will work with the member organizations to facilitate a governing framework similar to the frameworks other open source projects have adopted under its auspices.

    In general, reliance on event-driven architectures is on the rise thanks, in part, to the rise of digital business process initiatives that require the processing and sharing of data across multiple platforms in near-real-time. The AsyncAPI Initiative makes it simpler for disparate event-driven platforms to be integrated. It’s unlikely multiple organizations involved in a digital business initiative are ever going to standardize on the same event-driven platform, so an AsyncAPI specification provides a critical linchpin.

    Usage of the AsyncAPI Initiative is already fairly widespread, with Adidas, PayPal, Salesforce, SAP and Slack all employing it in production environments. In fact, the Linux Foundation cited research that identified AsyncAPI as the fastest-growing specification being implemented by developers, after seeing adoption rates in production environments triple from 2019 to 2020.

    Event-driven IT architectures have, of course, been around for decades. However, as they have gained traction in the modern era of software development, the need for the equivalent of a REST API for asynchronous communications between platforms, based on different event-driven architectures, became apparent. The AsyncAPI doesn’t replace the need for other types of API specifications, but Aniszczyk noted that, over time, it will soon player a larger role, especially as cloud-native application environments become more distributed and the number of use cases that can’t be addressed using traditional batch-oriented techniques continues to rise.

    In the meantime, the number of providers of event-driven platforms based on proprietary architectures spans vendors ranging from Oracle and IBM to cloud service providers such as Amazon Web Services (AWS). At the same time, open source messaging platforms such as Apache Kafka are starting to have a significant impact on how IT teams build their own event-driven platforms.

    The level of enthusiasm for an API specification that makes all those platforms more interoperable than they would otherwise be is unclear. However, as modern IT platforms continue to evolve, more IT teams are becoming aware of the crucial role API specifications play in preventing them from becoming locked into one platform.

  • CircleCI Previews Support for Arm Platforms

    CircleCI Previews Support for Arm Platforms

    CircleCI today previewed the ability to deploy applications on platforms based on Arm processors in a forthcoming release of its namesake continuous integration/continuous delivery (CI/CD) platform.

    Tom Trahan, vice president of business development for CircleCI, said that Arm processors are rapidly being embraced by DevOps teams seeking to take advantage of the price/performance advantages they currently have over conventional x86 processors. Amazon Web Services (AWS), for example, makes available an AWS Graviton2 service based on 64-bit Arm Neoverse processors that it claims provides a 40% advantage in overall price/performance.

    The Arm community, meanwhile, has adopted many of the libraries employed on x86 platforms, Trahan noted, which is making it simpler to automate the deployment of applications on Arm-based platforms using a CI/CD platform.

    It’s not clear how quickly developers are building applications for Arm processors. Historically, Arm processors can be found in a wide range of embedded systems typically deployed at the network edge. However, cloud services based on Arm processors are also becoming more widely available, and it’s only a matter of time before more Arm-based platforms are deployed in on-premises IT environments.

    Arm itself is also in the process of being acquired by Nvidia, which envisions running machine learning algorithms, and other classed of advanced workloads, on both Arm processors and graphics processing units (GPUs). Many of the early efforts to build processors optimized for running AI workloads at the network edge are based on Arm processors.

    The addition of Arm platforms to any IT environment will naturally create some management challenges for DevOps teams. In some cases, developers may even decide to build applications using, for example, the latest generation of machines from Apple, that are based on Arm processors, to streamline the application development and deployment process. In other cases, however, applications that are intended to be deployed on Arm processors might still be built on x86 systems.

    Regardless of approach, the arrival of more Arm-based platforms in the enterprise doesn’t mean other classes of processors are going to fade away. Rather, from a processor perspective, IT environments are about to become a lot more diverse as more workloads are deployed on a wider range of processors. It may be quite a while before Arm-based platforms usurp x86-based systems that still dominate the IT landscape. However, during any turbulent economic time, the number of organizations inclined to reduce the total cost of IT by embracing new platforms always increases.

    Fortunately, as more IT infrastructure is managed as code, the easier it becomes to switch platforms. There may even come a day when the decisions about which platform to employ and when is completely automated by machine learning algorithms trained to maximize IT infrastructure efficiency to the fullest extent possible.

    In the meantime, DevOps teams should expect, to one degree or another, to revisit their workflows processes in the months ahead. Not only are more workloads being pushed out to edge computing platforms where Arm processors are commonly found, those Arm processors will soon find their way into the rest of the extended enterprise.

  • Tricentis Aquires Neotys to Gain Load Testing Tools

    Tricentis Aquires Neotys to Gain Load Testing Tools

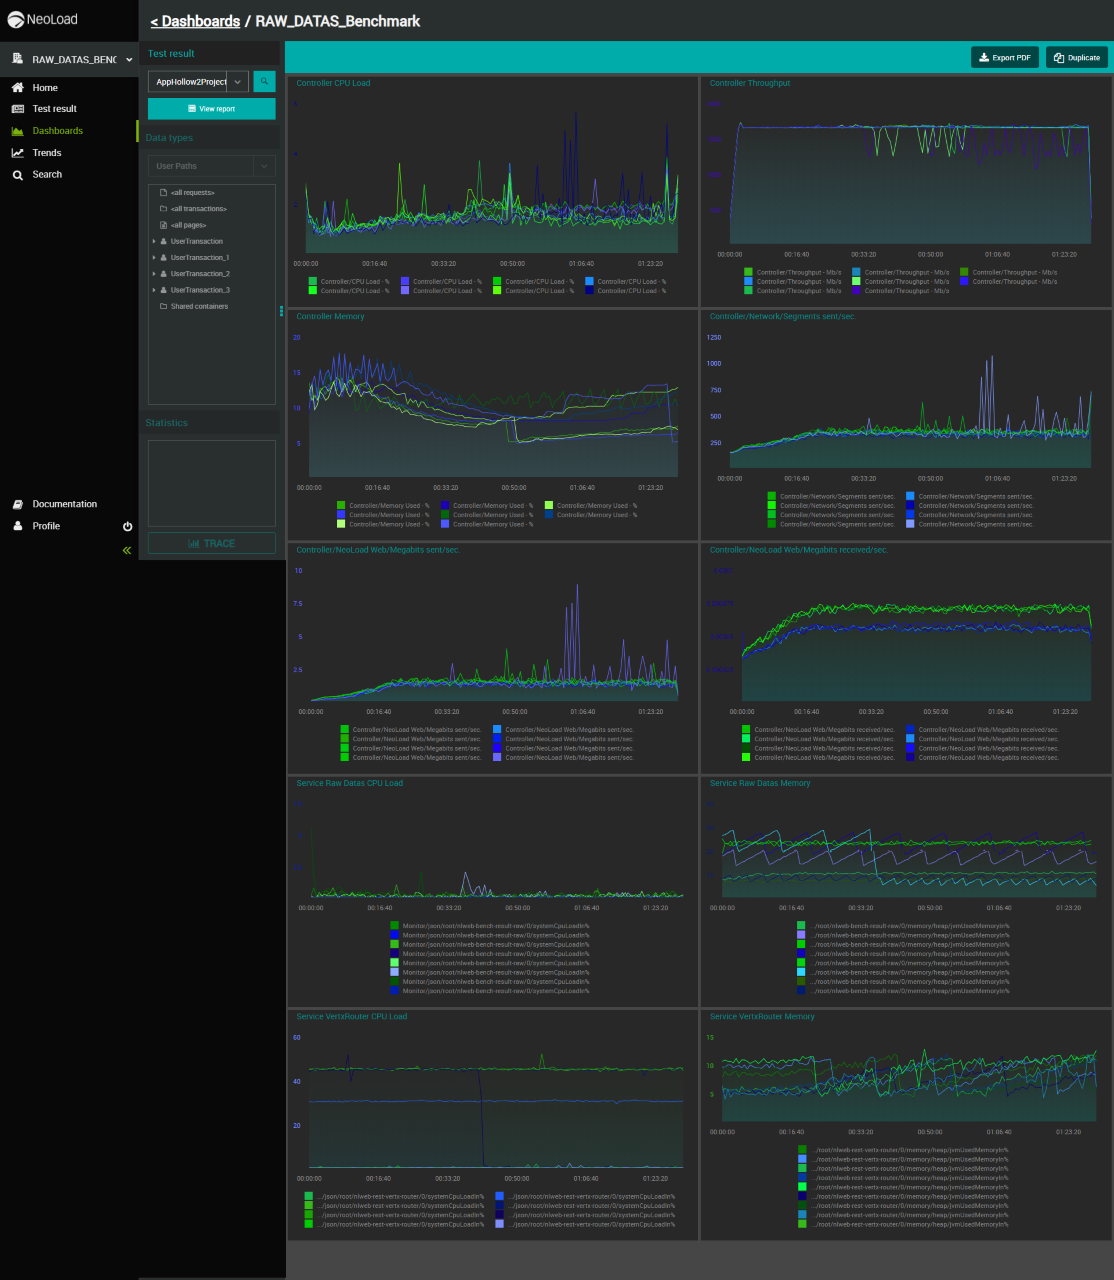
    Tricentis announced today it has acquired Neotys as part of an effort to expand the scope of its tools portfolio into the realm of load testing. Terms of the deal were not disclosed.

    Neotys provides application testing teams with automatic test design and maintenance, user behavior simulation and root cause analysis capabilities using a set of tools that are designed to be integrated within a DevOps toolchain.

    Sandeep Johri, Tricentis CEO, said the Neotys platform will extend the scope of Tricentis’ Tosca testing platform that today enables DevOps teams to employ machine learning algorithms to test the functions within an application.

    In general, Johri said there’s now a lot more focus on load testing, thanks in part to the rise of microservices-based applications that are starting to be deployed at scale. DevOps teams are, first, trying to identify, as early as possible, a single point of failure that might bring down an application. Second, modern microservices-based applications are designed to degrade gracefully when there is no single point of failure. Identifying what issues are leading to that degradation can be challenging, given all the dependencies that might exist within a microservices-based application.

    Neotys claims to have more than 600 enterprise customers, including BNP Paribas, Dell, Lufthansa, McKesson and Verizon. Tricentis claims to have more than 1,800 customers, including McKesson, Accenture, Nationwide Insurance, Allianz, Telstra, Rockwell Automation, Moët Hennessy-Louis Vuitton (LVMH PCIS) and Vodafone. The acquisition of Neotys will reduce the number of vendors that an organization needs to engage to gain access to a portfolio of testing tools, Johri noted.

    As IT organizations embrace DevOps best practices, more responsibility for application testing is clearly shifting left toward developers. However, it’s not quite clear to what degree that shift is either eliminating or reducing the need for dedicated application testing teams at the back end of the application development process.

    At the same time, many rote testing tasks are now being automated using machine learning algorithms. Those algorithms don’t completely eliminate the need for humans to test applications, but they do significantly reduce the testing time required. They should also create more time for developers to collaborate with one another to review more complex interactions within an application that machine learning algorithms are unlikely to be able to automate any time soon.

    The amount of time organizations devote to application testing has always been constrained. As deployment deadlines approach, often the first thing that gets reduced is the amount of time allocated to application testing. In many cases, developers deliberately don’t address some known issues until the first or second update to an application that has already been deployed in a production environment.

    Of course, integrating application testing within a DevOps process enables organizations to identify more potential issues earlier when they are easier and less expensive to fix. The challenge has always been getting developers to appreciate the value of testing early and often in the application development process.

    Regardless of how application testing continues to evolve in the age of DevOps the one thing that is certain is no matter how automated it gets developers are going to be more involved than ever.

  • Best Practices for Digital Experience Management

    Best Practices for Digital Experience Management

    The COVID-19 pandemic put digital services in the spotlight. The winners in 2020 and beyond will be those organizations which provide awesome user experiences for online products, services and apps. There is scant room for error, as digital leaders before the pandemic have upped their game even more.

    For example, streaming service provider Netflix’s 2020 Q4 revenue reached $6.64 billion – almost $14 million more than expected – and added 8.5 million paid subscribers. The company had more than 200 million users in the quarter and saw viewership for non-English titles jump 50% during the year as U.S. viewers sought new content from around the globe.

    Companies in more traditional sectors, such as restaurants and hospitality, also grew by investing further in digital strategies. Chipotle’s 2020 revenue increased 7.1% to $6 billion, with digital sales skyrocketing 174.1% and accounting for more than 46% of sales. Target’s digital sales increased 155% in Q4 while Costco grew e-commerce sales by 91% in FY20, as online ordering and curbside pickup became the new normal.

    Digital Experience Monitoring Basics

    To manage this onslaught of online customers and transactions, IT organizations are turning to digital experience monitoring (DEM). DEM is a broad area, but it comes down to delivering the best experience for your customers and employees by monitoring your IT assets and addressing issues that arise before they become problems. DEM allows you to mimic and test the end-to-end customer and worker experience. Such solutions can be used in on-premises data centers or run in multi-cloud and hybrid cloud environments.

    There are two key methods for DEM:

    Real user monitoring (RUM): This entails using real users’ devices to measure the performance of a page. A script is injected on each page to measure data on page load performance for every request made, monitoring the interaction of an application and the users. The data shows such aspects as how an application is being used and the geographic distribution of users.

    Synthetic monitoring: This technique tests the performance of a page using an automation tool rather than users’ actual experiences. Scripts are used to simulate how a user might move through a web application and then reports are created based on that performance.

    In a recent report, Gartner analysts said DEM products are evolving, moving from a focus on performance and availability to correlating infrastructure and operations (I&O) and business outcomes. Currently, fewer than 15% of digital business initiatives will require I&O leaders to report on business metrics from digital experience; that will jump to 70% by 2025, Gartner says.

    For years, organizations have been using monitoring tools to measure various aspects of their infrastructure. For example, IT operations management (ITOM) solutions track metrics and manage alerts and events for infrastructure hosted on-premises or in the cloud, including servers, networking systems, storage appliances and databases. The data also can be used for historical data analysis and to map out trends.

    DEM is specifically focused on the end user experience, giving IT professionals the visibility to run diagnostics, fix issues and measure performance at each point of contact between the users and the application. Acquiring a new customer is an expensive effort, and a customer can be lost because of a single poor experience. DEM is designed to ensure the optimal experience.

    Getting Started with DEM

    There are two common approaches for implementing DEM:

    Point tools: Domain-specific monitoring tools track and measure different layers of the technology stack, such as networks and applications. The upside to this approach is you get more in-depth coverage from the point tools, but it can lead to tool sprawl, which impairs visibility and increases costs.

    Platform: This approach provides native monitoring for many areas and integrates with other tools, as needed, to deliver a central, unified view that makes it easier to see everything at once. However, it doesn’t include best-of-breed performance or the deepest analysis capabilities you will want in every area.

    An important first step is to identify the metrics and outcomes priorities for your organization. Then spend time researching the proper toolset for the goals you want to achieve. If you decide on deploying multiple single-domain monitoring tools, remember that you will need an integration strategy. The tools will need to easily share data and display that centrally, to deliver a holistic view of digital experience. Integration is also critical for troubleshooting and connecting metrics to a specific business service. You also will need subject matter experts in these technology domains who can ensure that the DEM tool(s) keep pace with advancements in IT infrastructure and development technologies.

    The Future of Digital Experience Monitoring

    The DEM field is evolving, with more parts of the I&O stack coming under its purview. Solutions will offer more capabilities and be easier to integrate out of the box with other tools because the end-to-end flow doesn’t stop with monitoring and collecting metrics. ITOps staff need to take action on critical alerts with efficient workflows and intelligent recommendations. AIOps and machine learning analytics are playing a growing role here.

    DEM can reduce time-to-value for customers and workers, simplify and ease onboarding to new sites and apps and ultimately increase interactions and sales. Advanced solutions can fuel predictive analytics, form a deeper understanding of user behavior to optimize websites and apps in step with user requirements and dynamic infrastructure changes. In a digital-centric world, DEM capabilities are critical to the health and future of organizations in every sector.

  • Visualization Shines a Light on IT Metrics

    Visualization Shines a Light on IT Metrics

    Modern IT departments operate in a pressure cooker. Their highly distributed infrastructures are spread across legacy data centers and hybrid and multiple public clouds. Now, the Internet of Things (IoT) and the edge are part of the mix.

    Massive amounts of data are flowing through these multifaceted environments, and it falls on IT to make sense of it all, ensuring that issues don’t become problems and that it’s viable to produce measurable outcomes for the business. Dashboards are instrumental for visualizing and quickly making sense of that data.

    Metrics – numeric representations of data measured over time – give IT operators and site reliability engineers (SREs) a window into how a system has historically behaved. That data provides insights as to how the system(s) should perform in the future, and aids investigations when something goes awry. IT monitoring tools act as giant data lakes, holding time series data, while dashboards give everyone from IT administrators to C-level executives ways to easily digest the data.

    The visualization market is evolving. We’re seeing different kinds of databases, such as Prometheus, which bring with them new tools to leverage the data. Prometheus (PromQL) is growing in popularity in the DevOps space and becoming the standard for monitoring containers and microservices because it makes it easier to manage time series data. PromQL also comes with client libraries that include four core metric types:

    • Counter: Represents a single monotonically increasing counter where the value can only increase or be reset to zero on restart.
    • Gauge: Represents a single numerical value that can arbitrarily go up and down, such as CPU utilization.
    • Histogram: Samples observations and counts them in configurable buckets. It also can provide a sum of all observed values.
    • Summary: Samples observations and provides a total count of observations and a sum of all observed values. Configurable quantiles are calculated over a sliding time window.

    Selecting Visualization Charts

    Selecting the appropriate visualization dashboard for each user is important to maximize the value of the data. There are traditional line and bar charts, single value tiles – which display a single data point at a specific point in time – and lists and gauges, which offer a single value at a specific point in time in a series.

    Newer visualization types are now becoming common to address the various use cases in ITOps and DevOps. Let’s walk through a few:

    1. Honeycombs offer big-picture views of IT infrastructure, yet also display detail. The hexagonal display mirrors those in a honeycomb, and helps DevOps pros slice and dice the data based on attributes or tags. Each hexagon represents a specific host or resource, and can be organized in logical groups of elements. The colors change when thresholds are reached, and the hexagons can be sized differently based on the value of the metric. Consider a case of many AWS EC2 instances scattered across the globe. Each hexagon can represent an individual instance, and they can be grouped based on the “region” attribute. This honeycomb chart would let administrators see how each infrastructure site is performing.
    2. Gauge metrics use a language like PromQL to set a ceiling and a floor. If the user creates alert conditions based on particular thresholds, the dashboard will indicate if a certain resource has reached its threshold by changing the color. A gauge that turns red may indicate a critical problem, for example. Managed service providers have SLAs with clients to maintain uptime. If a problem arises, a red indicator on a gauge tile lets the IT administrator know immediately that the SLA agreement has been breached, and that an issue needs to be addressed.
    3. Heatmaps provide a graphical representation of the volume of data points within bucketed ranges. The color of each cell of a heatmap directly reflects the density of certain metric value ranges. Heatmaps are used to display group trends and spot outliers, which make them useful when viewing metrics with a wide distribution of values.

    Role-Based Requirements

    Picking the right chart depends in part upon the people viewing the data. CXOs, IT managers, sysadmins, SREs, network engineers and network operations center (NOC) operators will have different, yet overlapping, requirements.

    For instance, SREs want to ensure the reliability and resiliency of the infrastructure, so, through their dashboards, they look at everything from availability and latency to performance, efficiency and capacity planning. They can quickly spot outliers like server downtimes or memory issues and immediately begin to troubleshoot.

    CXOs, conversely, don’t need to get into the weeds of infrastructure operations. They use dashboards to gain a macro view of metrics for performance over time across websites and networks. They need to understand the correlation between IT metrics and business services and applications. Dashboards should be able to connect those dots.

    Other Considerations

    Finding the right visualization option is important. Once that is done, there are some other steps to take to ensure you get the insights you need from your dashboard:

    Positioning and ordering: Dashboard tiles should be placed in a logical order, with important high-level statistics near the top and the deeper, and more granular metrics progressively moving to the bottom to give users a quick understanding of system performance.

    Design: A well-designed dashboard with consideration paid to color schemes and themes also will make it easier for stakeholders to digest and understand the data.

    IT infrastructure performance is crucial to the health of a company. Massive amounts of data streaming out of systems can help IT administrators and others keep up-to-date about that performance and the overall end-user experience. Dashboards offer flexible ways to quickly view and understand the metrics; IT organizations now have a growing range of charts to choose from that can present the data they need in a way that works best for them.

  • Grafana Labs Aligns with Elastic on Observability

    Grafana Labs Aligns with Elastic on Observability

    Elastic and Grafana Labs have allied to create a plugin through which DevOps teams that are employing Elasticsearch within a DevOps workflow will be able to invoke a monitoring platform, based on Prometheus, that is managed by Grafana Labs.

    Raj Dutt, Grafana Labs CEO, said both companies are dedicating engineering resources to building and maintaining a plug-in for a service, based on open source Prometheus software, that is rapidly becoming a de facto standard for observability in DevOps environments. One of the primary reasons for that expanded usage is that Grafana Labs doesn’t require DevOps teams to move data into a central repository to analyze it, Dutt said.

    The overall goal is to eliminate the “tunnel vision” that results when relying on tools that only visualizes a narrow set of metrics, Dutt added.

    The cloud platform provided by Grafana Labs is based on open source Grafana visualization tools. The primary tool for visualizing Elasticsearch data is based on open source Kibana tools. Grafana, however, is based on a fork of Kibana, so the plug-in represents an effort to bring those two open source communities closer together. The two companies plan to collaborate on including more aggregations, broader query language support and support for space-saving constructs like rollups as the partnership evolves.

    Grafana Labs provides a cloud service that aggregates data, pulled from multiple instances of Prometheus, deployed on clusters and servers. Prometheus, especially, gained a lot of traction as organizations began to deploy Kubernetes clusters that are also based on open source software. Both Kubernetes and Prometheus are being developed under the auspices of the Cloud Native Computing Foundation (CNCF).

    Once DevOps team initially employ Prometheus to monitor Kubernetes, they frequently expand deployments to monitor additional platforms. That shift has resulted in many providers of proprietary monitoring tools to extend the data they consume to include the metrics captured locally by Prometheus. Grafana Labs claims it has more 1,000 customers, including Bloomberg, JP Morgan Chase, eBay, PayPal and Sony, for a total of more 650,000 active installations of Grafana around the globe. Existing customers of Elastic that are paying for Elasticsearch support include Cisco, eBay, Goldman Sachs, Microsoft, The Mayo Clinic, NASA, The New York Times, Wikipedia and Verizon.

    It’s not clear to what degree Grafana and Kibana might ultimately re-converge one day, but it’s clear there will be a fair amount of ongoing cross-pollination across the two projects. In the meantime, DevOps teams should be able to opt for whichever open source visualization framework they prefer alongside Elasticsearch.

    In the longer term, it’s clear greater appreciation for observability platforms that provide more context will drive a wave of consolidation among all the monitoring tools that enterprise IT teams rely on today. As part of the transition, enterprise IT teams might even standardize on a set of visualization tools that would eliminate the need to master different user interfaces. After all, the only way to actually achieve observability is through a set of tools that makes surfacing the context required easier to consume.

  • Copado Acquires New Context to Drive DevSecOps Adoption

    Copado Acquires New Context to Drive DevSecOps Adoption

    Copado, a provider of a DevOps platform for building applications deployed on the Salesforce cloud platform, announced today it has acquired New Context as part of an effort to expand the scope of its portfolio into the realm of DevSecOps best practices.

    Andrew Leigh, chief marketing officer for Copado, said the acquisition brings Copado tools and professional services expertise that will be applied to help organizations build and deploy secure, custom applications on top of the same cloud platform they already use to access a range of software-as-a-service (SaaS) applications.

    The New Context Lean Security Intelligence Platform enables developers to achieve that goal by analyzing code and then surfacing recommendations for when developers should apply specific security controls, Leigh explained. Existing New Context customers include Blue Shield of California, GE, Kaiser Permanente and Royal Dutch Shell.

    Like most organizations that have embraced DevOps best practices, it’s still early days as far as adoption of DevSecOps are concerned. However, it’s already apparent that Copado is well-positioned to advance adoption of a complementary Lean Security Intelligence Platform, said Leigh. Copado, which claims to have more than 1,000 customers, recently raised an additional $96 million in funding to help fuel those efforts. The company also claims it recorded 120% growth in annual recurring revenue (ARR).

    In the wake of the COVID-19 pandemic, more organizations are employing SaaS applications to drive digital business transformation initiatives. Rather than building every application from the ground up, it is often simpler to extend, for example, a Salesforce customer relationship management (CRM) application.

    Once organizations reach a certain level of scale, they then start to apply DevOps best practices to those builds. These efforts, however, are often uneven. A recent survey, conducted on behalf of Copado, found that while 82% have increased or maintained the size of their Salesforce development teams, the change fail rate jumped from 23% last year to 33% in 2020 when compared to a similar survey conducted a year ago. The survey also notes time to recover increased from 110 hours in 2019 to nearly 196 hours in 2020.

    The next major challenge facing organizations that have embraced DevOps is, of course, DevSecOps. The challenge is that, since Salesforce environments are unique, applications are constructed using a set of objects and tables that are specific to that platform. As such, Salesforce environments generally require a DevOps platform designed from the ground up to work with objects and tables.

    Salesforce, in its most recent fourth quarter, reported revenue of $5.82 billion, up 20% year-over-year despite the lingering economic impact of the COVID-19 pandemic. As such, the number of custom applications being developed on top of Salesforce should steadily increase, especially as low-code tools become more widely adopted. It’s now only a matter of time before more organizations reach application development initiative critical mass that warrants investing in a DevOps platform to manage them.

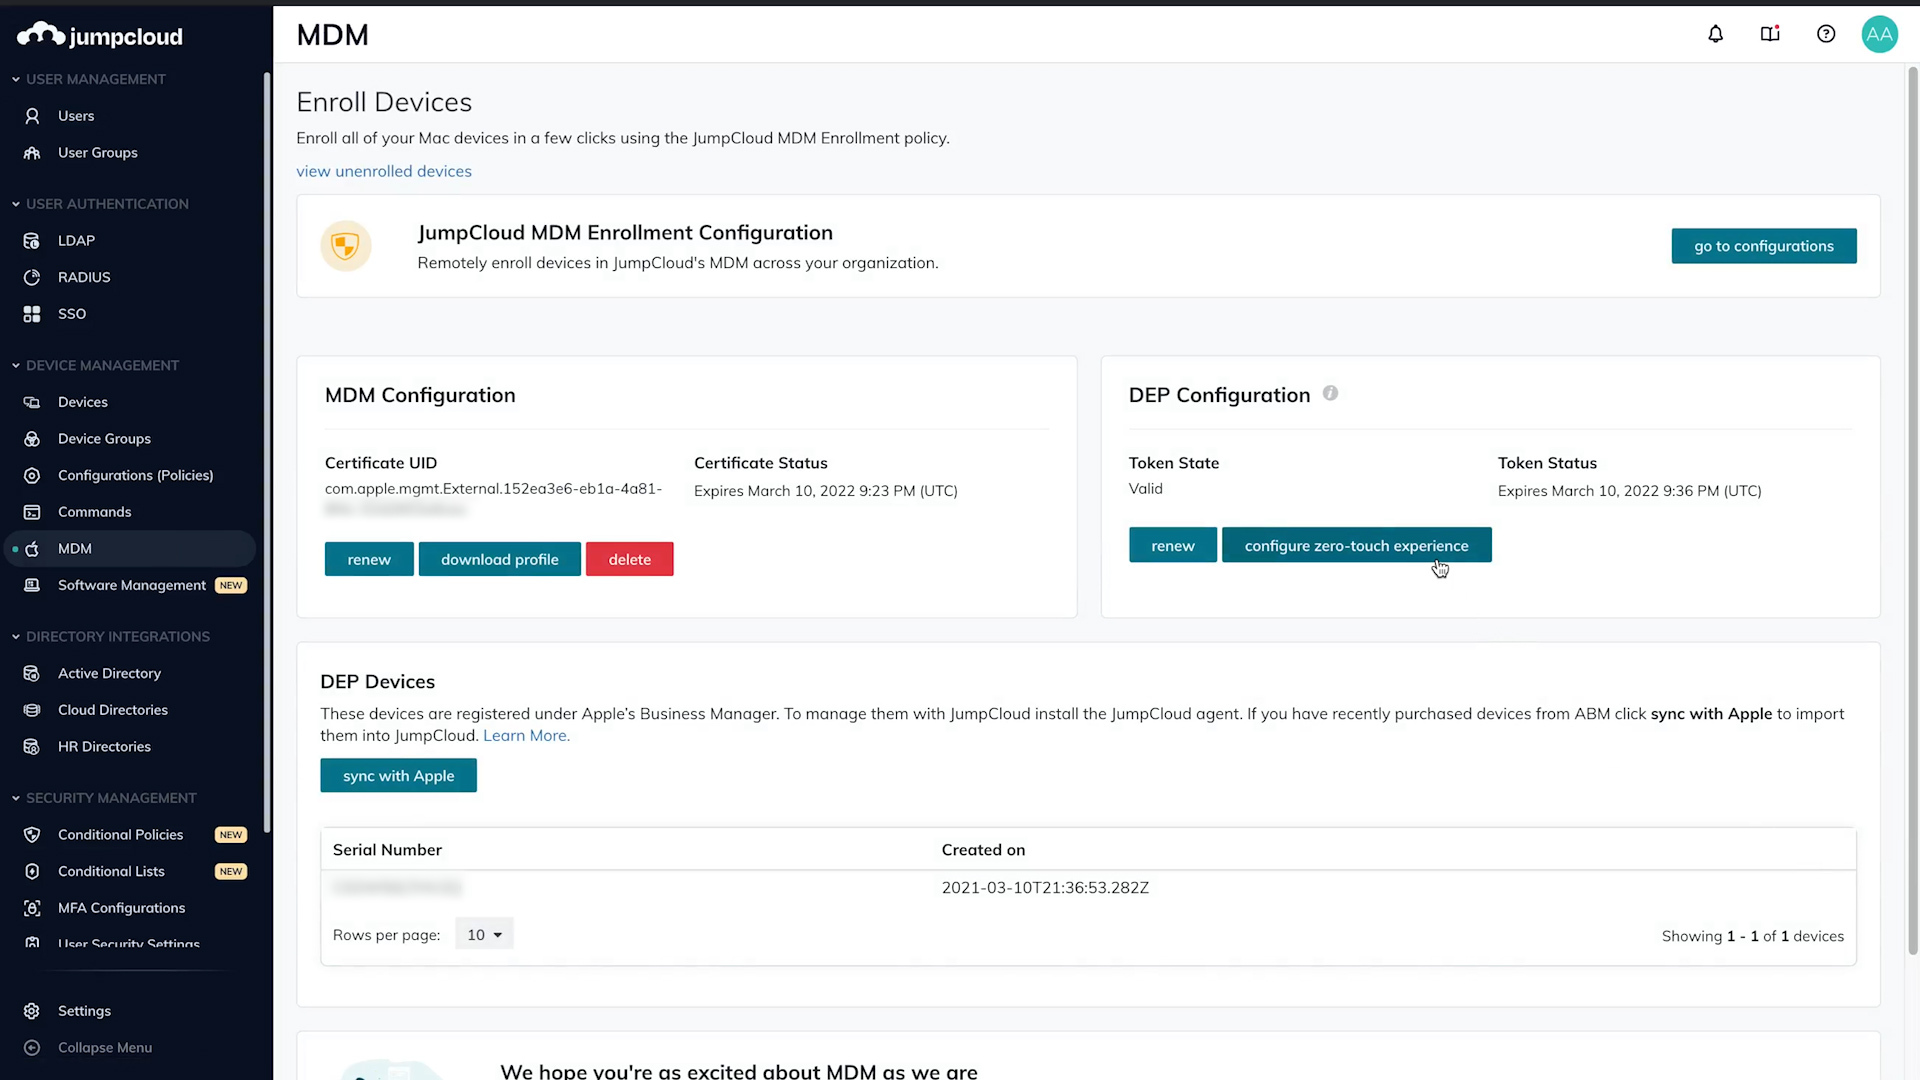
  • JumpCloud Brings Zero-Touch Provisioning to the Mac

    JumpCloud Brings Zero-Touch Provisioning to the Mac

    JumpCloud today announced it is adding a zero-touch enrollment for Macs capability to its cloud directory platform that will also be extended over time to applications.

    Greg Keller, JumpCloud CTO, said this new capability extends Apple Business Manager, formerly known as Apple Device Enrollment Program (DEP), all the way down to specific users by leveraging data that resides in the JumpCloud platform.

    Whenever a user logs into a new Mac, it can automatically be synchronized with the JumpCloud Directory, which then uses the identity of that end user to configure the device in addition to providing the appropriate access to all corporate resources via their JumpCloud credentials.

    Keller said the need for zero-touch approaches to IT administration has become more acute in the wake of the COVID-19 pandemic. With employees working from home more frequently even after the pandemic eventually subsides, Keller noted the days when IT teams could physically provision a Mac are on the wane.

    While Apple Macs still represent less than 10% of all the PCs shipped in a year, Keller noted small-to-medium (SMB) businesses are adopting Macs at a faster rate than large enterprises. As the endpoints become more diverse, Keller said the JumpCloud platform provides an alternative to Microsoft Active Directory for managing both Windows and Mac devices. Apple, of course, last year acquired Fleetsmith to gain access to provisioning tools. However, those tools are not yet integrated with any type of directory.

    Most recently, JumpCloud has added a tool that enables IT teams to remotely install software onto end user Windows devices, as well as integrations with Slack, Salesforce, Atlassian, GitHub and Amazon Web Services (AWS).

    Fresh from raising an additional $100 million in funding, JumpCloud is making a case for a zero-trust approach to managing endpoints using a directory that verifies the identity of each end user. JumpCloud, which makes a free edition of its platform available for individuals and small teams, is already being used by more than 100,000 organizations spanning more than a hundred countries. More than 3,700 of those organizations, including Cars.com, GoFundMe, Nimbus Therapeutics, Grab, Pulselive, SlimPay, Foursquare, Beyond Finance and Funding Societies, are paying customers.

    In the longer term, there may come a day when verbal commands are employed to provision endpoints for specific end users. In the meantime, the process of configuring and provisioning those endpoints is becoming more automated. IT teams are now able to remotely manage fleets of endpoint devices without having to physically touch them. In fact, there may be no need for IT managers to return to an office, as tasks become increasingly automated and able to be performed remotely.

    While there are a lot of options available to achieve that goal, Keller said the number of them that are tightly integrated with a directory to ensure the right system winds up in the right end user’s hands is few and far between. The challenge now is getting organizations to rethink their directory requirements at a time when IT teams are increasingly expected to deliver personalized, white-glove services regardless of where an end user is located.

  • Measuring the Value of DevOps-as-a-Service (DaaS)

    Measuring the Value of DevOps-as-a-Service (DaaS)

    The late great W. Edwards Deming, statistician, professor, author, lecturer, and consultant said, “In God we trust. All others must bring data.” The point is, if you want people to trust your information, then you need to present measured data. This is true for countless circumstances. As a DevOps consultant, I am often asked by my clients what data should be used to show the value of their DevOps capabilities, in a way that is acceptable to the stakeholders of those DevOps capabilities. A lot of excellent research results, published by DORA and others, describes metrics that demonstrate the value that DevOps provides to application development. More and more enterprises are embracing the idea of providing DevOps capabilities, such as pipelines, tools, hardened containers and tech stacks, as a centralized service to support their many application teams. The question then becomes, “What metrics should be used to show the value of DevOps-as-a-Service (DaaS)?”

    Before measuring the value of anything, you need to know two things: “What is it?” and “Why is it important?”

    What is DevOps-as-a-Service?

    In high-level terms, DaaS is DevOps capabilities made available to the users of those capabilities through portals and APIs. There is no standard set of services; DevOps capabilities offered vary from organization to organization. In my SlideShare, DevOps-as-a-Service (DaaS) Values, I illustrate a generic blueprint for DaaS.

    The DaaS blueprint has four layers, as follows:

    • Stakeholders – There are three types of stakeholders: business, app-dev users and DaaS teams.
    • Service access layer – This layer consists of user portals, APIs, and access security.
    • Service layer – The service layer consists of user services and management services. User services include things such as repositories, CI/CD pipelines, sandboxes, test data, configuration data, guides and training. Management services include service catalogs, issues and change requests, SLOs, SLIs, governance policies, experience monitoring and automated tasks.
    • Resources layer – This layer includes application stacks, infrastructure resources, tools, infrastructure code and topology data.

    Why is DaaS Important?

    The value of DaaS, as perceived by different stakeholders, can be summarized as follows:

    • Business – DaaS makes the business competitive.
    • App-dev Users – DaaS improves application development.
    • DaaS team(s) – DaaS improves management of DevOps capabilities.

    What Service Level Objectives (SLOs) Demonstrate the Value of DaaS?

    The SLOs need to be chosen to best fit the requirements of each application. The following are examples.

    Business value can be demonstrated by:
    ROI based on tracking cost savings relative to a benchmark comparing prior non-DaaS, trend cost per developer and per release.
    SLO agility of services – Lead time for changes, and frequency of releases.
    SLO reliability of services – change failure rate, time to restore services.
    SLO governance, compliance and security scores.

    App-dev user value can be demonstrated by:
    SLO availability of DaaS, service level indicators (SLIs) depend on service components and architecture.
    SLO service response time.
    SLO experience scores.
    SLO change request response time.

    DaaS team value can be demonstrated by:
    SLO scope of applications – number of apps supported, number of users per month.
    SLO number of requests served per month.
    SLO critical events per month.

    How Does an Organization Develop DaaS Metrics?

    Start by picking an application that is supported by DaaS. Do not try to boil the ocean and measure all applications at once. Then, appoint a DaaS SLO/SLI team to work on metrics development for the application. The team should include stakeholders from business, app-dev and DaaS support teams associated with the application.

    DaaS SLO/SLI team members determine the SLOs of DaaS that each class of stakeholder values the most, and then decomposes the services to identify sources of data that will form the most important service level indicators (SLIs).

    With the SLIs in hand, instrumentation, telemetry and analysis requirements can be determined and used to design monitoring agents, communication, analyzers, alerts and dashboards.

    Then, roles, policies, playbooks and responsibilities will complete the solution. Test the solution for the chosen application. As you gain confidence in the solution, adapt and expand the solution for use with other applications.

    Continue to monitor the progress and performance of the SLO metrics, and continuously improve them with experience and as newer technologies become available.

    What This Means

    DevOps-as-a-Service provides many valuable capabilities to business, app-dev users and DaaS teams. Metrics that demonstrate value to each class of stakeholder should be determined for each application that consumes the capabilities offered by each unique DaaS. A DaaS SLO/SLI team can determine the best metrics and system design for the implementation for an example application. The SLOs can be adapted and evolved for other applications in the organization, and used as a basis for continuous improvement.