Author: Mike Vizard

  • CircleCI Adds Test Insights Module to CI/CD Platform

    CircleCI Adds Test Insights Module to CI/CD Platform

    CircleCI today announced it has added a Test Insights capability to its continuous integration/continuous delivery (CI/CD) platform to make it easier to identify tests that are either taking too long to run or simply exhibiting some form of anomalous behavior.

    Dawit Gebregziabher, product manager for data insights at CircleCI, said Test Insights is designed to make it simpler for IT organizations to shift more responsibility for testing further left toward DevOps teams that identify issues as applications are being built on the CircleCI platform.

    Each organization will still need to determine what tools to employ to create a test, but once it starts running, the Test Insights module will be able to surface the tests that, for one reason or another, are problematic to execute, he added.

    Test Insights, for example, will flag flaky tests and identify the longest-running and most failed tests. It will also enable DevOps teams to identify performance changes over time to pinpoint changes in application behavior.

    Finally, DevOps teams can track benchmarks at the organization, workflow and job level, as well as metrics for mean-time-to-recovery, throughput and durations for 24-hour, 7-day and 30-day windows of time.

    The challenge DevOps teams often encounter is a test may be run even when it’s apparent the application will fail. Test Insights makes it feasible for DevOps teams to manage the testing process much more efficiently, said Gebregziabher.

    It’s not quite clear how far testing is shifting left. There’s no doubt more developers are testing their code before it is loaded into a production environment to hopefully avoid issues that will only become more expensive to fix later. Other organizations have dedicated software engineers to create testing processes that are tightly integrated with CI/CD pipelines, noted Gebregziabher.

    However, many large enterprise organizations continue to also hire and retain dedicated application testing teams that are trained to identify issues that might either adversely affect the end-user experience or run afoul of compliance requirements.

    Regardless of who does what kind of testing, however, it’s clear there’s a lot more focus on addressing issues earlier when they are much less expensive to fix. The goal should be to make it easier to optimize when tests should run based on probabilities that ultimately reduce the time wasted running tests that either will fail or are, for one reason or another, flawed.

    Developers, of course, are all equally committed to running tests, so organizations will need to determine for themselves how far to shift that process left. However, at the very least, DevOps teams should be able to identify patterns that might indicate there is a need for additional developer training. After all, it’s unlikely a developer is going to understand there’s an issue until some meaningful metrics are shared.

    In the meantime, the more testing that occurs at a faster rate the more likely it becomes that an organization can provide a superior application experience the first time—and every time—an application is built and deployed.
  • InfluxData Simplifies AppDev for Time-Series Databases

    InfluxData Simplifies AppDev for Time-Series Databases

    During an online InfluxDays North America 2021 Virtual Experience conference, InfluxData today expanded the capabilities of its application development tools using its Flux query language on top of its time-series database.

    The company has enhanced its InfluxDB Notebooks tool to enable developers to quickly set up an alert, build a task or write a Flux script without having to leave their browser.

    In addition, developers can compose Flux queries to be included in client code that can then be autogenerated within applications written in more than 10 different programming languages. There is now also an extension of Visual Studio Code that makes it simpler to create Flux scripts, query InfluxDB, create Flux tasks and manage buckets.

    Finally, InfluxData added the ability to explicitly define the schema of a bucket within InfluxDB to safeguard against unwanted changes; an application programming interface (API) tool, dubbed API Invocable Scripts, to make it simpler to define parameterized Flux scripts and the ability to send notifications from Alerta, WebEx Teams and ServiceNow to the InfluxDB Cloud platform.

    Tim Hall, vice president of product for InfluxData, said the overall goal is to reduce the level of complexity developers encounter when building applications that run on a time-series database. Many of those applications are now core to digital business transformation initiatives that require data to processed and analyzed over time. In effect, time-stamped data adds yet another dimension to any application, noted Hall.

    Time-series databases are typically employed by either an independent software vendor (ISV) to create, for example, a monitoring application, or an enterprise IT team that is building an application that lends itself to data that needs to be tracked over some period of time.

    In most instances, applications built on a time-series database are being deployed alongside, for example, relational databases that are generally invoked using SQL. As a result, InfluxDB has made it simpler to join data across relational and time-series data via SQL integrations the company added to Flux, noted Hall.

    DevOps teams, of course, are not always anxious to add another database they need to support, but as applications continue to evolve, more organizations are employing a mix of purpose-built databases to develop applications as the volume of data that organizations are trying to manage and analyze continues to grow.

    In the longer term, it’s clear time-series databases will play a critical role in driving digital business transformation initiatives. The challenge most organizations are now struggling with is determining which of these initiatives to prioritize. A time-series database coupled with the developer tools provided by InfluxData will enable IT teams to build the applications that drive those processes much faster, said Hall.

    In the meantime, IT teams would be well advised to at least become more familiar with time-series databases, because knowing the time when an event occurred is becoming a bigger application requirement. After all, knowing when something happened is now just as important as the record of what actually occurred.

  • Eclipse Foundation Launches Open Source Edge Computing Initiative

    Eclipse Foundation Launches Open Source Edge Computing Initiative

    The Eclipse Foundation in collaboration with the OpenAtom Foundation today launched the Oniro project and working group to create an independent implementation of OpenHarmony, an open source operating system.

    Created by the OpenAtom Foundation, the OpenHarmony operating system is based on a HarmonyOS originally created by Huawei. It is designed to support multiple kernels but uses the Linux kernel if a device has a large amount of memory.

    It also includes a DSoftBus capability for integrating physically separate devices into a single logical super device that enables one device to control others in addition to facilitating data sharing among distributed devices.

    Huawei, in collaboration with Linaro, Seco, Array, NOITechPark and Synesthesia, has also been contributing to a continuous integration/continuous delivery (CI/CD) platform that is part of the larger Oniro project.

    Mike Milinkovich, executive director of the Eclipse Foundation, said the goal is to provide a common layer of abstraction platform that can be employed across a wide range of embedded systems that are typically being deployed at the network edge. That level of fragmentation surrounding platforms that don’t provide a lot of significant differentiated value only results in slowing down the deployment of applications, noted Milinkovich.

    As part of that effort, a dedicated working group has been created to provide a vendor-neutral structure through which contributions to the project can be made with greater transparency. The OpenAtom Foundation was created in Beijing last year with the support of Alibaba, Baidu, Huawei, Inspur, Qihoo, Tencent and China Merchants Bank. The alliance with the Eclipse Foundation brings more traditional governance rules for building open source software to the OpenHarmony project.

    In general, DevOps teams should be tracking the development of proposed de facto standards for edge computing platforms closely. More applications are now being deployed on edge computing platforms that make it possible to process and analyze data at the point where it is being created and consumed. The DevOps challenges associated with building and deploying applications across a highly distributed computing environment are considerable.

    In many cases, organizations that never really attempted or mastered continuous delivery of applications and their associated updates will be sorely challenged when it comes times to support hundreds, possibly thousands of applications, running on embedded systems based on a wide range of processors.

    In addition, many of those same DevOps teams will start to see traditional batch-oriented applications being superseded by applications based on event-driven architectures that process data in near-real-time. In most cases, those applications are going to be built on microservices-based applications that are typically more challenging to build and deploy than a traditional monolithic application.

    Arguably, IT organizations are on the cusp of a new era of IT that assumes most organizations have not only mastered DevOps best practices but are now also embracing DevSecOps best practices to secure those application environments.

    It may be a while before the open source software that will be developed by the Orino project finds its way into production environments, but it should be apparent that reducing complexity at the network edge should be a high priority for all DevOps teams heading into 2022.

  • Mona Allies with New Relic to Converge MLOps and DevOps

    Mona Allies with New Relic to Converge MLOps and DevOps

    New Relic and Mona, a provider of a platform for monitoring the models used to provide artificial intelligence (AI), announced today they have formed an alliance to help bridge the divide between DevOps teams and data scientists.

    Most data science teams today build models based on machine learning algorithms using operations platforms that enable them to manage the life cycle of those models, otherwise known as MLOps. Mona provides a set of monitoring tools that are employed to detect drift that can occur as some of the underlying assumptions that were made when building the model are discovered to be less accurate or when new data sources become available.

    New Relic, meanwhile, provides an observability platform that is widely employed by DevOps teams to monitor and observe an IT environment. IT teams that have access to New Relic One can now also view dashboards provided by Mona that detect anomalies involving data integrity issues and model performance issues.

    The integration also enables users to create custom Mona alerts that are shared via the New Relic Alerts and Applied Intelligence service. That capability reduced the volume of alerts generated by correlating anomaly detection to specific IT events.

    Yotam Oren, CEO of Mona, said that level of integration provides a bridge between DevOps and data science teams that typically have widely divergent cultures.

    Incorporating AI models within applications is the next major DevOps challenge. There is almost no application being built today that won’t incorporate some level of AI. The challenge is AI models are built by data scientists that employ a wide range of machine learning operations (MLOps) platforms to construct those models. The pace at which those AI models are developed, deployed and updated varies widely. However, all organizations will eventually need to confront the problem of how to insert AI models within applications both before and after they are deployed in a production environment.

    There are two schools of thought about how best to achieve that goal. The first is to assume an AI model is just another type of software artifact that can be managed as part of an existing DevOps process. In that context, there may be no need for a separate MLOps platform. Conversely, proponents of MLOps contend AI models are built using pipelines created by data engineering teams working in collaboration with data scientists. Developers only become part of the process when an AI model needs to be inserted into an application environment. AI models may ultimately need to be incorporated within an application, but the proponents of MLOps platforms maintain building models requires a unique platform to manage a software artifact that is built by training algorithms.

    It’s only a matter of time before compliance issues force some form of convergence between DevOps and MLOps teams, noted Oren. The longer it takes to address both the cultural and technical issues that are required to meld DevOps and data science teams, the more challenging it will become as both teams are set in their respective ways.

  • New Relic Acquires CodeStream to Close Observability Gap

    New Relic Acquires CodeStream to Close Observability Gap

    New Relic today revealed it has acquired CodeStream as part of an effort to make observability data more accessible to developers.

    Buddy Brewer, group vice president (GVP) and GM at New Relic said New Relic CodeStream makes application telemetry data collected via the New Relic One platform directly available within an integrated development environment (IDE), now including Microsoft VS Code. In addition, there are also integrations with Microsoft Teams and the GitHub repository.

    The goal is to close an observability gap that exists today between developers and IT operations teams that stems from a lack of developer visibility into production environments, he noted.

    Finally, New Relic is also announcing a core user pricing option for New Relic One that is aimed at developers. Starting at $49 per month, developers gain access to a core set of capabilities such as CodeStream integrations, errors inbox, logs, GraphQL application programming interfaces (APIs) and the ability to build and run custom applications on New Relic One.

    Peter Pezaris, CodeStream co-founder and CEO, now GVP and GM, strategy and developer tools at New Relic, said becoming part of New Relic will make it easier to bridge the divide that exists between most developers and IT operations teams by making it much easier for developers to see how their code is actually executing in a production environment. That capability will eliminate scenarios where code that runs just fine on a laptop executes poorly in a production environment, he added.

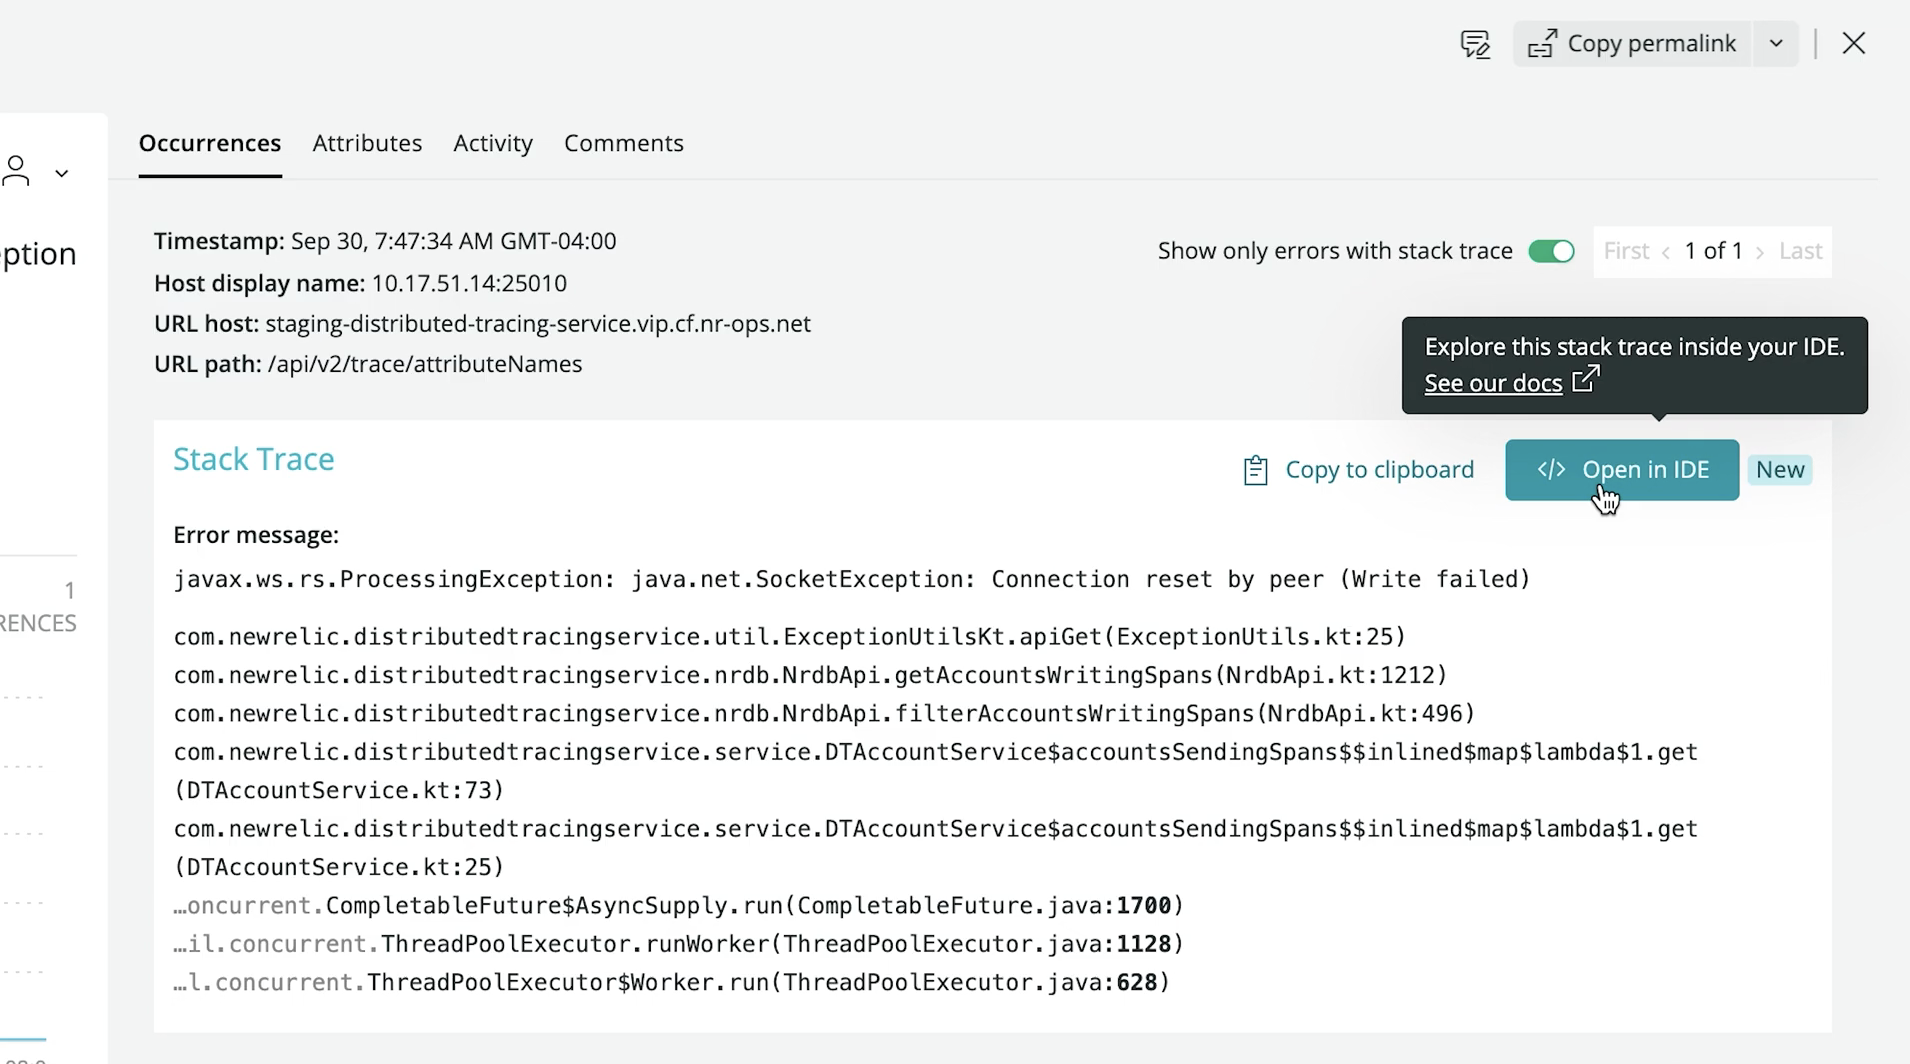
    Developers can also add inline code comments, trigger pull requests, request feedback and track issues directly from their IDE via integrations with a wide range of developer and communication tools. Developers also can switch from New Relic One into an IDE in a single click to navigate, triage and remediate production errors in the context of the code they wrote.

    New Relic is initially making New Relic CodeStream available for free—no credit card required—during a preview period that extends to January 12, 2022. Afterward, some of the more advanced features will require a paid user license once free tier limits are reached. Similarly, IT teams can also sign up for a free New Relic One account without entering a credit card to instrument their applications.

    As the responsibility for managing applications in production environments continues to shift left, Pezaris said it’s critical to give developers the tools they need to optimize code in a production environment.

    It’s not quite clear exactly how much responsibility for applications is shifting left toward developers; it differs from one organization to the next. Many are simply trying to reduce as much friction as possible between developers and their IT operations teams by providing more ‘connective tissue’ from New Relic that IT teams would have to otherwise write themselves, noted Pezaris.

    It may take some time to bridge the observability gap between developers and IT operations teams. Most IT operations teams are still coming to terms with what observability provides that existing IT monitoring tools don’t. Monitoring, at its core, focuses on predefined metrics to identify when a specific platform or application is performing within expectations. The metrics tracked generally focus on, for example, resource utilization. In contrast, observability combines metrics, logs and traces—a specialized form of logging—to instrument applications in a way that makes it simpler to troubleshot issues without having to rely solely on a limited set of metrics that have been pre-defined.

    In theory, at least, that level of observability should ultimately reduce the total number of incidents an IT operations team needs to fix by identifying issues long before they become an actual disruption.

  • Atlassian Survey Shows Lack of Collaboration in Software Development

    Atlassian Survey Shows Lack of Collaboration in Software Development

    A survey of 750 IT and engineering leaders found that while a full 83% of respondents agree that interdepartmental communication is critical for successful software development, only 41% of respondents view cross-collaboration to be a priority.

    The survey gathered responses from within organizations that generated more than $50 million in annual revenue and was conducted by Forrester Consulting on behalf of Atlassian.

    Overall, more than two-thirds of respondents (68%) said more departments than ever are involved with software development. Overall, 80% said they need to improve collaboration with other departments, but 82% don’t feel particularly confident about their ability to accomplish that goal. Three quarters (75%) also noted the need to improve collaboration within their own department.

    Well under half of the respondents (42%) said their culture, processes and tools enable the real-time teamwork and free-flowing information that help leaders make sound decisions.

    Among the subset of respondents that are highly collaborative, however, more than (53%) said they see greater customer satisfaction, with 59% reporting increased revenue because of that increased customer satisfaction.

    Suzie Prince, head of product for DevOps at Atlassian, said the challenge organizations face is finding a way to successfully employ a mix of synchronous versus asynchronous communication mediums to better enable collaboration. In fact, collaboration as part of any DevOps culture needs to be a C-level discussion to consistently accelerate the rate at which software can be developed and deployed, she added. The core issue is that not every management team is equally comfortable with open communications between the various departments that make up an organization, said Prince.

    It’s critical for C-level executives to set that tone and lead by example; DevOps best practices can’t only be adhered to by development teams. The entire business needs to embrace DevOps best practices as an operating model for the business to really attain the maximum benefit.

    Unfortunately, DevOps practices within development teams have been unevenly adopted, so it’s often very difficult to get the rest of the business to embrace DevOps principles. Organizations that do embrace DevOps, however, tend to be much further down the path toward becoming a digital business and can more adroitly take advantage of business opportunities as they arise or shift strategy as changing business conditions may warrant. In fact, organizations that embraced DevOps best practices arguably fared better during the economic decline that followed the onset of the global COVID-19 pandemic that took every business and IT leader by surprise.

    It’s not clear from the Atlassian survey results if a DevOps divide is starting to emerge that makes some organizations more competitive than their rivals. In theory, at least, if every organization is now a software company that happens to build something or deliver a service, then the faster they can reliably build and deliver applications the greater the competitive advantage they can attain and sustain.

    There are, of course, a whole host of factors that determine how competitive any organization might be. However, in the age of digital business transformation, it’s clear that being able to build and deploy software at a fairly regular cadence is the new table stakes required for simple survival.

  • HashiCorp Previews Updates to Consul Service Mesh

    HashiCorp Previews Updates to Consul Service Mesh

    During an online HashiConf Global conference, HashiCorp today made available a beta of an update to its open source Consul service mesh for virtual machines and Kubernetes clusters that makes it possible for multiple administrators to share the same instance of a multitenant service mesh.

    Version 1.11 of Consul will also add support for a command line interface (CLI) for Kubernetes that will provide an alternative to Helm charts for installing Consul on those clusters.

    Raymond Austin, director of product marketing for HashiCorp, said it’s become apparent that there is a need for a higher level of abstraction for managing application programming interfaces (APIs) that is easy to deploy across both legacy IT environments based on virtual machines and cloud-native environments based on Kubernetes clusters.

    Of course, in many cases, those Kubernetes clusters are deployed on top of virtual machines. However, there are also now more instances of Kubernetes being deployed on bare metal platforms at, for example, the network edge.

    As IT environments become more complex, a service mesh makes it simpler to discover, access and secure APIs that are now rapidly proliferating across the enterprise. That transition requires a more dynamic approach to not only managing APIs but also the network services those APIs depend on, added Austin.

    HashiCorp is betting that many IT organizations will prefer to rely on a lightweight open source platform supported by a single vendor rather than relying on more complex open source service mesh offerings being developed under the auspices of a consortium.

    It’s still not quite clear who within an IT organization is assuming responsibility for deploying a service mesh. Most often, it’s a development team that makes the initial decision. However, as IT operations teams become more aware that service meshes represent a capability that needs to be horizontally made available across multiple applications, it may be only a matter of time before some organizations decide to standardize on a single service mesh to reduce operational overhead, noted Austin.

    Service meshes will also play a critical role in simplifying management of networking and security services at a higher level of abstraction within a larger DevOps workflow.

    It’s still early days as far as service mesh adoption in the enterprise is concerned, but there are already a large number of service mesh options. In fact, there may never be a single dominant service mesh platform. Interoperability standards still need to be ratified that enable organizations that have standardized on different service meshes to apply policies to microservices spanning hybrid cloud computing environments.

    Of course, not every IT organization requires a service mesh yet, either. Many IT teams can still get by using a traditional proxy server or an API gateway until the number of microservices-based applications deployed starts to achieve critical mass. One way or another, however, the more APIs there are to manage, the more inevitable it becomes that an IT team will deploy a service mesh.

  • Pulumi Adds Registry to Share Secure IaC Code

    Pulumi Adds Registry to Share Secure IaC Code

    Pulumi this week added a public registry to its portfolio that makes it easier to discover packages that have been created using its tools to manage infrastructure-as-code (IaC).

    Joe Duffy, Pulumi CEO, said the Pulumi Registry will make it simpler for DevOps teams to share and reuse IaC tools that have been vetted versus always requiring each development team to write new code each time they want to programmatically provision infrastructure. Pulumi Packages provide modern cloud reference architectures in the form of software development kits (SDKs), code samples and how-to guides.

    One of the primary reasons that security has become a major cloud issue is that developers often misconfigure infrastructure. The registry provides a way to reduce those configuration errors by making it easier for developers to reuse code written in TypeScript/JavaScript, Python, Go and .NET that they have stored in repositories such as npm.

    In addition to the major cloud service providers, there are also Pulumi Provider Packages for Auth0, CloudFlare, Confluent Cloud, Datadog, DigitalOcean, Docker, GitHub, Kong, MinIO, MongoDB Atlas, PagerDuty, Snowflake, Spot by NetApp and others.

    There are also Pulumi Component Packages for deploying container applications on instances of Kubernetes and other related platforms in addition to deploying applications on serverless computing frameworks.

    Duffy said in addition to providing a “golden image” of their configurations the registry reduces the overall level of friction that often exists between developers, IT operations teams and cybersecurity professionals.

    The latest Pulumi offering is part of an ongoing effort to democratize cloud computing in a way that is repeatable and reliable, noted Duffy. Pulumi, for example, just added support for a set of AWS Cloud Control application programming interfaces (APIs) that reduce the number of APIs that developers would otherwise have to master. The more APIs there are, the more likely it is a developer will make a mistake.

    IT teams should expect that other cloud service providers will similarly streamline the APIs they present developers as part of an effort to make their services both more accessible and secure. In the meantime, frameworks provided by Pulumi provide a means to invoke those lower-level APIs at a higher level of abstraction for both developers and internal IT operations teams alike.

    It’s not clear today how many developers routinely employ IaC tools, but as the number of workloads deployed in the cloud steadily increases, so too does the percentage of developers that employ these tools. While that shift represents a major boon in productivity for developers, it brings with it additional security risks that many organizations fail to appreciate until it’s too late.

    The only way to really solve that issue is for organizations to adopt DevSecOps best practices that require a level of collaboration between DevOps and security teams that is still relatively rare. However, as the tooling provided continues to improve, the technical challenges associated with achieving that goal continue to decline. The next big issue, as always, is bringing together all the diverse cultures within an IT organization to actually implement those tools and define a set of best practices that work for all concerned.

  • Splunk Expands Scope of Observability While Lowering Costs

    Splunk Expands Scope of Observability While Lowering Costs

    During its online .conf21 conference Splunk Inc. today revealed a bevy of updates that advance observability while at the same time reducing the total cost of deploying its platforms.

    As part of that effort, Splunk also announced it will now make workload-based pricing available to all customers.
    Previously, a select number of small customers had access to workload-based pricing while other customers licensed Splunk platforms based on how much data was loaded into the platform. That approach, however, tends to discourage IT teams from loading as much of their data as possible.

    CEO Doug Merritt said workload pricing was created to enable a value-oriented pricing model that customers could employ instead of a data-centric model that can discourage IT teams from analyzing as much data as possible to improve IT operations.

    To further lower total costs, the company is also previewing a Flex Index option for customers that choose workload-based pricing to enable longer retention for lower-value data at a lower cost. Splunk is also expanding its cloud storage to include a preview of SmartStore, which allows larger volumes of data to be stored more cost-effectively on Microsoft Azure Cloud initially with support for Amazon Web Services (AWS) and Google Cloud Platform (GCP) forthcoming.

    Other enhancements to the portfolio include a preview of a data manager, a revamped onboarding tool for data stored in Amazon Web Services (AWS) and Microsoft Office 365, and Ingest Actions, which enables IT teams to act on data in motion in addition to data at rest stored in Splunk or the S3 cloud service from AWS.

    The company is also now making it easier to find and explore data via a federated search tool and a Splunk Dashboard Studio offering, available via Splunk Mobile, that makes it easier to create dashboards.

    At the same time, the company is also making available Splunk Operator for Kubernetes to make it easier to install its platforms in cloud-native environments. There is also now Splunkbase, a curated catalog that makes it simpler to find or develop a Splunk application.

    In terms of observability, the company is providing a preview of AlwaysOn Profiling for its application performance management (APM) platform, dubbed Splunk APM. AlwaysOn Profiling extends existing tracing capabilities to provide continuous code-level visibility and analysis.

    In addition, there is now a preview of an enhanced version of Database Visibility for Splunk APM, which automatically uncovers slow queries that are causing transaction latency without having to instrument a database.

    The company also announced that its real user monitoring (RUM) for mobile applications, which makes use of open source, now is generally available alongside the Splunk Observability Cloud for Mobile platform. The company also revealed there are previews of integration between Splunk Log Observer and Splunk Enterprise and Splunk Infrastructure Monitoring AutoDetect, a tool that automatically discovers infrastructure anomalies. There are also now additional Content Packs for managing Microsoft365, third-party APM tools and synthetic monitoring.

    Finally, Splunk has expanded its security portfolio to include Splunk SOAR App Editor, which provides a way to edit, test and create security orchestration, automation and remediation (SOAR) applications. There are now more than 350 SOAR apps now available on Splunkbase. The company also launched Splunk Intelligence Management based on a platform it gained with the acquisition of TruSTAR earlier this year and that it is making available security services via a team of experts dubbed SURGe.

    It’s not clear to what degree these additions will enable Splunk to fend off what has become a larger number of rival providers of observability platforms. However, as one of the most widely used IT operations management platforms in the enterprise, it’s clear Splunk enjoys an incumbent leader status it is determined to maintain.

  • Splunk Donates eBPF Telemetry Data Collector to CNCF

    Splunk Donates eBPF Telemetry Data Collector to CNCF

    Splunk Inc. announced during the KubeCon + CloudNativeCon North America conference that it donated a data collector to the OpenTelemetry project run by the Cloud Native Computing Foundation (CNCF).

    Splunk’s data collector runs as a sandbox-level program at the kernel of a Linux operating system and takes advantage of extended Berkeley Packet Filter (eBPF) technology to make it simpler to collect networking telemetry.

    The OpenTelemetry initiative itself spans a range of open source tools, application programming interfaces (APIs) and software development kits (SDKs) that are used to instrument applications. Previously, Splunk contributed the SignalFx Smart Agent and Smart Gateway to the OpenTelemetry project along with more than 64,000 code contributions.

    Morgan McLean, a director of product management for Splunk, said that while OpenTelemetry is officially in beta, some elements of the project are more mature than others. For example, tools for capturing metrics and traces are already being employed, while another set of tools for capturing log data will be ready sometime next year, he said.

    The data collector contributed by Splunk is among the first that operate at the kernel level to collect data, added McLean. That approach makes it possible for some types of data to be captured by default rather than requiring developers to always instrument their applications using agents to enable an observability platform. It will also contribute toward the eventual convergence of network operations and DevOps processes.

    Going forward, DevOps teams should expect to employ a mix of open source data collectors that operate at both the eBPF and application level, said McLean. The eventual goal is to instrument every application by default by making it much simpler to collect data. Today, most DevOps teams are employing a mix of proprietary and open source agent software to collect data that then must be deployed and then integrated with all the applications they build. Given the cost and level of effort required, the percentage of applications that are actually instrumented is, not surprisingly, fairly low.

    However, as agent software becomes more readily accessible, the percentage of applications that are instrumented should increase considerably in the years ahead. For DevOps teams that depend on that data to optimize application performance, that capability should prove to be a boon for improving overall observability in IT environments.

    Observability, in one form or another, has always been a core tenet of any DevOps best practice. Initially, DevOps teams focused on continuous monitoring as the most effective way to proactively manage application environments. However, it can still take days, sometimes weeks, to discover the root cause of an issue.

    Monitoring focuses on predefined metrics to identify when a specific platform or application is performing within expectations. The metrics tracked generally focus on, for example, resource utilization. Observability platforms combine metrics, logs and traces—a specialized form of logging—to instrument applications in a way that makes it simpler to troubleshoot issues without relying on a limited set of predefined metrics focused on a specific process or function.

    Those observability platforms then make it possible to correlate events so that it is easier to identify anomalous behavior indicative of an issue’s root cause. Armed with these insights, it becomes a lot simpler for IT teams to resolve issues faster.

    It’s unclear when OpenTelemetry tools will become more widely employed, but as more tools for collecting data become available, the impact on DevOps will be nothing short of profound.