Category: DevOps Toolbox

  • Site Reliability Engineering: How to Make the Operations Side of DevOps Actually Work

    Site Reliability Engineering: How to Make the Operations Side of DevOps Actually Work

    The DevOps movement often has been accused of focusing too much on the first half (Development) and not enough on the second half (Operations). Certainly there has been more attention paid to deployment of payloads than to operating running systems, leading to the dismissal of the handover between Dev and Ops as “throwing it over the wall.”.

    Lately, we have seen the emergence of a new focus on the stability and reliability of the systems that are the targets of those deployments, with the creation of the new practice of site reliability engineering (SRE). This has been a welcome addition to the IT toolbox, but it can still seem to put all the onus on Ops teams to catch whatever comes over the wall.

    The Problem with Site Reliability Engineering = IT Infrastructure

    In SRE, the IT infrastructure is expected to be highly automatic and self-healing in the face of any events. Here is the problem: That approach works well for foreseeable events, but less well for the unforeseen ones. Because of that factor, it works well in environments that run few types of individual workload types, but do so at very large scale. If you’re thinking that sounds like Google and Facebook, you’d be right.

    What this amounts to is massive engineering of the infrastructure to withstand known or foreseeable problems. However, typical enterprise IT environments are not like that. A large bank might have thousands of applications, each of which must accommodate changes on a pace that is dictated from outside the IT environment. Applying assumptions from one environment to the other is asking for trouble.

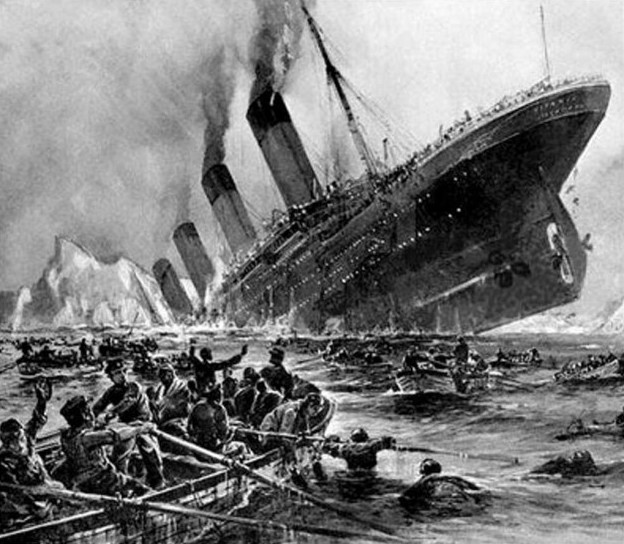
    To illustrate this, let’s look at an example from outside IT. Recently was the anniversary of the sinking of the Titanic, on April 15, 1912. The RMS Titanic itself embodies the principles of SRE, engineered to prevent or survive all manner of emergencies. The ship was equipped with state-of-the-art everything to transport its passengers in comfort and safety across the Atlantic.

    As we all know, that plan did not quite work out. A combination of unexpected changes in the environment (more icebergs than normal), business imperatives to maintain speed and mishandled warnings about the ice from other ships led the Titanic to disaster.

    While the consequences of an IT failure are rarely quite as dramatic as the sinking of an ocean liner, many of the same factors apply. IT administrators may believe that in the worst case their backups and disaster recovery plans will be sufficient to handle any problems, but these plans are designed around known and foreseeable problems. Unexpected circumstances can easily lead to cascading failures, which is why it is critical to be ready for the unexpected when it—inevitably— occurs.

    The Problem with Traditional IT Ops = Static Models

    The key flaw in IT Ops is reliance on static models of the world. These models come in many shapes – the CMDB is the “model” that many think of first, but static rulesets are also a model. The most dangerous models, though, are the ones that are invisible: namely, the filters that are put in place to determine which alerts and events are even worth considering.

    This is the flaw that ultimately sank the Titanic: The crew were unable to correctly priorities events and react to them in time to avoid failure. It is also the flaw that causes countless much more minor issues every day in data centers everywhere: the filesystem that filled up with logs, taking down the database that the critical business application relied on—and the filter that had not forwarded that alert because it usually was harmless. Or the loss of one leg of the redundant network link, which was ignored because the other leg was still up, so there was still a link—until that one failed too, and an entire site went dark.

    The key factor is that the filters were not wrong to suppress those alerts. By definition, informational or warning alerts are not the same as major or critical ones, and most of the time they can be safely ignored, to be dealt with later.

    Every now and then, though, a pattern of those alerts, if understood correctly, can identify a future problem in the making. These developing issues could be nipped in the bud, if only Ops teams had enough hours in the day to look at them and review them. But, of course, they don’t—every Ops team I have ever met is drowning in issues, and behind those there is a long and lengthening to-do list.

    What Can DevOps Do to Make Operations Better

    New approaches are emerging to make the principles behind SRE more widely accessible and applicable. In particular, more dynamic noise reduction and correlation is now possible, to sift those important alerts from the constant background noise and put them together into a picture of what is really happening. The key factor is to be able to do this in real-time and without a human having to plan out laboriously what are all the possible scenarios that they might need to know about in the future.

    Gartner has called this new approach Algorithmic IT Operations, or AIOps. The idea is to bring together all possible sources of events, whether those are alerts from the compute or network infrastructure, transaction slowdowns reported by an APM tool, automated deployments being run from a CI/CD toolchain, or anything else the might conceivably be relevant. All of this information then can be sifted by algorithms to understand what is actually important to Ops and brought to the attention of the right specialists who can work on the issues and get them solved fast. Part of that process is also the integration with systems of record (which generally means IT service management), and with automation and orchestration tools that can accelerate remediation activities.

    This is how we can get the Ops side of DevOps to where they need to be to be able to accommodate the ever-accelerating pace of change—whether from Dev teams wanting to run ever more frequent deployments, or from business users needing help with their own goals—or from the next unexpected issue to come down the line.

    — Dominic Wellington

  • The Postman Delivers More

    The Postman Delivers More

    Most of us use Postman during API development. The company claims 3 million users, and as one of them, that number doesn’t raise my eyebrows any. But if you are like me, you’ve figured out collections, how to back up your data and perhaps looked at tests, but not done much more. As a tool for API development, Postman is powerful and useful, but that means many of us don’t look very far beyond how quick and easy it is to set up an out-of-browser test environment to evaluate request/response.

    We use collections to separate projects, but really only as a way to group calls together and keep a single copy of each call close to hand while the history list scrolls through multiple copies.

    But for DevOps, there’s more. And they’ve just added to it again.

    Packing in the Features

    Groups can be used for grouping calls with tests, for example, and a command line tool can perform automated testing. If, like us, you use Postman to test as the API is developed, and use groups to keep those calls pulled together in one place, then testing from the source that already contains your entire API makes sense.

    And as of this week, Postman also includes the server side. Postman Mock service allows you to mock up the API calls and specify a valid return value. That means client-side developers can use Postman Mock for testing their app/page, while server-side developers are using the original Post

    man to develop the APIs that Mock emulates and testing is running tests from the real-world APIs that already are in Postman for development purposes.


    Dev, DevOps, Testing and Ops: Something for Everyone

    So a quick diagram shows that the entire development process has a bit of Postman in it if that’s your tool of choice:

    While all assist with agile development, for DevOps, the pieces that are the most beneficial are Test combined with Groups and the new Mock service. As long as the Mock service is configured for a group of calls, test can call them and the logged output can reflect that the test succeeded but ran through the mock service. Once the service is completed and the group is directed to point at the server, testing will run tests against the real API. Using Newman, the command line tool, these tests then can be integrated with your build toolset.

    The Mock service can take imports from SOAPui, if you are converting from SOAP calls or use SOAPui for REST and are moving to Postman. I’m told the Postman toolset also supports SOAP calls, but truth in writing, I’ve never even looked to see how that would be done. I’ve used both tools, but never on the same project.

    There’s a Cost, but There’s Also Value

    This next bit sounds a bit salesy, and I try not to do that. But for the price, there aren’t a lot of value-add tools out there that deliver this kind of value. Lori and I are talking about going Pro, as we both use Postman in projects. And considering we’re regular users, I figured if we didn’t know about most of these features, many of you wouldn’t, either.

    Mock is part of Postman’s Pro package, along with sharable team collections, and API documentation tools. That means it will cost you a little bit of money, but if you’re on a team and have been cobbling together a way to share collections, team collections and associated collaboration tools are worth the price—particularly since built-in auditing will show all of the changes made to Postman collection items. That means fixing a change-based error on the Postman side is easier.

    As of this writing, the cost for Postman Pro was $8 per user per month. My guess is sharing groups (or worse, each team member re-creating/maintaining them) costs more than that per month in many cases. Consider that documentation can be generated and shared to a private URL and the fact that Mock service enables parallel development, and $8 sure seems like a steal. Finally, Pro offers API monitoring, so performance and uptime can be tracked to better adjust to the realities of production. There’s more (such as integrations with some great Dev/Ops/DevOps tools), but I’ll stop.

    Summary

    Design, Development (both client and server, in parallel), Test, Monitoring … as long as you can get it deployed, Postman can help with the rest. Postman Pro has a reasonable price for the functionality it offers, and the introduction of the mock service makes agile development, tight timelines and consistent “start to deployment” testing easier. I’d venture to say it is worth taking a look at. And if you’re developing APIs without it, pop out and get the free version, you’ll quickly find why so many of us use it.

    You can find out more about the various editions of postman on Postman’s Product page.

    — Don Macvittie

  • AppDynamics Extends Performance Monitoring Reach to Developers

    AppDynamics Extends Performance Monitoring Reach to Developers

    AppDynamics, fresh off its acquisition by Cisco Systems, this week moved to extend the reach of its monitoring services all the way out to individual developers.

    The spring 2017 edition of the AppDynamics service now includes a developer toolkit intended to make it simpler for developers to track the performance of their code without having to get that data from an IT operations team.

    Matt Chotin, senior director of Developer Initiatives for AppDynamics, said the goal is to respond to the needs of developers who, in the age of DevOps, increasingly are being held accountable for the performance of their applications end to end. The toolkit enables those developers to directly invoke application programming interfaces (APIs) exposed by AppDynamics.

    The toolkit also provides additional AppDynamics support for the Go programming language, the Xamarin framework used to develop mobile applications and a plugin for Android applications. Now also available are dashboards for tracking individual session and crash alerts and reports that make it possible for developers to discover the root cause of a potential issue much closer to the time it occurs.

    But Chotin said the most unique attribute of the AppDynamics release is that developers can apply diagnostics to business transactions in two modes. One mode enables developers to examine code in pre-production and production environment, while another—a Live Mode—can be used against live application data.

    In addition to extending its reach out to developers, AppDynamics is making it easier for IT organizations to deploy its agent software. A new Universal Agent makes it simpler for the AppDyamics controllers to distribute those agents. Chotin said AppDynamics is also working on developing lighter-weight agents that would be used to provide better support for containerized applications.

    Finally, AppDyanmics is also simplifying its software licensing model in a way that enables sharing subscriptions.

    While AppDynamics has developed an extensive following among IT operations teams, reaching out to developers represents a new frontier. As responsibility for application performance shifts in the age of DevOps, Chotin said AppDynamics is discovering the developers want to be able to access directly the metrics that apply specifically to their code. Instead of being presented with information about every application running in the environment, developers want to be able to zone in on any and all issues affecting their specific code, he said.

    Obviously, not every IT organization is implementing DevOps processes to the same level of zeal. In many cases, IT operations teams are still mainly held responsible for application performance. But as the line between those IT operations teams and developers continue to blur, any move to embed instrumentation functions deeper into the application code base stands to benefit everyone. Of course, not every developer might be excited about being required to do that initially. But once they discover that the time between when there’s an issue and they can go back to writing code starts to drop, AppDynamics is betting that many of them are likely to insist on that level of instrumentation being available.

    — Mike Vizard

  • Testing: Your Secret Weapon for DevOps Success

    Testing: Your Secret Weapon for DevOps Success

    I spend virtually all day, every day, speaking with IT leaders who recognize that their bottom line ultimately rests on their ability to accelerate the delivery of innovative software. That’s why they’ve invested so much in digital transformation initiatives—including hiring the best and brightest developers, scaling Agile, driving DevOps adoption, automating the continuous delivery pipeline, and all the other components involved in moving from ideation to delivery as rapidly as possible.

    In most cases, this investment has exposed opportunities to optimize culture, process, and tooling—but not yet delivered the level of acceleration and flexibility that IT leaders expect. I’m frequently asked: “Now what? I think we’re ‘doing’ DevOps. But what else is needed to deliver on faster innovation?”

    Something as unsexy as “transform testing” is not what people expect to hear. As someone who’s been in the software testing industry since 2003, I know that software testing is typically seen as a necessary evil, not a strategic advantage. However, I’ve also witnessed how it can be a secret weapon for surging ahead of the competition.  

    The dirty little secret in the IT industry is that despite all the advancements in software development, software testing remains dominated by yesterday’s application lifecycle management (ALM) tools and manual testing—and they simply don’t meet the needs of today’s accelerated development processes. Transforming testing for the modern era represents a tremendous opportunity. It’s a low-hanging fruit that can help you increase acceleration, reduce risk and cut costs.

    Boost Acceleration

    Agile and DevOps initiatives aim to accelerate the process of delivering working software to the end user. However, even organizations that have adopted Agile and DevOps report dismal test automation rates: less than 20 percent for end-to-end testing. This means that after the rest of your software delivery pipeline is automated and optimized, an outdated testing process eventually emerges as the bottleneck. By transforming testing, you can increase your throughput significantly. I’ve witnessed many companies increase time to market by 55 percent by modernizing their testing process.

    Reduce Risk

    Now that software is the primary interface to the business, a software failure is a business failure. Yet, with today’s compressed and continuous delivery cycles, it’s simply impossible to test everything before every release—even if testing is automated. By aligning testing with your top business risks, you can automatically assess the overall impact to the core user experience and instantly determine if the release candidate has an acceptable level of business risk. This is critical for stopping high-risk software from impacting your prospects, customers, and partners.

    Companies still relying on traditional quality processes and platforms are usually covering only about 10 percent of their top business risks with their current test suite. A goal of 80 percent is typically achievable with about three months of effort.

    Cut Testing Costs

    There are hard costs associated with trying to retrofit outdated testing processes and tools into modern delivery processes. Many organizations try to bridge the testing gap by throwing an abundance of manual testers at the problem, typically through a global system integrator. By the most recent estimates, this approach consumes approximately 35 percent of an average IT budget—a total of $30+ billion per year, globally.

    A way to help testers achieve high test automation rates allows you to reallocate a large portion of that testing spend toward creative tasks which advance competitive differentiation. Many enterprises that transitioned manual testers into “scriptless” (non-technical) test automation have slashed testing costs—and eliminated one of the most significant constraints to achieving faster time to market.

    Get the Analysts’ Perspective

    Analysts at Forrester (e.g., Diego Lo Giudice) and Gartner (e.g., Joachim Herschmann and Thomas Murphy) have spent years advocating that transforming testing is a business imperative. If you’d like to get their perspective, I encourage you to review some of their latest research:


    About the Author / Sandeep Johri

    Sandeep Johri, CEO of Tricentis, has more than 25 years of experience as a technology executive and serial entrepreneur—including roles at Hewlett-Packard, Appcelerator, Oblix (acquired by Oracle), Blue Lane Technologies (acquired by VMware), and numerous other startups in Silicon Valley and India. Johri earned an MBA from Stanford University, a Master’s degree in Industrial Engineering from Wayne State University, Detroit, and a Bachelor’s degree in Mechanical Engineering from Pune University, India. Connect with him on Twitter.

  • DevOps Chat: The Evolution of APM with Jonah Kowall, AppDynamics

    DevOps Chat: The Evolution of APM with Jonah Kowall, AppDynamics

    In this DevOps Chat we speak with Jonah Kowall, VP of Market Developments and Insights at AppDynamics. Of course prior to that Jonah was a VP of Research IT Operations at Gartner. Jonah actually gave us a great overview of the evolution of APM  and how the market has evolved. He also tells where we might be heading now.

    It is not often you can get the lay of the land from an expert like Kowall, so I highly recommend you give this a listen.

    As usual, immediately below is the streaming audio of our discussion and below that is the transcript of our conversation.

    Streaming Audio

    Transcript of the Conversation

    Alan Shimel:                Hi, everyone. Alan Shimel, staging-devopsy.kinsta.cloud here for another DevOps Chat. Our guest on this episode of DevOps Chat is Jonah Kowall of App Dynamics. Jonah, welcome to DevOps Chat.

    Jonah Kowall:             Thanks, Alan. Happy to be here—great to speak with you and everyone else listening.

    Alan Shimel:                Thank you. So Jonah, before we jump into App Dynamics, you have a—you’ve had a bit of a career already. Why don’t you share with our audience a little bit about kinda your journey to how you got here today?

    Jonah Kowall:             Yeah, definitely. Well, I always knew I wanted to be a technologist and, for many years, I worked at about six or seven different startups. I co-founded one of the first content filtering companies back in the early 2000s and, you know, got acquired a couple of times.

    And I kinda shifted careers a few years ago, about seven years ago, and moved into the analyst world and kinda moved away from running ops and security and infrastructure and application performance and decided to take the analyst path, and did that for about four years, which was very interesting and different, learned a lot of new skills, a lot of new muscles were built.

    And I joined App Dynamics a little bit over two years ago, and I work with our       co-founder and CTO running product strategy. I do a little bit of marketing, but quite a bit of product management and kind of looking into where we’re going as a company to solve the next generation of problems that we’re starting to see in our customer base.

    So that’s a little summary of where I came from and however you’d like to take it is great.

    Alan Shimel:                Sure. I guess the real question is, do you know where you’re going, but we’ll come back to that in a second.

    Jonah, as I spoke to you offline about, I wanted to talk to you a little bit about what I have seen, you know, as an observer of the market at staging-devopsy.kinsta.cloud. In terms of the evolution of what used to be just a few years ago, a very kinda stable space called APM, right? We had, the APM space had a handful of players—App Dynamics was certainly one of them—who were, by the way, all doing pretty well, it seemed.

    And what we’ve seen in the last few years is, you know, in the—first of all, more people joining the fray, but more than that, in the race to distinguish one from the other, many players within this space are kinda rephrasing their mission, their—not running away from APM, but their APM plus, maybe. And so we’ve seen, you know, alphabet soups of ARAs and a whole bunch of different combinations.

    What’s your take on that, Jonah?

    Jonah Kowall:             So, when you look back—and, you know, when I started at Gartner, there was a lot of confusion around application performance and application monitoring. And there was like a general belief that anything that monitored some kind of application or even monitored the network and tried to extract application information was, in fact, APM.

    And what I kind of tried to do in my time at Gartner, and I think it sort of changed some things, was really focus APM on instrumentation of applications. So, how do we see the code, how do we get inside the application, how do we trace from end to end and really provide that visibility and the diagnostic capabilities that are really gonna be needed in today’s applications, which are incredibly complex and diverse, and consist of a lot of new technologies?

    So, building that kind of visibility is really hard to do. I mean, if an APM company—and there are plenty of them that have started over the last couple years—they have many, many years before their instrumentation becomes decent, if they’re even going down that path. And the ability to extract information from a running application, without breaking it, is very, very difficult to solve. It takes a lot of time, a lot of experimentation, a lot of work with customers.

    And so this market is very hard to enter into and compete with the three leaders in the space. It’s just a big challenge, and you’re looking at five to six years before these things mature, if they continue to pursue them. So what you’re kind of seeing, and what you alluded to, is that companies are trying to take a different angle and avoiding the deep instrumentation and just trying to provide SVKs and tools for developers to build those, you know, that visibility. But it’s a big challenge, because in enterprise and packaged applications, those products don’t work, and that’s really the challenge that I continually see out there when I observe the industry.

    Alan Shimel:                Got it. So, you know, certain—I’m sorry, Jonah, I have a little tickle. App Dynamics, you know, in, let’s call it an immature industry, rapidly become an 800 pound gorilla, and I think we’ve all seen the proof of that in recent news around acquisitions and so forth. But I’m not gonna go there, Jonah—suffice to say, App Dynamics is a market leader in its space.

    How does this evolution, if you will, changing dynamics, you know, you said you’re working on future problems—how do you think this plays into the future of App Dynamics?

    Jonah Kowall:             Yeah. Well, I think that applications and technologies will continue to evolve, and you know, we’re already starting to see a lot of new application paradigms that we’re gonna have to shift a lot of our core technology to support and to essentially leapfrog what the rest of the market is able to do, and we’re hard at work doing that.

    But aside from the deep, you know, introspection of software, there is also a big push for us to really understand the business, because today’s enterprises, regardless of what they do, whether it’s extracting natural resources from the earth or building cars or providing mortgages—these companies are all software companies, and their businesses depend and are driven by their software. And our goal is really to understand the business execution and the user experience of those transactions that are critical. And, in kind of taking that to the next level is really, how do we look at the outcome of software and of these business transactions as they come together.

    So, our vision is not only to increase our capabilities of the core of what we do in APM, but also to really provide a lens into the business that really provides that IT business alignment that everyone talks about and everyone struggles with today. So we really see that as the differentiator in these large enterprises that are really challenged with a lot of legacy and a huge amount of demand to change their businesses.

    Alan Shimel:                Got it. Got it, got it. So, Jonah, let me pivot a little bit to, there was another area I wanted to touch on with you, and that is this whole area of containers, micro-services—but containerization. Virtually every call, every briefing that I’m on, somehow or another containers make their way into the conversation. How big a focus is it over in the, in terms of product and in terms of the strategy at App Dynamics?

    Jonah Kowall:             Yeah, I mean, micro-services and containers are definitely the peak hype, let’s say, of the day—there’s no question about that. And they provide a lot of benefit, but a lot of people really feel that containers and micro-services are the answer to every problem. And this is something that we’ve seen over and over in our industry where, you know, there’s a new kind of angle to an existing set of technologies that we feel is really gonna make the biggest difference. And although containers and micro-services are both important paradigms, they’re not the answer to everything.

    Our customers are clearly retooling some of their applications around a micro-services architecture, and they’re definitely running workloads on containers, and these things are important for us to support, but are they more important than, you know, building core functionality to support new languages and new frameworks and really helping our customers with their more core business problems. It’s hard to say. I mean, both are clearly critical, but a lot of it is hype, and you know, the hype obviously fades as people become disillusioned with the fact that containers and micro-services don’t solve all your problems. They create a lot of new problems, and that’s just the reality of technology.

    So, as an industry, we’re very over rotated to containers, micro-services, and public cloud, and you know, we’ll soon realize those aren’t the answer to all of our problems—and oftentimes, they create new problems, as well. So, you know, I think it continues to be a cycle and, you know, I really think the evolution of cloud into a decentralized model will be a pretty interesting trend over the next, you know, 5 to 10 years as well.

    Alan Shimel:                Got it. I think we’ve barely scratched the surface. You know, Jonah, I was on a call previous to this and it was around software defined storage and networking and stuff, and it just—listening to it, I had such a déjà vu of sitting back in on the VMware stuff, you know, back in, I guess mid-2005, around then.

    Jonah Kowall:             Yep.

    Alan Shimel:                It just seems to promise so much change for us here; it’s crazy.

    Jonah Kowall:             [Laughter] It always does, and you know, it comes with challenges, always, and people become kind of disillusioned, but there are benefits to those that embrace it, do it well, and you know, have the types of problems that those technologies can solve.

    Alan Shimel:                Yep. Excellent. Well, Jonah, we’re just about up on our time. I’m gonna give you a surprise question here, if you don’t mind—if you can’t answer, that’s okay.

    Jonah Kowall:             Sure.

    Alan Shimel:                But I usually ask, the last question I always ask my guest is—recommend one book to our audience that you really think they should read to help them with their careers.

    Jonah Kowall:             That is an interesting one. I actually tend to, I do a lot of traveling. I actually flew over 200,000 miles in 2016.

    Alan Shimel:                Wow.

    Jonah Kowall:             So, when I actually get to read, I tend to read lighter materials, or I read very deep, technical materials that kind of help with some of the product work that I’m doing. So a lot of the books I read tend to not be too inspirational, but I do really enjoy participating in some of the open Slack communities. I enjoy reading a lot of blogs and other content that tends to be fresher.

    Alan Shimel:                Mm-hmm.

    Jonah Kowall:             You know, I read probably about 500 blogs in my RSS feed regularly, so that tends to really be how I get information, and I do really enjoy reading some of the Google Scholar, if you set some interesting alerts up, you can get some great research papers coming out from universities that are very interesting and forthcoming, just kind of highlighting some of the next generation thinking from the educational institutions all over the world.

    So that really tends to be more what I tend to read versus, you know, something that’s more career focused, I would say, or inspirational in that manner. So sorry I don’t have the best answer, but that’s what I tend to do.

    Alan Shimel:                No, no—that’s fine, and that works for us. Well, Jonah, I think we—well, we are out of time, but I want to thank you for joining us today on DevOps Chat, and I look forward to perhaps having you on again in the future.

    Jonah Kowall:             Sounds great. Thanks for your time, Alan, and thanks, everyone, for tuning in

    Alan Shimel:                Thank you. Jonah Kowall, App Dynamics, our guest today on DevOps Chat. 

                                        This is Alan Shimel for staging-devopsy.kinsta.cloud, and we hope to see you soon on another DevOps Chat.

    — Alan Shimel
  • 6 Big, Bad Mistakes in Configuration Management, Part 2

    6 Big, Bad Mistakes in Configuration Management, Part 2

    In Part One of my article on big, bad mistakes in configuration management, I reviewed the dangers of using the wrong tools for the configuration management job. Provisioning management tools, application release automation tools and continuous integration tools each have their place in your DevOps toolchain. But they should not be used as a substitute for ongoing configuration management. In this article I am focused less on misusing tools and more on bad practices, limited thinking and short-sightedness that should be avoided.

    Mistake No. 4: Direct Server Access to Production

    This one may not bite you … until it does. I’ve worked with many companies where developers have direct access to Production. This is not good. And, in many cases, it is a violation of compliance policies. Please don’t take offense, my developer friends. You shouldn’t want direct access to Production. I find that 9 times out of 10, your code is not the problem—the configuration is the problem. However, you’re being asked to log directly into the server to do comparisons between your environment (where it worked just fine) and Production. This leads to the, “How did he fix it?” problem, and it leads to the dreaded typos and other manual errors. I’ve witnessed companies lose millions of dollars in a matter of minutes because someone logged directly into a server and made an incorrect configuration change.

    The question is, How do you cut off direct access to Production? How do you quickly find configuration differences between environments without logging into the server? The answer is a good configuration management solution that quickly shows differences between the environments for all your tiers. This is easy when you’re doing file-to-file comparisons, but what about registry key comparisons, or WebSphere comparisons? Find a configuration management tool that gives you visibility fast, exactly when you need it, for the important parts of the stack that keep your applications running. And insist on a configuration management solution with robust RBAC (role-based access control) over what changes can be made, where and when they can be made, who can make them and even who can approve them.

    Mistake No. 5: Leaving Your DBAs Out of the Picture

    The majority of companies I work with have completely disconnected database and middleware teams—the DBAs don’t really know what the middleware team is doing and the middleware team has no visibility into what the DBAs are doing. I believe there are a couple reasons for this: people and technology. We won’t worry about the people aspect today, other than to say that each team thinks the other team is “quirky” J. From the technology aspect, traditional tools simply do not provide configuration visibility into both the middleware and the database tier. So the DBAs end up having one toolset, and the middleware team a completely different toolset. This prevents collaboration, orchestrated releases, and the complete configuration picture that’s needed to make sure your application is fully configured, performing, and running correctly.

    This is a big problem. In fact 37 percent of survey respondents admitted that they relied on scripting and manual processes to determine which databases were used by which applications in their ecosystems. And another 38 percent admitted they don’t even have a way to determine this information. Talk about blindfolds! My advice is to find a solution that both middleware and database teams can use. That doesn’t necessarily mean the DBAs will replace their favorite tools, but they’re now involved in the process, allowing that collaboration and orchestration that was missing.

    Also, if you use a single, integrated configuration management solution your management, middleware, OS and DBA teams will all have visibility into every aspect that makes the application run. The middleware team can see if there are schema changes that may be causing an application issue as opposed to spending hours looking for a middleware configuration issue they’ll never find, or vice versa. Having one unified tool cuts down on the mean time to diagnose because you can see all the tiers in one place.

    Mistake No. 6: Focusing Only a Single Part of the Stack

    The previous “big, bad mistake” segues nicely into this one: focusing on just a single part of the stack. There are many tiers supporting your application, and we’ve touched on several in this series—namely middleware, database and OS. Within each tier you may be supporting different technologies. Some applications may be running on IIS with a SQL Server back end while others run on WebSphere with an Oracle back end. Then you have the operating system settings to worry about: making sure registry keys are set, system services have the right accounts, filesystem permissions are accurate, all the correct versions of Linux packages are installed, etc.

    Based on a lack of comprehensive coverage up and down the application stack, many companies have chosen to explore configuration management tools for just a single part of it. These point tools tend to focus on the most business-critical applications, the one where they hit the most configuration issues or simply the one that’s most difficult to manage. This is not necessarily a bad thing to do, but take care not to be too single-minded. Try not to choose a configuration management solution that works well for one part of the stack but not others, or that works very well in one environment (Linux/Unix), but not very well in another (Windows). Managing these disparate point solutions, with maddening gaps and overlaps in coverage, can be exhausting.

    Choose a tool that’s extensible to other parts of the stack, business or other teams. My suggestion is to make a list of all present and future technologies you use that need configuration management support. Divide them into different parts of the stack and then rank them from “most onerous to manage and/or most business critical” to “nice to have.” Refer to this list when evaluating configuration management tools so you don’t lose sight of the forest from the trees. Make sure the tool can support all your top items and ask about their road map for your “nice to haves.”

    Tune into our upcoming webinar, which will touch on these topics as well.

    About the Author / Kristy McDougal

    Kristy McDougal leads Product and Sales Engineering for Orca, an application release and configuration automation solution for DevOps teams. Prior to launching Orca, Kristy was a Senior Pre-Sales Consultant within BMC Software’s worldwide DevOps specialist team. Before BMC, Kristy held technical positions at VaraLogix, Virtual Bridges, Global Foundries and Advanced Micro Devices. Her experience includes Unix systems administration, systems engineering, pre-sales consulting and post-sales services. Kristy is ITIL Foundation-certified and is an electrical engineering graduate of the University of Texas at Austin.

  • 6 Big, Bad Mistakes in Configuration Management, Part 1

    6 Big, Bad Mistakes in Configuration Management, Part 1

    Configuration problems come in many flavors. Some are mere nuisances. Often though, configuration errors can lead to more serious mishaps like application performance problems, policy compliance violations or even security vulnerabilities. They can often go undetected, quietly doing their damage in the background while everyone’s attention is focused elsewhere.

    Unfortunately, I find that configuration management is an area where many companies either 1) put it as a “last to solve” on their priority list (when arguably it’s quite important), or 2) try to solve it with a do-it-yourself fix, but in a way that’s not always extensible or that doesn’t end up working with their DevOps toolchain.

    Usually, I find configuration issues stemming from the age old problem: using the wrong tool for the job. In this blog I’ll address six big, bad mistakes of configuration management. (For the sake of brevity, three will be addressed here and three in an upcoming blog.)

    Before I get into it, though, there are so many definitions of configuration management that it warrants a brief summary so we’re all on the same page. I’m talking about the ongoing configuration management of the infrastructure tiers supporting your applications—the middleware, database and OS-level configurations that keep your applications’ lights on and everyone happy.

    Mistake No. 1: Only Considering Provisioning

    Notice I just mentioned the word “ongoing” in my definition of configuration management. I find that so often people forget to take the ever-important “ongoing” into consideration. I have many conversations with folks wanting to implement a “provisioning tool.” On the surface, they think they need just that: a tool that provisions infrastructure including all the tiers of the application. But when I probe further, what they’re really wanting is something that provisions and then continues to monitor, manage and fix. There’s a big difference there.

    Some tools do great at provisioning but lack the visibility and “ongoing” configuration management needs. Think of a provisioning tool as waving a bat at a piñata. Yes, you can “blow away your environment” and start over, but that blindfold prevents true visibility and ongoing interaction.

    When looking for configuration management, be sure to focus on your current and future needs. Do you just need a provisioning tool? Or do you need an ongoing configuration management tool? Or both? Most tools that tout doing both do one much better than the other, so be sure to do your research.

    Mistake No. 2: Using an ARA Tool to Manage Configurations

    In a previous position I spent quite a bit of time onsite with clients helping them automate their application deployment processes. What I found is that around 80 percent of “application deployment” tasks are actually configuration tasks. The application deployment is the easy part; it’s the configuration management aspect that causes all of the headaches. I would spend the majority of my time onsite hurriedly writing little scripts that would be hurriedly inserted into the deployment process that would set the application pool, restart the service, change a heap size, etc. I had to write the scripts because application deployment products are workflow automation engines with process wrapped around them. They are not meant to be infrastructure configuration management products.

    It bears repeating: Traditional application deployment solutions are not meant to be infrastructure configuration management products. They can get you part of the way there, but 1) you’ll need to script it all, which is not extensible and defeats the true purpose of a tool, and 2) they simply catapult your application (one way only!) into the next environment (i.e. Test to Staging, Staging to Prod), so you can forget about the “ongoing” piece we discussed above. Compare that one-way catapult launch to the complexity of routinely engineering one safe launch (and landing!!!) after another on an aircraft carrier on the open seas. A mission-critical task like this requires advanced technologies, visibility, communication and coordination to account for constantly changing environmental factors.

    Mistake No. 3: Using a CI or Build Automation Tool When You Need Configuration Management

    As bad as misusing an application release tool when you really needed a configuration management solution, it’s even worse using a continuous integration tool for this. Like many DevOps solutions, CI tools are particularly helpful for developers. CI tools like Jenkins and Bamboo require Dev teams to share or check in their updated code into a repository. The CI tool then detects potential problems early by automatically verifying builds for the developer. From the Dev team’s perspective, there is no more wondering if their code is going to work, and they spend less time debugging and redoing. The financial benefits of CI and the early warning system they provide should be obvious and considered a must-have for developers.

    But while detecting coding errors early saves a lot of hassle for the Dev and Test teams, Ops teams do not directly benefit from CI. Here’s why: Operations teams are concerned with the application release into Production environments and then the ongoing configuration management of the entire application stack including the application, middleware, database and operating system. Once the (application) baton is passed to them, they require visibility into and intelligence about the application’s operating environments—well after Dev and UAT. As good as they are for Dev teams, CI tools are simply not equipped to provide ongoing operations support, visibility and coordination in Production that modern Configuration Management solutions provide.

    These are just a few big, bad mistakes in configuration management and they focus largely on misusing tools beyond their intended scope. I will follow up with a Part II companion article that addresses configuration management practices to be avoided.

    Tune into our upcoming webinar, which will touch on these topics as well.

    About the Author / Kristy McDougal

    Kristy McDougal leads Product and Sales Engineering for Orca, an application release and configuration automation solution for DevOps teams. Prior to launching Orca, Kristy was a Senior Pre-Sales Consultant within BMC Software’s worldwide DevOps specialist team. Before BMC, Kristy held technical positions at VaraLogix, Virtual Bridges, Global Foundries and Advanced Micro Devices. Her experience includes Unix systems administration, systems engineering, pre-sales consulting and post-sales services. Kristy is ITIL Foundation-certified and is an electrical engineering graduate of the University of Texas at Austin.

  • Getting the Most Out of QA in Complex Environments

    Getting the Most Out of QA in Complex Environments

    We live in a world in which software is increasingly dominant. Not only do we rely ever more on software, but its complexity is becoming even greater. And with increased complexity, bugs are more likely to be intermittent, making failures difficult to reproduce. Sometimes this non-determinism results in failures never getting fixed. Any unfixed bug is potentially a security breach or catastrophic customer outage waiting to happen. With such risks on the line, ensuring your software is of the highest quality is essential to running a successful operation.

    To cope with this complexity while still providing some assurance of delivered software quality, the DevOps industry has embraced a variety of automated testing regimes. A development team of a given size is able to run many more tests than it could before and must triage, and attempt to resolve, a correspondingly larger number of test failures. Diagnosing the cause of each test failure can still take a lot of time, particularly if the problem is intermittent or otherwise not easily reproducible. In fact, developers can spend on average as much as 50 percent of their programming time debugging, not coding. Think of all the innovation that could occur if that time were reallocated.

    Traditional QA

    When it comes to Quality Assurance (QA), developers and testers are all aware of the sequence of deliverables, beginning with development delivering an untested product to QA, which releases the tested and approved product to the end user. However, when a bug is found, QA and Development must communicate with one another to solve the issue quickly. The effectiveness of the delivery channel between QA and Development hinges on the quality of the information about the failure.

    Some common challenges raised by inefficient QA processes include:

    • Complex control flow – Difficult to make inferences about how a failure unfolded
    • Non-deterministic failures – Hard to reliably reproduce a failure to investigate the root cause
    • International R&D – Collaboration is made more difficult by geographic separation

    Conventional test systems inform that there is a bug but offer limited information about the cause. Workflows such as continuous integration (CI) often offer clues, such as informing which commit to the codebase caused the failure. However, there are several cases where CI cannot directly help identify problematic code changes. For example, the triggering code change may be entirely correct, yet cause a pre-existing bug to manifest. The developer cannot simply stare at the modification in the expectation that the source of the bug will eventually appear. Conversely, the failure may not easily reproduce for the developers even if they run the same test again. In short, CI is often very good at making the easier bugs very easy to fix, but typically is of little help with the more difficult bugs, particularly intermittent ones.

    The Next Evolution of QA

    To bridge the gap between identifying a failure in the QA process and resolution by development, DevOps teams have adopted a variety of technologies to complement their automated testing setups. New to this scene is technology capable of recording all or part of a program’s execution for subsequent replay and analysis, capturing test failures as they happen. The recording contains all the information a developer needs to understand the exact set of conditions that led to the test failure. It can be analyzed on different machines to the one on which the failure occurred, facilitating collaboration between colleagues who can work on separate machines to resolve the same issue—a particularly useful benefit for large software companies with geographically distributed teams. By gaining the ability to debug an exact replica of the failure, developers immediately reduce the time and effort required to diagnose and fix failures, therefore speeding the development cycle.

    Being able to generate recordings of failed tests, especially those intermittent issues which might not otherwise get fixed, coupled with the productivity gains of increased collaboration between development and QA allows companies to maintain a competitive advantage in a volatile marketplace.

    About the Author / Greg Law

    Greg is the co-founder and CEO of Undo. Greg has 20 years’ experience in the software industry and has held development and management roles at companies including the pioneering British computer firm Acorn, as well as fast-growing startups, NexWave and Solarflare. Greg left Solarflare in 2012 to lead Undo as CEO and has overseen the company as it transitioned from the shed in his back garden to a scalable award-winning business. Greg holds a PhD from City University, London, that was nominated for the 2001 British Computer Society Distinguished Dissertation Award. He lives in Cambridge, UK with his wife and two children.

  • Help Us Understand CI/CD, DevOps & Job Scheduling

    Help Us Understand CI/CD, DevOps & Job Scheduling

    While plenty of vendors tell us what they think is happening in the market, the only way to really learn is from you, our readers. So we are asking you to take a few minutes to take this important survey on the adoption of CI/CD, DevOps and job scheduling.

    We will be giving a $50 Amazon gift card to one out of every 50 respondents. More importantly we will be publishing the results here on staging-devopsy.kinsta.cloud to share with everyone. The survey is sponsored by BMC and co-produced with staging-devopsy.kinsta.cloud.

    You can take the survey right here:
    Create your own user feedback survey
    Thanks for taking the time and helping us help us all.

    — Alan Shimel

  • How Developers Can Spend More Time Coding, Less Time Fixing

    How Developers Can Spend More Time Coding, Less Time Fixing

    I don’t think anyone became a developer because they loved to spend their time debugging. As frustrating as it may be, making sure your build works is critical—and this burden is now falling on developers. If your organization wants to deliver highly rated apps faster, building quality into the development cycle is imperative. Even though agile development has become a popular approach, it’s execution has a ways to go.

    A recent trends report in mobile and web development shows 25 percent of time is spent addressing a bug fix backlog. This can slow time-to-market and limit the amount of new features your company can roll out—not ideal when your top priority is to draw in new users and boost engagement to stay competitive. The good news is, the time spent debugging throughout the development cycle can be minimized. How? By shifting QA into the development process, you can spend more time coding and less time fixing.

    Mastering Agility in Practice

    The question for devs today isn’t whether they test, but when and how to do it best. We’ve all heard the vague, top-line answers before: “Adopt Agile development,” or, “Shift left.” The problem is, these terms and strategies can be challenging to execute in practice, especially without proper tools to make it happen.

    When we talk about “shifting left,” there’s still an important balance to be found as to which stage is right for dev teams to test—it can’t be too early, when there is nothing meaningful to test, and it can’t be too late, when the test batch pile is too big. Once your coding and testing processes are harmonized, you can effectively maximize your time and resources and get the job done faster and better.

    For development teams, if testing is done in bulk at the end, identifying the specific point in the build that needs to be corrected is like finding a needle in a haystack. When we shift quality left, defects are found earlier among a much smaller set of changes, and are therefore easier to fix. That’s why continuous integration (CI) calls for building, integrating and testing the system you’re developing upon delivery of even the smallest change.

    By testing continuously, uncertainty is reduced and feedback loops are made smaller, ensuring you’re building in the correct direction. The “shift left” trend is ultimately going to condense the dev cycle by getting quality back into the ingredient list. The earlier we deal with quality issues, the less focus is taken from our primary goal: building valuable, innovative technology.

    Find Tools that Mesh with Your Workflow

    Whether you use Selenium, Appium or Android Studio, new products need to integrate seamlessly into existing developer environments. Having to switch between building tools and testing tools is a big waste of time, and it’s unrealistic to expect a high adoption rate if the product is disrupting, rather than enhancing, your workflow. If you’re expected to shift testing into your development cycle, look for testing tools that seamlessly support the continuous integration of testing.

    Once your testing and building processes is aligned, the testing feedback and analysis becomes a new bottleneck. To minimize inefficiencies and feedback gaps, you need to carefully select tools that will improve visibility into build health, and help avoid batching up issues.

    Empower Developers to Satisfy Users

    At the end of the day, smaller batch sizes are only half the battle. No matter the batch size, quality only can be built in if it includes full test coverage, and if all the defects can be fixed in a way that actually meets user standards of quality.

    With tons of potential end user environments, injecting reality into the development process is crucial if you want to meet the high expectations of today’s consumers. With different phones, operating systems, levels of connectivity and apps running in the background, you never know what your apps will be put through once released. Leveraging stable test environments capable of recreating all potential user conditions throughout the developments cycle will maximize efficiency in development and accelerate the speed of innovation at your organization.

    Through a better delivery pipeline, mobile app and web developers are simply more effective. Once your test process is automated, aligned and maximized, writing better code can become your main focus. By taking a strategic, practical approach to shifting quality left—and giving developers the opportunity to focus on what matters most—you’ll see happier developers, and in turn, more successful businesses.

    About the Author / Paul Bruce

    Paul Bruce is Developer Evangelist at Perfecto, focusing on the value of quality and velocity throughout the software life cycle. He previously worked as an advocate for API development and testing practices and a full stack developer before that. He now writes, speaks, listens and teaches about software delivery patterns in modern enterprises and key industries around the world. Connect with him on LinkedIn and Twitter.