I spent a large portion of my career in the networking industry, marketing routers, switches and other gear that makes the internet work. Networking—like many industries—is currently undergoing a revolution that is in large part driven by software. Functions that used to be delivered as a standalone device can now run in software (not unlike the apps on your smartphone); and software is also being relied on more to make decisions about how traffic is routed through the network.
I still read up on the networking industry occasionally, and if you’re looking for an expert opinion or just good journalism in this space, you’d be hard-pressed to find a better source than Craig Matsumoto. Craig wrote an interesting opinion piece called “NFV, SDN, Big Data – It’s All About Automation.” You don’t have to know what those acronyms mean to understand the premise.
What’s interesting is that the same premise can be applied to many of the things that promise to make software development easier, faster and cheaper. DevOps, continuous delivery, continuous testing—all rely on automation to be successful.
DevOps, of course, requires more than just automation—as it’s also a cultural shift—but automation plays a huge role. The three main components of successful DevOps are commonly cited as tools (or technology), process and people (or culture). Automation is the primary goal of the first two: tools that enable you to automate previously manual tasks, and then establishing the processes that allow you to take advantage of this automation.
The same can be said of continuous delivery or continuous testing. Continuous testing relies on being able to automatically generate test cases, automatically create virtualized testing environments and create automated calls for testing.
The premise of a modern software factory also relies on automation. Any modern factory, whether it’s producing cars or toothbrushes, strives to improve efficiencies by eliminating as many manual tasks as possible.
The fact that software development and operations are lagging behind other industries in terms of automating the production of its goods (i.e., software) is maybe a bit ironic, given that software development is typically seen as more technologically advanced.
However, it’s also a result of the maturity of the industry and that fact that coding, by its nature, cannot be automated. But the tasks that surround the actual writing of code certainly can be automated, and that’s what the modern software factory promises. The more you can automate, the more successful you will be in delivering quality software faster, with reduced risk and costs.
Automation seems to bring with it concerns about employment—that is, there is a not-unfounded fear that it’s possible to automate oneself out of a job. However, there was an interesting study that came out, focusing on the automobile industry—one of the most well-known examples of factory automation. The study concluded that:
In the last six years, (2010–2015), according to the IFR (International Federation of Robotics), US industry has installed around 135,000 new industrial robots. The principal driver is automation in the car industry. During this same period, (2010–2015), the number of employees in the automotive sector increased by 230,000.
Essentially, automation not only improved production velocity and quality, it also resulted in a net increase in employment.
The message is clear: Automate what you can and only rely on manual tasks for what you must. If you focus on automating your software development life cycle, not only will you be able to deliver software faster, cheaper and with better quality, but you also will be well on your way to achieving continuous delivery and DevOps.
Trying to integrate applications on your own can eat your project alive. A seemingly simple project may look harmless when you start, but in the end do-it-yourself software delivery tool integrations can devour your entire software process.
The problem may be that building simple integrations appears easy. How hard can an integration be? But let’s look at what typically happens with integrations down the road using the example of one developer’s story.
A developer needs to send defects from Zendesk to JIRA, so he builds a one-way integration based on a workflow action (just a trigger). Soon enough, he realizes he is now managing two tools, and keeping them updated has become a big issue—a very manual process and a huge time-sink. So he designs something to support two-way updates. But that’s just the beginning; each tool changes every few months and an integration that seemed so simple on the surface becomes very complicated.
Then our developer tries to modify a simple JIRA workflow. Again, it seems straightforward, but it’s not, because the tools involved are constantly changing. There are complexities with workflows, and organizations undertake endpoint system upgrades. As a result, one change to the tool breaks everything he’s done. On top of this, it’s difficult now for him to know the hierarchy or how one item relates to another.
He starts to consider some of the challenges he’s facing. He needs to consider how the description is written in each tool. They are all different, so how does he make sure he conveys the information correctly every time? And each “simple” integration seems to create more pain points, creating auditability and traceability problems. Meanwhile, he has to manage other tools that are continually added to the mix.
He’s taken a look at both API and custom-tool approaches. He’s found that API integrations are brittle or they become too popular and then have to be maintained for an entire organization. But the alternative—custom tools—typically fall apart quickly.
And what happens when our developer decides to leave the company? There’s no one left who knows how to maintain the integrations he created. Meanwhile, new tool replacements mean someone has to build new integrations—and the puzzle becomes even more complicated.
This short scenario illustrates the unexpected challenges developers face in creating and maintaining integrations. The cost of building and maintaining tool integrations in an always-evolving landscape is deceptively high. And when an integration fails and the organization suffers critical downtime, costs (and tempers) skyrocket.
Many of the common pitfalls are readily evident, such as rich text problems, but the following three areas may be the most challenging to developers addressing integration issues and can’t be easily avoided:
Endpoint system upgrades and schema changes
Workflow rules and differences
Relationships
Endpoint system upgrades and schema changes: Much of the time, a different team from the one that developed an integration will perform the upgrade. Perhaps a new field was added. Regardless, simple changes to APIs can blow up an integration. API responses may change formats or the expected values for a field may change. When the team upgrades the system the URL may change, so avoiding duplicates is tough. So, too, is ensuring that the change is seamless. Changing some of the underlying features could result in unexpected behavior (and it will be hard to detect where the problem actually is). It may be that JIRA made API changes that caused custom select fields and comments to fail when using the “old way”; however, other features may continue to work as expected, making this failure silent.
Workflow rules and differences: Workflows are the complexities between systems. It is hard enough to reconcile teams, let alone the tools they use. Tools may require you to enter required fields, and this can constantly change. And workflows may not match up at all. How can you handle these differences without bouncing field values and allowing complex mappings to reconcile these? What happens when a system has a special action to change a status and fields are required at the same time, but the other system is open and doesn’t reflect this?
Because of these issues, it is critical to get the teams being integrated (e.g. testing and development) to discuss workflows and where the two teams align. These teams need to understand where workflows overlap so they can undertake proper integrations.
Relationships: These are not always apparent. As you grow and want traceability, you need to have synchronized relationships. How does this requirement trace to a test? How will you manage those relationships? The tools don’t match the way they manage relationships. Some allow one value, others multiple. Some allow relationships across projects and types, others are more restrictive. In addition to the rules of the system, how do you know what items to link once you have synchronized the artifacts? What happens if only one side of the link is synchronized or the items are not synchronized in the order that you expected?
Getting this all right requires intelligent systems that can look at one system and translate properly to another
Avoiding Integration Pitfalls
The first obvious step in avoiding pitfalls is to identify what they will be and when they’ll pop up. To do this, focus not just on the current problem, but also on the future. Consider the bigger picture, understanding that systems constantly change and teams work differently so there will be additional layers of complexity in any integration project down the road.
As such, my best advice is for development organizations to focus on the software their organizations are counting on them to deliver, not creating and managing tools to build that software. Put internal resources to work in IT areas where you can create competitive advantage for your company. And consider using third parties to address issues such as integrations.
About the Author / Shawn Minto
Shawn Minto is the senior director of Technical Services and Support at Tasktop and one of the original team members working with CEO and co-founder, Mik Kersten, on Mylyn prior to Tasktop’s founding. Shawn began his career at Tasktop as a software engineer, working on all aspects of the product and directly with our customers to support their needs. Currently he works with customers to understand their tool environments and offers suggestions on how to best leverage Tasktop through deployments and support. In his free time, he enjoys being outside, cooking, and renovation projects. Connect with him on LinkedIn and Twitter.
You know the feeling: You’ve put in hours of work developing a new feature. It has gone through QA, been tested and passed all stakeholder inspections, and now you’re ready to deploy. Despite your experience and preparation, you have a pit in your stomach. What if something goes wrong and it brings your app to its knees? What if it doesn’t function in your production environment the way it’s supposed to? We’ve all been there. Fortunately, we also have some ways to help.
Electric Cloud CTO Anders Wallgren recently participated on a webinar with Gene Kim, CTO, researcher and co-author of “The Phoenix Project” and “The DevOps Handbook.” Hosted by staging-devopsy.kinsta.cloud Editor in Chief Alan Shimel, the webinar addresses lessons learn from large-scale DevOps transformations, the business value of DevOps and some of the best tips and tricks for fighting deployment anxiety. We pulled out the top five tips and tricks from Kim and Wallgren for making deployment worries a thing of the past.
Tip 1: Automate Your Deployment
A theme throughout the webinar from both Kim and Wallgren was “automation.” One of the big reasons for this is that typically, when you automate your deployments, you’re also automating the diagnosis of problems in those deployments. You can’t always just rely on the exit code of a command-line tool to tell you whether something went right or went wrong. To help keep your deployments healthy, you’ll want to do testing along the way, possibly as a blue-green deployment or a partial deployment. However, if you don’t have automation behind that, it can be difficult to get that accomplished at speed. Without automation, you may start to rely on heroic efforts by individuals—so that every time you are doing a deployment, someone is having to do a figurative tightrope-walk to get everything accomplished. This creates a tough environment for your employees, and can lead to extensive downtime (and lost profits).
Tip 2: Enable Self-Service Deployments to Any Infrastructure
You’re probably wondering why this is a separate topic from automated deployments. That’s because the majority of deployments that occur in a given release pipeline aren’t going into production. Most deployments end up in testing environments (for performance testing, regression testing or just developer testing). It’s also important that you give your engineers the ability to use the same deployment methodology (artifacts, process definition, environment definition, etc.) regardless of the location to where they are deploying. From a cost perspective, allowing QA to test on a local Kubernetes cluster might be more cost-effective for your enterprise than running tests on Amazon Container Service. But, allowing teams to use the same approved automation as part of every deployment—to any location—means a more thoroughly rehearsed and therefore less anxiety-inducing deployment.
The ability to do self-service deployments also gives your teams the ability to move substantially faster when they need to deploy something for testing by avoiding the need to open a ticket and get your Ops teams involved. By allowing self-service deployments, you can avoid the process of running around to find the right person to accomplish the deployment you need to run, and empower your organization to react and build more autonomously across different groups. The result is better-tested and built deployments (resulting in lower deployment stress and fewer errors).
Tip 3: Self-Service Environments
We’re continuing to roll with the theme of automation, but this time we’re talking about self-service environments. More often than not, we’re working with complex distributed apps. This means things such as a containerized microservice application, DBMSs, messaging, key value stores, legacy applications and third-party vendors that we need to integrate with—all things that make our deployments complicated. Being able to consistently provision complex environments is a very important part of being able to successfully recreate a deployment as you promote the application through its life cycle.
It’s important to make sure that your engineers, and in particular, your QA and development engineers, have easy access to environments and that they’re not standing around waiting for access. When you don’t have the ability to get VMs or containers provisioned and configured correctly to receive your application, you run into problems. One of these problems is that your ability to test rapidly just became much more difficult. When you can’t get a near-production quality environment stood up in a few minutes, it means that your bug fix that requires just a few lines of code could potentially take weeks to test. Suddenly you need to requisition a set of VMs to test on (which could take weeks) and another day or two to do the deployment, and only then can you complete your tests. Things become painfully slow. And, when it comes to testing and fixing bugs, slow equals stress.
Tip 4: Artifact Repositories
Want to feel more confident about your releases? Look at your artifact repositories. Use of a shared artifact repository in production environments has been shown to be a good are a really good predictor of deployment success. If you’re not versioning your binaries, and have little insight into where binaries are coming from and how they were built, it can lead to failed deployments.
It may not be easy or simple to get your artifact repositories in line, but it’s a labor that will pay massive dividends in the long term. Electric Cloud worked with a massive online mortgage company that had the challenge of deploying large artifacts (gigabytes) into multiple data centers. To get everything up to speed, it was necessary to transfer those artifacts out of their build and test infrastructure and into their pre-production and production infrastructure. Because of the size of the artifacts and concerns about worldwide availability for the files, Electric Cloud worked with this financial services company to use Amazon S3 as the backing store for the repository server to create a long-term solution that is flexible and scalable.
Tip 5: Security and Auditability
If you work in a regulated industry, already know the heartburn auditability and governance can cause. Security is one of—if not the single—most important aspect of many application delivery pipelines. The reality is, we are just beginning to scratch the surface of the problems we will see the in the future when it comes to infrastructures getting hacked. So what’s our tip? Again, it comes back to automation. At ElectricCloud, there is a saying: Automation is auditing, automation is documentation.
The idea behind this is that by automating your deployment tasks, you are essentially creating a very real and tangible paper trail that shows what you intend to do (the automation definition) and a report of exactly what happened (the automation logs). When you rely on manual deployments, you suddenly take an aspect of repeatability and predictability out of your workflow. At that point, you are forced to report based on people’s spreadsheets, emails and memories. This is one of those things that doesn’t become a big deal until it’s a really big deal, and—to borrow another saying—an ounce of prevention is worth a pound of cure. In the case of auditability and security, being able to retrace your steps because your steps are always the same is a fairly foolproof method to making your audits much more smooth.
To provide a real-world example for how automation can make auditing and security much less painful, one of ElectricCloud’s clients is an aerospace customer with very stringent and demanding security standards. In the past, at the end of each release, it would have a two-week process where everybody had to sit down and compile a list of every single check-in deployed as part of that release. They had to understand where it got built and exactly how it was tested, and then assemble all of that information in a report. It was an extremely time-consuming, but seemingly necessary process. However, by automating many of the steps in the pipeline, the audit response effort went from a two-week process to just a few hours. They accomplished this because 99 percent of the information they needed was in the automation system and was simply scraped as part of process. The task went from manually pulling that data to just getting into it consumable formats.
Summary
By now you’ve certainly seen a theme emerge in our recommendations for reducing the stress of deployments—namely, automate! By putting effort into automation and streamlining your pipeline, you can take what was once a very labor-intensive and sometimes stomach-churning process and make it much more enjoyable. Not only will this save you time and money in the long run, but it will also allow you to focus on building better software, doing more deployments and focusing on the tasks that bring your business and your customers real value.
For more details on how you can relieve your deployment anxiety, and to hear the rest of the discussion focusing on the lessons learned from large-scale enterprise DevOps transformations and the business value of DevOps, watch the full replay.
About the Author / Sam Fell
Sam Fell is the Head of Marketing at Electric Cloud, responsible for driving awareness and demand for our DevOps Release Automation and Acceleration solutions. For 20 years, Sam has helped companies achieve success by marketing, selling, and implementing DevOps Release Automation, IT Change Management and Application Performance Management solutions. Prior to joining Electric Cloud, Sam held leadership roles at BMC, CA, Marimba and Nimsoft. Follow him on Twitter and connect with him on LinkedIn.
As cloud and DevOps have heated up, enterprise need for cloud portability and deeper DevOps integration have become pretty clear. The need for portability to avoid cloud lock-in has been a desire of enterprise cloud users from day one. A variety of people are attempting to address this need, but the market is still very much evolving.
In the area of DevOps integration, the two topics currently causing struggles are security and networking. Continuous deployment inevitably requires both to be part of the DevOps package, and those are the newest additions to the field, so it is still maturing.
Enter appOrbit
appOrbit recently came out of stealth mode with an overarching architecture to enable hypercloud and extend the DevOps process across the entirety of the dev/test/deploy ecosystem. The idea is to offer a platform that doesn’t care what languages or deployment tools you use, or even what databases you’ve tossed data into, and covers the process from first line of code to management and monitoring post-deployment.
That’s a big claim, so I got on the phone with appOrbit to poke around a bit. Better would be to take the time and use the toolset, but I’ll settle for our questions about the traditional weak spaces in the process, and about how they achieve some of the company’s claims. For now.
My first impression was that this was application release automation/application release management (ARA/ARM), and Rahul Ravulur, CEO of appOrbit told me I wasn’t far off; I just wasn’t thinking big enough. A large part of the process is ARA, but additionally, appOrbit worries about networking, security policy and long-term monitoring and management, all while offering deployment portability.
Finally, the End Game is in Sight
From the beginnings of the Ops side of the DevOps movement (what I like to call devOPS), the end goal was pretty obvious: to improve the entirety of the process. It was clearly going to take time—good network engineers are wizards that can make a network do astounding things—and we had to figure out how to make that more repeatable. On the DEVops side, repeatable was relatively painless: We already did a predefined sequence of steps over and over; the point was to break them into smaller iterations and automate what was ripe for automation. Much of Ops was the same, but networking and security had many more variables to take into account, and less history of “here’s a prescribed sequence, do it.”
If appOrbit can do as it claims—and its customer list includes some customers I’ve worked with that probably wouldn’t be there if the product was vaporware—then we’re seeing the culmination start. The culmination will include limitless portability, sort of a “we don’t care where you deploy, just tell us and we’ll do it”; it will include development tool agnosticism—“We don’t care what tools you used, we’ll deploy it”; and it will include complete solutions—“We’ll move your data, we’ll move your app, we’ll configure the target network, we’ll run the security checks relevant to the target platform.” It sounds like appOrbit has traveled quite far down that path already.
What, Exactly, Did You Intend?
One interesting bit appOrbit talked to me about and I’d like to take out for a spin is the idea of adding “intents” to security and networking. Tell it what you’re after, and through a combination of built-in functionality and plug-ins it will deploy your application as you intended. For things like opening a port, this seems pretty straightforward, but security and networking are complex topics. What is/isn’t covered by security policies/intents? What if my intent is for the system to create a VPN, lock down all the ports, then open just a few and connect the VPN back into the data center over an encrypted port? Who manages certs? Where does it get the credentials to get back into the data center? What happens if I take this whole VPN-based deployment and decide to put it inside the data center after all? Do I have to rework the networking intents to remove the VPN? The questions are endless.
But assume this is the beginning of a road that truly can end up with “deploy anywhere, and deploy as you intended.” That’s what we’ve been waiting for, and it’s inevitable, so I for one am glad to see us set off meaningfully down the path.
Improvement Makes Movement
The mere act of someone talking about having pulled all this together will be good for customers. Ravulur’s stress that “a lot of what we do is ARA” will no doubt make ARA vendors step up their attempts to be as inclusive as appOrbit is, and the market will move forward. appOrbit’s use case of “legacy app migration” without changing the app alone offers an avenue for enterprises to begin to move to new platforms. That in and of itself will be a help to the huge number of enterprises that want to move to a more modern environment but aren’t ready or able to rewrite entire systems. And again, it will spur on competitors—in this case in the application provisioning space, most likely—to try and implement similar functionality in a relatively short time frame.
Beyond Hope
In a nutshell, I hope that appOrbit can do all that it claims, but even if it falls short in some areas (I honestly have only touched on a few of the areas it has pulled together; there’s a lot here), it is a step forward, and I think the company will drive the market more toward the end goal of application portability from both the Dev and deployment sides, while automating a more complete solution.
To me, that’s all good. Not everyone is pure cloud, and a far fewer number want to be pure public cloud brand X. The automation tools I’ve been knee-deep in all have been massively complex under the covers, and no doubt this one is, too; simplifying automation so it is easy to adapt to a given environment is a huge part of the task these tools perform. Figuring out the weaknesses is what we customers have to do, but in the end, we’re moving forward.
I, for one, will look for a chance to play with appOrbit’s toys, validate some of its claims, and see how well it suits enterprise needs. But I don’t have a timeline, so if you’re interested, you should check them out yourself.
This article’s purpose is to compare the “big two” in the log analytics world—Splunk and the ELK Stack. But before we go into details, a short introduction to the competitors is required.
Splunk is the “Google for log files” heavyset enterprise tool that was the first log analysis software and has been the market leader ever since. The open-source ELK Stack of Elasticsearch, Logstash and Kibana is an up-and-coming rival that is a consolidated data analytics platform. The two compete in terms of features, usability and cost.
Overview
Splunk and the ELK Stack use two different approaches to solve the same problem. People typically choose one or the other based on how their organizations are structured and how much time they want to devote to log analytics. Splunk takes a pile of data and allows people to search through the information to extract what they need. ELK requires more work and planning in the beginning, but the value extraction is easier at the end.
The three key components of Splunk are its forwarder, which pushes data to remote indexers; indexer, which has roles for storing and indexing data and responding to search requests; and search head, which is the front end of the web interface where these three components can be combined or distributed over servers. Splunk also supports the integration of its functionalities in applications via SDKs. Common use cases include operational monitoring, security and user behavior analytics. Splunk is a paid service wherein billing is generated by indexing volume.
The ELK Stack is a set of three open-source products—Elasticsearch, Logstash and Kibana—all developed and maintained by Elastic. Elasticsearch is NoSQL database that uses the Lucene search engine. Logstash is a data processing and transportation pipeline used to populate Elasticsearch with the data (though also it supports other destinations including Graphite, Kafka, Nagios and RabbitMQ). Kibana is a dashboard that works on top of Elasticsearch and facilitates data analysis using visualizations and dashboards.
Both Splunk and the ELK Stack can be used to monitor and analyze infrastructure in IT operations as well as for application monitoring, security and business intelligence.
ELK vs. Splunk
Loading Data
Shipping data to Splunk is fairly easy. After installation, the forwarders come pre-configured for a wide selection of data sources such as files and directories, network events, windows sources and application logs, and they are used to import data into Splunk as shown:
In the ELK Stack, Logstash is used to ship data from the source to the destination. However, Logstash needs to be configured so that each field is identified before the data is shipped to Elasticsearch. This kind of configuration can be tricky for those who do not work with scripting languages (such as Bash, Python or Ruby), but there is good support online that can be found quite easily.
Visualizations
The Splunk web UI includes flexible controls that allow you to edit and add new components to your dashboard. Management and user controls can be configured differently for multiple users, with each having a customized dashboard. Splunk also supports visualizations on mobile devices with application and visualization components that are easy to customize using XML.
Kibana is the visualization tool in the ELK Stack, and like Splunk, the platform supports the creation of visualizations such as line charts, area arts and tables and the presentation of them in a dashboard. The search filter is always shown above the different views: If a query is used, it is automatically applied on elements of the dashboard. Splunk also has a similar option, but it involves configuration in XML. Still, Kibana does not support user management, but hosted ELK solutions provide it out of the box.
Search Capabilities
The search function is a key capability of any log management platform. Both the Splunk and ELK Stack’s web UIs support searching using a dedicated search field. The query syntax on Kibana is based on the Lucene query syntax while Splunk uses its own Splunk Search Processing Language (SPL). Those familiar with scripting languages may already be familiar with Lucene while SPL is proprietary and must be learned.
One other difference is that Splunk offers dynamic data exploration to help users to find and extract everything as a searchable field when formatted in a manner that allows searching for non-configured fields. Elasticsearch fields, on the other hand, need to be defined in advance to use aggregation over the log properties.
Here is one example of a query for each platform.
Kibana:
(beat.hostname: ES1 AND metricset.name: process) AND (system.process.username: root OR system.process.username: admin)
Splunk:
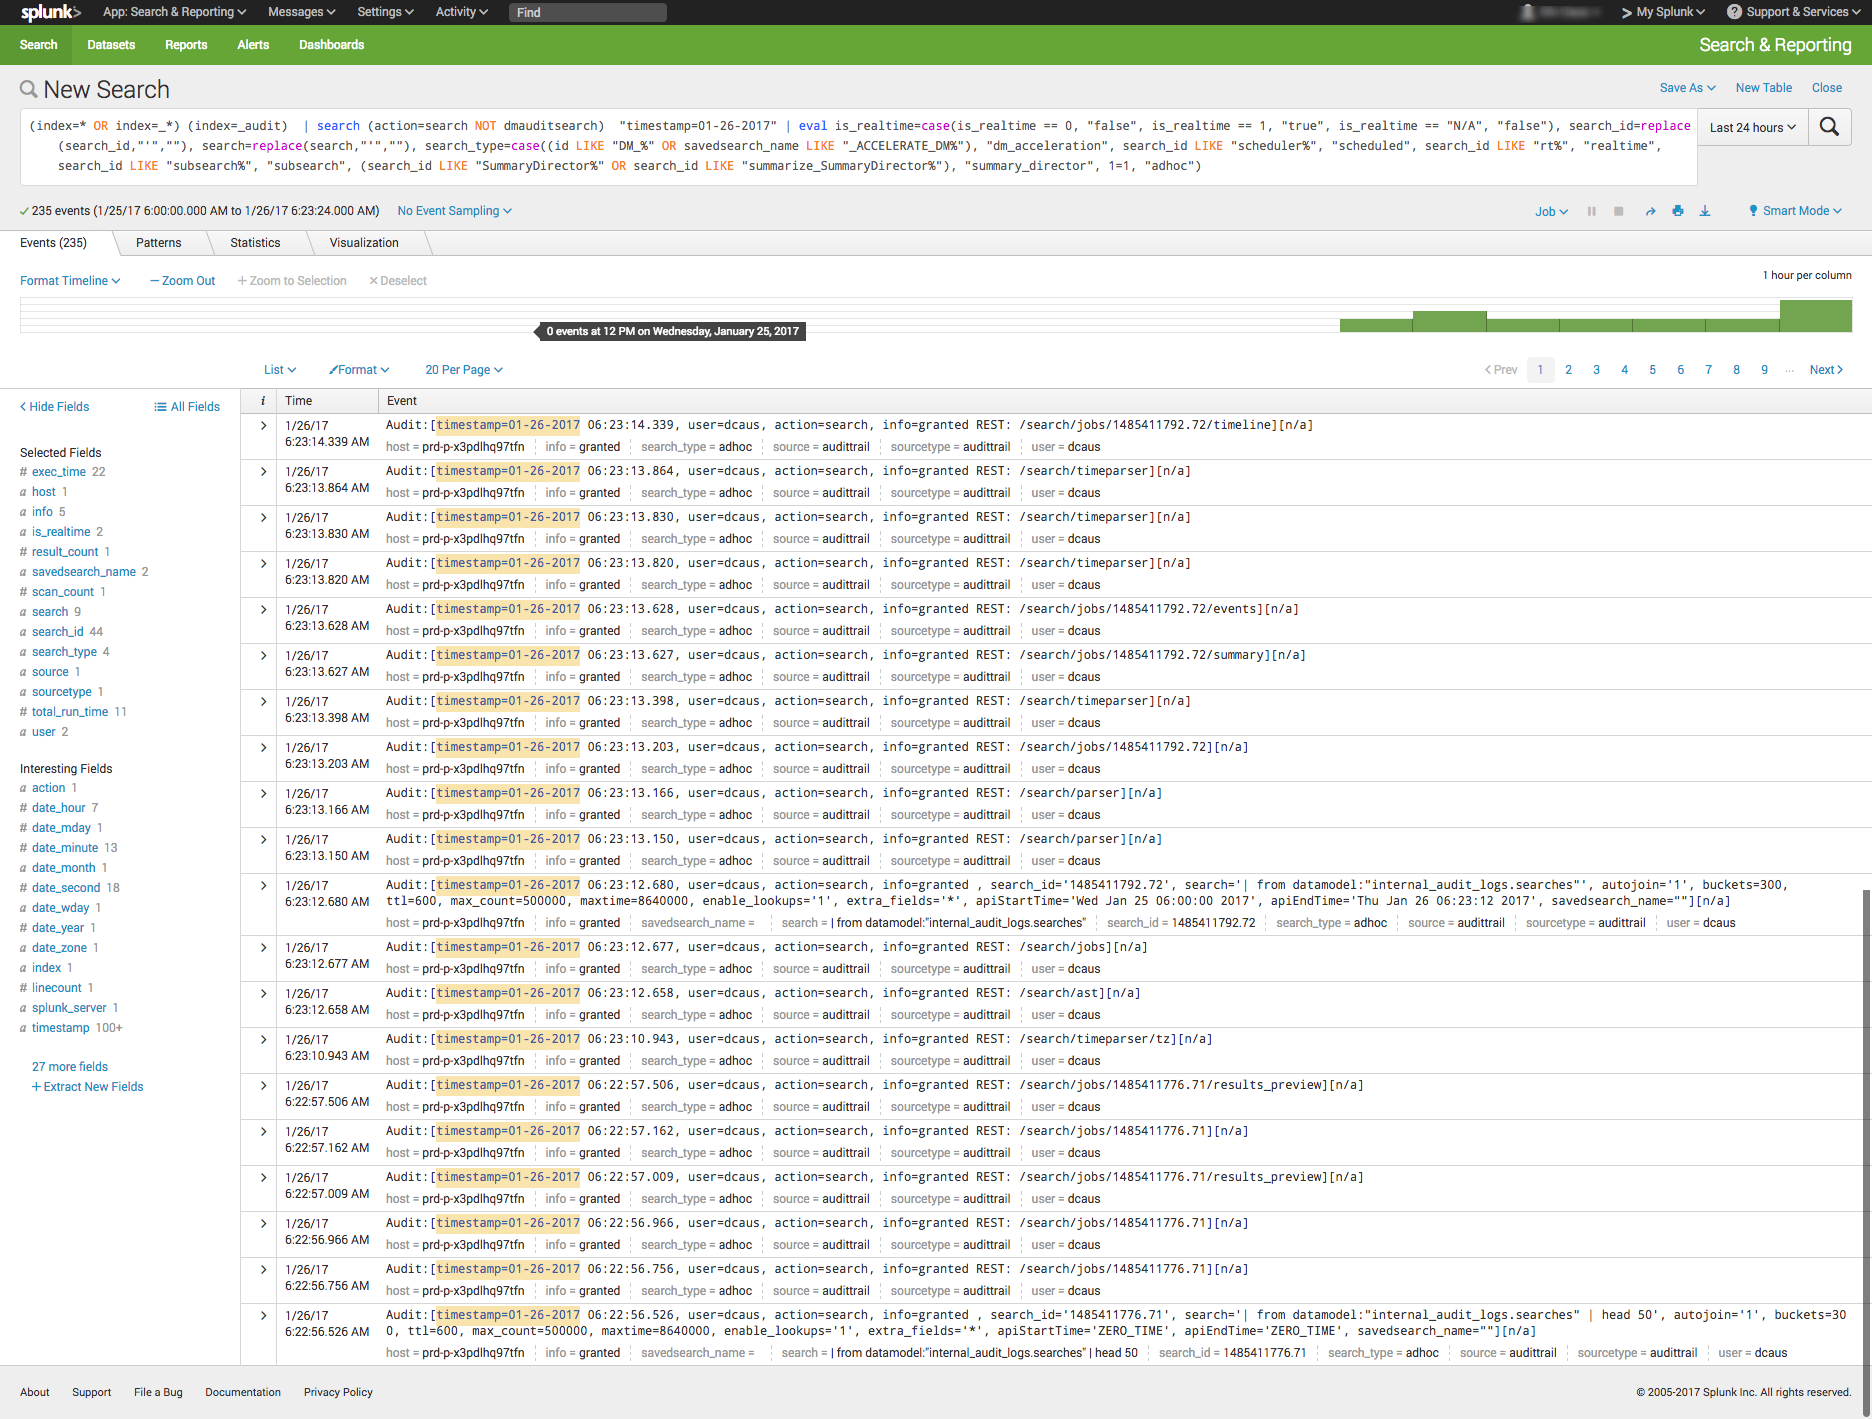
(index=* OR index=_*) (index=_audit) | search ( action=search NOT dmauditsearch ) "06:54"
The difference between SPL syntax and Lucene queries is that SPL supports the search pipeline (as in the example above) in which consecutive commands are chained together using a pipe character that allows the output of one command to be used as the input of the next one. Lucene query syntax is more straightforward and can work to generate the output from the query without additional transforming.
Traction and Community Support
Both Splunk and ELK Stack have large communities of users and supporters. ELK also has its own clear and extensive documentation for each separate tool, making it easy to get started. In addition, Elastic itself offers educational sessions worldwide.
In addition to having good documentation and a forum, Splunk, too, has customer and support platforms that offer various professional services. Splunk’s education program and instructors are available virtually or on site.
The Learning Curve
The ELK Stack’s learning curve is flat for what it’s meant to do. Elastic offers paid courses, but there is a lot of free material online due to the popularity of the open-source platform.
For Splunk, the learning curve is moderate in size, especially when carrying out more specialized analyzes. The company offers a trial period with extensive documentation, but the advanced Splunk educational courses are fairly expensive.
User Management
The ELK Stack provides role-based security as a separate paid tool. Splunk and managed-ELK services offer user management out of the box with user auditing included.
Pricing Levels
As already mentioned, Splunk is proprietary software with a price tag. After one integrates several data sources with the platform, the cost will increase greatly as data is continuously generated.
The open-source ELK Stack is free, but the true picture is not so black and white. The cost of the platform’s hardware and maintenance also adds up. To lower the cost of using ELK, features, plugins and tools must be developed.
Vendor Lock-In
Splunk’s high price tag comes with the benefit of offering an overall, well-rounded product. Users might be locked into a vendor, but that one vendor is all that is needed to do nearly anything. The open-source ELK Stack is seemingly free, but it does not provide many functionalities such as alerting out of the box—and it costs money to develop and maintain them.
One way to look at the Splunk-versus-ELK discussion is to frame it as the old Microsoft-versus-Linux debate. If you like Microsoft, you will probably prefer Splunk. If you like Linux, you will likely want to use the ELK Stack.
Final Thoughts
When one decides between these solutions, the ultimate choice should reflect not only on the platform but also on the customer’s specific needs.
Both Splunk and the ELK Stack are currently popular. But what might the future hold?
Splunk (Blue) vs. Elasticsearch (Red) on Google Trends
According to Google Trends, the ELK Stack has now overtaken Splunk in terms of the proportion of Google searches. But ELK’s traction does not stop there. As mentioned earlier, Splunk self-reports 12,000 total users. Elasticsearch is reportedly downloaded 500,000 times every single month. In IT departments, then, it is far more likely to meet people who are familiar with ELK than with Splunk, meaning that the adoption rate of the ELK Stack could “snowball” and increase even more in the future whenever ELK users join new companies or teams. People tend to use whatever software they already know or is already being used.
It’s clear that many functionalities are being added to the open-source ELK Stack. This, in turn, is shrinking the gap between it and Splunk. hose features currently found only in Splunk are likely to be added to ELK at some point in time.
So, if a more mature product is what you need, go with Splunk. But if you like a product that is more flexible, ELK is the way. Either way, it’ll be interesting to see how these two continue to compete.
Much of the initial focus on DevOps has been on accelerating the rate at which applications are built and deployed. But once those applications are deployed, it’s not too long before the focus shifts to the quality of the end-user experience. Aiming to make it easier to determine what the quality of that experience really is, Riverbed Technology has launched a Digital Experience Management initiative based on the SteelCentral management platform.
Erik Hille, director of product marketing for Riverbed, says the latest release of SteelCentral provides tighter integration between SteelCentral Portal and the SteelCentral Aternity end-user monitoring tool and SteelCentral AppInternals, an application performance management (APM) platform. The goal, says Hille, is to make it easier for an organization to holistically manage individual end-user experience by correlating information at the device, network and application levels. As part of that effort, Riverbed also has integrated the workflow between SteelCentral Aternity and AppInternals to create an integrated monitoring system.
Hille says IT operations teams can use a comprehensive approach to managing digital experiences that can be set up in fewer than 10 days. Once in place, IT operations teams can more quickly identify the root cause of any issue by correlating application, device and networking data through a single pane of glass. In addition, Riverbed is employing REST APIs to make it possible to consume alerts generated by collaboration tools such as Slack and HipChat. IT operations teams can not only automatically open incident management tickets, but also collect additional metrics via those APIs.
Riverbed is also providing integration between NetProfiler, a network performance monitoring tool, and NetIM, a network device management tool, to provide more visibility into how network infrastructure impacts network performance.
Hille notes that most IT operations teams are swiveling between different sets of tools to correlate the same information. The problem is that as more organizations strive to become a digital business, any performance issue has a direct impact on customer satisfaction and the amount of revenue being generated. Faced with that increased business pressure, Hille says IT organizations need to re-evaluate legacy approaches to IT operations based on silos. The goal should be to implement a more proactive approach to IT focused on proactively preventing issues from occurring or escalating, versus merely reacting to isolated events as they occur.
One of the few things in DevOps that developers and IT professionals can agree on is that whenever there’s an issue, it’s the fault of the network guy. That’s not always true, but it does take networking professionals a long time to prove their innocence. Until then, there’s a tendency to assume their guilty until proven otherwise. Obviously, that kind of bias isn’t in keeping with the whole spirit of integrated DevOps. A more comprehensive approach to application and networking performance management should go a long way toward reducing the amount of finger-pointing inside any organization.
There will never be a perfect IT environment. The goal is to discover issues before the end-user notices—and, failing that, resolve that issue in as little time as possible. Any argument about what exactly happened to cause the problem can occur at a later date and time.
Networking in the enterprise has always stood apart. It might take two minutes or less to spin up a virtual machine, but it can take two weeks to set up the network connections. To help bridge some of the gaps between networking and the rest of the DevOps team, Cisco Systems this week unveiled a series of intelligent switches that promise to do just that.
Via a Cisco intent-driven networking initiative, it soon will be possible to describe a business outcome that will be automatically enabled at the networking level, says Kiran Ghodgaonkar, senior marketing manager for Cisco. To achieve that goal, Cisco is moving to unify networking on an end-to-end basis, which Ghodgaonkar says primarily will require building a common controller that can be implemented at both the edge of the network and in the data center.
The first concrete step in achieving that goal is a set of Catalyst 9000 switches running an IOS XE operating system, which Cisco has imbued with machine learning algorithms. Over time, those algorithms will be deployed across both legacy networking infrastructures when appropriate, as well as any new networking and security equipment Cisco brings to market in the future. Once in place, IOS XE will make it easier to implement policies in software that spans everything from prioritizing traffic to implementing security polices.
This latest Cisco initiative follows the rollout a Tetration analytics platform based on an instance of Apache Spark and Cisco’s acquisition of AppDynamics, provider of an application performance management service delivered via the cloud. Ghodgaonkar says Cisco is aiming to combine analytics and machine learning algorithms to simplify network management in a way that furthers DevOps integration. Right now, however, the biggest impedance to achieving that goal, says Ghodgaonkar, is the fact that 80 percent to 90 percent of networking tasks still require manual intervention. Because of that issue alone, many organizations have experienced limited success in terms of integrating server, storage and networking management, despite the rise of software-defined networking (SDN) in the data center. In fact, to get past that issue, many organizations make investments in pre-integrated systems such as the Cisco Unified Computing System (UCS) platform. But the number of organizations willing to make that kind in forklift investment in IT infrastructure is not all that high when compared to the size of the overall IT market.
The biggest DevOps issue IT organizations now face, says Ghodgaonkar, is that as various elements of the IT organization invest in automation, silos of automation are created. Cisco says it has developed open application programming interfaces (API) will provide interoperability between its technologies and the rest of the IT environment to help break down those silos.
It’s still a little unclear these days just how much networking and IT operations can get automated. The good news is that, given the state of network management inside most organizations, things can only improve. The real issue (as any existing DevOps team already knows) may not be so much the technology as it is the culture differences spanning the compute, storage and networking teams.
Much of the inherent conflict that exists between developers and IT operations teams often comes down to how IT automation processes are implemented. IT operations teams generally have their own preferred tools for automating operations while developers have another. To resolve that issue, BMC Software unveiled Control-M Workbench, a set of development tools that extends an application programming interface (API) to allow developers to embed instructions for automating infrastructure using BMC Control-M automation platform.
Gur Steif, president for digital automation at BMC Software, says Control-M Workbench moves the responsibility for automating the IT infrastructure resources that their application consumes, including the ability to code, debug and test workflows. The IT operations team can then more easily deploy that application in a production environment, he says.
In effect, BMC Software is enabling IT organizations to put the control of how jobs are executed in a production environment in the hands of developers by moving that function further to the left of the DevOps life cycle. Control-M Workbench represents the first time BMC is venturing beyond its traditional IT operations base to create a tool that will primarily be employed by developers.
Steif says the goal is to enable IT operations teams to manage much higher volumes of application rollouts. In return for spending a few minutes on installing Control-M Workbench, IT organizations can deliver application 20 percent faster, while running jobs using 50 percent fewer full-time employees. In addition, Stief says production incidents can be reduced by up to 25 percent and batch processing failure rate can drop by as much as 80 percent.
Control-M Workbench is clearly part of a trend to give developers more control over and responsibility for IT operations. A recent survey of 650 IT decision makers conducted by BMC finds 94 percent of IT decision makers expect automation to spread into all other areas of business by 2020.
In addition, the survey notes that 73 percent of IT decision makers believe businesses that do not embrace IT automation to achieve the larger digital business strategy within the next five years will cease to exist in 10 years. The top three areas of investment priority in the next 24 months to achieve those goals are containerization, workload automation/scheduling and DevOps. Almost 9 in 10 (89 percent) respondents concur that IT automation needs to achieve their desired digital business objectives.
However, there are considerable obstacles that need to be overcome, including lack of budget (67 percent), skills (44 percent) and time (51 perent). In fact, 42 percent of the respondents concede that when it comes to digital business initiatives there are conflicting objectives between business units and CIOs that can get in the way of crafting a comprehensive IT strategy.
DevOps, of course, is more about people and processes than it is technology. Then again, DevOps isn’t going to be willed into existence without providing the tools needed to change the processes. Given the chicken-and-egg relationship between processes and tools, it becomes incumbent on the IT leadership to serve as the catalyst for bringing it all together.
Many developers are not so great at documentation. Ask anyone who’s been thrown into a large code base. Changes aren’t documented well, tribal knowledge thrives in the code comments, and anyone who says, “I’m confused, what does this chunk of spaghetti code mean?” is often treated with annoyance or even disdain.
That is something that DevOps doesn’t change. And there are, as with so many things in IT right now, complicating factors. First is APIs. In almost every shop, developers are responsible for the public-facing APIs. The same developers who don’t comment well are now documenting public-facing APIs. The other complicating factor is DevOps documentation mechanisms. Automated systems generate API documentation from developer comments. Again, the same developers that often don’t document their code well enough to efficiently on-board new developers.
Those of us who have used more than a couple of APIs know the problem intimately. Dozens, or hundreds, or thousands of us have to search for what the allowable values for a parameter or JSON field are in an API call are because far too often that is not well-documented.
The whole system grew naturally. APIs are the realm of developers; documentation was painful to get created because it required tech writers that were advanced enough to understand the purpose and function of the API; and development of documentation delayed API deployment—all are issues that lent themselves to automated generation and the developer in the code was best-situated to document it. In the API economy, and in light of both agile and DevOps, it just made sense to use generated documentation for this part of the project.
But we’ve got enough experience now to know that “good enough” isn’t. Far too often users are left to figure out the details, and quite often, those users don’t bother. That’s not a benefit in the API economy; it’s a risk.
Get Help With Your APIs
And it’s pretty easily resolvable. Get someone not knee deep in the code to try and use your API as documented. Get their recommendations on usability, and fix the issues they find. I’ve used APIs that have a dozen JSON base parameters, none of which are documented as to what’s allowed or not. I’ve used APIs where the JSON field was text, but the values were from a specialized list that was not made public and users had to hunt for allowed values. We’ve all been through it, and it is a massive waste of time.
If you have a customer base, use Alpha/Beta users to help with this process. Early access is generally people who know the project/product, so feedback will be more focused, but as outsiders they do not share in tribal knowledge. Without tribal knowledge, they will have solid input to improve API usability.
And in the end, an API is a consumable that you want customers to use. Telling them how to do so is important. And the current trendy way of doing so is not good enough. So make certain your process is good enough, or accept user loss as a consequence.
For those with established products/projects, do not wag your head and assume you have it covered. Some very cool, long-lived APIs have entire sets of JSON input values that are not well-documented. They were important enough to make them parameters (or return values for that matter), yet you didn’t document them well? Please, ask new users if they agree with your assessment of your API.
Don’t have time/man hours/whatever to address documentation shortcomings in your API? Then don’t publish an API. The only thing worse than saying, “You can’t integrate via API with our system,” is saying, “You can integrate with our system via API,” then not documenting it well enough to do so.
So keep the automation. But follow the new mantra:
Now that you have generated documentation, check that you have usable documentation.
And keep kicking it. APIs are the hard part, telling people how to use them is comparatively easy, so take the time to make your development efforts worthwhile.
Businesses are increasingly developing software solutions that can drive innovation and digital transformation. As the number of developers increases in the organization, the ratio of developers to IT also increases over time. The net result: more dynamic and complex dev/test infrastructure requirements and slower support from IT.
Developers and testers often cannot get their hands on infrastructure environments in a timely manner to accelerate delivery of software applications to their customers. They have to deal with lack of timely support from IT and long waits for hardware resources and for provisioning and configuring of the environments.
How does engineering IT manage this complexity and deliver more agility to their engineering stakeholders?
Provide Self-Service Creation of Dev/Test Sandbox Clouds
Engineering IT teams can increase the velocity of development and testing if they enable self-service ability for dev teams to quickly provision their own lab infrastructure and application stacks at a click of a button.
Self-service, API-driven infrastructure is a fundamental requirement for enabling developers to write code (which can be done using their favorite programming language) and make RESTful API calls to the underlying programmable infrastructure. This allows them to dynamically and automatically manage initial deployments and configurations as well as manage ongoing, automated dynamic provisioning of infrastructure, autoscaling, monitoring and alerting.
All this automation removes the confusion and error-prone manual steps for the entire application delivery process, including development, testing, staging and production deployments. This, in turn, accelerates software delivery and increases quality.
Additionally, if self-service is available as a SaaS-based delivery model, it is easy to add more features and workflows very quickly without having IT doing a major upgrade.
Breaking these silos improves collaboration between teams, accelerates velocity of software development, improves infrastructure utilization, increases overall operational efficiency and reduces costs.
Eliminating Silos in the Dev/Test Infrastructure
Silos are common in companies where various specialist teams (storage, networking, security) form fiefdoms around their respective functional areas. Silos impede velocity because they lead to complexity of operations, lack of consistency in the environment, and lack of automation.
Automating across silos turns into to an exercise of custom scripts and lot of “glue and duct tape,” which makes maintenance and change management complex, slow and error-prone.
Breaking these silos improves collaboration between teams, accelerates velocity of software development, improves infrastructure utilization, increases overall operational efficiency and reduces costs.
A hyperconverged cloud design with a software-centric, scale-out architecture tightly integrates compute, storage, networking and virtualization resources and other technologies from scratch in a commodity hardware box supported by a single vendor. Also, companies can keep costs under control by leveraging scale-out cloud designs that make it easy to start small, grow based on demand, and stay close to the right size and customer demands.
Additionally, development teams should have the ability to quickly deploy/clone/share complex multi-tiered application stacks between various teams and between development and testing, breaking the silos within the development organization.
Automate Operations, Monitoring and Patching
Engineering IT teams need to have complete visibility and control of their entire stack from the infrastructure up to applications. They need intelligent software to monitor the hardware and software stack, manage large-scale clusters and automatically handle routine but time-consuming and complex operations such as failure handling, patching, security updates and software upgrades.
Running a service with traditional sysadmin teams who execute the above activities manually becomes expensive—especially if they operate in server, storage, networking and security silos—as the dev/test environments become more dynamic and the demand for more environments and projects grows.
However, it is possible to use an intelligent private cloud platform that leverages hyperconverged scale-out designs, machine learning software and a SaaS-based operational console to reduce complexity and increase the agility of dev/test teams.
Cloud-based monitoring and advanced analytics dramatically reduce the need for experts in different parts of the infrastructure, scale linearly as the size of the operation increases and cut operational complexity by 90 percent.
Manage Resource Management Using Machine Learning
Applying machine learning to infrastructure management means intelligent software could learn about operational patterns, anticipate capacity needs, raise alerts about security anomalies, self-monitor and self-heal your environment in the face of failures, intelligently apply security patches and automatically upgrade hardware and software systems without any downtime. The next generation of infrastructure management will be driven by advances in machine learning and artificial intelligence, where the infrastructure is able to basically “drive itself” with minimal user intervention.
This will help engineering IT teams optimize resource usage and capacity based on current and future dev/test demand and also be able to better handle the availability and performance they can deliver to their engineering teams. A lot of efficient resource management comes down to capacity planning, utilization monitoring, right-sizing of workloads, demand forecasting and detecting zombie VMs and unused resources.
Demand forecasting and capacity planning can be viewed as ensuring there is sufficient capacity and redundancy to serve projected future demand with the required availability. Capacity planning should consider organic growth, which stems from natural service adoption and usage by dev/test teams. Having intelligent predictive analytics and machine learning can help greatly with accurate forecasting, alerting and providing lead time for acquiring additional capacity.
Better insights into how the infrastructure is performing can also help in fine-tuning performance of end user workloads. For example, an intelligent system that is monitoring a workload for storage performance might recommend using SSDs instead of spindles to increase the IOPS and improve workload responsiveness.
An intelligent private cloud platform that uses hyperconverged scale-out designs, machine learning software, and a SaaS-based operational console can reduce complexity and increase the agility of dev/test teams.
About the Author / Kamesh Pemmaraju
Kamesh Pemmaraju leads product management, product marketing, and technology partnerships at ZeroStack. Kamesh is a seasoned product management/marketing leader with a strong engineering and consulting background. In his most recent product roles at Mirantis and Dell, he focused on delivering private and hybrid cloud solutions to enterprises. He holds a Master of Science in Computer Science from Indian Institute of Science. Connect with him on LinkedIn and Twitter.

 Shawn Minto is the senior director of Technical Services and Support at
 Sam Fell is the Head of Marketing at Electric Cloud, responsible for driving awareness and demand for our DevOps Release Automation and Acceleration solutions. For 20 years, Sam has helped companies achieve success by marketing, selling, and implementing DevOps Release Automation, IT Change Management and Application Performance Management solutions. Prior to joining Electric Cloud, Sam held leadership roles at BMC, CA, Marimba and Nimsoft. Follow him on
 appOrbit recently came out of stealth mode with an




 Kamesh Pemmaraju leads product management, product marketing, and technology partnerships at