Category: DevOps Toolbox

  • Tailoring Enterprise Collaboration: Strategies for Success

    Tailoring Enterprise Collaboration: Strategies for Success

    In the age of SCRUM, Agile and DevOps, developers collaborate with their peers and colleagues more than ever before. Many developers already use a variety of collaboration tools on a daily basis, such as a team messaging application, an online discussion forum, or an open code repository.

    But while developers love to collaborate, it can be easy for them to forget that not everyone collaborates the same way. By focusing solely on collaboration products and solutions that work well for their development teams, developers are missing the opportunity to provide tailor-made collaboration capabilities to the applications they’re building, or to their entire company or organization. When it comes to developing collaboration capabilities for their organization, developers often fall short of business expectations, as their own personal needs differ from their constituents.

    Tailor-Made Collaboration

    Here are three recommendations on how to tailor a collaboration solution that will fit well for an entire organization:

    Beware of the “One Size Fits All” Approach

    Today’s array of collaboration tools is more sophisticated than many developers realize. In fact, incorrect assumptions about which platforms are “best of breed” result in rolling out collaboration technology that may have technical but not business, appeal. As many developers hold the keys to the platforms that are eventually put into practice within their organization, this leaves executives at the hands of those who often see collaboration platforms as group chat spaces and wikis for sharing code.

    However, other lines of business don’t only collaborate with chats or wikis. A business with thousands of employees located around the world cannot only use general correspondence streams to acquire the information they need to successfully do their jobs. It is unrealistic to expect that messaging platforms alone can support groups of people across departments who do not necessarily understand one another. For instance, IT and Marketing departments’ daily operations are far from the same—so then why would a “one size fits all” approach for workplace teamwork be successful?

    Developers must look beyond topline technologies and examine a full range of collaboration solutions that can also provide centralized repositories for information, customized landing pages and unified communication capabilities.

    Identify and Understand Communication Gaps in Business Processes

    As departments differ, mindsets across organizations vary as well. The developer creating the back end of the platform operates in a unique workflow and framework from those utilizing the platform. It is, therefore, critical to demonstrate a clear integration between different levels of the organization to create a unified understanding of how people work.

    Individuals who rely on each other to accomplish tasks need to interact in a variety of ways, including through a centrally located platform to converse on ideas and join forces on project development. To create useful online spaces, developers should attend meetings with other teams to truly understand their needs. By doing so, they will gain perspective on how their peers operate in the workplace, and develop a platform that is increasingly applicable and effective.

    Build a Plan for Scale and Growth

    By better understanding business needs, developers can predict the appropriate scaling requirements for their collaboration solution. Scaling a collaboration solution may involve setting up workspaces and areas for mass access to thousands or tens of thousands of people, but many of the leading tools cannot scale past several thousand users. For global businesses with multiple constituents and varying workflows, messaging-based approaches may not suffice on their own, as they are not scalable methods to distribute content to a high volume of people.

    Ultimately, enterprise collaboration work patterns are shifting toward more speed, and developers are at the heart of the transition. However, being overly reliant on the technical appeal of specific collaboration tools will not lead to the best outcomes for the business.  Developers need to design and build collaboration solutions that not only assist their colleagues to communicate, but also help drive collaboration that impacts business outcomes at scale. By understanding the nature of the way an organization needs to collaborate, developers can provide solutions that directly contribute to increased revenue, empowering them as strategic partners in organizational change.

    About the Author / Stephen Hamrick

    Stephen Hamrick is VP Product Management, Collaboration Software at SAP. Based in Palo Alto, California, Steve leads the product management, user experience, and documentation teams for enterprise social software products at SAP. He has spent the last 20 years of his career in the enterprise software technology industry, focused primarily on collaboration and social software. Connect with him on LinkedIn and Twitter.

  • DevOps 2.0 for Digital Transformation

    DevOps 2.0 for Digital Transformation

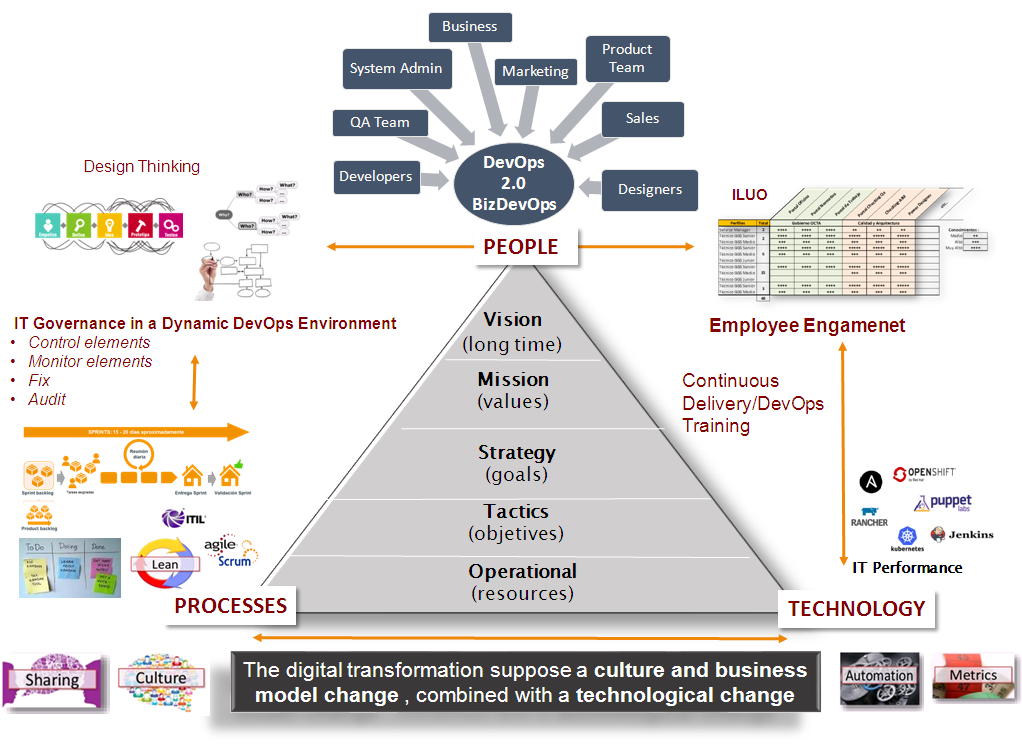
    We already know that DevOps is a culture, a movement, a philosophy of software development and delivery. It focuses on the communication, collaboration and continuous integration of the entire organization—a new conception of software development whose adoption is not easy. It aims to streamline software delivery by removing barriers between developers and IT operations teams. It also aims to reduce the inefficiencies of processes, adopting new tools, and even proposing changes in business architecture.

    Agile practices allow development teams to deliver iteratively more frequently, among other things. In DevOps, the entire process cycle is automated to achieve continuous integration and continuous deployments (CI/CD). The test and safety teams are involved from start to finish following an end-to-end strategy. At the same time, with the principles of Lean, we have removed from the whole process what does not add value. Thus, it is getting more productivity, maximum value and improvement in the time to market.

    Talking about DevOps is thinking about techniques, patterns and good practices. It will help us to provide our organization with an efficient software architecture—an architecture based on microservices, with everything-as-a-service mentality (XaaS). We are talking about container, automation, elasticity, self-scaling, infrastructure such as code, monitoring, configuration management, self-sustaining and adaptable systems and ecosystem, all of which allow us to deliver value with fast, reliable and frequent developments, not to mention zero downtime and, of course, the ability to undo the changes.

    How Do We Prepare to Meet User Expectations?

    DevOps aims to help an organization to produce software products and services quickly. But end users are becoming more and more demanding. We must use techniques that allow us to make faster, functional deliveries to the production environment, mitigating the risk involved.

    At present, we face users with greater technological knowledge and greater expectations in the dynamic and interactive experience than we used to some years ago. This has evolved and given rise new one called DevOps 2.0 or BizDevOps (business, development and operations).

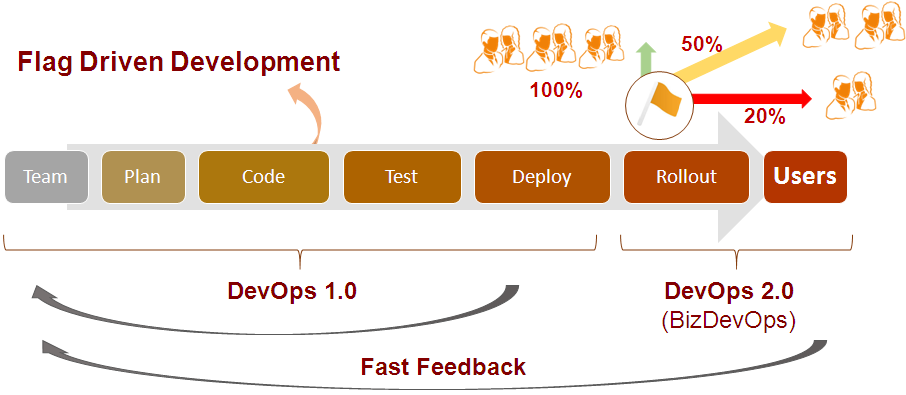
    DevOps 1.0, as the origin of the movement, was focused on operations teams giving continuous feedback to development teams as well as to SQA teams. However, DevOps 2.0 is now focused on extending the benefits of feedback to the entire organization (marketing, sales, product, etc.). This is what will allow a greater adaptation to the IT boom and the digital transformation (IoT, intelligent platforms, big data, etc.). Additional benefit of DevOps 2.0 is faster continuous software deliveries, without compromising the stability of systems in production.

    Toggling Features or Feature Flags

    At this point, the key is to use techniques that helps to decouple the software delivery of new functionalities. In other words, it is about making these new functionalities available to the end user based on business rules instead of the operation teams. The idea would be that, for instance, marketing and sales department can decide, using “flags,” when to release or enable a new functionality to the end user. It will allow us to deploy new functionalities to the production environment more frequently without enabling them to the end user. This removes the “fear” generated by the daily deployment processes in production environments. This is what is known, in DevOps 2.0, as the rollout.

    Using this simple best practice for development, called Flag Driven Development, we do not make available the new functionality to 100 percent of users. It will be delivery in stages, starting with 1 percent of users, then with 10 percent, then with 30 percent, etc. with the ability to quickly enable or disable the functionality when something does not work as expected. In addition, it allows us to make available different versions of a functionality for different types of users (customer segmentation). There are several SaaS models and open-source solutions we can use to implement this type of techniques like Feature flags, toggles or controls.

    What are the Benefits of DevOps 2.0 Techniques?

    The use of this type of techniques during the development process provides these benefits:

    • Quick scaling
    • Stability of the system
    • Integrity of the applications is not compromised.

    This way we succeed in reducing the risk associated to each new delivery of functionality, in any productive environment. Business stakeholders can control when new features are available to end users, who continuously demand new changes and improvements.

    For organizations, DevOps 2.0 will bring DevOps power to non-technical teams such as marketing, design, sales and business. Now all teams will have the skills and responsibilities that are required in a DevOps culture. It enhances the confidence, communication and feedback that is needed from all teams in a DevOps strategy.

    Therefore, one of the major pillars of the DevOps 2.0 approach is the ability to control, through a control panel interface, the launch of new features of applications in production environments. This process would be launched in a controlled way by both technical and non-technical people. Also, the process will be separate from the development and continuous deployment.

    At the same time, this type of coding techniques will allow to perform real-time analytics, making changes to the functionalities of a system that may also impact in the application performance monitoring (APM) tools. This makes it possible to determine when a particular functionality is degrading the global system performance and needs to be disabled quickly, as well as identify which functionalities are improving the end user experience (UI/UX).

    There are a lot of articles about these “Fast Feedback” practices. I hope this article help you better understand the potential impact of DevOps on your organization.

    About the Author / Jesús Pérez Franco

    Jesús Pérez Franco is an Operations Manager at Gfi Spain. His big passions are Agile Development and DevOps Continuos Delivery (Continuous Integration, Deployment, QA Automation and Infrastructure as Code, etc.). Connect with him on Twitter and LinkedIn.

  • Feature Branching vs. Feature Flags: What’s the Right Tool for the Job?

    Feature Branching vs. Feature Flags: What’s the Right Tool for the Job?

    A dev team’s branch management strategy can have a significant impact on the rate at which it can release high-quality software. In this article we’ll explore the pros and cons of several different approaches for enabling multiple concurrent streams of dev work in the same codebase. We’ll see that two major factors—the cost of merge conflicts and the ability to release streams of work independently—are often in tension, but that Feature Flags provide a way to resolve that tension.

    Merge Conflicts

    New products start off as a small codebase, usually only being worked on by a handful of developers. This situation doesn’t call for much formal process. However, even when a team consists of just two devs, it’s still preferable to avoid working on the same files at the same time to avoid merge conflicts.

    Unfortunately, even when we’re trying to avoid stepping on each other’s toes, it’s still pretty common for work streams that seem unrelated to end up touching the same files. Sometimes it’s these unexpected merge conflicts that can cause the most pain—any iOS developer who’s been around the block a few times probably has acquired some scar tissue from an epic three-way XIB merge in their past. In this article we’ll explore some different ways to deal with the challenge of merge conflicts when multiple developers are working on the same codebase.

    Some people might argue that merge conflicts aren’t that big a deal these days and mostly are solved if you just use modern tools such as Git. This is unfortunately not true. Git certainly makes creating branches trivial, but it does not always make merging parallel changes within those branches trivial. It has some powerful features to automatically merge changes when possible. These automatic merge heuristics can feel almost magical at times, but they are not actually magical. If you make parallel changes that affect a large XML file—for example, a XIB or an IDE project file—Git likely will not be able to merge those without human assistance.

    Most importantly, Git cannot automatically resolve semantic conflicts. For example, imagine that in one branch Alice renames a method and in another branch Bob adds a new usage of that method. When those two branches are merged, Git will do nothing to help resolve the fact that Bob’s branch is calling a method using the old name. Bob’s code is calling a method that no longer exists. In fact, Git will not give Alice or Bob any clue that there is a conflict, since these semantic conflicts aren’t detectable by our current set of tools.

    We’ll only find semantic conflicts when we try to compile our merged codebase, and even then only a subset of them. If the codebase is in a dynamically typed language such as javascript, we might not find out until our users start reporting app crashes in production.

    Beyond the productivity hit of having to manually resolve these inevitable merge conflicts, the spectre of introducing a conflict can have a more pernicious, long-term effect on a codebase. A developer who sees an opportunity to incrementally improve the quality of the codebase is slightly disincentivized to do so if they sense that it could lead to a merge conflict.

    The calculus for whether the effort of making a small improvement is worth the investment gets shifted as the cost of that change becomes higher. This introduces a subtle drag working against the internal quality of a codebase over time. What’s more, the type of small but broad refactorings that can gradually improve a codebase—or stop it gradually degrading—are exactly the type of changes that often lead to a merge conflict. In my opinion, this is the true hidden cost of branch-based development—it disincentivizes the sort of “boy scout rule” improvements that can prevent areas of a codebase from gradually degrading into no-go zones.

    So, having established that merge conflicts are a Bad Thing, let’s look at how we might avoid them.

    Working Directly on Master

    A small team starting out on a new app might initially try to mitigate the risk of a big unexpected merge conflict by having all devs push frequently to a shared master branch—one of the central tenets of continuous integration. When everyone is frequently synchronizing their changes in a shared master branch, an unexpected merge conflict is revealed earlier and is easier to deal with.
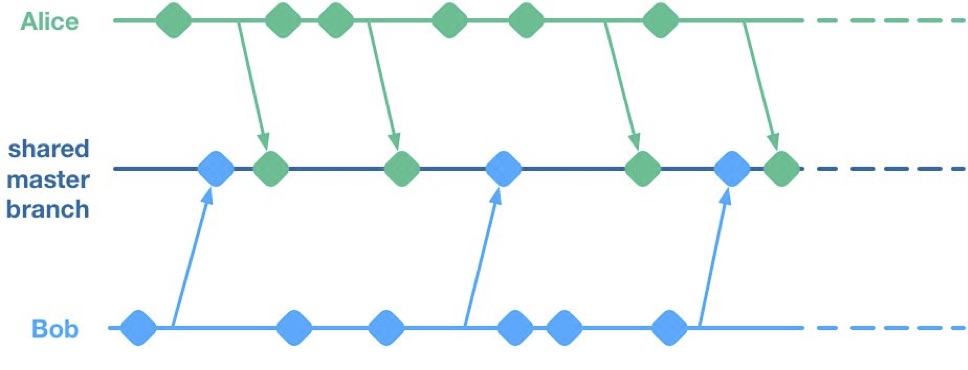
    Unfortunately, having multiple streams of work landing on a shared master branch comes with a big drawback: If any of the streams of work are not ready for release, then nothing on the shared branch can be released. Let’s see why using a hypothetical example.

    Alice and Bob are a two-dev team working on a mobile app. They have two streams of work in progress. Bob is working on a big overhaul of how user preferences work, while Alice is finishing off a critical new feature for the app which the big bosses have decreed must be pushed to the app store by the end of the week. This team is trying to avoid big merge conflicts by frequently pushing their code changes to a shared master branch as they go.

    On Thursday, Alice is wrapping up her changes and doing some testing. While giving the app a general run-through she notices that the user preferences section is crashing. She asks Bob if he knows why. Bob explains that he’s in the middle of overhauling that area of the code. It’s taken a little longer than he expected and it might be buggy for a while. Alice gives Bob a look. She explains to him that her feature has to get to the app store this week. Bob gulps. Over the course of two long days Bob and Alice are able to roll back Bob’s changes, some of which had gotten tangled up with changes that Alice had been making as part of her new feature. They manage to ship to the app store by Saturday, and a crisis is averted.

    We see here that because Alice and Bob were both committing to a shared branch, their independent streams of work became entangled. Alice could not release her changes without Bob’s and vice versa. This is the huge drawback of working on a shared branch—although we will discover later on that there are ways to mitigate this.

    Feature Branches

    To avoid this issue of coupled work streams, dev teams very often will move away from pushing in-progress code onto a shared branch. Some teams will opt to continue working on master on their local machines but only push to the team’s shared repo once the work is complete. Other teams will opt to use Feature Branches, maintaining separate streams of work on isolated branches and only merging them into master once they’re complete.

    As an aside, it’s interesting to note that when using a distributed source control system like Git, these two approaches are essentially equivalent; the only difference is whether the unmerged in-progress changes are visible in a remote feature branch or hidden on a dev’s local master. As such, I’ll talk about both variants as Feature Branching.
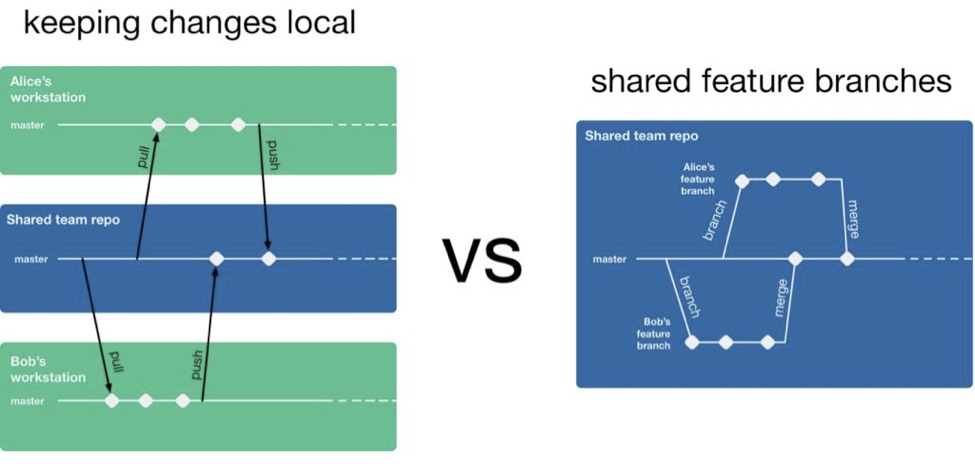
    So, if a team is using feature branching, then all their problems are solved, right? Unfortunately not. We’ve now re-introduced the risk of painful merges. Work that is being done on a feature branch is not integrated with other changes until it is merged to a shared master branch. Whenever two streams of work both touch the same files, either inadvertently or intentionally, there is a latent merge conflict which continues to grow in size until one of those stream’s branch lands on master. Some teams will try to mitigate this issue by frequently merging changes from master back into in-flight feature branches.
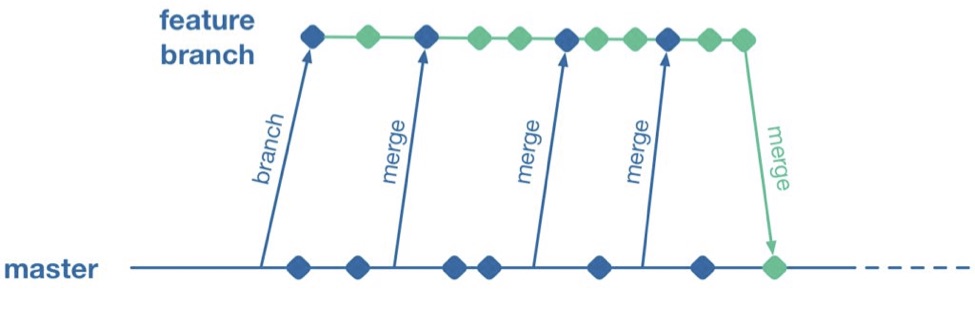
    However, this does not help when parallel changes are occurring on isolated branches. Alice’s branch will only see Bob’s changes when his feature branch lands on master. The latent merge conflict between these parallel changes is now waiting for Alice the next time she merges from master.
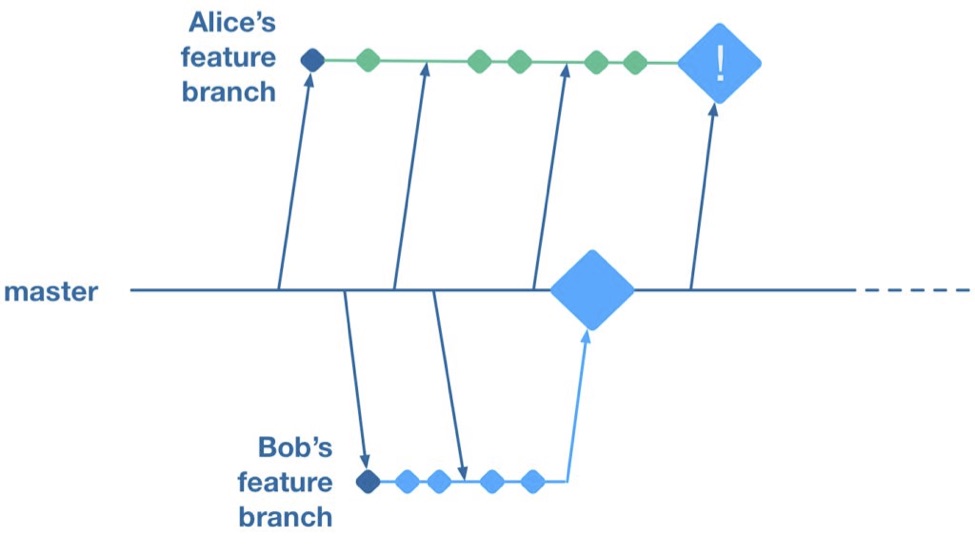
    (Thanks to Martin Fowler’s feature branch writeup for inspiring the above illustration)

    Some teams attempt to solve this problem by “cross-merging”—pulling work on one feature branch across into another feature branch to break down the size of latent merge conflicts between those branches.
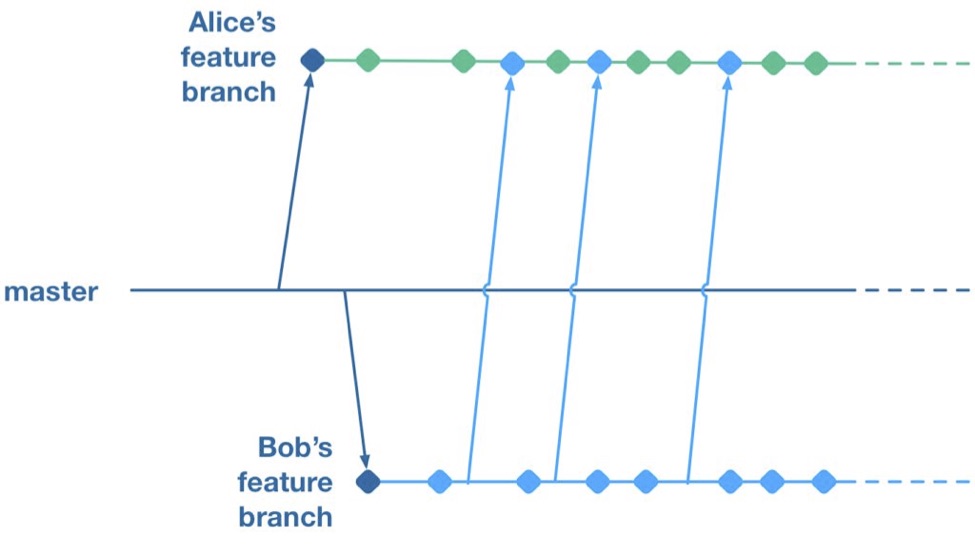
    However, as soon as you merge two feature branches together you’ve essentially created a shared branch of in-progress work, and are back to the same problem as teams who are pushing in-progress changes to a shared master: Code changes from both work streams are now intermingled. Your features are now coupled together and cannot be released independently.

    To summarize, feature branches allow teams to decouple streams of work such that they can be released independently. However, they introduce a risk of large merge conflicts when parallel feature branches contain large sets of changes. Remerging from master into feature branches only helps once parallel work has already landed, and cross-merging between branches couples features together in the same way as working on a shared master.

    Feature Flags

    What alternative does a team have if they want to avoid the merge conflict risks Feature Branches introduce? They could go back to frequently integrating changes on trunk, but we established that this has the major drawback that formerly independent streams of work are now coupled together and cannot be released independently. This is where a technique called feature flags (aka feature toggle, bits or flippers) can help.

    A feature flag is a way to isolate work-in-progress code by placing it behind a “flag” or “toggle.” The work-in-progress code will only be exercised if the flag is flipped on. Otherwise, it will sit within the codebase as “latent code.” Here’s a sketch of how a basic feature flag might be used:

    if( featureFlags.isOn(“my-new-feature”) ){
    showNewFeatureInUI();
    }

    Unless the my-new-feature flag has been configured as “on,” the new feature will not be exposed within the app’s UI. This means the app can be released even if the code implementing new feature is totally bug-ridden, as long as that feature’s flag is flipped off.

    By using feature flags, in-progress changes can be pushed into a shared branch without blocking release from that branch. If Bob is halfway through his feature and Alice wants to push a release of her feature, the team can do that by creating a release where Alice’s completed feature is flipped on while Bob’s half-finished feature is flipped off. We get the benefit of continuous integration of developer work streams (reduced risk from merge conflicts) while still keeping release of those work streams decoupled.

    This technique is not particularly new. It is part of a family of techniques sometimes referred to as trunk-based development (you can tell the technique is not new because the name uses trunk rather than the mastermoniker, which is more common today due to git’s predominance). Flickr, Etsy, Github and Facebook are some better-known proponents of the technique. Facebook’s use of feature flags is one of the key enablers for its famous ability to deploy facebook.com from a shared branch twice daily.

    Drawbacks of Feature Flags

    As with the other approaches discussed so far, feature flags have their share of drawbacks. They introduce a fair amount of noise into a codebase as we now need to explicitly implement some sort of branching logic for any incomplete feature. This noise can lead to some messy code over time unless care is taken to retire old feature flags once they are no longer necessary. Testers can take a while to get comfortable with feature-flagged apps—the idea of shipping unfinished, untested code to the app store takes a while to get used to. If the flags can be controlled remotely at run time, then teams need to understand that the new configuration of flags must be tested before being applied to apps deployed to end users.

    Finally, certain types of changes are particularly hard to protect via feature flags—broad but shallow changes that touch a lot of files can be a challenge. Happily, feature flagging is not an all-or-nothing approach; feature branches can still be used for a change that would be particularly fiddly to implement behind a flag.

    Succeeding with Feature Flags

    When a team starts to adopt feature flagging they will usually run afoul of some of the challenges discussed above, and eventually figure out ways to mitigate them. Here are some of those techniques for working successfully in a feature-flagged codebase.

    Expire Your Flags

    A lot of teams get a bit flag-happy when they first start using the approach. They tend to introduce a lot of flags, but not take the time to retire the flags once they not longer need to control whether a feature is on or off. Make sure to take the time to retire old flags—they introduce design drag in your codebase and confusion when managing flags. Some teams take quite aggressive approaches ensure old flags are expired, such as setting “timebombs” when they create a flag, or having it throw an exception if it’s still in use after a certain period of time. Other techniques include adding a flag removal task to the team’s backlog at the time the flag is created as a reminder.

    Flags Aren’t a Silver Bullet

    It doesn’t always make sense to use a feature flag for a new stream of work. Flags lend themselves best to a new feature or alternative feature where access to the feature can be controlled from a single point in the code—often by showing or hiding a button or changing what happens when you tap some part of the UI. Other types of work, such as internal refactoring, is hard to protect behind a flag. For that type of work, consider using a feature branch, ideally breaking the work down into smaller chunks that can be implemented incrementally in a series of branches rather than one long-lived branch. This will reduce the risk of a large merge conflict growing over time.

    Summary

    Feature flagging and feature branches are both ways to decouple parallel code changes and allow teams to release changes with less coordination overhead. Feature branches are easy to get started with, but can lead to painful merge conflicts. This risk of merge conflicts tends to disincentivize making incremental improvements to a codebase, and can lead to areas of the codebase becoming “no go” zones. Feature flags allow teams to practice true continuous integration and totally decouple code changes from feature release, at the cost of some complexity in implementing each flag.

    Feature flags are not a silver bullet and aren’t always the right choice, but it’s easy for a team to experiment with the approach. You can get started simply with a single hard-coded if/else statement, see how it goes and take it from there.

    About the Author / Pete Hodgson
    Pete Hodgson is a consultant to Rollout.io, a software engineer and an architect. His clients range from early-stage San Francisco startups to Fortune 50 enterprises, focused on enabling continuous delivery of software at a sustainable pace via practices like test automation, feature flags, trunk-based development and DevOps. Pete is a frequent podcast panelist, regular conference speaker in the US and Europe, and a contributing author.
  • Best Practices for Internal Communication in DevOps

    Best Practices for Internal Communication in DevOps

    DevOps has become a widely popular method of collaboration in the IT world. The combination of development, operations and quality assurance, DevOps requires every project have clear communication channels between development teams and individuals. In this article, we’re going to explore some of the best practices for internal communication within the DevOps structure.

    Software development is the game that runs on invention and communication. Therefore, communication methods and channels play a significant role in project success. Better communication between managers, engineers, developers and testers leads to better performance and more satisfying results. Each practice presented can help improve communication within teams and make your work more synchronized and efficient.

    Digital Communication Channels

    Scott W. Ambler notes in his communication diagram, e-mail communication is noted as more effective than any other documentation options, including paper memos, audio tapes and others. E-mail is the best way to share official documents and company memos, making it more suitable for external communication in the DevOps project. But while most individuals today are able to access their e-mail on their smartphones, and e-mail enables users to send large attachments and contact several team members at once, DevOps teams tend to rely on more interactive communication channels.

    Depending on the project needs and the preferences of team members, internal communication can be either through project collaboration apps, an intranet or even the usual communication apps or social media. Since Ambler’s diagram shows that video conversation is by far the most effective form of project communication (aside from face-to-face meetings), most project managers rely on apps with video-calling and videoconferencing functionality.

    Regular Meetings

    Regular meetings are the backbone of the DevOps communication. They can be organized in-person or through videoconferencing apps. Same as with the Agile Project Management structure, the DevOps team should meet at least twice a week. Preferably, the meetings should occur on a daily basis. The Monday or morning meeting can be used for assigning tasks to each team member and the Friday or end-of-day meeting can be used for assessing completed work and for future planning.

    Building Soft Skills

    Unfortunately, HR practices in many industries rely on stereotypes. One of the most prominent stereotypes about IT professionals is their lack of interpersonal skills. Although some engineers and developers fall into this generalization, their knowledge and interests go far beyond IT and technology topics. Still, even the most talkative and assertive members of the development team need to work on their soft skills to improve the team’s communication.

    Improved soft skills enable team members to collaborate more effectively and to develop strong working relationships. The first task of every manager is to find the soft skills already present in your team. This will give the team the chance to find the best opportunities for further development. After the initial skill appraisal, manager can enroll members in courses for assertive communication, negotiation and conflict-solving, depending on their needs and current capabilities.

    Importance of Time Management

    The whole DevOps paradigm strongly relies on effective time management. The implementation of the DevOps model often changes the whole development process and wipes out all the previous scheduling and time-management patterns. A good manager needs to motivate his or her team to change their long-held habits and pace their daily routines so they can keep up with the new organizational patterns.

    We already mentioned how regular meetings are essential for successful DevOps implementation. When organizing the meeting, schedule managers need to leave enough working time so each team member can effectively work on their tasks. Too many interruptions can break up the work process make it difficult for employees to focus. Effective time management relies on both team and individual needs and gives your team the flexibility to work as efficiently as possible.

    Use of Data Insights

    Internal communication on DevOps projects needs to be smart. It needs to be specific, measurable, attainable, realistic and timely, and one of the ways to achieve this is to use accumulated data from current and previous projects. The thorough analysis of accumulated data can give managers more details on:

    • The average number of working hours the team will need to release a new app, make various updates or make patches;
    • How to make the team’s communication more efficient;
    • Identifying the areas where the development strategy is losing its momentum; and
    • Understanding how each task influences the project delivery.

    Constant adaptation and changes in work processes is the base for successful DevOps implementation. This ideal can be achieved only through effective communication between team members. Communication also requires time, so the only way to ensure effective DevOps work is to combine strategic skills, process development, excellent time management and smart data insights.

    About the Author / Nate Vickrey

    Nate Vickrey is a business consultant and an online author. He is mostly engaged in finding the best solutions and latest trends regarding company management and culture. Nate is also the executive editor at one Bizzmark Blog. You can follow Nate’s work on his Twitter page.
  • 5 Team Skills That Make DevOps a Success

    5 Team Skills That Make DevOps a Success

    When starting their DevOps journey, your team will discover it needs to develop some new skills. Most likely the team is good at typing code and solving issues, but what about the soft skills?

    Many teams have to learn how to deal with issues themselves—as self-supporting teams, there is no longer a manager who will help them out and tell them what to do.

    During the Phoenix Project DevOps business simulation, the majority of teams discover collaboration and communication are skills they lack. I am often surprised how few people can really facilitate standups, retrospectives, Andon-sessions and other communication methods.

    Here are the five team skills that participants recognize as core skills they learn (or could learn) during the simulation.

    The Standup

    The standup is a very powerful way to share knowledge about certain issues. The team will stand together for a short time and discuss an issue that blocks the flow, needs clarification or needs to be high priority. So, who should initiate this standup and who should lead it? I’ve noticed a lot of participants find it very difficult to manage this standup initally, but after a few times the team discovers the key elements of a successful standup:

    • Chose a facilitator. Someone who is leading this session. It doesn’t matter who (it doesn’t have to be a manager).
    • Share the focus: What are we going to talk about?
    • Keep it short (time is ticking).
    • Make sure we all understand the outcome.
    • The importance of listening and engagement.

    Facilitating a Retrospective Session

    DevOps is also about continuous learning and experimenting. One of the important steps in this process is retrospective. This activity explores the past round of work and reviews what went OK and what needs to be improved. Again, during the simulations I discovered that not many participants know how to execute this activity. After being shown the right example, the team often can perform this activity themselves. This is what teams learned during the simulation:

    • Someone from the team must facilitate this process.
    • Make sure the improvement is supported and understood by the whole team.
    • Test the improvement before to applying it.
    • Record the discoveries—this becomes part of the visual management system and part of the team backlog of improvement needs.
    • This team skill is one of the skills that more than one team member should be able to execute.

    Managing the KanBan

    During a project, teams sometimes will have standup moments to discuss the work visualized on their KanBan. Work will move from backlog to doing and done, and new priorities will change the order of work. During the simulation participants will take the lead in this process, but some don’t find this easy. After the sessions they discover:

    • Use standups to discuss the changes on the KanBan, make sure the team is fully involved when moving notes around.
    • Challenge participants to share their thoughts. Saying “yes” doesn’t always mean “yes.”
    • Errors are made, but that doesn’t mean somebody has failed and should be punished. Keep the session safe and open.
    • The KanBan is a form of visual management system (VMS). The VMS is not the goal—it is an instrument and must help the team to visualize flow, limit work in progress, drive productivity through an awareness of what people are working on and continuously improve the process.
    • Make sure at the end of the session, all participants know what’s agreed.

    Managing an ‘Andon’ Session

    ‘Andon’ is a very powerful instrument to explore a situation that stopped the flow. As soon as the flow stops, someone “pulls the rope” and the team “swarms around” to investigate the error and try to continue the flow as quickly as possible. This session should be led by a team member; it doesn’t matter who. During this session, the team discovers the following learning:

    • Make sure the session is short and focused on fixing this blockage and restarting the flow.
    • Make sure we are not blaming each other; it should be about exploring what stopped the flow, fixing it and agreeing how to prevent it from happening again.
    • Make sure the whole teams swarms around and participates.
    • Create a safe environment.

    Collaboration

    Doing the work is not always easy. Sometimes we don’t know what to do. Sometimes we need help, and sometimes we are not happy with the actions of a team member. This is what collaboration is all about.

    One of the first aspects of collaboration is helping each other. But, this is not always effective. Sometimes it’s even disruptive or we just take some work from somebody else if we think he is too busy. Here’s what participants learned about collaboration during the simulation:

    • We have to avoid “compensational behavior.” This is about taking other people’s work with the intention to help the other. Sometimes this person doesn’t know you took the work and he or she does it again, creating unnecessary double work.
    • Collaboration is about shared goals and shared processes. We should all know what we are doing and how.
    • It’s also about clear roles and responsibilities. If you know what your colleague is doing, you know what you have to do. And the other way around.
    • You must have an open team culture in which it is also safe to say you don’t know and to ask for help.
    • Collaboration is fun, and it gives energy if we as a team achieves something.

    Conclusion

    I have visited many global DevOps conferences in the previous years and have listened to numerous speakers declaring, “It’s all about people.” And they were right. Unfortunately, the audience often did not get many useful answers.

    A high-performing collaborative team needs team players who know how to deal with the collaboration and communication issues themselves without needing management intervention.

    Teams will have to go through the stages made famous by Bruce Wayne Tuckman (Forming, Storming, Norming, Performing and Adjourning) to become an effective, collaborative team.

    Continuous learning is a key success factor and a critical competency for any DevOps team. Why not start this learning journey in a safe and challenging environment?

    A simulation such as the Phoenix Project is a very powerful instrument to teach teams how to collaborate and become high-performing. The environment is safe and feels like the real work environment. Participating in this simulation with an actual team allows you to capture and agree on actions to takeaway. Outcomes can easily be transferred to day-to-day work.

    I wish you a lot of soft skills.

    About the Author / Jan Schilt

    Jan Schilt is owner of GamingWorks. His background is Human Resource Development (MSc). Within GamingWorks he is responsible for Business Simulation design, Facilitation and Train the Trainer. He is also an expert in developing learning activities related to organizational change. He builds all the simulations and has delivered more than 300 workshops worldwide.


  • SRE vs. DevOps — a False Distinction?

    SRE vs. DevOps — a False Distinction?

    Just a few days before he died at the beginning of the 1990s, a wise man taught us that “the show must go on.” Freddie Mercury’s parting words have long provided the guiding light for many, if not all, ops teams. In their eyes, the production environment should be exposed to minimum risk, even at the expense of new features and problem resolution.

    About 10 years ago, Google decided to change its approach to production management. It took the company only a few years to realize that while R&D focused on creating new features and pushing them to production, the Operations group was trying to keep production as stable as possible—the two teams were pulling in opposite directions. This tension arose due to the groups’ different backgrounds, skill sets, incentives and metrics by which they were measured.

    Trying to bridge this gap between the two groups, one of Google’s ops leaders, Ben Treynor, thought of an innovative solution. Instead of having an Ops team built solely from system administrators, software engineers—with an R&D background and mentality—could enrich the way the team worked with the development group, change its goals and help with automating solutions.

    Site Reliability Engineering, or SRE

    And so, the Site Reliability Engineering position was created. According to Google, SRE engineers are responsible for the stability of the production environment, but at the same time are committed to new features and operational improvement. Google decided its SRE teams should be composed of 50 percent software engineers and 50 percent system administrators. The engineers were driven to use software as a way of solving problems and perfecting what had historically been solved by hand. They integrated easily with the development team, and encouraged code quality improvements and automation testing.

    Understanding the value of SRE, several organizations of various sizes decided to embrace its principles. Some, such as Dropbox, Netflix and Github, are well-known for being at the forefront of technology leadership.

    Wait, Isn’t That DevOps?

    DevOps is a more recent movement, designed to help organizations’ IT department move in agile and performant ways. It builds a healthy working relationship between the Operations staff and Dev team, allowing each to see how their work influences and affects the other. By combining knowledge and effort, DevOps should produce a more robust, reliable, agile product.

    Both SRE and DevOps are methodologies addressing organizations’ needs for production operation management. But the differences between the two doctrines are quite significant: While DevOps raise problems and dispatch them to Dev to solve, the SRE approach is to find problems and solve some of them themselves. While DevOps teams would usually choose the more conservative approach, leaving the production environment untouched unless absolutely necessary, SREs are more confident in their ability to maintain a stable production environment and push for rapid changes and software updates. Not unlike the DevOps team, SREs also thrive on a stable production environment, but one of the SRE team’s goals is to improve performance and operational efficiency.

    Google tried a few approaches to implementing the SRE process before finding the one that suited them best. One of these approaches attempted to tie the number of permitted releases to the product’s stability. The principle underlying this process is that new releases are green-lighted based on current product performance.

    For each service, the SRE team sets a service-level agreement (SLA) that defines how reliable the system needs to be to end users. If the team agrees on a 99.9 percent SLA, that gives them an error budget of 0.1 percent. An error budget is exactly what the name suggests: the maximum allowable threshold for errors and outages. Here’s the interesting thing: the development team can “spend” this error budget in any way they like. If the product is currently running flawlessly, with few or no errors, they can launch whatever they want, whenever they want. Conversely, if they have met or exceeded the error budget, and are operating at or below the defined SLA, all new releases are frozen until they reduce the number of errors to a level that allows the launch to proceed. This process ensures that both the SREs and developers have a strong incentive to minimize the number of errors in production.

    Another interesting approach recommended by Treynor, which is more related to SRE professionalism and efficiency, is allowing SREs to move between projects. Moreover, he suggests allowing SRE engineers to move to development, and even the other way around. As the work done by both teams is similar, these transitions help the Ops team gain better and deeper knowledge of the product and code, and bring the Dev teams into the production space to help them understand its challenges. This strongly promotes a team atmosphere, rather than one in which an individual feels that “I’m on the SRE team for this product.” As part of this approach, Treynor had Dev teams handle 5 percent of the operations workload. This, according to many organizations, adds to the SRE team’s motivation and effectiveness.

    Riddles in the Dark

    Well, SRE seems perfect. As already stated, several large-scale organizations have chosen to move some of their production operations from old Ops to SRE. However, there are still a few questions that need to be asked:

    Is the position of SysAdmin (production/ops) no longer relevant for SysAdmins?

    Historically, almost all system administrators have come into their roles through tech support and similar work, or even just running Linux on their desktops and then transitioning into server work. It should be pretty clear that the same path is not available into SRE. To retain their positions, SysAdmins should now be more code-oriented, have better technological knowledge and be receptive to new methods of conducting the work they already do.

    Can an SRE team prevent production incidents?

    One of the strengths of a professional site reliability engineer is the ability to handle the growth of production load and traffic in-house. Monitoring and analyzing processes and logs with platforms such as the ELK Stack is part of the day-to-day workload, and the team should be able to identify problems as they occur, and even foresee risks to software stability. The power of this position—based on the skill set it requires—lies in developing solutions for these problems and risks. As Ciara, a software engineer in Google’s cloud storage SRE team, described it in a “Life in Google” post, “We solve cooler problems in cooler ways.”

    Are we doing DevOps or are we doing SRE?

    This question is usually asked by people trying to position themselves in the Operations world. According to many companies that implemented SRE in a slightly different way than Google, you don’t have to decide. At Reddit, ops engineers work on reducing toil, improving deployment and scaling processes, but they are referred to as “DevOps.”

    At Logz.io, we bridge the gap between developers and production through the use of automated monitoring and performance stress-testing. And we personally refer to it as “DevOps” rather than “SRE.”

    So, is it Just a Question of Context?

    In her blog, Charity Majors talks about SRE and DevOps being two different operational approaches that any organization can choose to work by, but insists on emphasizing that there is no “correct” approach. Although Google and Dropbox have decided on SRE, this does not mean the rest of the world should do so as well. What fits Google’s needs and organizational philosophy does not necessarily work for other orgs—at any scale. Moreover, Charity believes that DevOps, having grown and evolved within a broader variety of software organizations, is the more flexible, collaborative and adaptable approach, and will work better for most software organizations at all stages of development.

    On the other hand, SoundCloud senior engineer, Matthias Rampke issued a series of tweets on how SRE and DevOps were basically the same, with only one difference—high management support. Though in contradiction to her blog, Charity lent weight to this opinion during an AskMeAnything event that revolved around DevOps and SRE. She shared a story about a friend who was hiring for a startup, which, as an experiment, posted the exact same job description twice, the only difference being that one listing was titled “DevOps engineer,” and the other “SRE.” At the time of relating the story, DevOps was winning by 10 percent or 20 percent. However, all this means is that the job title is irrelevant, and naming an SRE team does not magically bestow qualities upon it. Rather than focusing on the title, organizations must focus on the work being done.

    To summarize, we can quote Matt Simmons, a technologist with many insights into this topic, who says, “Not every infrastructure needs an SRE, but every infrastructure could use an administrator who acted more like one.”

    — Asaf Yigal

  • ChatOps: Has the Fat Lady Already Sung?

    ChatOps: Has the Fat Lady Already Sung?

    One of the sometimes unsung stars of the DevOps scene is ChatOps. I have heard lots of folks use the term, but what does it really mean to you? ChatOps is a phenomenon that started, perhaps not surprisingly, inside of GitHub. It was only natural that developers leveraging the repository to share and build better code would eventually start collaborating in ways that other messaging options just couldn’t provide.

    Whether ChatOps in GitHub is something that gave rise to the growing enterprise collaboration and chat  product/services market is open for debate. There is no doubt, however, that the 30 (give or take) cloud-based messaging and chat platforms out there today are looking to make their mark in the world of developers, engineers, admins, DevOps and IT professionals. Some of the larger players in the space have already launched features designed specifically to appeal to this set of users, with Atlassian HipChat and Slack among the leaders. But they are not alone. I thought it would be worth the effort to take a look at some of the players and up and comers in the space.

    HipChat has been a strong proponent of ChatOps for a time now. The company has consistently been tagged as a leader and boasts product integrations with many different tools and services. For example, a Puppet integration brings the power of ChatOps to joint HipChat/Puppet DevOps customers. Slack has made strides as well. Integrations with incident management and response providers including VictorOps and PagerDuty are only a few examples of how Slack has given teams the ability to collaborate on and fix problems with just a few clicks.

    Despite the millions of users already using Slack, HipChat, Microsoft Teams, Facebook Workplace and other apps in the market, there is still no definitive proof of whether any of the competitors have won the hearts and minds of the IT professional. In fact, we are seeing many of general IT publications writing about several of these tools because many of their users are in that category. The original ChatOps tool that was brought to life in GitHub, for all we know, may still be king among the IT audience.

    Will the Jury Reach a Verdict?

    There are two things that are certain in the market: The jury hasn’t yet decided if there is a ChatOps winner among the numerous options, and developers and other IT professionals may want to consider other options before reaching a decision. Unfortunately, for as much as the true IT practitioners despise marketing, there simply has been no way to avoid the  buzz that the aforementioned providers have created. Chances are, if you are searching for a solution, one of the biggies is going to pop up in the top of your browser and potentially block you from finding all options available.

    The Choice Gets Tougher

    The foundational similarity between top platforms is that they use cloud-based applications to connect teams in efficient, collaborative and transparent ways. Mobile workflows and the growth of BYOD has increased the popularity of enterprise messaging and chat platforms as they create ways for employees to quickly reach one another on their own terms. Yet even so, enterprise messaging vendors are learning that  to be effective, they must also provide users with agility, security and the ability to execute on change.

    Options to Consider

    The past couple ​of year​s​ have highlighted just how competitive this space is, and how quickly it is moving. If you work in an environment that leverages ChatOps or are considering ChatOps options, the list below presents a few of the lesser-known or up-and-coming platforms out there with the potential to become your ChatOps solution. That is not to say that the big guys such as HipChat or Slack are not worthy. On the contrary; they are great solutions. But some of these others might be worth looking into:

    Newcomer Flock entered the U.S. market in September 2016. With an eye on the developer community, the startup worked quickly to open its API to developers and has started adding integrations with partners such as PagerDuty, Bitbucket and Appsignal. Flock’s biggest differentiator is that it allows developers to build bots, widgets and apps on its framework using Java and Node.js SDKs, which easily feed into Flock’s Appstore for distribution. Flock allows developers  to spin up applications in just days. For developer teams stretched on time and budget, they’ll find the application has GitHub integration, engages quickly after being turned on and offers low costs for its paid version.

    Ryver, founded in 2015, provides all-in-one team collaboration, from chats, posts and files to the option to invite as many team members and guests as needed. Additionally, Ryver has a broad range of functionality that offers the ability to share long-form posts or threaded discussion, and integrates with the likes of Google Docs, Dropbox, Asana, Jira, Twitter and Facebook, among others. Ryver recently rolled out its “Global search” bar, which allows a keyword search to locate multiple matches across conversations and solves email’s common problem of archiving data.

    Third, there’s ChatWork, known as a group app for global teams. ChatWork is available in five languages and says it supports 124,000 customers in 205 countries. Last month, ChatWork announced new features to connect multiple chat platforms through the ChatWork desktop app as well as a new screenshot feature. The multichat and chat service integration features allow users to be logged into multiple ChatWork accounts without having to change browsers or log in and out repeatedly. This comes in handy when using multiple ChatWork accounts, such as personal and business accounts at the same time. It also allows teams that use Gmail, Outlook or Skype to use these services together from a single area within the desktop app.

    eXo Platform began as an open-source project in 2002 focused on implementing the industry’s first Java portlet container. The project grew into a company in 2003, to start working with its first customer, the U.S. Department of Defense. Today, eXo is an all-in-one open-source digital collaboration platform that provides knowledge, document and content management, social engagement and project collaboration tools integrated into your business’s applications. It is full-featured and extensible, and has a great design. eXo helps companies connect their employees, customers and developers through social, collaborative and content-driven intranets, websites and dashboards.

    Assembla is a set of cloud-based task and code management tools for software developers. Created in 2005, Assembla hosts more than 100,000 commercial and open-source projects and is used by more than 800,000 users in 100+ countries. With Assembla, software engineering teams can manage tasks, teams and code in one place with SVN, Perforce, Git repos, cardwall view of tickets for drag and drop planning, wikis and more. Integrations include Slack, Github and Zapier.

    Finally, there’s Salesforce company Quip. Quip was founded in 2012 by Facebook and Google alumni and combines documents, spreadsheets and chat into one experience. With Quip, enterprises can manage projects, finalize budget plans, share meeting notes and stay connected. Quip is used by thousands of the world’s most well-known and innovative companies, including Facebook, NewRelic, Quora, and Pinterest.

    As you can see, there are lots of choices out there if you have not already settled on Slack or HipChat, or if you want to see if something else is better for your situation. If you haven’t heard the singing, there is still time to check them out.

    — Alan Shimel

  • Get Your DevOps Right With These 7 Technologies

    Get Your DevOps Right With These 7 Technologies

    Editors’ Note: As with all of our contributed articles, the views expressed in this article are of the author, not staging-devopsy.kinsta.cloud. Due to its vendor-agnostic stance, staging-devopsy.kinsta.cloud does not endorse any particular technology.

    There was a time when the operations team and the developers regularly were at each other’s throats. The developers were never satisfied with production code updates and the server administrators chafed at developers piling up the serve requests and circumventing the processes.

    However, the battle lines have been somewhat erased since the advent of DevOps. IT teams adopting DevOps can move rapidly from concept to production to enhance the business impact, quality and velocity of the application delivery. Many organizations are shifting to DevOps because of its high efficiency and the number of people taking DevOps training are also increasing due to numerous job opportunities in this field.

    DevOps Technologies to Know

    A number of technologies have emerged to help in the shift to DevOps, providing services ranging from the configuration management to application portability. Following is a list of seven technologies worth noting.

    Splunk

    Splunk is used for detecting and fixing issues across the life cycle of an application in real time. It allows the developers to see data from the production environments, eliminating the need to access production machines. Splunk enables DevOps processes including continuous integration and deployment.

    The Splunk platform is used for DevOps to:

    • Provide end-to-end visibility across each and every component of the DevOps tool chain.
    • Utilize the objective metrics to make sure the code meets the quality SLAs and is operational.
    • Correlate the business metrics with changes in code to obtain new business insights.

    ScriptRock GuardRail

    ScriptRock Guardrail is designed to rapidly pinpoint the differences in configurations on desktops and servers, comparing the states between systems and over time. ScriptRock Guardrail shows what has changed, helping simplify diagnostics and decreasing downtime.

    Developers who work with agile methodologies are accustomed to a test-first way of working with the unit tests, making sure that everything works as planned. As continuous delivery becomes more prevalent, the DevOps and Ops teams need to take a similar approach. This is where the ScriptRock GuardRail comes into its own, providing you the tools to construct and build infrastructure level unit tests and view the results visually, thus making it very easy to rapidly drill into the real problem and get your services running.

    ScriptRock GuardRail focuses on addressing the key prerequisites to any DevOps, and, more precisely, initiative and automation. They are described below.

    • Visibility: The GuardRail platform delivers visual configurations showing differences between like devices, configuration drift monitoring and automated visualization and scanning of network device and server configurations.
    • Accountability: Users can curate and filter configurations to generate policies that can be utilized to ratify the configurations on a continuous or ad hoc basis.
    • Automation: All the policies can be exported to Windows PowerShell DSC, Docker, Ansible, Puppet and Chef.

    ScriptRock GuardRail works with any automation tool and can be delivered as single-tenant SaaS, multitenant SaaS or a virtual appliance on-premises.

    SaltStack

    The SaltStack Enterprise Software helps DevOps organizations by organizing the systematic motion of code into production by maintaining the complicated infrastructures refined for optimal application delivery and business service. While DevOps is not a tool, it requires a tool-centric approach to enable continuous delivery. SaltStack helps to configure as well as quickly deploy the dynamic applications and general-purpose infrastructure they run on. DevOps is gaining wide popularity around the world because of the tools like SaltStack that enhances its efficiency.

    SaltStack is a cloud infrastructure tool and delivers the systems management for application configuration, cloud building, server provisioning and data automation. It is an event-driven tool and can automate the tasks within DevOps workflow and makes the operations highly approachable for the developers. SaltStack provides a common language and common way to manage the servers and thus helps to bridge the gap between Devs and Ops.

    Puppet

    Automation is the foundation for many DevOps practices. It is the key to continuous delivery and faster deployments. Automation imposes consistency across the production, testing and development environments. It makes sure users can rapidly orchestrate the changes throughout the infrastructure: container and cloud deployments, virtual machines and bare-metal servers.

    No matter where it runs, Puppet provides a standard way of operating as well as delivering a software. Users define what they want their infrastructure and apps to look like utilizing an easy-to-read common language. From there, they can enforce, test and share the changes they want to make across their data center. Reporting and visibility is available at every step of the way to help prove compliance and make decisions.

    The Puppet Enterprise enables users to test changes before deploying them to production. With Puppet Enterprise, the infrastructure is defined as code, which enables users to adopt the best practices of agile development including automated deployment and testing, and deliver the software more reliably. This is because the configurations are consistently promoted, shared and tested across all environments, from Dev laptops through test to production.

    Atlas

    Atlas was the first commercial product released by HashiCorp, provider of open-source tools that enable the efficient deployment of software-defined applications and data centers. Atlas provides visibility into the infrastructure, including virtual machines, containers and servers, in addition to service discovery and configuration management. Building on the popular open-source projects of HashiCorp such as Terraform, Consul, Serf, Packer and Vagrant, the closed-source proprietary Atlas enables DevOps across different cloud services, which include OpenStack, Azure, Google Compute Engine and AWS, and provides a dashboard for maintaining, deploying and developing applications.

    Many engineers are shifting to Atlas today for their organizations’ customer engagement platforms. Atlas brings it in one place and enables the companies to handle end-to-end starting from configuration management to container deployments across various cloud environments. Every open-source tool is fine alone, but the capability to handle and orchestrate them as a whole is extremely powerful.

    Chef

    Chef is a cloud infrastructure and systems framework that automates the management, deploying and building of the infrastructure via repeatable, short scripts known as “recipes.” But the actual strength of Chef lies in its utilization of the pluggable configuration modules(also known as cookbooks), about 2,000 of which are available through Chef community. Facebook, the high-profile user of Chef, recently open-sourced few of its own Chef cookbooks, which include its Grocery Delivery and Taste Tester testing framework, which watches a source code repository such as Git and keeps the local Chef server in sync.

    The complex tasks are automated by Chef that are otherwise resource- and time-intensive. But, more importantly, Chef allows users to focus their efforts on improving and innovating the quality of their services. It also opens the door to more efficiency and collaboration across the organization.

    Docker

    Through its containerization technology, Docker brings portability to the applications wherein the applications run in self-contained units that can be moved across the platforms. It consists of Docker Hub, a cloud service for workflow automation and application-sharing and Docker Engine, which is a lightweight packaging and runtime tool.

    Docker has revolutionized the containerization of applications enabling DevOps to package any kind of application in a lightweight environment. The packaging is done in a way as easy as installing a mobile app. Docker is considered as the most popular DevOps tool. By using docker, the developers can containerize their apps and can run them anywhere. Built on top of Linux containers, docker is a powerful ecosystem where DevOps can use many apps (available on Docker Hub) to the maximum advantage.

    About the Author / Savaram Ravindra

    Ravindra was born and raised in Hyderabad, India, popularly known as the ‘City of Pearls’. He is presently working as a Content Writer at Appmajix Technologies. His previous professional experience includes Programmer Analyst at Cognizant Technology Solutions. He holds a Masters degree in Nanotechnology from VIT University. He enjoys spending time with his friends. He can be contacted at savaramravindra4@gmail.com. Connect with him also on Twitter and LinkedIn.

  • How Much QA is Enough in Software Development?

    How Much QA is Enough in Software Development?

    People working in quality assurance as testers, managers or engineers know what it’s like having to justify their existence; it’s been part of the job for many years. QA experts have had to fight the perception that what they do is a bottleneck, overkill and it slows everyone down.

    Finally, however, QA is getting the attention that it deserves. Companies are gradually investing more in QA skills and tools. This began with the onset of Agile and DevOps—methodologies which have now infiltrated mainstream software development practices everywhere. Since those practices focus on speed, efficiency and quality, engineering leaders have grown to understand that great products are not achievable without adequate QA checks and balances. Another risk is the unflinching nature of high user expectations: Thanks to social media, one user complaint can quickly escalate into others across the web, creating an uncomfortable perception problem for the software provider.

    Robust testing practices can prevent egregious flaws in the software that result in poor user experience and performance—or, worse, a breach. True, testing can sometimes get in the way of speed. Yet no matter how fast you release a product, if it doesn’t work well, no one’s going to buy it, much less use it.

    Nevertheless, we can continually improve the QA practice to fit into modern development teams’ workflow. Testers need to work with developers and master automated testing, while developers need to sometimes engage in testing; everyone should think about the appropriate level and amount of testing. You can have too much of a good thing.

    The Right QA Balance

    The below ideas can help your organization reduce conflict between QA aficionados and those who would rather code and release as fast as possible.

    1: Assess, analyze and report. Developers and testers alike are highly technical; they like numbers. Therefore, the more that the QA team can quantify the risk of an application, provide evidence as to the effectiveness of current QA practices and use metrics to show the need for more QA resources when warranted, the faster that everyone will get on board.

    There are plenty of tools that can deliver common quality metrics such as total number of defects, defect leakage, test coverage, test pass/fail rates, test completion rates, code coverage and application uptime. It’s important to share and discuss these metrics throughout the development team and with product and business managers. What constitutes high quality for the development team may not be the case with executives who are closer to the end user/customer.

    2: The gut check. After metrics, take into consideration the comfort level of your team and company concerning product flaws. In regulated spaces, or for applications that collect sensitive private data, the tolerance for bad code and security gaps is usually low. Gather feedback from different perspectives and roles in the organization for a balanced perspective on the QA practice and areas for improvement.

    3: Get people involved. Quality assurance is no longer a separate activity from development; especially when you are practicing Agile and DevOps, the responsibility for quality is shared. Therefore, developers, business analysts and operations managers all should be doing their work with an eye to quality, delivering feedback regularly to the QA team. Provide opportunities and incentives for any team member to attend events and training related to software quality.

    4: Streamline testing. Test automation tools are helping product teams be more comprehensive in testing, by automating low-risk test cases so that testers can focus their exploratory and manual methods on high-risk or new features. This is a positive development, although testers must take time to learn how to use the tools. Some other ways that can help teams be more efficient in testing include:

    • Conducting more testing early in the sprint. This avoids the 11th hour disaster of finding a major flaw right before the release deadline.
    • Per Agile methods, dividing development tasks into smaller chunks with team members from different disciplines to ensure testing is being done all the time and with visibility by all.
    • Using test driven development (TDD) or behavioral driven development (BDD), which requires that QA, developers and business stakeholders meet at the beginning of a project to agree upon requirements and test cases. Developers then write code against the test, until it passes. New tools are helping bridge the gap by writing requirements and user stories in plain English.
    • Outsourcing part of the testing load during a major project, which can help increase coverage and reduce stress on your team. However, understand that too much outsourcing will undermine any efforts to develop QA as an internal best practice and “mindset” for software teams.

    If your team is committed to QA as a best practice, not an afterthought, those at the top will need to invest properly in the right tools, training and people to get results. Misconceptions about QA still exist; contrary to the view of some DevOps experts, we can’t (and shouldn’t) automate every test. As well, even though developers are now testing the code they write, you still need experienced testers on your team. With the pace of innovation and the high stakes in the marketplace, organizations need more—not fewer—people engaged in testing.

    For testers who love their job, as many of them do, it’s an exciting time to be in the field. Companies increasingly are seeing the value of QA and testers continually are gaining more tools and tactics to excel at helping their organizations produce really great software.

    About the Author / Kyle McMeekin

    Kyle McMeekin is Senior Sales Engineer at QASymphony. Prior to QASymphony, he was a programmer analyst at Cognizant Technology Solutions. Connect with him on LinkedIn.
  • DevOps: Here’s How to Slack Securely

    DevOps: Here’s How to Slack Securely

    With 1.7 million daily active users, it’s clear Slack has come to dominate the team chat world, especially in the tech industry. This, however, means that a fair amount of security is required to ensure that strategic assets remain safe.

    From a security perspective, Slack has done a solid job of keeping its assets on lock, going so far as to score Geoff Belknap from Palantir in 2016 as its chief security officer. The company is also transparent about its approach to security and has dedicated a whole section of its website to it, including interviews with Belknap and others that delve into Slack’s precautions and philosophy around security.

    The company has also certified many of its products to meet strict compliance regulations including FINRA, HIPAA and SOC 2 and 3, which makes it a no-brainer for small teams and enterprises alike.

    So, it’s perfectly possible for companies of all shapes and sizes to lean on Slack for team chat and ops without worrying too much about security. However, no one’s perfect, and Slack’s ubiquity and popularity mean it will always be a target for cybercriminals looking to steal information—that’s basically the nature of being a cloud-based application.

    While, there’s no need to run scared, you do need to be smart about how you use this valuable tool. Here are a few tips for running Slack securely at your organization.

    Use Slack for SecOps

    Slack can be easily used for distributed security alerting, which means every member of your organization can play a role in keeping the business secure.

    Your security operations likely include members of the DevOps team as well as dedicated security folks, and Slack can help all team members integrate security into their workflows seamlessly. DevOps folks may not frequently log in to Threat Stack platform directly. However, any relevant alerts or notifications can be sent to them immediately via Slack, where they can be reviewed and the determination can be made whether further action is needed—all without having to step outside the daily workflow. This means security tasks don’t pose an extra headache, but are just a natural part of the way the company’s operations run.

    Require Two-Factor Authentication

    Slack’s built-in security precautions won’t do you much good unless you actually put them into practice. One great example is two-factor authentication (2FA). It’s up to team owners and admins to require this of their users (otherwise, it will be optional, and most users won’t bother). It is highly advisable you take advantage of this feature, which makes it much more difficult for hackers to tap into your organization’s Slack channels.

    Set Up User Provisioning and Deprovisioning

    Security-minded organizations need to be conscious of and work around insider threats. This also includes employees who have left the company, whether on their own terms or due to an incident.

    To ensure that you do not have any “lurkers” who might be able to take advantage of company information shared on Slack after they have left the company, it’s a good idea to plan ahead for user provisioning and deprovisioning.

    In fact, this should be built into your process for onboarding and offboarding employees, just like it would be for email or any other company asset. If possible, automate the process, so that the moment someone leaves the company, they no longer have access to Slack. To get started, here’s Slack’s guide to provisioning and deprovisioning users.

    Don’t Share Secrets

    Slack is a great place to have secure conversations, which unfortunately can lull some users into a false sense of complete security. “Secure” doesn’t mean you should treat it like it’s watertight; in other words, Slack should never be used to share secrets such as passwords, sensitive customer data or valuable corporate IP—basically, anything that could be considered highly confidential. A good rule of thumb is this: If a piece of information could be dangerous in a hacker’s hands, it doesn’t belong on Slack. Instead, it’s a good idea to use encrypted communication channels, like PGP-enabled email.

    Educate Users

    None of the tips above will do your organization any good if no one knows about them. So make sure that you regularly educate your users about steps they need to take to stay secure while using Slack (such as never sharing passwords there). You should hold user security training whenever new employees come on board, and also make sure to do a refresher now and again with the entire company.

    Additionally, if you change up security protocols around tools like Slack, make sure employees are given a heads up and reminded when new measures go into effect so they know what to expect. Remember: The best offense is a good defense.

    Don’t Slack on Security

    Slack is a great platform with all kinds of benefits for teams. As long as you take the right security precautions, there’s no reason why it can’t be used to its full potential on your team, whether you’re a small shop or a multinational enterprise. As with any other tool, the shared responsibility model is key. Take responsibility for your half of the security equation, and you should be well on your way to a secure Slack implementation.

    — Pete Cheslock