Category: DevOps Toolbox

  • Flexera Extends Scope of Open Source Scanning Tools

    Flexera Extends Scope of Open Source Scanning Tools

    Now that many IT organizations have adopted an open source-first mentality to acquiring new software, tracking their dependency on all the various modules they are employing is becoming more challenging with each passing day. To help IT organizations track both usage and dependencies of open source software, Flexera has updated the FlexNet Code Insight software to continuously scan the network for open source software and highlight any known security and compliance issues.

    Based on code Flexera gained when it acquired Palamida in 2016, FlexNet Code Insight is now easy to navigate using a single dashboard, says Jeff Luszcz, vice president of product management at Flexera. Its capabilities span high-level package analysis to more detailed analysis that detects when snippets of open source code are being used within a third-party application regardless of build dependencies, sub components, source code, modified source code and binaries and even Docker containers being used.

    In addition, this release of FlexNet Code extends the integration Flexera provides to continuous integration servers and third-party build tools to automate scans during the software development process. IT organizations also can create their own custom plug-ins, says Luszcz.

    FlexNet Code Insight can identify 13 million open source components and supports more than 70 extensions. That includes integration with data from the National Vulnerability Database and security vulnerability assessment software developed by Secunia Research, which Flexera acquired in 2015.

    Luszcz says FlexNet Code Insight is a natural complement to the tools Flexera already provides for tracking use and dependencies between instances of commercial software. The difference now is a steady increase in the rate enterprise IT organizations are now depending on open source code, which changes more rapidly.

    Flexera is not the only vendor these days focusing on identifying open source software (OSS) vulnerabilities and associated compliance issues. But it does uniquely provide tools spanning both commercial and open source software. That capability is especially appealing to senior IT executives who would prefer to rely on a single vendor to provide both classes of tools, says Luszcz.

    While there’s currently a lot of enthusiasm for open source software in the enterprise, Luszcz says many IT leaders don’t appreciate some of challenges that lie ahead. Most open source software is made up of modules provided by different developers working within the confines of an open source project. Updates to that software to address, for example, a security flaw are not easily propagated throughout the ecosystem. In fact, Luszcz says that very issue lies at the heart of recent security breaches that occurred at Equifax.

    Having a local repository to keep track of what software is being used simply isn’t enough, Luszcz says. IT organizations need an end-to-end approach for monitoring all the updates made to that software regardless of where it originates.

    Of course, when it comes to open source software there really is no going back. Lusczs notes that as far as compliance and security are concerned, the proverbial genie is already out of the bottle. The only question now is how to marry OSS tools to DevOps processes to make living with that open source genie a lot easier for all concerned.

    — Mike Vizard

  • How to Ensure DevOps Success in a Distributed Network Environment

    How to Ensure DevOps Success in a Distributed Network Environment

    Data-centric applications are not typical, and the environment where they’re deployed are also not typical. Most often, they’re deployed into large, distributed network of machines, which compels the question of whether DevOps practices and tools can be applied to distributed applications.

    To be successful, DevOps practices for data-centric applications must work smoothly even when production environment is a distributed network. For that to happen, developers and testers must define best practices for DevOps as well as continuous deployment into these distributed network environments.

    Can DevOps Work in Distributed Environments?

    Let’s say you’ve adopted a distributed network environment for your data-centric application production environment. Unless you’re able to successfully and rapidly develop your application for such an environment, it’s a wasted effort. Although DevOps is the solution, how many DevOps tools allow you to develop applications in distributed network environments?

    Here are three critical steps to ensure DevOps success in a distributed network environment:

    1. Containerize applications
    2. Use DevOps tools to enable a continuous DevOps life cycle
    3. Use sandboxes throughout the DevOps life cycle

    Why are they important? The above three steps help you address the what, how and where aspects of your data-centric DevOps problem:

    1. The What (Containers) —A distributed network environment, most likely, is heterogenous and consists of different types of systems and applications. Putting your application within containers will make them look uniform and allow you to easily move them from non-production to production environments, as well as from on-premises systems to cloud.
    2. The How (DevOps Tools) — To rapidly develop your application you’ll need to quickly iterate through the program-test-deploy cycle. DevOps tools help automate these steps.
    3. The Where (Sandboxes) — Sandboxes help you decide where you develop your application so that its infrastructure and environment looks the same whether you access it from development lab, or testing lab, or production data center or anywhere else.

    Of these, two steps are common to both data-centric and non-data-centric environments. Containerizing applications is definitely important to data-centric applications whose requirements don’t seem to affect DevOps tools much. Nevertheless, the DevOps practices still apply fully.

    However, the data-centric environment is quite different from a typical application environment. This makes sandboxing for distributed network environment all the more essential for data-centric applications.

    Playing in the Sandbox

    Sandboxes (also called uber containers) are basically self-contained infrastructure environments that can be not only configured to look identical to your final target deployment but also created and run from anywhere.

    Developers, for example, can create a sandbox that looks exactly like their production environment—hardware, network, OS versions, software and even cloud APIs. Sandboxes can be spun up so developers can do their development and then torn down when they are done.

    Similarly, testers can create a sandbox that looks like their internal IT environment to run a bunch of tests and then re-configure it on the fly to look like their external cloud environment so they can run some more tests. This will enable them to test all possible environments that the application could run in, without actually disrupting the production infrastructure.

    So, what, technically, is a sandbox?

    A physical sandbox is a protected space where you have complete control and others are allowed only by your invitation. You can build whatever you want with the sand and even bring your own toys into it. If you don’t like it, you can always start over.

    Similarly, a technological sandbox provides a controlled environment where you can build and test what you want without disrupting what’s outside the environment. You can even install your own software (bring your own toys) to create the desired environment for your application.

    In fact, a number of vendors are now offering sandbox solutions (also called “environment as a service”) that provide a simple interface for creating any target infrastructure environment and configuring it with any control you want. You can bring applications, tests, tools and automated processes to your sandbox. User access to your sandbox is highly controlled so no one can mess up the infrastructure that you are currently using in your sandbox.

    You can even reserve and schedule sandboxes so that whole teams of developers and testers can share the infrastructure for hours, days and even weeks at a time. These sandboxes can be triggered even from the outside, right from your DevOps tools.

    If you’re developing a data-centric application such as an internet of things (IoT) application, it needs to be deployable on distributed network infrastructure. Sandboxes provide a great way to mimic these complex, large-scale environments and allow developers to build applications that can run in this type of environment.

    Wrapping Up

    Ideally, it is possible to combine containers, DevOps tools and sandboxes to enable continuous deployment in a distributed network environment. The key is to package your application in containers, use DevOps tools to automate the process of moving through the various stages of your development cycle and create sandboxes to mimic the target product environment required to run those applications.

    About the Author / Sreeram Sreenivasan

    For more than eight years, Sreeram Sreenivasan has worked with various Fortune 500 companies in areas of business intelligence and sales and marketing strategy. He’s the Founder of Ubiq BI, a cloud-based BI platform for SMBs and enterprises. He’s also the editor of Fedingo blog, which covers a wide range of business growth topics.

  • Making Software Maintenance Cool Again with DevOps

    Making Software Maintenance Cool Again with DevOps

    What makes DevOps so important? Part of the answer lies in how DevOps encourages more appreciation for and investment in software maintenance.

    Traditionally, the IT industry has been like the construction industry. People who design new things (architects or software developers) are at the top of the value hierarchy, whereas the folks who build and maintain them (construction workers and IT Ops admins) are not held in such high esteem.

    This isn’t to say people hate admins, of course (or construction workers, for that matter). What I mean is that the work of building and maintaining tends to be seen as less creative and exciting—and ultimately less important—than the work of designing new things.

    This is why software developers in the pre-DevOps world got most of the glory. They created new code that did exciting things.

    Meanwhile, admins on the IT Ops team were stuck deploying and maintaining that code—and occasionally cleaning up messes created by developers who wrote bad code. Admins were also the first folks to take the blame when something went wrong.

    This isn’t to say that developers cause all the problems, of course. Some mistakes can be attributed to admins. Others are the result simply of poor communication between developers and admins.

    Still, in general development work—which involves creating new features and innovations—was what was celebrated. Maintenance work performed by IT Ops was less glorious.

    DevOps and Software Maintenance

    One of the most important—yet also most underappreciated—results of the DevOps movement is that it has made software maintenance cool again.

    In addition, DevOps provides more organizational support for maintaining software, while also facilitating the type of communication between developers and admins that leads to better maintenance.

    DevOps does this through principles such as the “you build it, you own it” mantra, which stipulates that whoever writes code is also responsible for deploying and maintaining it.

    Even if your organization doesn’t adopt that particular DevOps practice, it probably still seeks greater collaboration between developers and IT Ops. As a result, when something breaks in production or needs to be upgraded to maintain reliability, developers are involved, too.

    Celebrating Software Maintenance in DevOps

    Despite the emphasis that DevOps has brought to software maintenance in practice, you still don’t hear a lot of talk about maintenance work in the DevOps world.

    In essence, coding is still seen by many people as the coolest type or work that is done in the DevOps world. What DevOps has done is break down the silos separating those who code from those who maintain. It hasn’t necessarily made maintenance itself the object of more excitement.

    It may be time for that to change. Forward-thinking organizations should recognize that software maintenance—which includes tasks such as applying updates, monitoring applications and scaling host infrastructure—is just as crucial for a seamless application experience as the applications themselves. This should become an explicit part of the DevOps conversation.

    — Chris Tozzi

  • HashiCorp Terraform Enterprise Empowers IT Administrators

    HashiCorp Terraform Enterprise Empowers IT Administrators

    Most of what passes for management of IT infrastructure often amounts to little more than a Word document describing how a system is configured. HashiCorp developed Terraform to enable IT organizations to programmatically manage IT infrastructure. Now the company is taking that concept a step further with the release of Terraform Enterprise, a collaboration application that can be employed to programmatically manage IT infrastructure without requiring IT administrators to know how to program.

    HashiCorp co-CTO Armon Dadgar says Terraform provides an application that makes its Sentinel policy management framework more accessible. Previously, use of Terraform and Sentinel were limited largely to developers looking for a common way to manage infrastructure as code. But Dadgar says customer requests made it clear there was also demand for a collaboration application that did not require any programming skills to employ.

    Terraform Enterprise includes Workspaces, a set of modules that that can be delegated to separate teams. Dadgar says Workspaces are roughly equivalent to Git repositories that have access controls for each IT team, using a secure access markup language (SAML) that comes with built-in encryption.

    In addition, Terraform Enterprise exposes an application programming interface (API) that can be invoked for integration with existing tooling or application delivery pipelines. Dadgar says with the rise of multiple clouds in an organization, it’s now only a matter of time before existing approaches to managing IT infrastructure simple become obsolete. Pressure from developers to increase the amount of time it takes to provision and update IT infrastructure is only going to increase, says Dadgar.

    HashiCorp is effectively trying to smooth over one of the more contentious aspects of DevOps. In theory, developers want more control over IT infrastructure largely because they often view internal IT teams as being too slow. To enable IT organizations to be more responsive, various APIs have been exposed that can be invoked using IT automation framework. Many of those frameworks, however, require programming skills that most IT administrators don’t possess. Many organizations also don’t want developers to be managing IT infrastructure when they could be devoting that time to writing and test applications. Dadgar says Terraform Enterprise provides a graphical user interface (GUI) through which all the benefits of managing infrastructure as code can be attained without having to teach administrators how to program, or allowing programmers to invoke IT infrastructure resources without any adult supervision.

    HashiCorp is not the only provider of IT management frameworks trying to solve this issue. There are rival declarative frameworks for automating IT and many providers of the latest generation of software-defined infrastructure are embedding modern IT management frameworks within pre-integrated systems. But HashiCorp is one of the few vendors providing organizations with a dual approach using the same core underlying set of APIs. Rather than continuing to be at odds with one another, developers and IT administrators now could find it easier to collaborate using whatever approach to infrastructure as a code they best see fit.

    — Mike Vizard

  • DevOps Dozen Nominations Are Now Open

    DevOps Dozen Nominations Are Now Open

    [su_heading]The 3rd annual DevOps Dozen awards are now open for nominations. [/su_heading]

    The DevOps Dozen honors the best of the best in DevOps. The third annual DevOps Dozen awards opened for nominations today. Finalists will be selected based upon how many people nominated them. The top 4 to 6 nominees in each category will then make it to the finalists. The winners will then be voted on by our panel of judges.

    You can nominate up to two entrants in the 12 categories for the DevOps Dozen. It is one nomination per person though. We are also requiring name and email address for all people nominating. While that is not going to thwart ballot stuffing, we hope people take these awards in the spirit they are meant to be.

    As stated earlier, we will take the top 4-6 nominees in each category and designate them finalists. Our panel of judges will then pick the winners from that finalists list. Finalists can submit a presentation on why they deserve the award. These can be sent to judges@devops.com. Finalists will be announced 2nd week of November and winners will be announced in December.

    Who are the judges? This is tough. We couldn’t have anyone who might be eligible for an award. That disqualifies vendors, practitioners and many others. However, I think we have 4 great judges:

    1. Alan Shimel, founder, editor-in-chief, staging-devopsy.kinsta.cloud
    2. George Hulme, long time tech journalist and editor at staging-devopsy.kinsta.cloud and Security Boulevard
    3. Jayne Groll, CEO and co-founder of the DevOps Institute
    4. Ericka Chickowski, an original editor of staging-devopsy.kinsta.cloud and well know tech journalist

    So what are the dozen categories for the DevOps Dozen this year? Well you can get the full story at the site itself. Here they are as well:

    [su_custom_gallery source=”media: 117944,117942,117948,117947,117946,117943,117950,117951,117949,117941,117945,117940″ width=”600″ height=”130″]

    If you have questions after visiting the DevOps Dozen website, write us at DD@devops.com.

    The DevOps market is so crowded with worthy winners that we know some great companies and people won’t make the cut. However, there can be only one (as they say)

    Voting for finalist nominees is open for just 2 weeks, so don’t waste time. Nominate your favorites today. Good luck to everyone vying for the DevOps Dozen.


    — Alan Shimel

  • OutSystems: Low-Code Apps Require Sound DevOps Processes

    OutSystems: Low-Code Apps Require Sound DevOps Processes

    As more IT organizations embrace low-code application development platforms, many of them are discovering that accelerating the rate at which they develop applications can be too much of a good thing.

    António Barros, product manager for OutSystems, says most of the organizations that have adopted the company’s namesake low-code platform are just now coming up to speed on automated testing. Barros estimates that only 20 percent of the organizations using the OutSystems platform are also employing automated testing tools. The majority of OutSystems customers continue to rely on manual testing even though it’s apparent low-code platforms will produce applications much faster than manual testing can keep pace with. OutSystems has identified five stage of DevOps maturity, he notes, but none of its customers has achieved that level of DevOps maturity.

    To help them get a little further down the DevOps path, OutSystems, at its recent NextStep 2017 conference, announced an extension of its partnership with Indigo to provide tighter integration with the OutSystems platform. In addition, OutSystems plans to make available digital transformation playbooks, including one for DevOps, beginning in 2018. Outsystems has already integrated its platform with the Jenkins automated server to provide continuous integration and continuous development (CI/CD) capabilities.

    Barros says it’s not only critical to engage in continuous testing, but the application needs to be designed to make it easier to isolate user interface, application programming interface (API) and unit testing. Otherwise, automating the testing process becomes more difficult than it should be, says Barros.

    Developers for years have resisted low-code platforms, which automatically generate much of the code that needs to be written for an application. Some fear the platforms can’t build applications that scale. Others have simply decided they prefer to write code themselves. But these days, organizations are under more pressure than ever to deliver applications faster, which has led many organizations to rely more on low-code platforms such as OutSystems.

    It’s not clear just how popular low-code platforms will become. OutSystems revealed at its conference it has signed up 122 new customers in the last quarter alone. On average, it now takes organizations eight weeks to build and deploy an application on the OutSystems platform, with new release cycle updates occurring every 48 hours, says OutSystems CEO Paulo Rosado.

    Michael Facemire, an industry analyst with Forrester Research, told conference attendees that adoption of low-code platforms is now a matter of economics. The starting salary for a developer in the San Francisco Bay area is $145,000, says Facemire. As the salary of a developer with a few years of experience now reaches more than $200,000 in the Bay area, companies in that geography will have no other option but to employ low-code platforms, he says.

    Obviously, developers might be less expensive in other regions. But Facemire notes that no matter what the region, developers are in short supply. That need for speed, he adds, is also why organizations are rapidly adopting containers and serverless computing framework. The challenge IT organizations will face is finding a way to put quality control processes in place to don’t compromise either the speed of the development process or the quality of the end user experience, he says.

    By the same token, however, no one really appreciates code that arrives late, no matter how great it might be.

    — Mike Vizard

  • DevOps and Data Portability

    DevOps and Data Portability

    You have a classic car. You’re in the middle of restoring it, and it looks mighty sweet. Paint is polished, wheels are stock, hubcaps (or spokes) are shiny, engine is completely restored to original spec.

    But it has no gas tank.

    A bit of a stark comparison, but that’s where we’re at with application release automation (ARA)—at least in terms of portability. And where we’re likely to stay.

    Hold on, I’m a Fan

    Before the DevOps aficionados get out the torches and pitchforks, let me be completely clear that I’m a huge fan of ARA, and explain again why.

    Tools such as Jenkins allow DevOps teams to automate the entire build/test stack—or, as much of it as their organization requires. That is a huge step forward, for all the reasons we’ve covered in the past, including the one I think is often overlooked or underemphasized. With frequent build/test feedback, the code is still fresh in the developers’ head when they learn of problems. Most of the time, they are fixing before moving on to the next task, which is a huge plus compared to waterfall, where many problems show up long after the developer in question has forgotten what the code is doing because they’re off on other things.

    Likewise, tools such as Puppet, Ansible and Chef (to name a few) allow DevOps and security to set standards via script, and use those scripts to deploy over and over. This has all the benefits we’ve discussed, too—speed of delivery, reduction of human error, repeatability that becomes stability, etc. This gives operations the ability to answer, “Is server X set up to do this new thing?” by looking in deploy scripts and quickly updating things if the answer is no, but X will be required going forward. That’s one of my favorite bits of Application Provisioning.

    Riding the Gap

    For those unfamiliar, ARA simply bridges the gap between DEVops and devOPS. Tying code being released to platforms and configurations it will be released under. It has the ability to rapidly re-target a release to a new environment, and it can do predictable and repeatable releases, offering the benefits of application provisioning for the actual release segment. Most tools do this by tying together your favorite build tools and provisioning tools, and giving Ops a control panel that can manage the process end-to-end.

    The benefits are huge. Particularly for Operations and Security (who have another place to standardize and insert essential monitoring), but also for development because it offers one further step in testing and by doing so reduces the surprises six months down the road, when you’ve forgotten what

    Bubblegum += 10

    Is in your code for.

    So don’t take my intro as offensive. I am a fan. But I’m a realist. There is no panacea.

    It’s About the Data (as Always)

    The two weakest parts of most ARA systems are server provisioning and data issues. Server provisioning is setting up OS/hardware, and many ARA systems tend to assume you magically did elsewhere, but this problem is only an issue in highly physical environments and there are tools to handle the problem; they’re just not integrated well with most ARA systems. Data issues are the bigger problem.

    It’s cool that we can drag and drop a couple boxes, and magically switch our deployment from inside the DC to a cloud provider in the time it takes the ARA to build/deploy. But we all know that’s not how the world works. Now you have an application, complete with database that is correctly configured and security that does AAA solidly … and no data.

    “Just move the data, then!” the choir sings. No, that’s really not how it works in an enterprise. Data itself is an object of security and compliance, and some source databases are so massive that moving them is a nearly impossible chore in and of itself. Amazon tips its hat to this fact with its import/export service.

    This was the reason why I gut reacted to the “No more physical data centers!” crowd back in the midst of the hype with an eye roll. The amount of data stored in data centers is staggering, and often not portable at all. Add to this the fact that such data isn’t going to reduce, and we have a quandary.

    What About Moving Forward?

    Sometimes, it is necessary to accept that the current state is not changeable, but take steps to improve the future state. I don’t see this as a reasonable approach in this case, because the rules of data aren’t changing in a way to change future state in a positive way. We’re generating more data every day, and that data will end up stored somewhere. Be careful where you store it, think long-term strategic. Having ARA doesn’t magically make that data portable, so make sure that where you store it today, while it’s small, is where you’ll want to store it in five years, when it is a massive, largely immobile asset.

    What to do … What to do

    Use ARA to multitarget all of those apps that are portable without terabytes of data, and make sure data generation/collection/analysis apps are on the architecture you will want them on moving forward. ARA offers a ton of other benefits, so data portability isn’t a deal breaker—or even a significant negative, since you probably already knew some datasets weren’t going anywhere—but don’t expect miracles out of it. It can’t make your large datasets portable, so don’t expect it will. And use it to target the platform your organization feels is most appropriate for apps that will generate or collect a lot of data.

    — Don Macvittie

  • VMware Unveils IT Automation Tools Suite

    VMware Unveils IT Automation Tools Suite

    VMware over the last two years has been making steady advances in automating the management of IT. At the VMworld Europe 2017 conference VMware unveiled a vRealize Suite 2017 offering that combines the latest releases of vRealize Operations, vRealize Automation, vRealize Business for Cloud and vRealize Log Insight software into a single offering designed to optimize lifecycle management across a software-defined data center (SDDC).

    Mahesh Kumar, senior director of product marketing for cloud management at VMware, says the driving force behind the development of vRealize Suite 2017 is to enable the automation of IT operations in support of an IT organization’s larger DevOps strategy.

    The elements of VMware vRealize have been upgraded as follows:

    • vRealize Operations 6.6 adds tools to help organizations analyze workload placement decisions to automate the balancing of workloads across clusters and data stores. It includes a predictive distributed resource scheduler (pDRS) and native VMware vSAN management and monitoring capabilities.
    • vRealize Automation 7.3 adds support for Admiral 1.1, the lightweight container management portal that VMware previously announced. Virtual Container Host instances generated by VMware vSphere Integrated Containers, Docker hosts, and for Docker volumes can employ vRealize Automation to create and attach volumes to containers. It also delivers increased support for VMware NSX network virtualization software.
    • vRealize Business for Cloud 7.3 is now being exposed as a tab in vRealize Operations 6.6 to better drive cost efficiencies by making operational and cost metrics readily available. It also delivers improved insights into the costs of Amazon Web Services (AWS) and Microsoft Azure public clouds alongside VMware-based private clouds.
    • vRealize Log Insight 4.5 now provides integration with vRealize Operations to provide root-cause analysis of logs and metrics.

    Resistance to IT automation continues to decline. Many IT operations professionals naturally are concerned that IT automation will lead to unemployment. But managing IT operations at the present level of scale required simply can’t be accomplished using manual processes. In addition, developers are voting with their code to employ public clouds that have already been automated. IT teams who want to make a case of continuing to deploy application workloads in a local data center need to be able to provide a cloud-like experience, which can be accomplished only by employing automation. Kumar notes that VMware is trying to arm IT administrators with the analytics required to make a financial case for continuing to deploy applications on instances of VMware running on-premises or in a public cloud.

    Most IT organizations today are focused on automating disparate deployments of IT infrastructure and software. While that represents an advance over manual processes, many of those same organizations now are wrestling with various islands of automation. VMware is trying to unify automation across all the compute, storage and networking technologies it delivers to fashion an SDDC that enables IT organizations to be more agile. Longer term, however, IT organizations that employ stacks of software other than VMware will need to find a way to automate DevOps across heterogeneous IT environments.

    — Mike Vizard

  • Differentiating Between CI Pipelines and DevOps Assembly Lines

    Differentiating Between CI Pipelines and DevOps Assembly Lines

    “What’s in a name?” wrote the greatest Bard who ever lived.

    All I can say is, he lived in simpler times, when DevOps and the confusing world of continuous integration (CI), continuous deployment (CD), CI/CD, the other CD, application release automation (ARA), pipelines, assembly lines, etc., didn’t exist.

    The biggest challenge today is that vendors use overloaded terms to describe completely different use cases. CI vendors claim to support CI/CD, even though the “D” here is just a deployment to a development environment and not staging or production. ARA vendors claim to enable continuous delivery, even though they do not include critical steps such as infrastructure provisioning, security patches or configuration management.

    The terms “pipelines” and “assembly lines” are relatively new. Multiple vendors have recently announced pipelines and assembly lines, and the differences aren’t obvious at first glance. So let’s do a deep dive.

    What are CI Pipelines?

    Continuous integration has evolved tremendously over the last few years. What started as a simple process of automating build and unit tests for each code change has evolved into a pretty complex workflow.

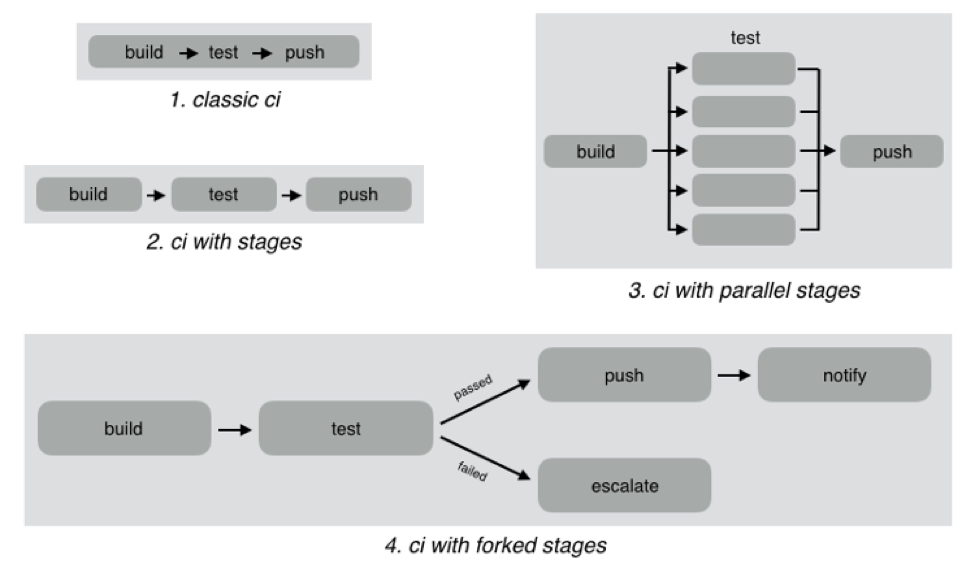
    As an example, look at the different CI workflows shown below:

    In classic CI, all build and test instructions were included in a single blob and instructions were executed serially. If all instructions executed successfully, CI was successful, and if anything failed, then it was marked failed. Almost all CI providers, until recently, offered just classic CI.

    However, as CI became mainstream, developers wanted to define more complex workflows with decision trees and parallelism. CI pipelines support this complexity, such as:

    • Defining the CI workflow in stages, so you can get results from a stage faster without having to wait for the entire workflow to finish. This also enables scenarios such as running a basic test group and only running the extended test suite if the basic tests pass.
    • Running stages in parallel, so you can split tests or test your code against different environments or language versions, and get faster feedback.
    • Forking your CI logic based on the results of a stage.

    While CI pipelines are a huge improvement over classic CI, they are still limited to developer-focused workflows. Jenkins, Teamcity, Shippable, Gitlab and CircleCI all support some form of CI pipelines.

    What are DevOps Assembly Lines?

    DevOps assembly lines are focused on automating and connecting activities performed by several teams, such as CI for devs, infrastructure provisioning and configuration management for ops, test automation for test, security patching for SecOps, semantic versioning and approval gates for release managers, deployments for multiple environments, and so on.

    Today, most organizations use various tools for automating specific DevOps activities. However, the DevOps toolchain is fragmented and gluing it together to achieve continuous delivery is a challenging task.

    Most teams adopt one of the following approaches:

    • Using cultural collaboration as the glue between silos. As an example, when a new application version is available, the test team creates a JIRA ticket and assigns to ops. Ops then copies the application version information into their deployment scripts and run them.
    • Writing ad-hoc scripts to trigger one activity from another, including passing state information through intermediate storage such as S3. In this case, the DevOps engineer would likely write a Jenkins job that runs automated tests, and then pushes application version information to S3. Another Jenkins job polls the S3 bucket, and when a change is detected, runs the deployment scripts.

    The first approach introduces inefficiency and unnecessary human-dependent steps. The second approach is better, but only works well for small teams working on a single application. It creates a Frankenstein of spaghetti automation when you have many applications or even a single application with microservices.

    DevOps assembly lines address this problem by focusing on gluing together these various DevOps activities into streamlined, event-driven workflows with the ability to easily share state and other information across activities.

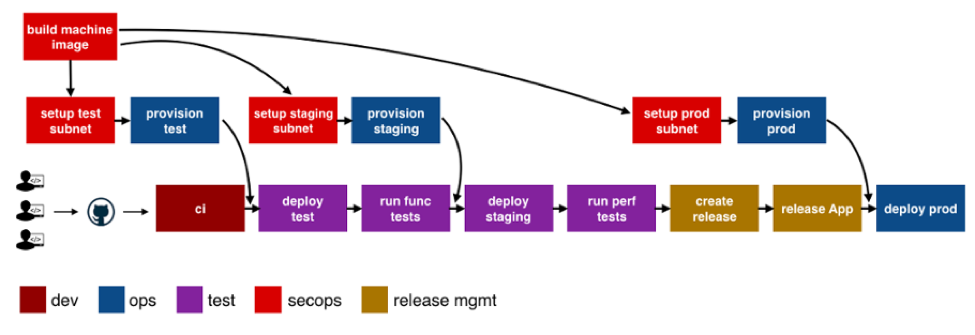
    The following image shows a typical assembly line for a single application or service:

    See the difference? The CI pipeline is just ONE activity in the assembly line. Each of the boxes in the picture above is a pipeline, just for different activities! Each has specific needs with respect to tools integration, runtime, configuration, notifications, etc. In addition, each pipeline is owned by a different team, yet needs to interact with other pipelines and exchange information. For example, if the ops team changes provisioning scripts for staging environment, the test team needs to redeploy the application and run performance tests.

    A DevOps assembly line is, therefore, a “pipeline of pipelines.”

    DevOps assembly lines need to support the following:

    • Ability to easily define workflows across multiple pipelines.
    • Versioned and reusable workflows, enabling rapid changes and scaling for multiple applications and/or microservices.
    • Integrations with all popular source control systems, clouds, artifact repositories, DevOps tools, languages, services, etc.
    • Runtime to execute every pipeline, including pre-installed tools and CLIs, and the ability to use the right runtime, depending on pipeline type.
    • Accelerators/playbooks for common pipelines and tools.
    • Ability to pass state and other information while triggering dependent pipelines.
    • Automatic triggers or manual approval gates between each pipeline.
    • Configurable notifications for each stage of every pipeline.
    • Release automation features such as semantic versioning of packages.
    • Audit trails for each pipeline, with the ability to go back or forward to a specific state.
    • Abstraction of all sensitive information like passwords, tokens, keys, etc. for security reasons.
    • Roles and permissions restricting assembly line and pipeline actions.
    • Manage DevOps infrastructure, including spinning VMs and containers up and down as required.
    • Visibility into each pipeline and stage, including logs, status and versioned data.
    • Metrics and Analytics across pipelines to help identify bottlenecks.

    In short, DevOps assembly lines help automate and scale end-to-end workflows across all teams and tools, enabling continuous delivery.

    About the Author / Manisha Sahasrabudh

    Manisha Sahasrabudhe is co-founder and vice president of product management at Shippable. Prior to Shippable, Sahasrabudhe was senior program manager at Microsoft. She can be found online at Linkedin.
     

  • The Right DevOps Tools for Value Stream Velocity

    The Right DevOps Tools for Value Stream Velocity

    Think of DevOps tools as stepping stones to releasing new functionality into the hands of your customers faster and more frequently. Working together, tools automate processes and help companies become modern software factories. But isolated tools, like a lone rock in the middle of a river, are much less useful.

    Disparate tools may help an individual or a team do their job, but they impede the progress of the larger organization. To achieve desired efficiency across the application life cycle, companies may waste time and amass technical debt by integrating tools with scripts.

    The other answer is that organizations get restrictive. They may establish a “center of excellence” for DevOps that prescribes a toolchain that works together, but are those tools going to be the best fit for all individuals and teams, supporting an agile mindset?

    The ideal scenario is for a DevOps toolchain to become an integrated, dynamic continuous delivery powerhouse where “best fit” tools work in concert to enable better performing teams and better customer experiences.

    Start with the Right Tools for the Job

    DevOps teams are focusing on automating and streamlining all aspects of the application life cycle. It makes sense to choose the tool that’s best for the job. And teams should feel free to experiment and take advantage of new tools emerging every day that solve new problems or do a better job solving existing problems.

    Typical areas of DevOps tool investment include:

    • Planning and managing development work
    • Managing, tracking and documenting all code changes
    • Building, managing and deploying containers
    • Automating iterative builds/continuous integration
    • Developing and deploying to cloud platforms
    • Automating the deployment of applications into environments at all stages
    • Provisioning, configuring and monitoring environments
    • Managing all types of testing with the right requirements and data
    • Validating security before vulnerabilities become a problem
    • Promoting better agile team collaboration
    • Monitoring and managing an application in production

    These tool categories each serve a vital role in the application life cycle. However, there remains a significant lack of coordination and shared knowledge across the DevOps toolchain to generate the value stream velocity that can keep businesses competitive and customers engaged. For example, if a testing function is isolated, it becomes a black hole of activity and often a bottleneck to delivery.

    Build the Smarter DevOps Toolchain

    When teams can visualize, orchestrate and track the continuous delivery value stream from development through production, the pipeline becomes an intelligent entity of its own. How is the pipeline performing? How is it adding value to the organization? How do you improve the pipeline?

    For example, by integrating the planning and management solutions as part of the value stream, you can keep track of the user stories—including where they are deployed, what tests have been done and the results. Bi-directional integration enables automatic updates in the planning/management tool. Layer in collaboration tool integrations, and dev teams can get instant feedback and respond more quickly, shifting quality left.

    The result: real-time information and the ability to plan and prioritize more effectively. Release and development teams now have a shared view and understanding of release status and business implications.

    The testing function is another area where tools can work better together. Instead of sequential and separate functional, integrated, performance, API or security testing, you can build a testing workflow that runs in parallel, automatically promotes tasks, monitors progress and sends feedback of testing status. This can include orchestrating the generation of the right test cases, test data and virtual services for the app under test. With all the testing knowledge gathered in one place, it’s easy to see testing gaps and determine the risk of a release.

    Launch DevOps Mission Control

    A control center that manages the continuous delivery value stream can help teams not only manage the health and schedule of an active release more effectively, but it can also provide the visibility and analytics to help teams iteratively improve.

    There are a number of tools on the market that look beyond the silos of the application life cycle to connect and extract value from an end-to-end toolchain. As you assess tools that can enable a dynamic value stream, ensure they have capability in these five areas:

    1. Plug and play integrations: Does the tool support common DevOps plug-ins? How easy is it to integrate tools, whether they are open source, commercial or home grown?
    2. Full pipeline visibility: Does it enable orchestration and tracking of all releases at all stages—planning, development, test and production—including feedback loops and planning for the next release?
    3. Continuous quality: Does it support a shift-left testing model to ensure testing happens continuously and rigorously? Does it help you prioritize your testing and automate risk assessment for your releases?
    4. Business value alignment: Does it provide intelligence about the app content in the pipeline? Can you see what code is deployed where in the pipeline and its status? Can you map how the content of a release aligns to business priorities?
    5. Actionable analytics: Does it extract meaningful data points from pipeline operation to provide analytics that support real-time decisions, as well as inform improvements over time? Can you get insights into release and pipeline performance, testing coverage and speed, release readiness, team productivity, and so on?

    With intelligent integration of your DevOps toolchain you can increase your value stream velocity and deliver the best quality apps—every single time.

    — Patricia Johnson