Category: DevOps Toolbox

  • Salt Security Adds Support for GraphQL APIs

    Salt Security Adds Support for GraphQL APIs

    Salt Security has extended its platform for securing application programming interfaces (APIs) to include support for APIs built using GraphQL.

    GraphQL is an open source data query and manipulation language for APIs that was originally developed by Facebook. It provides a more efficient approach to querying data than the REST APIs that are widely used today.

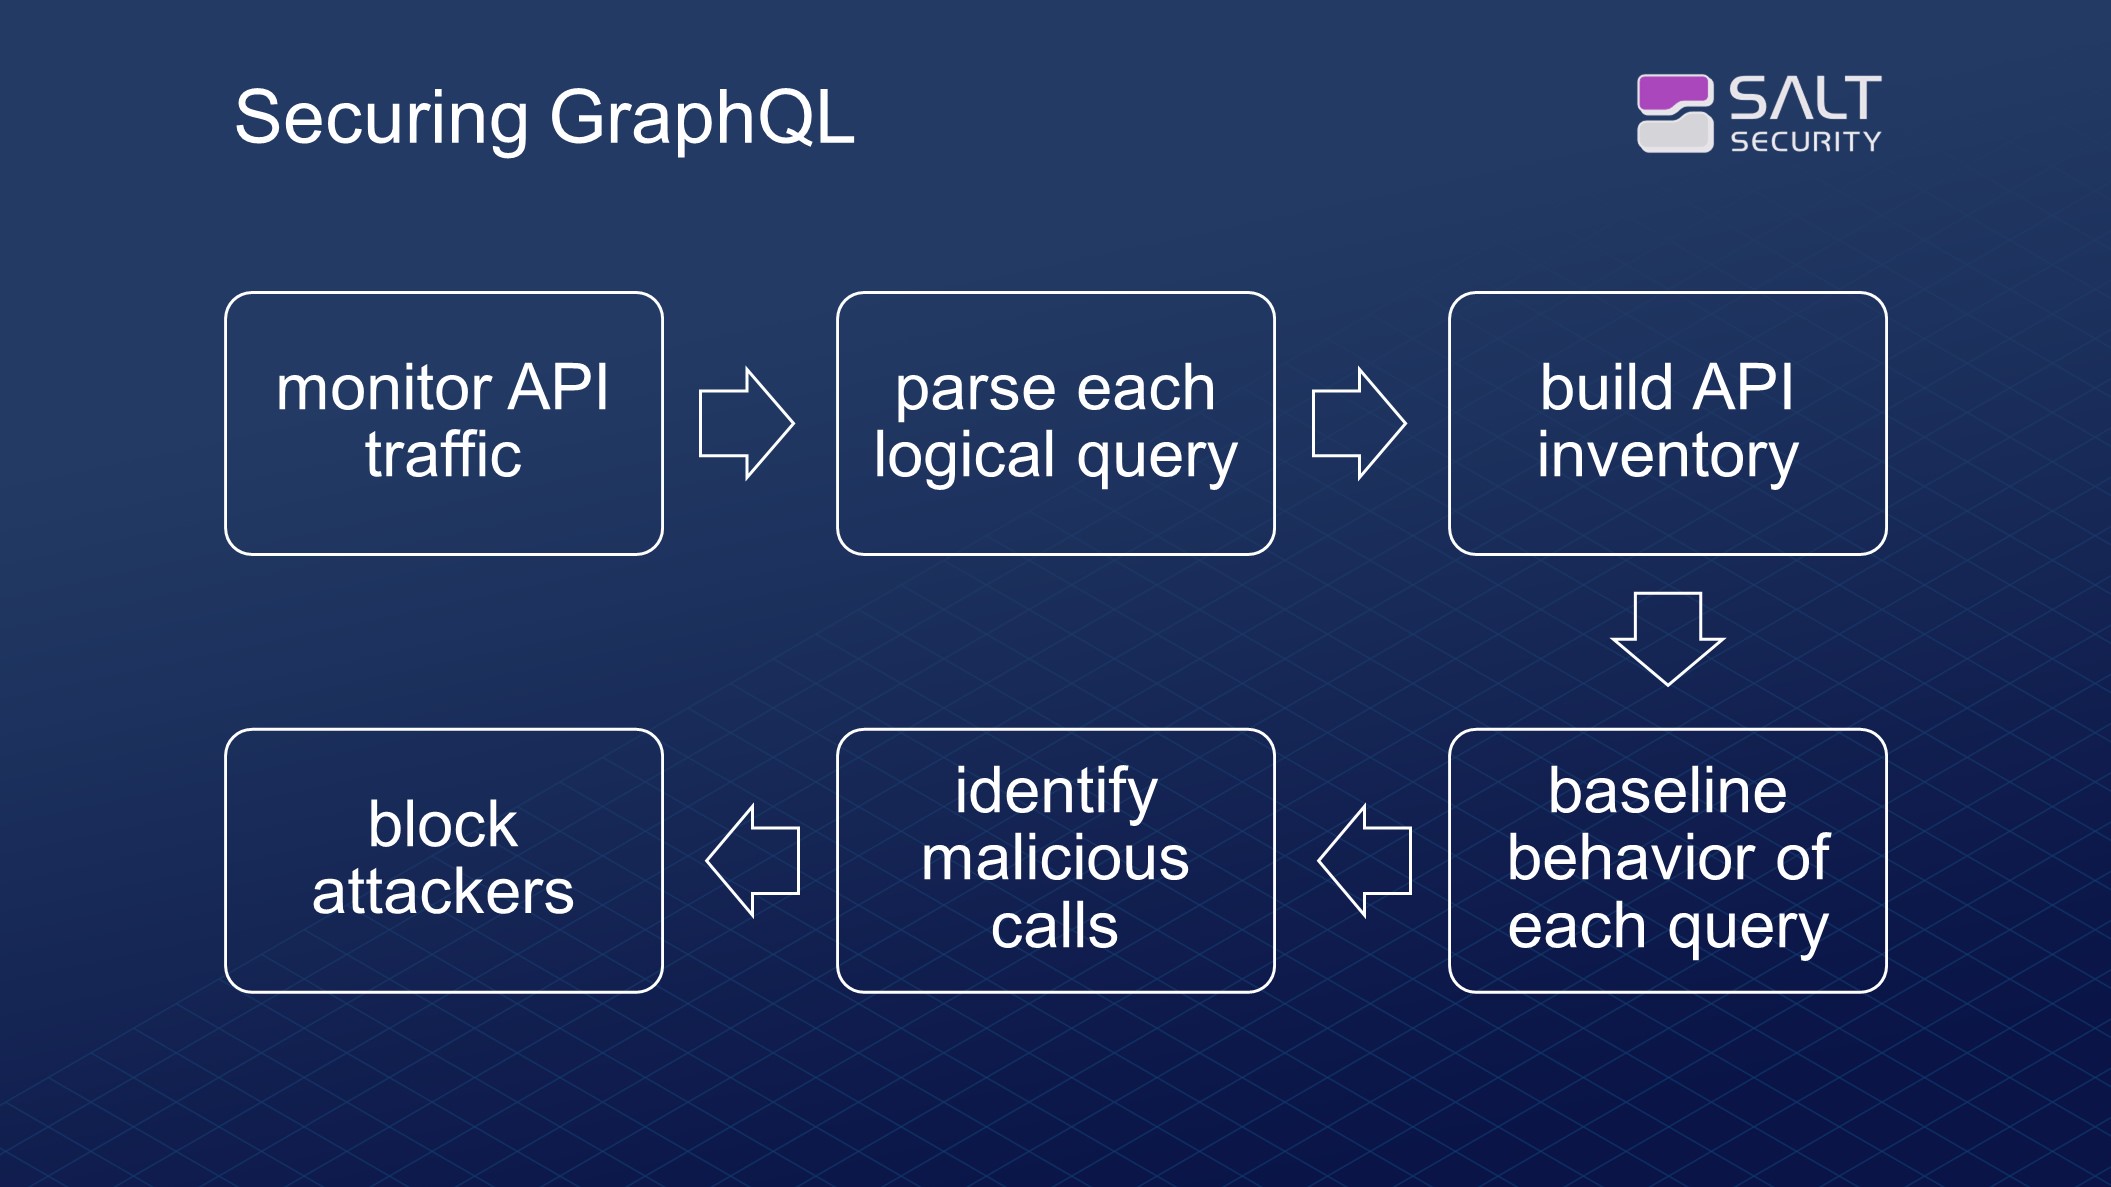
    Elad Koren, chief product officer for Salt Security, said adding support for GraphQL alongside existing support for REST APIs to the Salt Security API Protection platform will make it possible for security teams to discover those APIs, mitigate data exposure, stop attacks and eliminate vulnerabilities. The Salt platform parses the complex structure of each GraphQL query to identify unique object entities that are then used to create a complete inventory of the GraphQL APIs being employed.

    APIs built using GraphQL are more challenging to secure because of the unique call and response formats, noted Koren. Cybercriminals can also, for example, leverage GraphQL capabilities such as nested queries and query batching, to launch distributed denial of service (DDoS) attacks, he said.

    Many developers will tend to assume that, because GraphQL is relatively new, most cybercriminals are primarily focused on exploiting REST APIs. However, as more developers employ GraphQL, it’s only a matter of time before cybercriminals begin to find ways to exploit APIs that may not be as secure as the REST APIs that many organizations already know how to secure.

    The Salt Security platform itself is based on a big data engine that employs machine learning algorithms and other forms of artificial intelligence (AI) to identify attacks in real-time. It creates a baseline to identify legitimate system behavior while preventing cybercriminals from using penetration testing tools to perform reconnaissance.

    From a DevOps perspective, the Salt Security API Protection Platform integrates with tools such as Jira and Slack to ensure that remediation details are routed to the right development team in addition to helping track tickets to ensure remediation fixes are implemented. It also can be integrated with security information event management (SIEM) platforms from vendors such as Splunk and Sumo Logic to enable incident response for both DevSecOps and security operations teams.

    Most IT teams will not be replacing REST APIs with GraphQL-based APIs overnight. However, there will soon be enough APIs based on GraphQL to warrant additional security measures. Less clear is to what degree those security measures will be put in place by DevSecOps teams versus a security operations team.

    One way or another, however, the number of APIs that need to be secured is accelerating rapidly as organizations roll out a new generation of microservices-based applications that drive mission-critical digital business transformation initiatives. Each microservice has its own API that needs to be built and then secured. Unfortunately, most APIs are built by developers that don’t always have the greatest appreciation for security. As such, while more responsibility for API security is shifting left toward developers, many security teams would be well advised to make certain every API being deployed is fully secure.

  • Postman Survey Shows Focus on Building and Deploying APIs

    Postman Survey Shows Focus on Building and Deploying APIs

    A survey of more than 28,000 developers and application programming interface (API) professionals published today by Postman found nearly half of respondents (49%) are now spending the majority of their time developing APIs. More than a quarter (28%) now spend 20 or more hours per week working with APIs.

    Kin Lane, chief evangelist for Postman, a provider of a platform for building APIs, said that shift reflects an increase in software development and integration activity that began at the start of the COVID-19 pandemic. Almost two-thirds of respondents (63%) said the pandemic somewhat or significantly affected their work, with almost half of those respondents noting that changes made with their organization were enabled and supported by APIs.

    Additionally, a full 94% of respondents said the investment of time and resources into APIs will increase or stay the same for the next 12 months. The biggest obstacle to creating APIs is lack of time (45%) while the biggest obstacle to consuming an API is lack of documentation (55%). In terms of API goals, the survey found that quality (80%), agility (66%) and reliability (65%) are the top three goals among survey respondents.

    However, the survey also noted only a third of respondents said they could build and deploy an API in anywhere from a single day to a week, with most requiring one week to a month. About one-third also said they deploy APIs to production between once per week and once per month. More than 80% of respondents noted that less than 25% of their changes fail while a similar percentage said they can recover in less than a day with a third reporting they fully recover in less than an hour.

    The Postman survey also found that more than three-quarters of respondents (76%) have less than five years of experience with API development. Only half of respondents indicated that they agree or strongly agree that the leadership of their API team has a clear sense of where their API practice should be in five years. However, microservices (58%) and Kubernetes (50%), containers (46%), serverless architecture (44%) and GraphQL (35%) were ranked among the technologies that respondents were most excited about heading into 2022.

    On the plus side, more than 60% of respondents felt their API leadership and governance teams demonstrated a “willingness to change” as well as duly considering “the interests and opinions of employees.” When it comes to regularly providing feedback and process, more than half of leadership and governance teams (53%) scored well.

    The top two ways API teams collaborate is via a dedicated collaboration platform (50%) or by publishing API artifacts to repositories such as GitLab, GitHub and Bitbucket (45%), according to the Postman survey. The most widely used DevOps tools are Jenkins (37%), Azure DevOps (26%), GitHub Actions (25%), AWS DevOps (23%) and GitLab Pipelines (22%).

    In terms of deploying APIs, continuous integration/continuous delivery (CI/CD) platforms are the most widely employed (57%), followed by deploying APIs in the cloud (38%), frameworks (34%) and custom-built deployment methods (27%).

    Just over 70% of respondents ranked security and performance as the top factors considered when integrating with an API. When producing an API, however, the top factors are integration with internal systems, integration with external systems, adding functionality to an internal system and enhancing functionality for an end customer. Similarly, when consuming an API the top factors are integration with external systems, adding functionality for end customers, adding functionality to internal systems and integration between internal systems.

    In general, Lane noted that, as more APIs are developed and deployed to drive various digital business transformation initiatives, organizations will need to pay more attention to API discovery and management. There’s a tendency for different teams within organizations to not only create redundant APIs but also forget about so-called zombie APIs that are no longer supported but can still be exploited by cybercriminals.

    Overall, Lane said the survey makes it clear more organizations are pursuing an API-first approach to digital transformation. The challenge now is managing all the APIs that can quickly become too much of a good thing.

  • What 30 Years of Linux Taught the Software Industry

    What 30 Years of Linux Taught the Software Industry

    Linux has become the largest collaborative development project in the history of computing over the last 30 years. Reflecting on what made this possible and how its open source philosophy finally imposed itself in the industry can offer software vendors valuable lessons from this amazing success story.

    The web may not have reached full adulthood yet, but it has already crafted its own mythology.

    August 25, 1991: Linus Torvalds, a 21-year-old university student from Finland, writes a post to a Usenet group: “Hello everybody out there using minix — I’m doing a (free) operating system (just a hobby, won’t be big and professional like gnu) for 386 (486) AT clones […]”. A few weeks later, the project, which will eventually be known as Linux, is published for the first time.

    This is the starting point of an epic that few could have foreseen.

    Fast-forward 30 years and the Linux kernel isn’t only running on most of the web servers and smartphones around the globe, but it also supports virtually all of the much more recent cloud infrastructure. Without open source programs like Linux, cloud computing wouldn’t have happened.

    Among the major factors that propelled Linux to success is security. Today, the largest software companies in the world are taking open source security to new levels, but the Linux project was one of the first to emphasize this.

    How Linux Became the Backbone of the Modern IT World

    Brief History

    Open source predates the Linux project by many years and is arguably as old as software itself. Yet, it is the success of the latter that propelled this movement in the 1990s. When it was first submitted for contribution in 1991 by Torvalds, the Linux kernel was the GNU project’s ‘missing link’ to a completely free software operating system, which could be distributed and even sold without restrictions. In the following years, and as the project started to incorporate proprietary licensed components and grow in popularity, a clarification on the meaning of “free software” became necessary.

    This led to the coining of the term “open source” as we use it today, thanks in part to Eric Raymond’s seminal paper The Cathedral and the Bazaar, a “reflective analysis of the hacker community and free software principles.” Open source was chosen to qualify software in which the source code is available to the general public for use or modification from its original design, depending on the terms of the license. People may then download, modify and publish their version of source code (fork) back to the community.

    Open source projects started gaining traction in the late nineties thanks to the popularity of software like Apache HTTP Server, MySQL and PHP to run the first dynamic websites on the internet.

    Facts and Figures

    Today, not only is Linux powering most of the digital era, but open source has become the leading model for how we build and ship software. Though most people don’t realize it, much of the technology we rely on every day runs on free and open source software (FOSS). Phones, cars, planes and even many cutting-edge artificial intelligence programs use open source software. According to the Linux Foundation, 96.3% of the world’s top one million servers run on Linux and 95% of all cloud infrastructure operates on it. Other infrastructure also relies on open source: 70% of global mobile subscribers use devices running on networks built using ONAP (Open Network Automation Platform).

    Linux adoption is very high in professional IT, where it’s become a de facto standard, especially with the advent of the cloud era. In fact, 83.1% of developers said Linux is the platform they prefer to work on. This success is due, in large part, to the community that contributed to its source code since its creation: More than 15,000 developers from more than 1,500 companies. Linux went on to become, arguably, the biggest success story of the free software movement, proving that open source could lead to the creation of software as powerful as any sold by a corporation.

    The Linux Foundation, a non-profit technology consortium founded in 2000 to support the collaborative development of Linux and OS software projects, is itself a big success. It now has more than 100 projects under its umbrella, spread across technology sectors like artificial intelligence, autonomous vehicles, networking and security. Several subset foundations have also emerged over the years, including the Cloud Foundry Foundation, the influential Cloud Native Computing Foundation, and the recently announced Open Source Security Foundation. The Foundation estimates the total shared value created from the collective contributions of its community to a whopping $54.1 billion.

    All these achievements may not have been possible without the embrace of open source by the enterprise world, which may represent its biggest win.

    Enterprise Adoption

    Companies began to realize that many open source projects were easier and cheaper to implement than asking their developers to build the basic pieces of an internet business over and over again from scratch.

    Twenty years ago, most businesses ran atop proprietary software from Microsoft, Oracle and IBM, and the idea of collaborating on big software projects might have sounded laughable to them. Today, these companies, along with relative newcomers such as Google, Facebook and Amazon, are not only employing thousands of full-time contributors to work on open source projects like Linux, they also regularly choose to open source some of their state-of-the-art projects; from Google Brain’s machine learning platform TensorFlow and container orchestration platform Kubernetes to Facebook’s React.

    There’s no question that open source software created a new wave of business opportunities. As more companies took an interest in open source projects, they realized they didn’t necessarily have the in-house expertise to manage those projects themselves and turned to startups and larger companies for help.

    Even Microsoft, which famously warred against the very concept of Linux for nearly a decade, made a strategic shift to embrace open source in the 2010s, led by CEO Satya Nadella. The IT giant finally joined the Linux Foundation in 2016 and acquired GitHub, the largest host for open source projects, two years later. It has since become one of the biggest sponsors of open source projects.

    As a consequence, the stakes have been raised for open source software, which is the engine powering the shift toward the cloud for virtually every company. In this context, security is becoming a topic of the utmost importance, and the commitment to secure the open source ecosystem is growing fast.

    Setting a Standard for Security and Trust

    Open Source Security Issues

    Following the OSS adoption boom, the sustainability, stability and security of these software packages is now a major concern for every company that uses them.

    The Census II report on structural and security complexities in the modern-day supply chain “where open source is pervasive but not always understood” revealed two concerning trends that could make FOSS more vulnerable to security breaches. First, the report said it is common to see popular packages published under individual developers’ accounts, raising the issue of security and reliability. Second, it is very common to see outdated versions of open source programs in use, meaning they contain fewer security patches.

    The 2021 OSSRA report agrees: “98% of the codebases audited over the past year contain at least one open source component, with open source comprising 75% of the code overall.” The report also noted that 85% of the audited codebases contained components “more than four years out of date”.

    This highlights the mounting security risk posed by “unmanaged” open source: “84% of audited codebases containing open source components with known security vulnerabilities, up from 75% the previous year. Similarly, 60% of the codebases contained high-risk vulnerabilities, compared to 49% just 12 months prior.” Not only is the security posture affected, but there are also compliance issues that can arise from unsupervised integration of open source content because licenses can be conflicting or even absent.

    Because large corporations are now a big part of the open source ecosystem, their sponsorship is a welcome source of financing for many people whose work had been done for free until now, yet it may not be enough. The open source community is well-known for its commitment to independence, its sense of belonging and its self-sufficiency, and expecting contributors to voluntarily address security issues is unlikely to succeed.

    This is where the experience of building Linux over 30 years and coordinating the work of thousands of individual contributors may be an example to follow.

    Linux Foundations

    In Linux kernel development, security is taken very seriously. Because it is an underlying layer for so many public and private software ‘bricks’ in the digital world means that any mistake can cost millions to businesses, if not lives. Since the beginning, it has adopted a decentralized development approach with a large number of contributors collaborating continuously. Therefore, it has consolidated a strong peer-reviewing process as the community development effort grew and expanded.

    The last stable release at the time of writing is 5.14, released on August 29th, 2021, only a few days before the 30th birthday of the project. The most important features in the release are security-related: One is intended to help mitigate processor-level vulnerabilities like Spectre and Meltdown and the other concerns system memory protection, which is a primary attack surface to exploit. Each Linux kernel release sees close to 100 new fixes per week committed by individuals and professionals from the likes of Intel, AMD, IBM, Oracle and Samsung.

    With such broad adoption and long history, the Linux project has reached a level of maturity that few, if any, other FOSS projects have seen. The review process and release model have built confidence for numerous downstream vendors. Although the world is not perfect and it is arguably difficult for them to keep up with such a high rate of change, they can at least benefit from strong security enforcement mechanisms and they can adapt their security posture in concordance to their “risk appetite”: Vendors are able to do the calculus of determining how old a kernel they can tolerate exposing users to.

    Pushing the Boundaries of Open Source Security

    Heartbleed and the Fragility of OS Security

    In April 2014, a major security incident affecting the OpenSSL cryptography library; disclosed as “Heartbleed.” The developer who introduced the bug acknowledged that, though he was working on the project with a handful of other engineers:

    “I am responsible for the error because I wrote the code and missed the necessary validation by an oversight. Unfortunately, this mistake also slipped through the review process and therefore made its way into the released version.” OpenSSL, an open source project, is widely used to implement the Transport Layer Security (TLS) protocol. In other words, it’s a fundamental piece used to secure a large part of the web.

    Open source was seen as fundamentally secure for a long time because the more people examine a line of code, the better the chances of spotting any weakness. Additionally, this model prevents “security by obscurity,” whereby the bulk of the protection comes from people not knowing how the security software works—which can result in the whole edifice tumbling down if that confidential information is released or discovered externally.

    This incident was a major turning point for a large share of the biggest web corporations: They realized that many open source technologies underpinning their core operations could not be “assumed to be secure” anymore. Any human error could have huge implications; therefore, a specific effort had to be made to improve the security in this specific space.

    A New Era for Open Source

    As we advance in an era where open source is omnipresent in codebases, tooling, networks and infrastructure and is even in fields other than software, security awareness is starting to take hold. But it needs a lot more work.

    A big part of the challenge, to begin with, is for the industry to understand the scope of the problem.

    Google just announced that it will be committing “$100 million to support third-party foundations that manage open source security priorities and help fix vulnerabilities.”

    The Secure Open Source (SOS) pilot program, run by the Linux Foundation, will reward developers for enhancing the security of critical open source projects that we all depend on.

    In doing so, Google leads the way in enlarging the financial sponsorship of big players like companies and governments — which are increasingly sponsoring open source both directly and indirectly. However, they also recommend that organizations “understand the impact they have on the future of the FOSS ecosystem and follow a few guiding principles.”

    What could these principles look like?

    A Roadmap to Safely Use and Contribute to Open Source

    The Linux Foundation proposed a specific Trust and Security Initiative which describes a collection of eight best practices (with three degrees of maturity) open source teams should use to secure the software they produce as well as by a larger audience to “raise the collective security bar.” Here they are:

    • Clarifying the roles and responsibilities, and making sure everyone is aware of their security responsibilities across the organization.
    • Setting up a security policy for everyone; in other words, a clear north star for all members of the organization.
    • ‘Know your contributors’ is defined as a set of practices to make risk-based decisions on who to trust and fight offensive cyberwarfare techniques, such as the poisoning of upstream code.
    • Locking down the software supply chain: This has become a preferred target as adversaries clearly understood that they can have a bigger and more effective impact with less effort than targeting individual systems.
    • Provide technical security guidance to narrow potential solutions down to the more appropriate ones in terms of security.
    • Deploy security playbooks to define how to do specific security processes, specifically incident response and vulnerability management processes, like creating roles and responsibilities or publishing security policies. This may feel formal, antiquated and old-school but having pre-defined playbooks means that teams can focus on shipping software and not learning how to do security, especially at the least convenient and most stressful time.
    • Develop security testing techniques with automated testing strongly recommended since it scales better, has less friction and less cost to the teams and aligns well to modern continuous delivery pipelines.

    However, the authors of the guide are aware that some major challenges are still facing the industry and, as such, need to be addressed. They mention:

    • The lack of open source security testing tools
    • The fact that open source package distribution is broken
    • The fact that the CVE format for vulnerability disclosure is also broken
    • The lack of a standard for a security build certificate which would allow any consumer to transparently verify that a product or component complies with the announced specifications

    “The types of verification can and should include the use of automated security tools like SAST, DAST and SCA, as well as verification of security processes like the presence of security readmes in repos and that security response emails are valid.”

    A scheme like this could have a significant and lasting effect on the security quality of open source software and the internet at large.

    The Linux project, born 30 years ago, is present in all layers of the modern software stack today. It is used by all the largest server clusters powering the modern web and any business going digital will use it at some point. This unparalleled longevity and success have demonstrated that the open source model was compatible with the requirements of enterprise-grade services and economically viable. Now that open source is all the rage in the software industry, a consensus and action plan on how to ensure the sustainability of this ecosystem becomes urgent. The top priority for businesses that depend on it is to adopt strong application security guidelines, like the ones promoted by the Linux Foundation, which have proven their value.

    One last note on the nature of open source: As businesses are now much more bound by the common use of open source components to build upon, they should not fall into the “tragedy of the commons” trap. This would mean waiting until others take action; for instance, to improve the global software security landscape. This might be one of the biggest challenges confronting our highly collaborative industry.
  • Intel Woos DevOps Teams with API and Processor Advances

    Intel Woos DevOps Teams with API and Processor Advances

    During the online Intel Innovation 2021 event, Intel announced today a unified Developer Zone for accessing application programming interfaces (APIs) that it makes available via a oneAPI toolkit to IT teams that want to more easily invoke a wide range of processor types and classes.

    At the same time, the company also revealed it is creating a set of oneAPI centers of excellence that will make it easier for DevOps teams to consume those APIs. Partners participating in that initiative include Oak Ridge National Laboratory, University of California Berkeley, University of Durham and University of Tennessee. Intel will also make the Intel Graphics Visualization Institutes of Xellence part of this program.

    Next year, Intel is also promising to deliver oneAPI 2022 toolkits that will add 900 additional capabilities including an ability to develop applications for CPUs and graphical processor units using what Intel described as the first unified C++/SYCL/Fortran compiler.

    The company is also planning on making available Data Parallel Python tools in addition to expanding its Advisor accelerator performance modeling tools to include support for VTune Flame Graph to visualize performance hot spots.

    There will also be additional oneAPI integrations to add support for Microsoft Visual Studio Code and the Microsoft Windows Subsystem for Linux 2 platform. Intel also created an Intel oneAPI AI Analytics toolkit to enable out-of-the-box AI development that is supported by workstations running Linux from Dell Technologies, HP and Lenovo. Additionally, Microsoft and Intel have agreed to create a complete data science toolchain to Windows 11 that will become part of the Surface Laptop Studio framework for building applications.

    Greg Lavender, chief technology officer, senior vice president and general manager of the software and advanced technology group at Intel, said it’s critical to make sure that DevOps teams add support for the acceleration engine and extensions that Intel makes available within its processors to the runtime environments they deploy. Otherwise, developers will never be able to routinely invoke those capabilities to build next-generation applications.

    The company also revealed that next-generation Intel Xeon Scalable Processors, code-named Sapphire Rapids, will have additional acceleration engines to both simplify deployments at scale and optimize processors’ core utilization in a way that reduces power consumption. Overall, Intel is promising up to a 30x total performance gain for artificial intelligence (AI) applications running on these processors.

    Other hardware advances announced today include a 12th generation Intel Core family based on 7-nanometer processors and a Mount Evans project through which Intel is collaborating with Google Cloud to build processors based on application-specific integrated circuit (ASIC) chips.

    The company also unveiled an Intel ArcTM Alchemist family of graphics systems on chips (SoCs) that take advantage of machine learning algorithms to optimize performance and touted an Intel Tofino fabric processor (IFP) that adds intelligence to network switching via support for P4 programming tools.

    Finally, the company noted that an Aurora supercomputer, due out in 2022, will exceed two exaflops of peak double-precision compute performance.

    As Intel seeks to regain the processor high ground from rivals such as NVIDIA, ARM and AMD, it’s clear that the future of IT will be defined by a broad range of processor classes that all have unique capabilities. The challenge now is deciding which of those capabilities to actually make available to developers that are largely dependent on the runtime environment that DevOps teams decide to make available.

  • GitHub Expands Developer Productivity Tools Portfolio

    GitHub Expands Developer Productivity Tools Portfolio

    During the online GitHub Universe 2021 conference, GitHub today unveiled a bevy of updates intended to boost developer productivity by making it easier for developers to write code faster and collaborate more easily.

    The GitHub Copilot tool that GitHub developed in collaboration with OpenAI, a research and development lab, to help developers write better code faster is being extended via a technical preview to add support for Java and the integrated development environment (IDE) JetBrains.

    In addition, the Codespaces tools that GitHib makes available to pre-configure development environments is being extended to include support for devcontainer feature composition, the GitHub command line interface (CLI) and REST application programming interfaces (APIs) along with additional access controls.

    GitHub Actions has also been updated to add support for deployments using the OpenID Connect standard in addition to providing access to deployment environments to simplify approvals, improvements to reusable workflows and auto-scaling functionality for self-hosted runners.

    There is also now a Command palette tool in beta to help developers navigate GitHub along with a public beta of a GitHub Issues tool that makes it simpler for developers to filter, sort and group issues and pull requests. Additional features that have been added since GitHub Issues was first previewed include iteration support, reporting and data visualization tools and the ability to employ it across public projects.

    Finally, GitHub is adding, in beta, support for Ruby as a programming language that CodeQL analysis engine can now scan for vulnerabilities along with the ability to customize permissions for accessing GitHub Enterprise Cloud.

    Ryan Salva, vice president of product management for GitHub, said collectively GitHub is committed to making developers more productive by, for example, autocompleting code as developers write. Support for additional programming languages will also be forthcoming in the months ahead. The goal is not to leverage AI to replace developers but, rather, eliminate the drudgery that gets in the way of developers becoming more creative, noted Salva.

    There won’t come a day any time soon when developers won’t have to type to write code, but it is possible to leverage AI to provide a type-ahead capability that reduces coding errors, added Salva.

    The goal should be to enable developers to create more application experiences at a time when more organizations than ever are consuming applications that drive a wide range of digital business process transformation initiatives, said Salva.

    As part of that effort, Salva noted it’s also critical to reduce the amount of friction developers encounter writing code starting with setting up the development environment itself.

    It’s not clear yet what impact all the focus on developer productivity and collaboration will have on the rate at which applications are being built and deployed. However, as developers become more productive, the number of application development projects that can be launched simultaneously should increase. In fact, there may come a day when applications are being built faster than organizations can deploy them without adopting continuous delivery best practices that rely on higher levels of automation to install software.

    Regardless of that application delivery challenge, however, it’s a problem most organizations right now would consider themselves fortunate to have.

  • Codenotary Uses Immutable Database to Verify Software Artifacts

    Codenotary Uses Immutable Database to Verify Software Artifacts

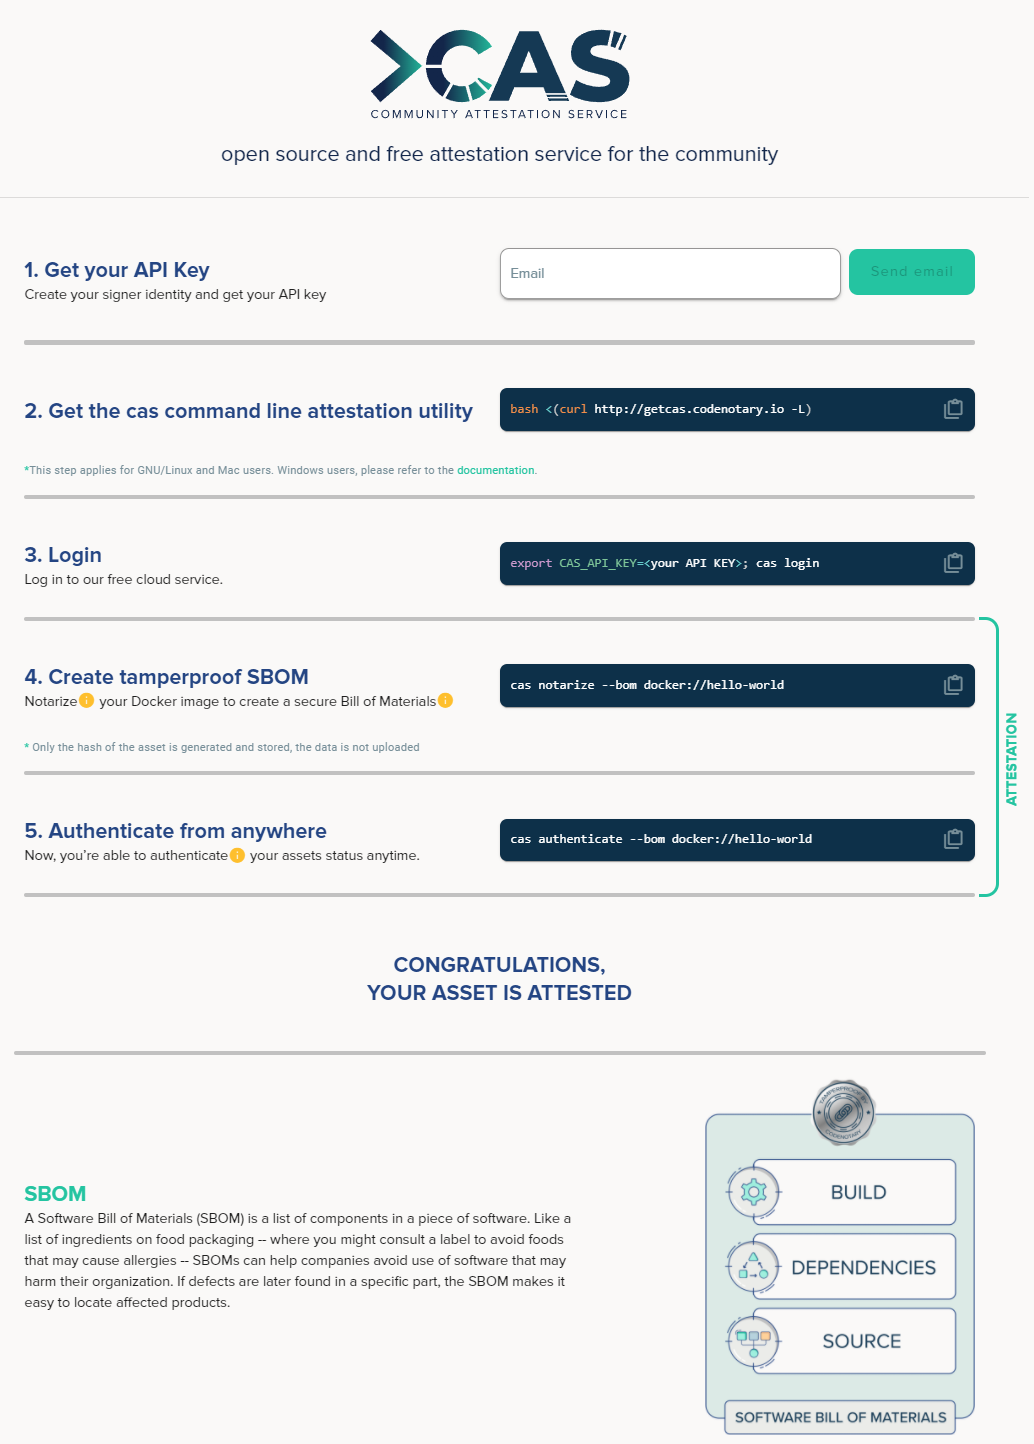
    Codenotary today unfurled a free notarization and verification service for open source artifacts and containers to enable IT organizations to track the provenance of the components that make up their applications.

    Dennis Zimmer, Codenotary CTO, said the Community Attestation Service is based on an immutable open source immudb database that cryptographically attaches an identity to each software artifact. Additionally, the Community Attestation Service can be integrated with the continuous integration/continuous delivery (CI/CD) platform that DevOps teams employ to build and deploy applications using those artifacts, added Zimmer.

    The identities created by the Community Attestation Service can then be used to verify a software bill of materials (SBOM) that will soon be required by not only every U.S. federal agency but also organizations that are trying to better secure their software supply chains in the wake of a series of high-profile breaches, said Zimmer. The Community Attestation Service will also encourage developers to reuse source code, builds, repositories and Docker container images that they know they can reliably employ within a zero-trust IT environment, noted Zimmer.

    Some developers have, of course, been signing their code for years, while others simply didn’t see the need. With its free service, Codenotary is trying to expand the pool of developers that will not only sign their code but do so in a way that can’t be tampered with later, noted Zimmer.

    Unlike blockchain databases that are employed to provide immutable records of transactions, Zimmer said the immudb platform was created to provide an immutable database capable of processing millions of transactions per second. That database is also being used to build a wide range of applications that go beyond the scope of the Community Attestation Service so DevOps teams can have confidence in the viability of the underlying platform, noted Zimmer.

    In the wake of some troubling security breaches, it’s now only a matter of time before security teams start to ask more difficult questions about how applications are built. Developers could wait for those cybersecurity teams to eventually create policies that DevOps teams would be required to enforce, or they can more proactively embrace a service that tracks the provenance of code that hopefully, has been scanned for all known vulnerabilities. In fact, it may not be too long before organizations decide not to employ code that has not been verified. There may even be a backlash against using code that is unsigned that could result in many existing applications either being updated or outright replaced.

    On the plus side, Zimmer noted there’s a lot more awareness of the need to sign code. The challenge is most organizations don’t have the processes in place. Fortunately, there’s a lot more interest in DevSecOps best practices to ensure the integrity of code. However, awareness of the need for something doesn’t always result in concrete actions being taken unless DevOps teams can simply make it easy for developers to do the right thing. After all, it’s not as though developers want to employ insecure code, it’s just that they are often simply too busy to make sure every last artifact employed is verified as secure.

  • FinOps Cloud Cost Optimization via Governance-as-Code 

    FinOps Cloud Cost Optimization via Governance-as-Code 

    Cloud implementations continue to grow in scope and complexity. Too often, this expansion also means costs keep spiraling out of control. In this article, we’ll examine why the emerging practice of cloud financial management (FinOps) is so essential to containing costs in the cloud. We’ll then discuss the challenges teams encounter as they start to apply FinOps approaches. Finally, we’ll reveal the opportunity presented by employing governance-as-code to establish continuous cloud cost optimization—and how this approach makes it practical for teams to put the theory of FinOps into practice so they can keep cloud costs in check.

    The Emergence of FinOps

    For many organizations, there’s been a race to leverage cloud services, with teams seeking to realize advantages in flexibility, agility and efficiency. Within an organization, it’s not only a matter of more workloads running in the cloud, it’s a matter of more distinct deployment models being used, more teams using cloud services and leveraging multiple service providers.

    In the process, teams have had to contend with rapid growth in the size and diversity of the implementations that have to be managed—and paid for. It is this latter aspect that has been a rude awakening to those responsible for managing budgets. Left unchecked, this growth in cloud use has led to spiraling costs and predicting, managing and controlling these costs only grows more difficult as deployments get more complex and more frequent.

    This need for improved cost management has given rise to a new discipline: Cloud financial management; or FinOps. In short, FinOps is a way of bringing financial discipline and accountability to the variable-cost paradigm found in the cloud. FinOps brings together a combination of technologies, processes and teams, including professionals from technology, finance and business. By gaining an improved ability to understand, track and manage cloud costs, teams can begin to maximize the value realized through their cloud expenditures. Given the strategic and urgent nature of cloud cost management, it’s not surprising that FinOps teams are growing. According to research conducted by the FinOps Foundation, FinOps teams expanded 47% over last year, and these professionals are expecting their teams to grow 75% in the next year.

    Challenges in Establishing FinOps

    While there’s a lot of promise behind the establishment of FinOps practices, there are also many obstacles standing in the way for teams. When the FinOps Foundation queried respondents about top challenges, these were the top five responses:

    • Getting engineers to take action (39%)
    • Dealing with shared costs (33%)
    • Accurate forecasting (26%)
    • Reducing waste or unused resources (25%)
    • Full allocation of costs (23%)

    Lacking comprehensive control and visibility over multi-cloud environments means these teams can’t proactively manage costs—and too often find out about wasted expenditures and high costs of underutilized resources after the fact. Because stretched teams are reliant upon manual follow-ups and tactics, it is difficult to get engineers to respond as quickly and effectively as needed.

    Compounding these challenges is the fact that across teams, different tools and processes are used. For example, different development teams might be using different provider services along with varying deployment tools, such as AWS Cloud Formation, HashiCorp Terraform, Kubernetes and so on. This inconsistency introduces inefficiencies and miscommunication and stifles team productivity.

    While the cloud offers a range of benefits compared to legacy, on-premises infrastructure, without proper governance, cloud costs can quickly spiral out of control. In fact, Gartner analysts report that in the next few years, 60% of organizations will encounter cost overruns in public clouds.

    Rethinking Cost Management

    For all the reasons articulated above, teams are being asked to take a new approach to cloud cost management, one that aligns with the principles of FinOps. For many, this means embracing the concept of governance-as-code to optimize cloud costs. Cloud governance-as-code represents a way to automatically and dynamically apply policies, including for cost optimization, in fast-changing cloud environments.

    With governance-as-code approaches, policies are defined using a standard language. Code associated with cost policies is created, deployed and maintained in much the same way developers manage application or infrastructure code. Developers don’t have to worry about tracking or managing costs. Cost policies are continuously evaluated against current state, utilization and configuration of cloud infrastructure. If any violations occur, automated notifications and workflows can be triggered. Here are the key requirements for using governance-as-code to establish continuous cloud cost optimization:

    Cost Policies are Defined via an Intuitive Language

    Traditionally, development, operations and financial groups worked in silos. Each team had its own tools, workflows and policies, and even fundamental terminology could vary substantially.

    To maximize the potential of continuous cloud cost optimization via governance-as-code, solutions need to enable teams to define, manage and revise policies using an easy-to-understand, consistent language. This makes it much easier for different teams to collaborate and gain alignment on key cost management policies and best practices.

    Finally, to be effective in establishing continuous cloud cost optimization, governance-as-code offerings need to employ a language that is independent of any specific programming languages that application developers may use. Further, these languages should be applicable to the broadest set of applications, cloud services, development tools and so on. This is vital to ensure that development teams retain maximum flexibility in the tools and services they can use.

    Cost Policies are Managed and Deployed via Git Within CI/CD Workflows

    Once policies are reviewed and finalized, teams must be able to apply these policies within the development organization’s existing continuous integration/continuous delivery (CI/CD) workflows.

    Through robust governance-as-code approaches, teams can create cost policies as code artifacts and deploy them via open source version control systems like Git. Through this approach, teams can apply policies in a manner consistent with their software development and delivery life cycles.

    By codifying cost governance in this way, cost controls can be deployed via Git within a CI/CD pipeline. This approach enables teams to avoid complex manual processes associated with tasks like managing tickets, requesting changes and so on. This also helps teams keep up with the accelerating pace of today’s dynamic cloud and development environments. Further, this approach means governance code can be traced through various state changes, rolled back if needed and so on, just like application code.

    Cost Policy Violations are Detected and Addressed in Real-Time

    Through continuous cloud cost optimization via governance-as-code, teams are  empowered to institute not only continuous detection but also immediate action. Policies can be employed at regularly scheduled intervals or they can be triggered based on certain events.  This approach enables enforcement of workflows and actions that may be required. If policy violations occur, notifications to relevant teams or team members can happen automatically and advanced workflows can be triggered. For example, a policy could identify RDS instances greater than 30 days old that have had no connections in the last 14 days. It would then notify the owners of these instances. If they don’t take action in seven days, the instances could automatically be stopped.

    Cost Policy is Continuously Enforced and Refined

    Continuous cloud cost governance-as-code has a never-ending life cycle, just like the team’s software development life cycle. Cost governance code is built, deployed, tested and released, and the process continues as new policies are developed and refined over time. As requirements change, teams need to be able to periodically analyze cost data and update policies as needed.

    As organizations continue to invest larger sums in their cloud implementations, the need to establish strong FinOps capabilities will only grow more critical. However, as these cloud deployments continue to grow more complex, it can get increasingly difficult to realize the promise of FinOps. For these reasons, employing governance-as-code to establish continuous cost management is emerging as a key approach. With this approach, teams can achieve sustained compliance and minimize waste.

  • New Relic Acquires CodeStream to Close Observability Gap

    New Relic Acquires CodeStream to Close Observability Gap

    New Relic today revealed it has acquired CodeStream as part of an effort to make observability data more accessible to developers.

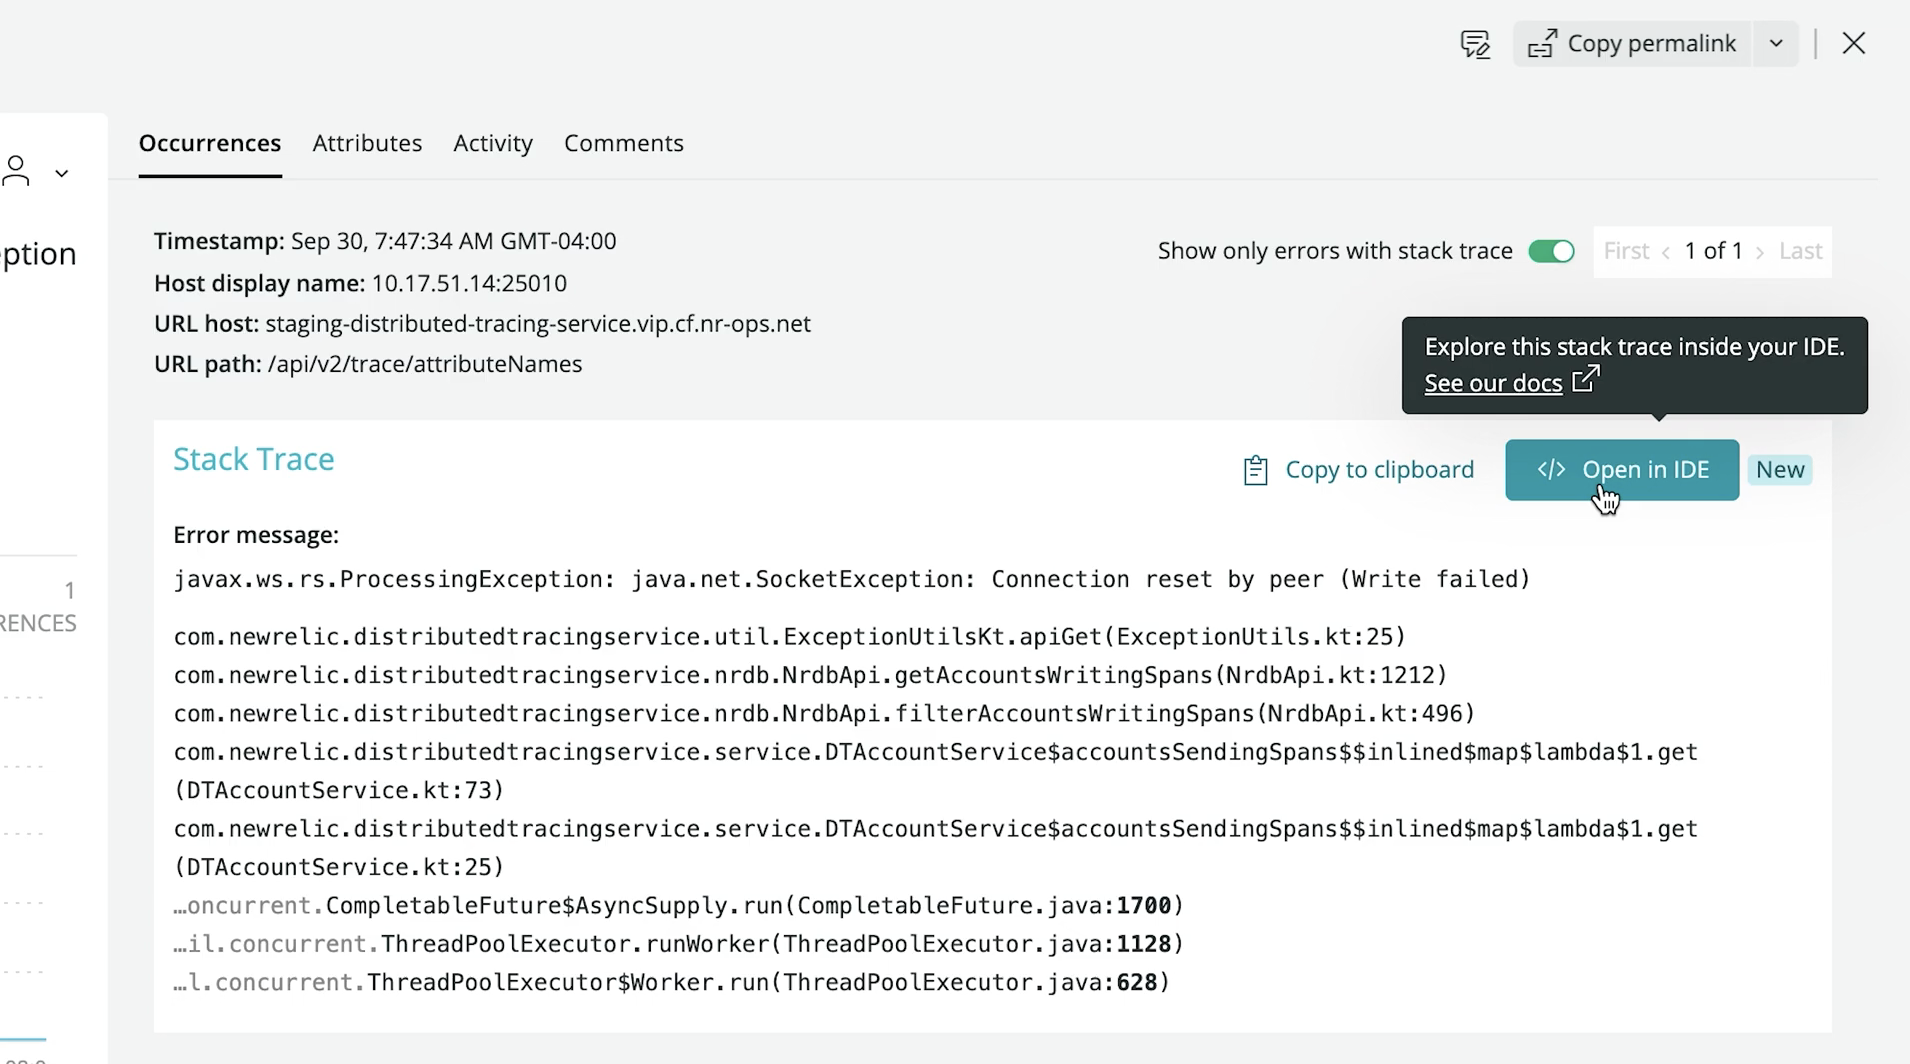
    Buddy Brewer, group vice president (GVP) and GM at New Relic said New Relic CodeStream makes application telemetry data collected via the New Relic One platform directly available within an integrated development environment (IDE), now including Microsoft VS Code. In addition, there are also integrations with Microsoft Teams and the GitHub repository.

    The goal is to close an observability gap that exists today between developers and IT operations teams that stems from a lack of developer visibility into production environments, he noted.

    Finally, New Relic is also announcing a core user pricing option for New Relic One that is aimed at developers. Starting at $49 per month, developers gain access to a core set of capabilities such as CodeStream integrations, errors inbox, logs, GraphQL application programming interfaces (APIs) and the ability to build and run custom applications on New Relic One.

    Peter Pezaris, CodeStream co-founder and CEO, now GVP and GM, strategy and developer tools at New Relic, said becoming part of New Relic will make it easier to bridge the divide that exists between most developers and IT operations teams by making it much easier for developers to see how their code is actually executing in a production environment. That capability will eliminate scenarios where code that runs just fine on a laptop executes poorly in a production environment, he added.

    Developers can also add inline code comments, trigger pull requests, request feedback and track issues directly from their IDE via integrations with a wide range of developer and communication tools. Developers also can switch from New Relic One into an IDE in a single click to navigate, triage and remediate production errors in the context of the code they wrote.

    New Relic is initially making New Relic CodeStream available for free—no credit card required—during a preview period that extends to January 12, 2022. Afterward, some of the more advanced features will require a paid user license once free tier limits are reached. Similarly, IT teams can also sign up for a free New Relic One account without entering a credit card to instrument their applications.

    As the responsibility for managing applications in production environments continues to shift left, Pezaris said it’s critical to give developers the tools they need to optimize code in a production environment.

    It’s not quite clear exactly how much responsibility for applications is shifting left toward developers; it differs from one organization to the next. Many are simply trying to reduce as much friction as possible between developers and their IT operations teams by providing more ‘connective tissue’ from New Relic that IT teams would have to otherwise write themselves, noted Pezaris.

    It may take some time to bridge the observability gap between developers and IT operations teams. Most IT operations teams are still coming to terms with what observability provides that existing IT monitoring tools don’t. Monitoring, at its core, focuses on predefined metrics to identify when a specific platform or application is performing within expectations. The metrics tracked generally focus on, for example, resource utilization. In contrast, observability combines metrics, logs and traces—a specialized form of logging—to instrument applications in a way that makes it simpler to troubleshot issues without having to rely solely on a limited set of metrics that have been pre-defined.

    In theory, at least, that level of observability should ultimately reduce the total number of incidents an IT operations team needs to fix by identifying issues long before they become an actual disruption.

  • HashiCorp Previews Updates to Consul Service Mesh

    HashiCorp Previews Updates to Consul Service Mesh

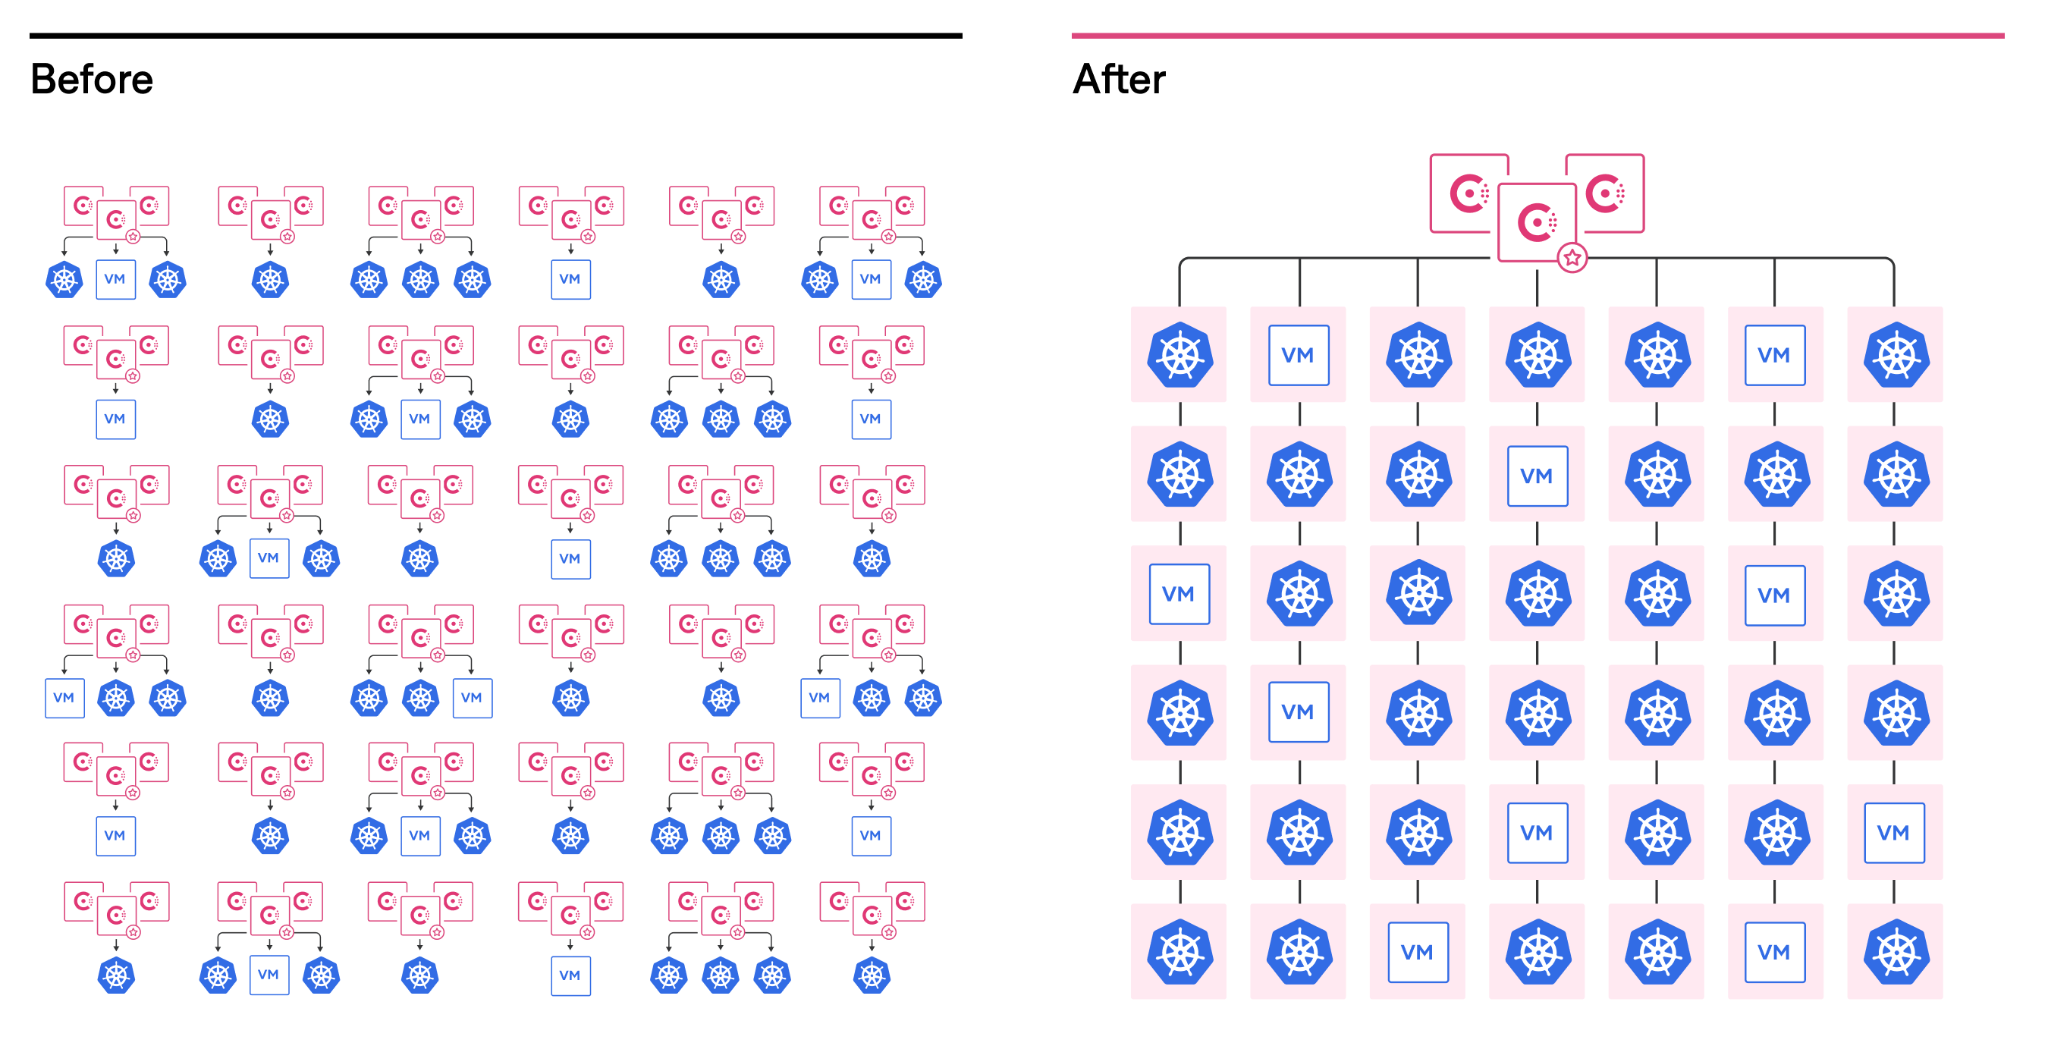
    During an online HashiConf Global conference, HashiCorp today made available a beta of an update to its open source Consul service mesh for virtual machines and Kubernetes clusters that makes it possible for multiple administrators to share the same instance of a multitenant service mesh.

    Version 1.11 of Consul will also add support for a command line interface (CLI) for Kubernetes that will provide an alternative to Helm charts for installing Consul on those clusters.

    Raymond Austin, director of product marketing for HashiCorp, said it’s become apparent that there is a need for a higher level of abstraction for managing application programming interfaces (APIs) that is easy to deploy across both legacy IT environments based on virtual machines and cloud-native environments based on Kubernetes clusters.

    Of course, in many cases, those Kubernetes clusters are deployed on top of virtual machines. However, there are also now more instances of Kubernetes being deployed on bare metal platforms at, for example, the network edge.

    As IT environments become more complex, a service mesh makes it simpler to discover, access and secure APIs that are now rapidly proliferating across the enterprise. That transition requires a more dynamic approach to not only managing APIs but also the network services those APIs depend on, added Austin.

    HashiCorp is betting that many IT organizations will prefer to rely on a lightweight open source platform supported by a single vendor rather than relying on more complex open source service mesh offerings being developed under the auspices of a consortium.

    It’s still not quite clear who within an IT organization is assuming responsibility for deploying a service mesh. Most often, it’s a development team that makes the initial decision. However, as IT operations teams become more aware that service meshes represent a capability that needs to be horizontally made available across multiple applications, it may be only a matter of time before some organizations decide to standardize on a single service mesh to reduce operational overhead, noted Austin.

    Service meshes will also play a critical role in simplifying management of networking and security services at a higher level of abstraction within a larger DevOps workflow.

    It’s still early days as far as service mesh adoption in the enterprise is concerned, but there are already a large number of service mesh options. In fact, there may never be a single dominant service mesh platform. Interoperability standards still need to be ratified that enable organizations that have standardized on different service meshes to apply policies to microservices spanning hybrid cloud computing environments.

    Of course, not every IT organization requires a service mesh yet, either. Many IT teams can still get by using a traditional proxy server or an API gateway until the number of microservices-based applications deployed starts to achieve critical mass. One way or another, however, the more APIs there are to manage, the more inevitable it becomes that an IT team will deploy a service mesh.

  • Say Goodbye to Late-Night SRE Wake-Up Calls

    Say Goodbye to Late-Night SRE Wake-Up Calls

    Thousands of SREs, on-call engineers and DevOps pros all over the world dread nothing more than the late-night incident alert. The pager buzzing at 2:00 a.m. can cause panic for SREs and leave IT and DevOps teams with quite a mess to contain. But incident response doesn’t have to cause panic if you have the right automation tools in place. If you have ever wondered why companies like Amazon, Google and Zoom rarely suffer service outages and downtime while other companies struggle to achieve similar efficiencies, you’re not alone. In fact, you’re halfway to understanding what makes incident response automation such a vital component of your workflow. 

    Without a doubt, the best way to take back control over manual incident response and—once again—sleep through the night is to implement a powerful automation solution for incident response. We’ve listened to stories from SREs around the globe about the benefits of automated incident response. Plus, we’ve experienced them ourselves (from companies like Cisco, for example).  In the end, we’ve learned a thing or two about creating efficiency by leveraging automation and integration. Below, we’ll briefly cover how leveraging automation to remediate issues with or without a human in the loop is the best way to say goodbye to 2:00 a.m. wake-up calls.

    An Overview of Incident Response

    First, a staggering fact: In 2019, 17% of global enterprises lost more than $5 million every hour their servers were down, according to Statista. Even for smaller companies, the cost of servers going down is enormous. Following the news of Facebook’s recent outage (losing $13.3 million an hour; not counting the loss from the stock price drop), the need for minimizing downtime and reducing these costs is clear. 

    In order to fix issues faster, organizations need an easy-to-use tool that SREs and DevOps teams can implement to troubleshoot and automate incident response. For one, users should opt for a drag-and-drop system. This method is preferred over headless automation tools that too often result in data loss and extended downtimes.

    Next, IT organizations need to take the next step with automation and implement best practices. We can go from asking “How do we bring in automation?” and start to think in terms of “What are the use cases when I do?” A winning incident response toolset will help customers navigate this challenge. An automation platform should also allow users to fine-tune workflows with a library of connectors and actions that are comprehensive enough to get the job done. Ideally, your cloud stack should include several functions such as alerting (such as PagerDuty), monitoring (like Datadog) and analytics (Splunk, for example), while integrating with collaboration tools like Slack and Jira.

    What Are Some Typical Use Cases?

    Let’s dive deeper into three use cases that incident responders and engineers commonly encounter. These examples demonstrate why a powerful automated platform lets small businesses automate effectively and ensure long-term uptime just like larger enterprises.

    Incident Response Automation

    It’s all hands on deck when that 2:00 a.m. incident response alert goes off. Why rely on manual responses which can often lead to broken uptime SLAs and even drag down a company’s reputation? Automation is the key to operating any large-scale service in the cloud.

    Cost Management

    The costs of extended periods of downtime don’t stop at the checkbook. When incidents occur without drag-and-drop automation, long-term side effects can dramatically up the company’s losses.

    Orchestration

    Orchestrated automation tools provide credential management, templates, playbooks and data processing for any company size. They empower users to curate services to their liking as well.

    Want to Learn More about Automated Incident Response? 

    Sign up for this upcoming staging-devopsy.kinsta.cloud webinar on Monday, October 25th at 3:oo p.m. Eastern. We hope you’ll join us to learn more about how to integrate automation into your workflow and stop those pesky 2:00 a.m. wake-up calls.