Category: DevOps Toolbox

  • CA, IBM Partner to Drive DevOps on the Mainframe

    CA, IBM Partner to Drive DevOps on the Mainframe

    CA Technologies and IBM announced today at the Built to Change Summit they are combining their tools and platforms to bring DevOps process to mainframe environments.

    The two companies are extending their existing relationship to include a partnership to jointly develop and sell new services for IBM’s Cloud Managed Services on z Systems (zCloud). Included in that effort is CA Brightside, a platform for bringing DevOps processes to mainframes using existing open source tools and frameworks such as Jenkins, Gradle and IntelliJ via a command line interface and CA Mainframe Resource Intelligence, a software-as-a-service (SaaS) application for monitoring consumption of mainframe resources.

    Other managed services will be based on CA Service Virtualization software for rapidly testing and modifying applications in place; CA Mainframe Operational Intelligence to monitor applications; and CA Data Content Discovery to find, classify and protect data.

    The services are available today to all IBM Managed Cloud Services for z Systems clients in North America and will then be rolled out globally throughout the rest of 2018.

    Greg Lotko, general manager for mainframe at CA Technologies, said that although CA Technologies competes with IBM when it comes mainframe software, it has a vested interest in making sure mainframes stay relevant at a time when organizations are looking to replace less agile forms of application development that use waterfall and ITIL processes with DevOps methodologies that speed application development. From a practical perspective, end customers are demanding that CA Technologies and IBM work more closely together, he said.

    Barry Becker, vice president of hybrid cloud services for IBM, added that as the line between mainframes and distributed applications continues to blur, it’s clear organizations want to be able to treat mainframes as back-end platforms that make a wide variety of enterprise data available to those applications. That need is driving many those organizations to extend DevOps processes to mainframes.

    Historically, competition for control over application workloads within internal IT organizations between mainframe advocates and proponents of distributed computing  has tended to be fierce. But Becker said that as digital business transformation gains traction, there’s now a greater appreciation for the need to leverage transaction processing and big data applications that are widely deployed on mainframes. Not only is it not practical to rewrite all those applications, he noted, applications running on mainframes are more secure. The creates the need to extend out to the mainframe the DevOps processes that are being used to build distributed applications, he said.

    Zealotry that tends to focus on the merits of one platform above all others is usually counterproductive. The rise of DevOps presents organizations with an opportunity to bridge a divide within their organizations that, in some cases, is decades old. Of course, mainframe proponents are not likely to abandon waterfall and IT methodologies overnight. But DevOps processes can mainframe environments a lot more agile at a time when senior business and IT leaders are now judging the merits of one platform versus another increasingly on how flexible it allows the business to become.

    — Mike Vizard

  • Eggplant Extends Scope of AI Applied to Application Testing

    Eggplant Extends Scope of AI Applied to Application Testing

    Reliance on machine learning algorithms and other forms of artificial intelligence (AI) to not just run application tests at scale  but actually construct them may be about to increase.

    The latest release of a Digital Automation Intelligence (DAI) Suite from Eggplant enhances the AI capabilities baked into the testing tool to include the capture and analysis of runtime performance data in a way that enables a testing process to “learn” where potential bottlenecks are hidden. Eggplant CTO Antony Edwards said DAI Suite will then suggest a series of tests designed to make it easier for developers to identify the root cause of the problem.

    The goal is to reduce reliance on humans to construct formulaic tests, which Edwards said often limits the rate at which applications can be deployed and updated.

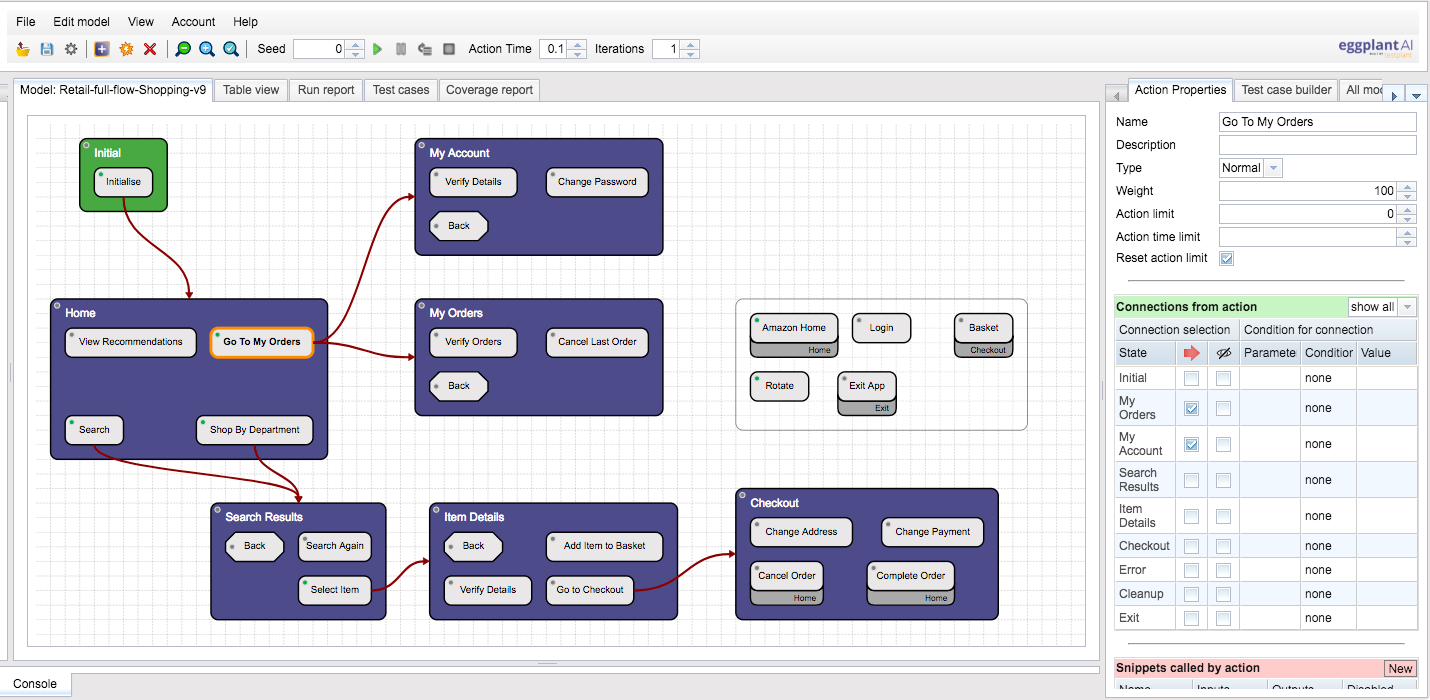
    Eggplant’s DAI Suite

    Other new capabilities being added to DAI Suite include enhancements to Eggplant Functional, which now takes advantage of AI to discover the elements of a graphical user interface (GUI) to automatically populate the automation logic in an Eggplant AI application model. Eggplant Performance, a load and performance testing product, has been integrated with JMeter, an open source performance testing framework, to enable developers and testers to reuse JMeter assets as well as creating load test scripts. Additionally, new real-time key performance indicators (KPIs) can be employed to shorten the feedback loop between testing and analysis.

    Both Eggplant Manager and Eggplant Automation Cloud are now 10 times faster and provide higher levels of testing scalability, according to the company.

    Edwards noted that, in general, application testing is too formulaic. The end goal should be on identifying the best way to delight an end user rather than merely trying to check a compliance box. That requires being able to test more application use cases at scale without slowing down the overall application development life cycle. In fact, he said the biggest hindrance to DevOps today is a reliance on manual testing processes that are driving a $32 billion testing services sector.

    It’s now only a matter of time before AI is applied more broadly to application testing. As the number of applications being developed increases, the more challenging testing becomes. The longer it takes to conduct those tests the more tempted developers are to short-shrift the testing process altogether, believing whatever issues that might arise can be addressed quickly using agile development methodologies. However, not only are there more dependencies than ever between applications, but also end users are less forgiving. Many of them will not, for example, ever give a mobile application that initially disappoints them a second look. Compounding that pressure is increased reliance on digital business processes, where the quality of the underlying application experience directly correlates to the perception of the value of the corporate brand.

    Developers may not always have the highest regard for application testing. But as IT continues to evolve, chances are high there soon will be many more developers perfectly happy to take advantage of all the AI help they can get.

    — Mike Vizard

  • ChefConf 2018: Chef Grows Beyond Infrastructure to Apps

    ChefConf 2018: Chef Grows Beyond Infrastructure to Apps

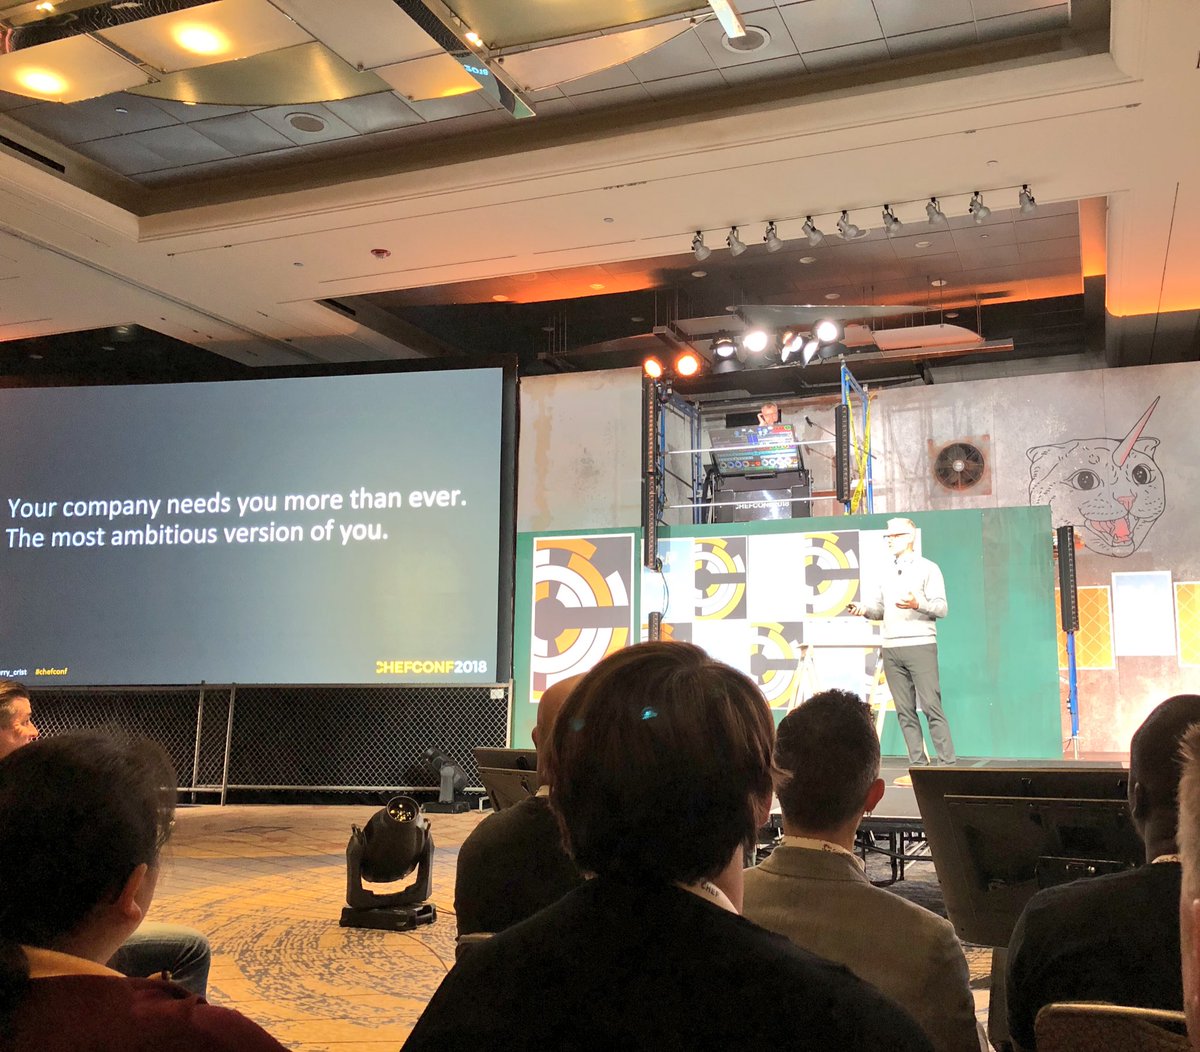
    chefconf keynoteHere I am in Chicagoland for my third ChefConf. I caught the keynotes today with Nathan Harvey, Barry Crist, Adam Jacob, Corie Scobie and more. The big news at this year’s event is that Chef is focused on more than just infrastructure and compliance—Chef is bringing automation to apps and the entire software delivery life cycle.

    I spoke with Chef CEO Barry Crist about this and he said there is a sea change taking place with software is delivered. Chef has seen this wave coming and, over the last few years, has been retooling its offerings to match this. Today, Chef Automate and Chef Habitat represent the heart of Chef’s arsenal in its mission to offer the premier platform to automate the software development, deployment and security life cycle.

    I personally have seen this shift over the last few years. I think back to when we launched staging-devopsy.kinsta.cloud. Chef was already a popular solution within the DevOps community; however, most people will tell you that they used Chef for configuration management. It was great to be able to make sure that as you spun up new instances in the cloud, your infrastructure was configured exactly as you wanted. By automating and using a Chef-type of solution, you could spin up new instances at-will and their configuration would be exactly the same or exactly as you desired.

    At the time, that was pretty cutting-edge. People were writing Chef recipes for all kinds of tasks—again, usually around configuring infrastructure.  With the advent of microservices, containers, Docker and Kubernetes, this type of automated deployment has become commonplace. But the need to automate, especially with security and compliance and app deployment, is perhaps an even bigger mission.

    Crist acknowledged these facts during his keynote. In speaking about Habitat, Crist noted that not only did many of Chef’s customers not understand the real story behind Habitat, but that half of Chef’s own employees didn’t, either. One person who did was Julian Dunn, director of product marketing, who I interviewed on DevOps Chats about Habitat when it first launched. Tony Bradley wrote that it could be a game changer back then, as well.

    Habitat has come a long way since then and still has a ways to go to grow into its ambitious potential, but it is very functional right now. Chef has several clients here at ChefConf talking about their Habitat deployments and plans. Chef now tags Habitat with Automate Any App Anywhere – Build, Deploy, Manage.

    Perhaps further along than Habitat, however, is Chef Automate. In fact, Chef Automate 2.0 was announced ChefConf, and it seems to be an almost complete rewrite of the program, as it is now built on Microsoft Go. Here is Chef’s take on Automate 2.0:

    Chef Automate has been rebuilt from the ground up to provide performance, scale and advanced analytics required by enterprises using DevOps at scale to meet the demands of post-digital transformation. Chef Automate now provides a single control plane for infrastructure and compliance automation to enable a closed-loop ‘detect, correct, automate’ process to make infrastructure effortless.

    New features include:

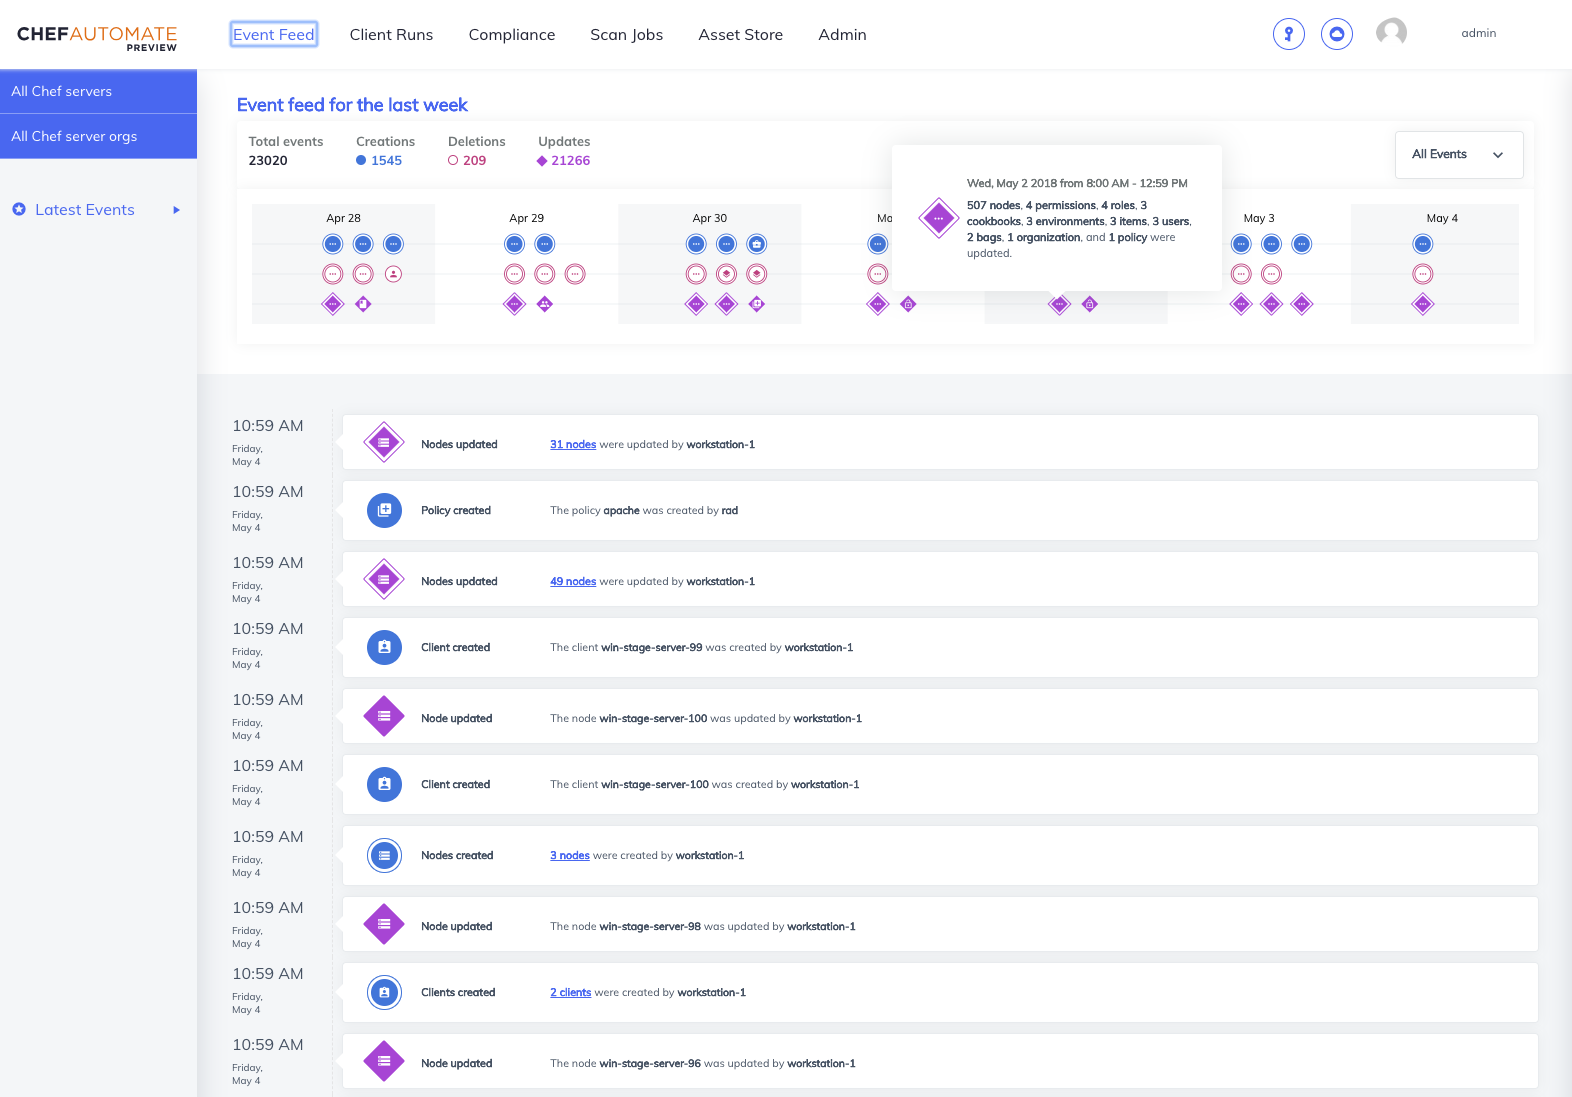
    • Enhanced operational visibility and debugging – New tools and visualizations, including a streaming event feed, trend graphs and a rich query language, help users analyze infrastructure and compliance automation data from a unified dashboard.
    • Compliance scanning and reporting in any environment – Integration with cloud compliance capabilities of InSpec 2 enhances scanning, which can now be used to evaluate cloud configurations (AWS, Azure, Google Cloud) via APIs for compliance on either an ad-hoc or ongoing basis. Chef Automate 2 also supports scanning of Cisco IOS equipment as a significant start on extending modern compliance capabilities to network devices.
    • Re-architected for speed and flexibility – A Go-based microservices architecture, with a modern, performant web UI atop a REST API, enables Automate 2 to support tens of thousands of nodes from a single installation. In-place upgrades with automatic data migration from Chef Automate 1 ensure that customers retain all historical information.

    Additionally, Chef has released something called Chef Workstation. From the release:

    Chef Workstation enables DevOps teams and practitioners to complete ad-hoc DevOps tasks using all of the familiar Chef capabilities, without agents. This provides a simple and effective way to use Chef to complete tasks and then seamlessly scale those tasks through Chef Automate.

    Capabilities include:

    • New standard desktop/laptop experience for Chef – Includes a new ‘target mode’ for executing Chef recipes or entire cookbooks remotely and Introduces ‘chef’ command as the single point of entry.
    • Foundation for a better workstation experience – Bundling all the tooling previously included in the ChefDK provides an improved user experience and cohesion between tools to deliver a seamless experience for any infrastructure automation task.

    Finally, new enhancements to Inspec, Chef’s compliance and security solution, were announced. Besides security and compliance being built into most everything Chef does, Inspec now sports:

    • Cloud configuration compliance – Verify AWS and Microsoft Azure policies, with Google Cloud Platform support in beta. More than 10 new AWS resources bring it to CIS Level 1 benchmark completeness.
    • Improved out-of-the-box experience – More than 30 new resources, including support for Cisco IOS network devices as agentless targets, are built in.
    • Drastically improved performance – Users now see up to 90 percent performance gains on Windows and 30 percent on Linux/Unix.

    I will report more as it comes here in Chicago and ChefConf 2018.

    — Alan Shimel

  • Chef Embraces Microservices to Advance IT Automation

    Chef Embraces Microservices to Advance IT Automation

    Chef at the ChefConf 2018 conference today unveiled a series of DevOps offerings, including a revamped version of Chef Automate that has been rewritten using the Go programing language to improve performance and scalability. Now based on a microservices architecture, Chef Automate 2.0 a new user interface based on a REST application programming interface (API) that also serves to enhance integration. There also are a variety of visibility and debugging tools built into the platform, including a streaming event feed, trend graphs and a query language.

    Chef Automate

    At the same time, Chef unveiled Chef Workstation, which enables members of a DevOps team to take advantage of IT automation capabilities on a local PC without having to load any agents.

    Chef also updated its Habitat application release management software to include support for Kubernetes Operator for Habitat and the Open Service Broker originally developed by the Cloud Foundry Foundation, the ability to export to Azure Container Service (AKS), a Helm chart exporter for Kubernetes clusters and integration with operational analytics software from Splunk. Habitat also is now available in an on-premises edition as well as as a software-as-service (SaaS) application.

    Finally, Chef updated InSpec, the company’s compliance automation tool. The latest version can now verify Amazon Web Services (AWS) and Microsoft Azure policies, while support for the Google Cloud Platform support is in beta. InSpec also now has built-in support for more than 30 new resources, including Cisco IOS network devices as agentless targets.

    Chef is touting InSpec performance gains of 90 percent on Windows and 30 percent on Linux systems.

    Julian Dunn, director of product marketing for Chef, said as more companies transition to emerging technologies such as containers and Kubernetes, the need to rely on IT automation frameworks increases. In fact, while container use is widespread, more than half (51 percent) of 347 application and operations professionals surveyed by Dimensional Research on behalf of Chef said they have fewer than 10 percent of their production applications deployed using containers. Dunn said that survey also finds that adoption of DevOps practices in general are still limited—just over half the respondents (53 percent) said they are using both infrastructure and app automation for DevOps.

    However, 46 percent survey respondents said by 2020 they will have more than a quarter of their applications containerized, while 45 percent said at least a quarter of their application deployments will be based on microservices. That accelerated rate of transition will require IT organizations to rely more on IT automation frameworks to implement DevOps processes, Dunn noted.

    Further complication matters, Dunn said organizations are trying to lift and shift existing applications into multiple public clouds while continuing to develop new applications faster than ever to drive various digital business transformation initiatives.

    There’s no doubt that IT organizations are relying more on IT automation frameworks more than ever. The question is, Which one will they use? There are now more IT automation framework choices than ever. Chef is betting that a comprehensive approach based on a modern microservices architecture spanning both IT management and compliance ultimately will win the day.

    — Mike Vizard

  • Functional Programming: Island of Misfit Functional Programming

    Functional Programming: Island of Misfit Functional Programming

    The age of functional programming is dawning. The hype cycle has heated up, and IT departments are getting both real and perceived benefits out of the idea that a function runs on demand only.

    For some, the benefits are very real. Bursty processing, or things that are frequent and quickly resolved, see a benefit from being implemented on functional architectures, and the cost of functional architectures is arguably far better than the cost of cloud instances. I say “arguably” because you can always cram more onto an underused cloud instance, but you pay as you go—even more literally for functional programming, so additions each have an incremental cost. But it is incremental, and you have the power to choose whether functional is right for any given bit of the architecture.

    So why the title? Remember The Island of Misfit Toys from the much-beloved Christmas story, “Rudolph the Red Nosed Reindeer”? They were all just a little off. In a world flooded with perfectly good toys, they were left unattended and unwanted.

    That is a risk functional runs in the long run, also. The idea that you can pop a function out there, configure the access point (almost ubiquitously a web application firewall entry point, but things change so we’ll stick with the generic “entry point”), and start sending requests is great. The fact that you only pay for that bit of time when your request is actually being serviced is great, too.

    But this ideas assumes security is baked in at the functional level. If you are deploying this function anywhere with a public IP, it assumes hardcore security is baked in.

    And failure to have that security baked in is the first reason you might have a misfit toy.

    By definition, functional programming-based systems are complex systems. They are the ultimate evolution of microservices. They will suffer all of the headaches and heartaches associated with SOA and add on the issues with REST versioning, etc. There will be 50 or 500 functions, each clipping along and doing its thing, composed to make a single application (in a purist world, composed in a functional programming app).

    Some of these functions will become outdated and unused. You can’t leave them laying around, waiting to be abused. Indeed, a new form of financial attack might be to look for just such abandoned toys and start calling them repeatedly and rapidly.

    Imagine coming in one day and having Finance ask you why your bill at functional provider X tripled in the last month, only to find a function you left hanging around was being called for no good reason?

    But the complexity inherent in lots of small bits of code, each doing a specific task, pretty much guarantees there will be cruft left lying around unless you are very careful.

    And that, my friends, is (finally, I know) the point of this blog. Our monitoring tools today lean toward watching the performance of the application, but you need more than that before you go all-in on functional programming. You need build tools that can tell you when a given function is no longer called—from anywhere. That is a tall order which none of the previous distributed methodologies has managed to master, but it is more important in a world where you have functions sitting in various public clouds with public-facing IP addresses.

    There also needs to be a definitive source code scanner. Those are slowly getting better, but imagine if a library the build system pulls in and uses for 20 or 30 different functional programming microbits becomes compromised? We’ve seen enough instances of ignoring the problem is begging to be a victim, so scanning on build is more important with more systems using external libraries. Or more accurately, with external libraries being pulled into more microservices. There are companies/service providers that will validate your external dependencies and only let you load open source libraries they have certified as safe. I’ve never used one, but they’re worth looking into.

    A list of entry points and places they are accessed from is useful for internal-only applications. You can’t do that with a publicly exposed REST API that anyone can call, of course. I’m a developer and a D&D player, so I’ll use that example: Wizards/Hasbro cannot control where this API is being called from. The same is true for any web services APIs that exist to give others access. But internal APIs that are an integral part of internal systems and not called externally? Those you need an automated way to find references to them in internal source and keep a count. Much like garbage collection, you’ll want to take down ones whose count reaches zero.

    The thing is that in many ways functional programming reduces operational complexity. It certainly reduces operational overhead. But that complexity is replaced with a different kind of operational complexity; maintenance becomes a bigger issue, and the already occurring breakup of code into smaller chunks increases, bringing cross-reference complexity along with it.

    Keep that in mind. You will have orphaned functions, you will have security concerns, you will have changed operational complexity. Plan for these things from day one. They are not at all deal breakers, and the benefits of functional are already clear in certain verticals with more general benefits being discovered as I type. But they’re the new problems that will require answers in this new architecture.

    So, build in oversight and tools from the beginning and go see how functional programming could benefit your project. At this time, it isn’t the answer to every problem, but—like most cool new IT things—it is another tool to have at hand when solving problems for the business.

    And don’t let your functional programming microservices end up on the Island of Misfit Functional Programming.

    — Don Macvittie

  • AppDynamics Taps into SAP Applications

    AppDynamics Taps into SAP Applications

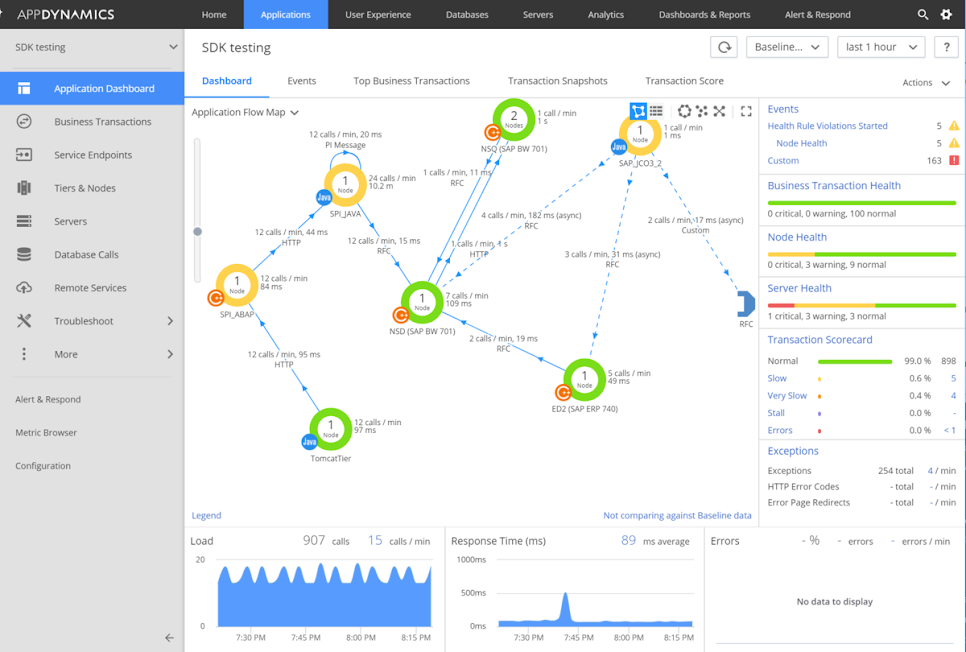
    Application performance management (APM) is starting to be  employed more widely as more organizations embrace digital business transformation. As the number of digital business processes spanning multiple applications increases, so does the need to understand what’s occurring inside both greenfield and legacy applications. In fact, at the heart of many of those digital business processes are enterprise resource planning (ERP) and customer relationship management (CRM) applications from SAP. To make it possible to gain insights into those applications AppDynamics, a unit of Cisco Systems, announced today it is making available AppDynamics for SAP.

    Jonah Kowall, vice president of market development and insights at AppDynamics, said his company is now able to support ABAP, the proprietary language SAP developed to build its applications. That language also has been employed extensively by IT organizations to customize those applications.

    SAP currently is trying to transition its customers to building custom applications on a cloud framework based on the Cloud Foundry platform-as-a-service (PaaS) environment. Most of those applications are be written in Java or the new Jakarta platform that replaces Java. SAP has also provided a software development kit and application programming interfaces (APIs) for tapping into S/4 HANA ERP applications.

    But there is a massive installed based of ABAP applications running in enterprise IT environments. Much of that code is now being integrated with other applications as part of a larger digital business transformation initiative.

    Kowall said those extensions are now driving organizations to apply an agent for the AppDynamics APM to custom applications written in ABAP. Historically, enterprise IT organizations only applied APM to their most critical applications. But as organizations move to digitize business processes, they now need to able to track transactions spanning multiple applications. Given the reliance many organizations have on SAP applications, it’s inevitable those transactions will involve SAP applications that were customized using ABAP.

    In addition, Kowall noted that being able to discover precisely where those custom applications are involved in any transaction is pivotal when it comes to upgrading to the SAP S/4 HANA applications, which are based on the SAP in-memory database, or lifting and shifting a legacy SAP application into the cloud.

    Kowall said organizations that have used ABAP to customize SAP applications now will have visibility down to the code level, including queries being made to the underlying database. From a DevOps perspective, that capability will go a long way to breaking down yet another silo in the enterprise. AppDynamics expects the first order of business for many organizations will be simply to create a performance baseline for their ABAP applications, which in many cases are likely to be an eye-opening experience, he said.

    The focus on digital business transformation is likely to spur adoption of DevOps processes over a much broader swath of the enterprise. Rather than simply apply DevOps processes to new applications, many organizations soon will extend DevOps into the realm of legacy application environments as well. That may take some time to play out, given the scope of the cultural changes involved. But at this point, those changes are now all but inevitable.

    — Mike Vizard

  • The Past, Present and Future of DevOps Infrastructure

    The Past, Present and Future of DevOps Infrastructure

    Infrastructure automation enables organizations to set up operating frameworks that allow smooth functionality with enhanced usage, minimal scope for error and faster deployment of code. The process of infrastructure automation eases development and operations processes by introducing good deployment practices such as computerized testing and versioning.

    The need for automation was realized when the demand for deploying error-free applications at a faster rate increased. Additionally, competition from similar businesses forced organizations to look for a way to bridge the gaps between development and operations to deploy applications that would serve their business needs.

    The Challenge of Implementing DevOps Practice

    The following challenges present a roadblock in bringing out the best results of DevOps practices:

    1. The disparate work cultures of the development and operations teams.
    2. Non-involvement of DBAs in release cycles.
    3. Failure in deployment of error-free codes.

    The Emergence of DevOps

    The introduction of DevOps practices resolved a lot of problems in terms of increasing business operations efficiency. It created a common operating framework where disparate teams including development and operations teams can work together and deliver applications faster that will, in turn, result in effective business operations and an increase in ROI.

    Adopting DevOps involves:

    1. DevOps experts outlining of traceable metrics for creating a roadmap by visualizing the desired outcome.
    2. Creating a pilot framework that will include the tools of both development and operations teams further integrating these existing tools with the DevOps experts’ robust ecosystem,
    3. Analyzing, designing, constructing, automating and implementing the network based on the metrics and resources collated.

    DevOps Tools:

    The DevOps infrastructure automation process uses several tools that define and drive the success of the implementation process. Here is a short overview of some of the more well-known and widely used tools.

    • Jenkins – A Java-based continuous integration (CI) tool contributes to the faster delivery of applications. Jenkins must be aligned with a version control system such as GitHub or SVN. Whenever the code repository receives a new code, a Jenkins server builds and tests the new code and informs the team about results and any changes. Over time, Jenkins has moved from being just a CI tool to being used as an orchestration tool that builds pipelines for application provisioning and deployment.
    • Chef – A ruby-based configuration management tool, Chef includes cookbooks that code infrastructure in domain service language (DSL) in combination with a little bit of programming. Chef creates virtual machines and customizes them in accordance with the rules listed in the cookbooks. An agent residing on all the servers that need configuration extracts the cookbooks from the chef master and runs them on the server to get the desired results.
    • Puppet – Also, a ruby-based configuration management tool, Puppet was developed with system administrators in mind. A configuration code is written using Puppet DSLs and is wrapped in modules. Puppet performs a similar function to Chef but, unlike Puppet, Chef is a developer-focused tool. It runs a puppet agent on all servers that require configuration and extracts the compiled module from the puppet server and installs required software packages as prescribed by the module.
    • Ansible – An agentless configuration management and orchestration tool, Ansible can be used for cloud computing. Ansible has configuration modules called “Playbooks,” which are written in YAML format and are easy to compose in comparison with other configuration management tools.
    • Docker – Docker, a process-level virtualization tool, creates isolated environments for applications known as containers. These containers can be transferred to any other system without making any application changes. Docker has evolved as the next step in virtualization. It is beginning to become a favorite of many DevOps practitioners and leading cloud experts.

    The Future of DevOps Infrastructure Automation

    A lot of organizations are beginning to benefit from the implementation of DevOps infrastructure automation. And with the pace at which the demand for DevOps services is increasing, infrastructure automation has a long way to go.

    As per statistics, by bringing DevOps practices into the picture, organizations can benefit by deploying code up to 30X more frequently and reduce the deployment failure to less than 50 percent.

    — Veritis

  • More App Dev Models Increase DevOps Pressure

    More App Dev Models Increase DevOps Pressure

    A bifurcation in types of developers will become more pronounced in the years ahead as more application code moves to the network edge. As that transition continues occurring, the pressure on IT operations to be able to be able to flexibly manage different classes of applications by embracing DevOps processes will correspondingly increase.

    Mike Piech, vice president and general manager of middleware for Red Hat, said applications running on internet of things (IoT) devices and smartphones present developers with a finite amount of compute resources that require them to have advanced skills. Conversely, back-end applications can now take advantage of multiple layers of abstraction, including (soon) serverless computing frameworks based on event-driven architectures that make potentially unlimited compute resources available. The availability of all those compute resources, however, encourages developers of back-end services and applications to be less disciplined when writing applications.

    The good news is that it’s getting easier to right-size applications using trial and error methods versus having to commit to a specific computing architecture up front, said Piech. If something doesn’t work as well as it should, modular approaches to microservices make it possible to more easily move application code to where it should best optimally reside. Rather than focusing on the rigor of the underlying architecture, developers are free to experiment with different tools and languages more now than any time in the history of IT, he said.

    In fact, Piech speculated that many graphical user interfaces will continue to run locally while accessing a wide variety of back-end services via application programming interfaces (APIs). That approach essentially creates a new form of hybrid computing wherein developers no longer need to think much about the runtime environment, he noted.

    However, all that freedom tends to put a lot more pressure on the IT operations team. As the types and classes of applications continues to evolve, Piech said it’s only a matter of time before more organizations move further down the DevOps path. Adoption of DevOps processes across organizations has been somewhat uneven. But as developers experiment with different computing models, the expectation is that operating teams will be flexible enough to dynamically make the appropriate adjustments, he said.

    Longer term, middleware and databases will eventually be deconstructed into sets of microservices that developers can call when needed. Today, IT operations teams make available monolithic application servers and databases. Many of those databases and application servers are starting to be encapsulated in Docker containers as part of a first step toward lifting and shifting applications into the cloud before transitioning to more agile microservices-based frameworks, Piech said.

    In some cases, those services will be accessed directly via a platform-as-a-service (PaaS) environment or a serverless computing framework. Piech said Red Hat expects serverless computing frameworks based on event-driven architectures will be used mainly to provide bursting capabilities as a complement to long-running stateful applications that typically consume a fixed amount of IT infrastructure resources. It’s probable stateless applications that run intermittently also will find their way on to serverless computing frameworks. Red Hat has thrown its support behind the open source OpenWhisk serverless computing framework.

    There clearly will be many more types of distributed applications running across the enterprise. IT operations teams may not have much control over what types of applications run where and when. But they will be expected to be able to deploy and manage them all, regardless.

    — Mike Vizard

  • From One-Size-Fits-All to Custom-Fit for IT Ops

    From One-Size-Fits-All to Custom-Fit for IT Ops

    The downfall of the all-in-one IT management suite and the rise of the customized IT Ops toolchain

    Here is how enterprise IT Ops used to work: you would make your choice among the Big Four vendors and buy in (quite literally!) to their strategy. This meant a suite of products that came preintegrated (more or less) out of the box, and—at least on the sales proposal—covered all of an IT organization’s needs across a huge spectrum of activities.

    selection of tools hanging ready to use
    Photo by Barn Images on Unsplash

    Broadly speaking, each of the Big Four’s suites included some flavor of the following: monitoring, ticketing, configuration management and asset tracking and automation and orchestration. Some vendors were stronger in one area than in another, but unless you had pretty specific needs, each vendor could be your one-stop shop.

    Development and improvement inside these suites was mainly incremental and occurred at a fairly leisurely pace. Meanwhile, startups with bright ideas would come along occasionally and challenge the incumbents in specific areas, only to be bought by one of the mega-vendors if they showed enough promise.

    There was a symbiotic relationship between vendor and IT buyer, as IT professionals built decades-long careers as experts in this or that vendor’s technology stack, with the wall of framed certifications to prove it. CIOs were reassured by the fact that there was a readily available pool of experts to hire, and continued reinvesting in the next iteration of their chosen vendor’s stack.

    The Old Model No Longer Fits Modern IT

    In the last decade or so, this comfortable status quo has broken down. The cracks were already showing before then, but only the most agile and forward-thinking organizations were moving fast enough to trip over them. As more and more businesses began to expect greater and greater responsiveness and speed from their IT departments, the huge sprawling suites of the mega-vendors were no longer able to keep up with the required rate of change. Leisurely 18-month release cycles no longer cut it in an agile world, where that time span may encompass several entire strategies.

    In the old world, to call something “best of breed” was a sniffy dismissal of a one-trick pony, as opposed to the more supposedly versatile offerings of the Big Four. In the new world, it became obvious that aside from a handful of tentpole products that were genuinely good and fit for purpose, most of the individual components of the big suites was distinctly unexciting. Worse, the main value proposition of the suites—that they came preintegrated out of the box—started to break down as well. Many IT professionals were still fiercely loyal to individual products, but they became more willing to pick and choose, rather than buying into the whole vision.

    In parallel, the rise of simple integrations—primarily REST APIs—made it easier than ever before to connect disparate solutions together into a single IT Ops toolchain. Worse (from the point of view of the incumbent vendors), sometimes it was easier to connect modern point solutions than their own component pieces, weighted down by the baggage of decades on the market.

    How to Deliver the Flexibility and Agility the Business Expects?

    These days, it is becoming commonly accepted even among the most staid and risk-averse organizations that the way to go is no longer to align to a single IT vendor and trust them to deliver on their vision, but rather to design custom-fit, multisolution toolchains, including home-grown, open source and commercial tools.

    agile jump
    Photo by Max Bender on Unsplash

    But what to do if you find yourself dealing with the consequences of this sort of IT monoculture?

    Look Back At How You Got Here

    The first step is to re-evaluate past buying decisions and strategic alignment. It is very important to do this without assigning blame; it was a different time, and those choices may well have been the right ones for the prevailing environment at the time, when integration between tools from different vendors was legitimately difficult.

    Don’t Just Throw Everything Out

    In many environments, too, the correct solution may well not be a clean sweep. One or more of those tentpole products that kept the overall suite looking good past its sell-by date may well still be perfectly fit for purpose and not worth the hassle of swapping out. However, other components are probably legitimately lagging behind the state of the art, in which case it is worth replacing them with something more fit for purpose.

    Count Costs – All Costs

    Include cost in these calculations, but remember to include all costs. Maybe you or a predecessor signed a big enterprise license agreement (ELA), so Product X is “free” in that context. But what does it cost to keep Product X running, in terms of ancillary licenses, hardware requirements and, last but not least, skill and effort on the part of the IT administrators? I don’t want to name specific products or vendors as examples, to avoid the discussion devolving into particulars, but it’s worth bearing in mind that many legacy products have shallow talent pools—not that many people are available on the market, and many of those people are coming to the ends of their careers, which makes them both expensive and reluctant to change employers. Instead, up-and-coming technologies often have much deeper and wider talent pools, with many more experienced specialists available at all salary and skill levels. If you don’t believe me, try hiring half a dozen COBOL programmers and half a dozen Node.js coders, and then we’ll talk …

    IT Ops hard at work
    Photo by Giu Vicente on Unsplash

    Your IT Ops Toolchain, For Your IT Ops Needs

    Moving from one of the big all-in-one suites to an assemblage of different tools, all flying in loose formation, is not easily done. Any technology transition of this sort is a Project with a capital P, and needs to be planned and managed with due care and attention. However, there is a large payoff at the end in terms of increased agility and flexibility within IT Ops. In turn, this affords IT the ability to offer their business counterparts the sort of responsive and even proactive IT support that moves IT from being a cost center, on a par with Facilities, to a strategic differentiator that enables new business initiatives.

    Business as usual doesn’t cut it any more, and assumptions that used to be valid have fallen apart. Decisions based on those assumptions need to be re-evaluated. New, more flexible approaches will set up IT Ops for success in the newly flexible world we are already living in.

    — Dominic Wellington

  • Red Hat Aims to Push IT Management to the Cloud

    Red Hat Aims to Push IT Management to the Cloud

    Red Hat at the Red Hat Summit 2018 conference this week showed a technology preview of an instance of Red Hat Insights, a predictive analytics IT management application capable of identifying operations issues before they become a problem, running as a software-as-a-service (SaaS) application.

    The instance of Red Hat Insights will be extended to apply analytics to any infrastructure platform. Red Hat plans to eventually make the rest of its IT management portfolio available as a cloud service.

    Joe Fitzgerald, vice president and general manager for management at Red Hat, said the goal is to enable management of virtual machines, container, infrastructure-as-a-service and physical servers all from a single pane of glass.

    Cost analytics also will be embedded in those services, adds Fitzgerald. Cost is now a much bigger issue because cloud service providers bill customers based on actual consumption. Previously, a virtual machine left running on an on-premises server might result in someone being yelled at, but no additional cost, notes Fitzgerald. Now, however, if an IT organization doesn’t turn off those virtual machines, it will end up paying more.

    Fitzgerald noted that management of IT operations is becoming increasingly automated. Red Hat is now adding integrations with the agentless Ansible framework it acquired in 2015 at rate of 50 a week. There already  are 1,600 integrations with Ansible. He said the fact that Ansible presents IT operations teams with a declarative approach to automating IT using YAML files makes IT automation much more accessible. Other frameworks require IT operations teams to learn how to program, which becomes a significant barrier to adoption, but YAML files allow IT operations teams to make use of familiar shell scripts.

    Many organizations now are moving up the IT management curve as applications become more distributed, Fitzgerald said. Every platform they have comes with its own management tools. But the need for a control plane through which multiple platforms can be centrally managed is now becoming more evident, he said, especially as IT organizations realize they will be running many different types of platforms for many years to come.

    Other benefits to shifting IT management into the cloud is that the move eliminates the need to deploy a local server just to run IT management software and all updates to the IT management platform are provided by the applications provider.

    Obviously, Red Hat is not the only IT vendor building a centralized, cloud-based approach to managing distributed computing environments. But as Ansible becomes more widely adopted, the opportunity arises for Red Hat to engage in a broader IT management conversation with IT organizations.

    Most enterprise IT organizations are rapidly approaching something of an IT management crisis. Each platform adopted creates yet another silo that makes adopting integrated DevOps processes even more challenging. While most organizations are not likely to abandon the management tools from the vendors that built those platforms, IT organizations are demanding thet underlying infrastructure exposes an application programming interface (API). In fact, it’s the proliferation of all that software-defined infrastructure that now makes it feasible to centralize the management of IT in the cloud.

    — Mike Vizard