Category: DevOps Toolbox

  • How to Implement an Effective CI/CD Pipeline

    How to Implement an Effective CI/CD Pipeline

    DevOps bridges the gap between development, operations and IT services teams efficiently. To foster a DevOps culture, implementing the right DevOps tools with the right DevOps process is essential. Continuous integration/continuous delivery/continuous deployment (CI/CD/CD) help developers and testers ship the software faster and safer in a structured environment.

    Unlike the traditional software life cycle, the CI/CD implementation process gives a weekly or daily update instead of monthly or quarterly. The fun part is customers won’t even realize the update is in their applications, as they happen on the fly.

    A Brief Insight About CI/CD/CD Terminology

    • Continuous Integration: CI is a process in which developers integrate new codes into a shared repository several times a day. This is a better approach than the traditional one, where the developer will build new codes in isolation and then integrate into the main repository at the end of the project lifecycle. The primary goal is to detect any integration bugs at the initial stage so it can be rectified quickly. It triggers a new build whenever a new code merges with the existing main repository. Test runs are performed against these new builds to check for any breakage.
    • Continuous Delivery: At the end of the CI, CD comes in. CD ensures to automate the software delivery process and commits to deliver the integrated code into the production stage without any bugs or delay. CD in the DevOps implementation process, helps developers merge the new code with the main branch consistently so they can build an instant software-ready product. It is responsible for checking the quality of the code and performs tests to check whether it can release the functional build to the production environment.
    • Continuous Deployment: The most critical part of the automation occurs at this stage of the delivery pipeline. Whenever there is an important change in the code, the corresponding build and deployment occur simultaneously. It is achieved through continuous deployment process where it allows to perform live deployment changes for every code modification that passes through the CI stage. During this stage, there is no manual intervention right from the initial code until the code is in the production stage.

    Benefits for Implementing CI/CD

    The ultimate aim for any software application is to reach its potential customers faster than ever before. This is exactly what the CI/CD pipeline offers to any business model that leverages a software process which reduces the risks in each build and helps the end product to reach the customer quicker.

    • Achieve Faster Feedback Through CI Tools: For every committed code, the corresponding tests are run simultaneously to avoid any link breakage at later stages. Faster feedback helps to check the quality and impact of the code.
    • Greater Visibility: With CI/CD pipeline setup, the whole process of new builds, test results and any issues with new builds can be analyzed. This transparency allows the developers to know which changes in the build led to the brokerage and to avoid them in the future.
    • Early Bug detects: Conducting various types of automated testing allows to identify any bug issues at an early stage without any last minute surprises. These automated tests along with few manual test runs, help to fix any issues that may arise.

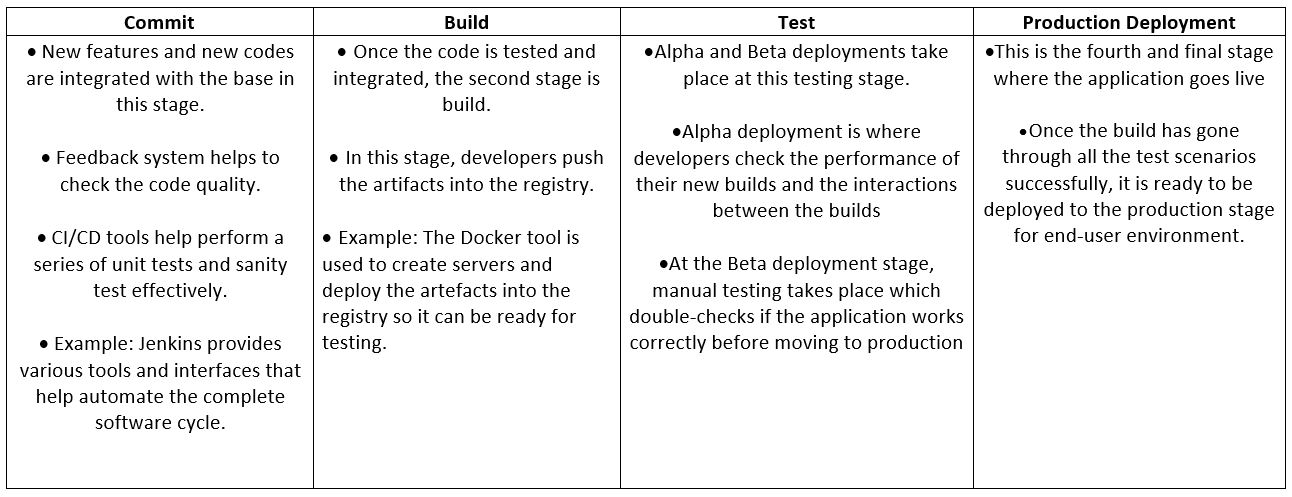
    The Different Stages of CI/CD Pipeline Implementation

    To get the full benefits of the modern DevOps environment, embarking on a scalable CI/CD DevOps implementation is important. It lays a strong foundation for building an agile DevOps for your business.
    Tools for the CI/CD Process

    Tools are the magic wand that help automate a successful CI/CD pipeline and ensure a faster software delivery.

    • Open-Source Tools or Proprietary: Depending upon the budget and the client’s requirement, business can opt for open-source tools such as Jenkins for automating the CI/CD process.
    • Cloud or Self-Hosting Services: To self-host your CI/CD application, tools such as Jenkins and Cruise Control help to setup, configure and monitor the application effectively. Otherwise, you can get SaaS providers to host on cloud services.
    • Build Status: Choose a tool which embraces the transparency and visibility of the entire process through appropriate notifications, through email or other type of communication.

    Possible Challenges of CI

    • You might need a discipline strategy to address an issue by the CI/CD pipeline, otherwise the whole fast feedback is in vain. 
    • Slower builds eventually take place as newer builds keep adding to the product.
    • Failure to train the resources to adapt to new tools and patterns.

    Wrapping Up

    In this era of faster software shipping and building quick releases on the fly, adopting a more robust project cycle that accelerates the delivery pipeline is crucial. Implementing DevOps services is the optimal way to get the effective collaboration between cross-functional teams through the CI/CD process.
    — Jay Elango

  • Render Taps Manifold to Expand Cloud Services for Developers

    Render Taps Manifold to Expand Cloud Services for Developers

    The rate at which DevOps teams that rely on cloud services from Render will be able to discover new tools is about to increase significantly, thanks to Render’s new alliance with Manifold, a provider of a marketplace-as-a-service platform.

    Render already offers logging, monitoring and other DevOps tools, and will use the Manifold technology to create its own marketplace. Render CEO Anurag Goel said the partnership will provide his company with a platform that enables instant access without having to navigate as many configuration steps because Manifold has automated those processes.

    Goel said Render has been growing at a rate of 50% per month by focusing on the needs of developers, a strategy that has resulted in more than 100 million http requests a week on the Render platform. That approach has allowed the company to differentiate its cloud platform from much larger rivals such as Amazon Web Services, Microsoft Azure and Google Cloud Platform, which are not as focused on the developer experience, he said.

    Manifold CEO Jevon MacDonald said Manifold has focused its efforts on building a marketplace that allows smaller cloud service providers to offer tools and applications with a user experience that rivals any of the marketplaces provided by the big three cloud service providers but without having to build and maintain that marketplace themselves. Manifold also works with each provider of tools and applications on the marketplace to automate the configuration process, he said.

    Over time, marketplaces have proven to be critical for cloud service providers because they provide the foundation on which developer ecosystems are created. The easier a cloud service provider makes it for DevOps teams to discover new tools and applications, the larger that ecosystem tends to become.

    Obviously, AWS, Microsoft and Google have massive DevOps ecosystems in comparison to Render. However, with the rise of cloud-native platforms such as Kubernetes, it will become much easier for DevOps teams to build applications on one cloud platform and deploy them on another. To attract developers of cloud-native applications, Render has built a containerized platform as an alternative to legacy platform-as-a-service (PaaS) environment.

    Render is betting that cross-platform strategy for building applications becomes more commonplace, more developers will opt to build applications on cloud platforms specifically focused on providing a superior developer experience. Current Render customers include smaller startups such as 99designs, Gatsby and Indie Hackers by Stripe.

    As developers start to shift toward cloud-native technologies, it remains to be seen how many DevOps teams will be willing to consider alternative cloud platforms. The major cloud service providers have built business models around providing as little support as possible. While it may not be possible for cloud service providers to support each DevOps team with an expensive support contract, there does appear to be plenty of room for cloud service providers to create a richer developer experience that goes beyond a basic one-size-fits-all approach.

    — Mike Vizard

  • Red Hat Unveils Ansible Platform

    Red Hat Unveils Ansible Platform

    At the AnsibleFest 2019 conference, Red Hat this week announced the general availability of the Red Hat Ansible Automation Platform that combines several IT automation technologies into a single subscription.

    Built on top of Red Hat Ansible Engine, the platform also includes Red Hat Ansible Tower, a management console, and Red Hat Network Automation, an instance of Ansible designed to automate the management of network resources.

    Red Hat is also providing access to a software-as-a-service (SaaS) analytics application that enables IT teams to monitor how deeply Ansible has been adopted within any IT environment. That application also provides access to Ansible Content Collections, a packaging format that streamlines the management, distribution and consumption of Ansible content, and Automation Hub, a repository for certified content packaged using Ansible Content Collections.

    Richard Henshall, product manager for Red Hat Ansible Automation, said with this offering Red Hat is trying to make it easier for enterprise IT organizations to implement Ansible at scale. Most of the time the Ansible framework is adopted from the bottom up within an IT organization. Red Hat Ansible Automation is intended to make it easier for enterprise IT organizations to centrally deploy and manage all their instances of Ansible, he said.
    Although it’s not possible to know how many instances of the open source IT automation framework have been installed, Henshall noted there are already more than 4 million Ansible nodes that are tied to a paid support subscription from Red Hat. Most of those instances involve organizations that have adopted a declarative IT automation framework as part of their overall DevOps strategy, he said. While IT organizations don’t necessarily have embrace DevOps to employ Ansible, Henshall said there is a strong correlation.

    Much of that success can be tied to the fact that as a declarative framework Ansible doesn’t require IT operations teams to learn how to program to manage IT operations at scale. That approach has allowed IT teams to adopt the open source framework to meet the demands for more agile approaches to managing IT infrastructure stemming from developers who have embraced best DevOps practices.

    In addition, IT infrastructure vendors such as Cisco Systems, NetApp and F5 Networks have begun to embed Ansible within their server, storage and networking platforms. As those vendors sell the latest edition of their offerings, the number of IT organizations exposed to Ansible should begin to substantially increase.

    Henshall said the biggest issue now is expanding the scope of Ansible deployments. Most organizations initially wind up using Ansible to automate disaster recovery before moving on automate additional existing processes. Red Hat is now trying to encourage those teams to create new processes that previously would not have been possible without an IT automation framework, he said.

    Ansible may not be a de facto standard in the enterprise just yet, but it’s well on its way. Of course, there are still many IT professionals for one reason or another still tend to resist relying on IT automation frameworks. There are also several rival IT automation frameworks that have been embraced by DevOps teams. But when it comes IT automation, it’s clear Ansible is starting to emerge as the path of least resistance.

    — Mike Vizard

  • Split Software Adds Feature Monitoring to Feature Delivery Toolset

    Split Software Adds Feature Monitoring to Feature Delivery Toolset

    One of the issues that has long plagued both development and test is determining exactly where problem code exists. The increasing rate of change that agile and DevOps have brought to projects makes this problem worse than ever because changes today can impact code from yesterday–or yesteryear.

    The constant flux that modern software is in makes tracking down issues that much harder. This is offset a little bit by the fact that changes are generally smaller and more incremental because there are several iterations to get improvements into place and short sprints are the norm. But not completely offset, because a defect may just now be showing up, even if it was introduced several iterations ago.

    Feature Delivery tools offer the ability to group changes into features, then turn them on and off as needed. In the case of Split, they can also be phased in to see impact upon users. While the name uses “feature”, any code change like “feature enhancement” is included.

    The announcement pertains to new functionality called Feature Monitoring. This new addition to the toolset allows monitoring of features in production to show the DevOps team what is happening with their changes in real time. It also allows for advanced targeting of users so small groups can get the updates and evaluations made on how the changes impact those users in production.

    Feature monitoring captures error data, and feature tagging ties that data to features, meaning defect identification and resolution can both happen at a faster pace. Less looking where there isn’t a problem, and more information about how buggy a new release is.

    Given that I’ve recently written a fair amount about testing and the issues test DevOps team members face with rate of change, this seems custom-designed to address those issues. While there is no silver bullet, the faster issues can be identified, assigned and repaired, the better the overall application quality will be–and that is what this announcement is about.

    Not having used the tools yet, I can imagine some thought has to go into inter-related functionality, but that has always been true–you have to know what works as an overall system and can be placed together in a release versus what has to be held back if a given piece is incomplete. The way I envision Feature Delivery, and more specifically Feature Monitoring, being used would be smaller pieces than an entire release. Even if a new feature is going live, someone knows what inter-related pieces must be complete, so simply shifting that knowledge left will allow effective feature tagging.

    Finally, the ability to turn updates on and off by changing flags means less downtime, and if planning is done well, the virtual or complete elimination of rollback plans. Agile and DevOps talk of fix and re-release, but we’ve all seen scenarios where that simply isn’t an option, and this may be the solution we’ve been looking for–rollback by changing a flag that changes what code is executed. Flag-checking occurs in code with if-then’s though, so after many iterations code clean-up, it would likely need to be done just to keep the code from being overburdened with nested logic for iterations that are known to be stable.

    I think I’ll add this to my list of markets/products to dig deeper into and actually put to the test. We have a set of servers sitting idle at the moment, and a mobile app we use for testing, perhaps we’ll take some time to test out flagging and nesting.

    In the meantime, it is definitely worth a look. Anything that eases test burden and might remove the need for rollback planning is worth a look. Meanwhile, keep kicking out the tools that run business.

    — Don Macvittie

  • Deadline Extended! Get Your Tools Included in Our DevOps Tools Directory

    Deadline Extended! Get Your Tools Included in Our DevOps Tools Directory

    We’ve extended the deadline for inclusion in the DevOps Tools Directory, due to the number of last-minute entries we’ve received so far. The new deadline is this Friday, Sept. 20, so don’t wait!

    The DevOps market is growing so fast that it’s getting difficult for us (and, I’m sure, you) to keep up with all the new players out there. That’s why we’ve put together a tools survey that we hope tools vendors will take part in, so that we can create a comprehensive directory that developers, IT operations and executives can use to discover the right tool for their DevOps toolchain.

    The survey is also going to be used to help us recognize the top vendors in each category through our annual DevOps Tools Awards. (Did someone say awards?)

    The DevOps Tools Survey breaks tools into categories based on their utility as they relate to building applications. The categories are: creating, assuring, assembling, securing, delivering, running and analyzing. Organizations can submit up to three tools to be included in the directory.

    Want to be a part of the action and get your tool listed? Simply click on this link to get started. The process takes only about 10 minutes max, and will give us the information we need to get your tool included. It costs nothing to be included in the directory, and enhanced listings are available as well.

    Hurry, time’s running out! Don’t wait! The deadline for submissions is Sept. 20.

    — Charlene O’Hanlon

  • Why COBOL Still Matters After 60 Years

    Why COBOL Still Matters After 60 Years

    In the world of DevOps, the Agile Manifesto and countless other application delivery frameworks, one has to wonder how an anachronism such as the programming language COBOL (common business-oriented language) has managed to remain relevant. After all, COBOL has its roots back in the 1940s, and was built upon Rear Admiral Grace Hopper’s work on the FLOW-MATIC programming language (a text-based programming language). Hopper, who worked as a technical consultant on the FLOW-MATIC project, is sometimes referred to as the grandmother of COBOL.

    Last century, COBOL quickly became one of the most used programming languages in the world and it is still quite popular, claiming more lines of code in active use today than any other programming language. It offered a huge advantage over the other programming languages of the era. One that can be summed up as portability. From the outset, COBOL was the first popular language designed to be operating system-agnostic. In other words, it could be run on numerous different systems with little change made to the source code. What’s more, as a text based language, COBOL used English words and phrases to make it easier to understand and also made it somewhat self-documenting. 

    While much of the programming world has moved onto JavaScript, Python, PHP and even C and C#, COBOL can not be ignored. It continues to evolve and remains relevant, even in the age of the cloud. Simply put, it still has some chops to it. Take for example:

    • COBOL is a Language of Business: It is still used by the majority of major banks and insurers. The language can be found in widespread use across numerous other sectors, such as retail, healthcare, government and automotive. For most of those businesses, no other programming language has displaced COBOL and it remains as the back-office business language of choice.
    • COBOL is Extremely Portable: From the outset, COBOL was designed to be operating system agnostic, meaning the same applications developed under it could run unchanged across many different platforms. That allows COBOL developers to focus on building applications, instead of worrying about the intricacies of operating systems. That fuels DevOps and agile by allowing developers to test and deploy across a wide range of supported platforms.
    • COBOL Continues to Evolve: It supports and integrates with numerous platforms and works with operating environments such as Linux, mainframes, Windows and UNIX. What’s more, COBOL also integrates with Java, C#, Docker containers, mobile, .NET and JVM as well as Azure and AWS cloud environments. It can be used today to build cloud, containerized and managed code apps. And continues to evolve to meet the challenges of the future.
    • COBOL is Easy to Learn and Understand: It was created with the objective of making it easier for programmers to work with computers and each other. That objective has translated into a language easy to learn and understand by using English phrases and commands. The readability aspects of COBOL make it self-documenting, along with an ease of use not found in other languages. What’s more, the language costs less to maintain and its readability means it is easier to maintain.
    • COBOL is Future-Proof: It has continually evolved and now works with industry-standard IDEs, meaning programs can code with COBOL using familiar tools that support teams. COBOL developers are able to use the language alongside contemporaries, without having to forgo the latest IT tooling and processes.

    While many in the DevOps world sell COBOL short, there are many reasons why the language remains popular today. It continues to meet the needs of business and embraces many of the changes the cloud and new techniques can throw at it. COBOL is even now embracing APIs, micro services, the cloud and distributed platforms, making it a worthwhile tool for business today.

    — Frank Ohlhorst

  • The Bedrock of Digital Transformation

    The Bedrock of Digital Transformation

    Trends come and go. I’m old enough to have been persuaded, twice, about the good sense of flared jeans. I had a space hopper. I had a Betamax video player. Fads and cool ideas are a constant white noise, vying for our attention. Some will stick, some won’t. And that’s true in technology. No-one admits to owning a C5, but plenty of us built PowerBuilder and Delphi apps. A few of us tinkered with Smalltalk.

    But genuinely smart, enduring ideas find a way of sticking, of evolving, and adapting. No-one these days thinks of a phone as a wired device stuck to a wall which you could only use if you asked someone to connect you. And no longer do you have to employ anyone to run in front of you with a flag as you drive your motor car. Like cars and phones, good ideas endure and in the world of computers and IT, the COBOL language is no exception.

    Very few organizations of any size are not being impacted by today’s digital era and the seismic changes being seen in the market place. Entire industries have been disrupted beyond all predictions in the last decade or so. Indeed 88% of the Fortune 500 have dropped off that list in the last 50 years, as those who fail to keep up with the pace of change are being replaced by those who can adapt.

    But adapting isn’t easy. Making fast progress toward new digital objectives is often hampered by practical barriers that are individually difficult to solve, particularly in the case of the existing technology landscape already in place. Things such as vendor lock in, complex business processes, interdependent apps and data, inefficient delivery processes, technical constraints and skills issues.

    Additionally, the technology landscape is forever changing, but only growing in complexity. Today, large global enterprise businesses typically run a hybrid environment, which is a consequence of adopting multiple waves of technological advancements over time. Each individual advancement offered opportunity and progress, but eventually results in a highly complex and inefficient technology environment. Most organizations are pursuing digital transformation programs with a view to reduce complexity, create better flexibility and reduce total cost of ownership.

    There has been tremendous value created in business applications and data and there is a lot to be gained in digital transformation by leveraging that value as much as possible, in transforming it with the minimum cost and risk. Much of this value is encapsulated in systems built some time back, and which have evolved with the business. Oftentimes, using COBOL technology. COBOL was invented way back when, but has adapted to support ongoing business technology demands and rigors.

    Having an appreciation for where your organization is today, along with an awareness of what needs to be achieved in regard to the required updates, the process used and the infrastructure considered, can assist with plotting the pragmatic steps to develop a plan that delivers transformational value. With some of the most critical systems being written in COBOL, these core systems continue to power a variety of fundamental processes in modern business.

    The risks of ripping and replacing systems are measured as an average IT project failure rate of 71%, which amounts to a $1.7tr cost in a single year. These are dreadful numbers and no organization wants to waste that sort of time and money and reputation. There is now a growing realization, from many years of experience in those more radical transformation projects, that their success rate is relatively low, planned costs and timescales typically grow exponentially, and the risks to successfully continue business during such a transformation are unacceptably high.

    Enter stage left a more pragmatic approach: modernization. This concept prioritizes on protecting the value of what companies already have, exploiting advancements in technology to deploy and integrate applications in new ways and to surface and integrate data in new ways, with the minimum change to what already exists. Creating portability and operational independence for applications and data is becoming recognized as the fastest and most future proofed path to building a platform for digital transformation. Market influencers such as Gartner and IDC have commented on it, and most of the global systems integrators are industrializing their modernization practices to support companies successfully transform. So what is the underlying technology acting as the catalyst for this modernization and transformation?

    COBOL enters its seventh decade of helping run great chunks of the world’s largest IT systems entirely thanks to its staying power; its adaptability.

    COBOL’s endurance owes a lot to its original design that make it readable and portable, meaning it can be picked up by new staff quickly, and deploy wherever it is needed. What kept it in such demand owes more to the ongoing evolution of the language itself, and the tooling surrounding it. COBOL works alongside, integrates with and supports containers, cloud, JVM, .NET, JSON/REST, micro services, modern IDEs and other technology typically associated with more contemporary names. COBOL technology plugs directly into a DevOps toolchain that is adopting continuous delivery practices for some of the economies’ most important IT systems.

    COBOL is, in fact, a 2019 technology; just with a 60-year heritage.

    Next time you pick up your mobile to make a call, or sit in your car to drive to work, ask yourself how you feel about how old that idea is.

    — Derek Britton

  • DevOps Dozen 2019 Nominations Are Now Open

    DevOps Dozen 2019 Nominations Are Now Open

    The DevOps Dozen awards are back and now open for nominations. This fifth annual DevOps Dozen honors the best of the best—the leaders and innovators in the DevOps community. This year’s awards will include 12 categories, including three new ones, with a winner chosen from each. As in years past, the top four to six nominees in each category will become finalists, who will be selected based upon the number of nominations they received. Nominations are made by you, the audience, and you can nominate up to two entrants in each category; however, you can nominate someone only once. In addition, everyone nominating will be required to provide their name and email address to help stem any potential ballot-stuffing. The winners will be selected by our esteemed panel of judges.

    Last day to submit your nominations for the DevOps Dozen 2019 awards is Oct 10. Here’s where to vote: https://www.surveymonkey.com/r/devopsdozen2019

    Who are the judges? This was tough. We couldn’t have anyone who might be eligible for an award. That disqualifies vendors, practitioners and many others. However, I think we have four great judges:

    1. Alan Shimel, founder and editor in chief, staging-devopsy.kinsta.cloud
    2. Jayne Groll, CEO and co-founder of the DevOps Institute
    3. John Willis, CEO and founder, Botchagalupe Technologies
    4. Charlene O’Hanlon, managing editor, MediaOps Inc.

    The 2019 DevOps Dozen Categories

    So what are the dozen categories for the DevOps Dozen this year? That you can get on the site itself, but here they are as well:

    1. Best DevOps Solution Provider

    This category recognizes the best consultant/solutions provider in DevOps—those helping companies in their DevOps journeys.

    1. Best DevOps Practitioner of the Year (New)

    DevOps is a team effort and team success depends on the work of every member. However, there always are few who go above and beyond  the call of duty. Their passion, energy and enthusiasm is contagious. This category recognizes these real humans of DevOps.

    1. Best DevOps Solution Provider Executive

    We want to recognize the top executive at a DevOps tools or solution provider—not an executive leading a DevOps transformation within a company. Nominees can be any C-level executive, GM or SVP.

    1. Best staging-devopsy.kinsta.cloud Podcast of the Year (New)

    Which was your favorite DevOps Chat we’ve done this year? Check out our 2019 DevOps Chats on a multitude of topics ranging from CI/CD and testing to DevSecOps, Kubernetes, containers and more. Let us know which one you liked best.

    1. Best DevOps Book / eBook

    There are so many great DevOps books and eBooks that have been published in addition to “The Phoenix Project.” This category highlights that are the most popular and make a great read.

    1. Top DevOps Evangelist

    This category is one of our favorites. We are blessed in DevOps to have so many great evangelists who travel the world spreading the DevOps gospel. Nominees can work for a company in the space or not. This should be a really competitive category.

    1. Best DevOps Transformation

    This category recognizes organizations that are setting the bar in transforming their business through DevOps.

    1. Best DevOps Transformation Leader

    We want to acknowledge the key leaders driving the charge within organizations that have had the most success with their DevOps transformations.

    1. Best New DevOps Solutions Company

    This category seeks to recognize newer companies that have made an impact in the DevOps space and we believe will be tomorrow’s leaders. Nominees must be in the DevOps market less than 24 months.

    1. Best DevOps Conference of the Year (New)

    There’s an abundance of IT conferences throughout the year, and more are including a DevOps track or even focusing exclusively on DevOps. What tops your list of DevOps events?

    1. Best DevOps Presentation of the Year

    This category recognizes the best DevOps-themed presentation of the past year from any of the myriad conferences.

    1. Best staging-devopsy.kinsta.cloud Article of the Year

    staging-devopsy.kinsta.cloud publishes multiple new articles every day. Which was the best one? Let us know so we can recognize the author.

    Thank you again for your enthusiastic response to last year’s awards. The full list of 2018 finalists and winners are available to view here.

    Also, the product/technology-specific DevOps Dozen awards now will be part of our DevOps Tools Guide and Awards. This new initiative is our effort to create a comprehensive listing of tools and tools vendors to help end users better understand the DevOps market landscape, and to enable staging-devopsy.kinsta.cloud to recognize the top vendors in each category through its annual DevOps Tools Awards. To be included in this year’s guide, please complete the survey.

    There are so many great companies and people involved in DevOps that it’s always difficult to pick the winners. We know some worthy choices will not be voted tops in their category; however, acknowledging them in our awards process helps show how important they are in the DevOps space.

    As stated earlier, the top four to six nominees in each category will be designated as finalists, who then can submit a presentation on why they deserve the award to judges@devops.com. Finalists will be announced the second week of November and the winners, who will be chosen by our panel of judges, will be announced in December.

    If you have questions, send them to DD@devops.com. Voting for finalist nominees is open for three weeks, so don’t waste any time—nominate your favorites today. Good luck to everyone vying to be one of the DevOps Dozen 2019!

    — Alan Shimel

  • GitHub Enterprise Server Update Extends Enterprise Push

    GitHub Enterprise Server Update Extends Enterprise Push

    GitHub has expanded its push into the enterprise with the 2.18 release of GitHub Enterprise Server, which includes a bevy of updates intended to make administrators’ lives easier.

    Mario Rodriguez, head of product for GitHub Enterprise, said the enterprise edition of GitHub is seeing triple-digit growth as large companies more aggressively embrace DevOps tools and processes that already have proven themselves to be effective when building and deploying large-scale web applications.

    To make it easier for administrators of those environments accessing either an on-premises edition or software-as-a-service (SaaS) version of GitHub Enterprise Server, the latest edition enables administrators to employ an issue-transfer capability to delete an issue in one repository and move it along with its associated metadata to a new repository in a single step.

    Other additions to GitHub Enterprise Server include an assignable commenters capability that allows maintainers with write access to assign an issue or pull request to anyone who has commented on it, regardless of their organization membership or repository permissions.

    If an issue or pull request belongs to a milestone, the name of the milestone now also will display on the project card and in the project card details sidebar. An issue or pull request from milestones can be added or removed using the details sidebar, and project cards can be organized by milestones using the search bar.

    GitHub is now also providing administrators with repository templates that allow them to own or have write access to a template repository. That capability allows anyone with access to the repository to generate a new repository with the same directory structure and files. If an administrator creates a user-owned repository, they also now will be able to watch it for updates automatically. However, forks no longer will be automatically watched, even for those granted push access.

    Rodriguez said GitHub is also starting to extend the scope of its platform to address best DevSecOps processes. Expanded dependency graph support adds security alerts to projects that rely on “yarn.lock” files. Those alerts help developers stay on top of vulnerabilities that impact their dependencies, which Rodriguez said is critical because security issues these days can wipe out all the productivity gains previously made in a DevOps process.

    An expanded audit logs capability allows administrators to see changes to settings for organizations and repositories, in addition to seeing when PAT and SSH are being used to access information and when there’s been a change in organization and repository membership.

    In general, Rodriguez said GitHub Enterprise Server, which gets updated once a quarter, provides 95% of the GitHub repository capabilities accessed by more than 40 million developers to share code and download open source software. Enterprise IT organizations clearly want to replicate the GitHub developer experience behind a firewall to ensure no one is inadvertently accessing proprietary software that provides them with a competitive advantage. The challenge, of course, is not so much setting up the repository as much as it is defining all the DevOps processes that need to revolve around it.

    — Mike Vizard

  • Challenges of Big Infrastructure Monitoring

    Challenges of Big Infrastructure Monitoring

    The growing complexity of today’s IT reality is indisputable: Software is becoming more complex, and the infrastructure it runs on is equally so. This complexity comes, in part, from adding layers upon layers to the infrastructure we manage—from bare metal servers to VMs to containers to function-based computing—and from how quickly we cycle in new technologies and how slowly old technologies are cycled out.

    Ephemeral and multi-generational infrastructure (often side by side) are the new normal. Old and new technologies co-mingle, and while new technologies may be shiny and exciting, they quickly become ordinary as the next new thing comes along.

    Here’s a sobering stat: In Q4 2017, IBM’s mainframe business grew by 32%. So even while cloud, AI and security initiatives are on the rise at IBM, mainframes sustain a bulk of their business. Old tech perseveres, and we have to find new solutions to bridge the gap between old and new.

    The hodgepodge of technologies—and the challenges they bring—are compounded further when we’re talking about big infrastructure.

    What Qualifies as Big Infrastructure?

    For the purpose of this discussion, big infra is an organization that has been around for at least 10 years. That means they’ve had success, they’ve grown and their infrastructure has grown along with them, and the technologies at play have expanded as well.

    Your organization’s exact age, size and revenue aren’t particularly material; what matters is you’ve had enough time to accumulate resources, people, practices and technologies to create what I think of as a trail mix problem—basically enough legacy infrastructure to start creating problems.

    The Challenges of Big Infrastructure

    The challenges of big infra stem from the technology itself and from the way people use that technology. As an organization grows, its teams often become larger and more siloed, and departmental goals become disconnected. Even when working toward the same goal, departments diverge in their methods for reaching that goal.

    Now, add tools and technology to the mix: Over time, teams choose tools they prefer, or build their own, which works out okay for a while until they have to collaborate with another department that uses different tools and a completely different set of practices.

    Now, add in different work styles and personality types and company politics, and everything gets tangled up fairly quickly. Trying to keep track of who’s using what, how they’re using it and what’s working (or not) is no easy task.

    One customer, for example, had one team using Chef and was all in, and were trying to get buy in from other teams as well, but there was another team that was early days Docker, hand rolling Docker hosts, and didn’t want to adopt Chef. Then there was a different team who was early days Kubernetes and didn’t want to use Docker, and yet another team using Puppet. Once they had to work with each other, things broke down—someone has to win out. You almost have to maintain a logical map of what team uses what tools as a precursor to prepare for a meeting with these business units. Not only is there no consistency in how applications are deployed, there’s also no consistency in how these different technologies are monitored.

    For example, in the past, Netflix stated monitoring accounts for 30% of their infrastructure cost, and recently mentioned they’re planning to spend $1.9 billion on infrastructure in 2019. Think about the scale and complexity involved—they’re storing and analyzing the logs, behavior and metrics for systems supporting some 125 million subscribers.

    Connecting Disparate Data Across Big Infra

    So, how can you streamline and connect all of the data spread across fragmented tools and systems?

    One solution is a data lake, a centralized repository that lets you funnel data into one place, so you have a holistic view of your infrastructure. In reality, big infra ends up spawning multiple data lakes that become siloed from one another.

    You also likely have a square peg/round hole situation—data in one format needs to be transformed to another format before it can get into one of the data lakes.

    This is where a monitoring tool becomes essential. Look for a monitoring tool designed to collect data in disparate data types and transform it into any number of formats, so you can set up an automated workflow to get data flowing from legacy systems (e.g., mainframes) alongside modern infrastructure like containers.

    An example of this idea is with Sensu, and our support of the Nagios plugin spec and Prometheus exporter metrics (amongst many other metric formats). By using a monitoring tool that works with various metric formats, companies can plug the service checks they’re already using plus data from multi-cloud infrastructure into their monitoring setup and get valuable information about their systems.

    A visualization tool such as Grafana is the icing on the cake. With Grafana, you can hook up data wherever it’s stored (e.g., Graphite, InfluxDB, Prometheus, etc.), visualize the data and display it on shareable graphs and dashboards. Using a monitoring tool as a data source for Grafana means companies can display monitoring incidents and inventory—and even mix that data with different data sources on the same Grafana dashboard. Combining a holistic monitoring solution with Grafana’s visualization capabilities gives a data-driven view of your infrastructure that you need—even if it remains a multi-generational, multi-siloed, multi-data-laked, 2,000-different-format-typed trail mix of big infra.

    — Sean Porter