Tag: devops

  • In DevOps, Standardize to Minimize Architectural Debt

    In DevOps, Standardize to Minimize Architectural Debt

    I recently reading a great Q&A with the Etsy CTO John Allspaw over on The New Stack, which contained some nuggets of good advice that increasingly are important as we continue the journey toward DevOps adoption. Of particular note were statements on the introduction of “new” things to solve problems. In a nutshell, Allspaw reinforced the importance of standardization as a means to reduce architectural debt.

    If you aren’t familiar with the concept of architectural debt, it’s similar to technical debt, in which choices made today incur longer term investments of time and money when future changes are introduced. If you settle on a caching solution such as Redis, for example, there are technical and architectural implications. You can’t simply switch out Redis for memcached later without significant changes to both code and the infrastructure.

    Even your choice of load balancer today implies architectural debt because of the growing inclusion of scalability as part of the application infrastructure itself. The result is integration with automation and orchestration systems that are not easily changed later on if you decide you want a different solution. The style of service registry you choose is an architectural decision that impacts clients, servers and systems across the microservices architecture. Switching from client-side to server-side will later be costly.

    That’s architectural debt.

    Allspaw noted the need to not reinvent the wheel when possible, and instead encourage the collaborative aspects of DevOps as a means to avoid reinventing the wheel and potentially increasing the architectural debt load on the organization.

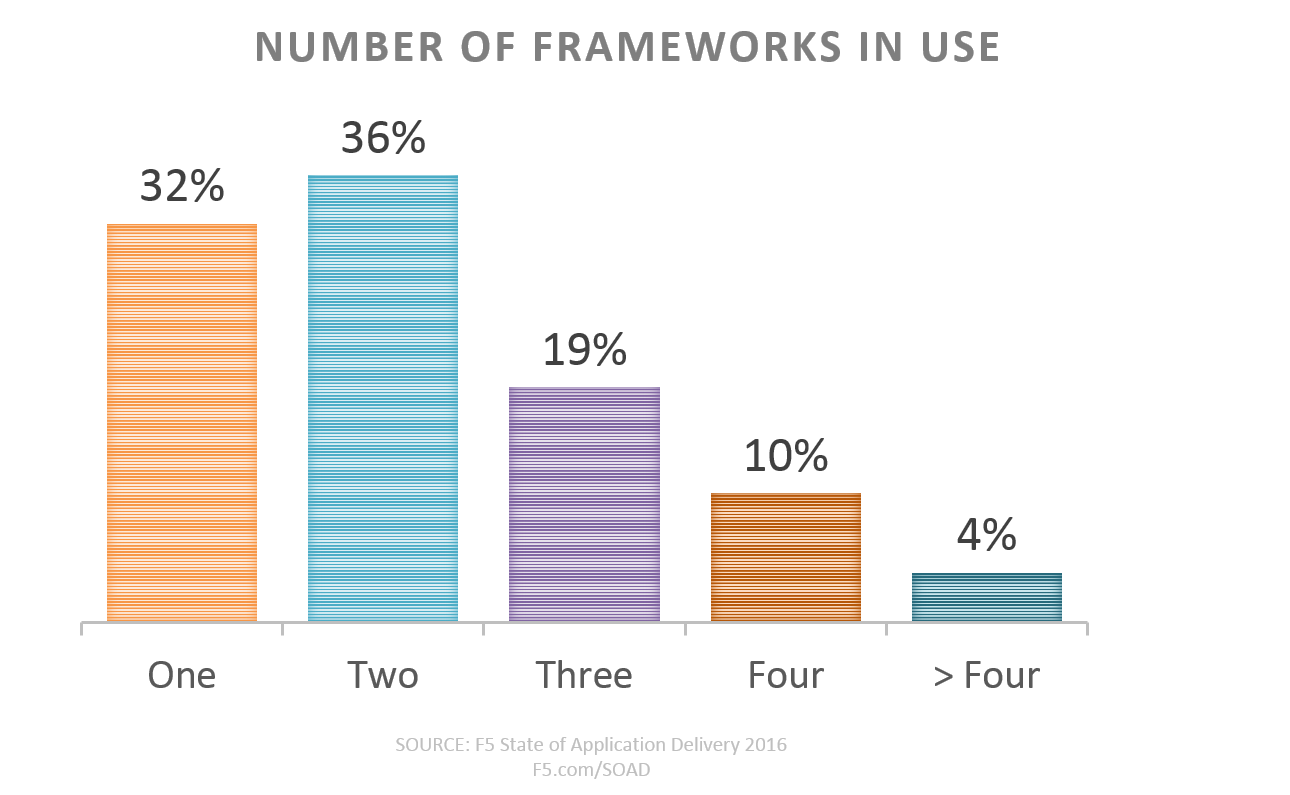
    This is not a new concept. There’s a reason enterprises in particular proudly proclaim themselves “Java shops” or “Microsoft shops” and primarily require development in one or perhaps two languages, but no more. Maintainability is a component of technical debt, just as middleware decisions are a component of architectural debt.frameworks in use soad2016

    So as we continue to see wider DevOps adoption, it’s important that we carefully consider the impact of our choices in terms of the automation, orchestration and integration required to implement continuous delivery and deployment. Once you’ve invested time and energy (and probably budget, too) in Puppet or Chef, VMware or Cisco, OpenStack or SaltStack, you’re going to find an unavoidable amount of technical and architectural debt in development as well as production across infrastructure and networking teams.

    Each of these systems, solutions and frameworks comes with its own components. It isn’t just a language, it’s a comprehensive system with management and repositories and agents and reporting components. All of these impose certain architectural requirements on organizations, from needing certain software running to prescriptive details on networking that must be enforced, lest the system break down.

    We’re already starting to see that fragmentation in enterprises that are engaged in automation and orchestration efforts. When asked the number of automation frameworks (Cisco, VMware, Python, OpenStack, Chef, Puppet, etc…) in use, one-third today reported using three or more.

    That’s not necessarily “bad,” as it could be indicative of standardization across silos (networking wants to use Cisco, infrastructure is already on VMware, and Python is being used to cobble it together by ops), but it also could be an early sign of the kind of fragmentation that causes exponential growth in technical and architectural debt.

    Certainly there is room for experimentation in these early days, but it behooves us to maintain a watchful eye on the use of frameworks and systems and languages we employ for automation and orchestration to ensure we don’t end up buried in technical and architectural debt.

    Standardization, even loosely enforced, can help minimize the impact of that debt before it spirals out of control.

  • Vapor IO Introduces OpenDCRE 1.2, the First True DevOps Platform for Physical Infrastructure

    OCP, AppliedMicro and BASELAYER team with Vapor IO to further efforts to modernize today’s data centers through open source projects, bringing out-of-the-box management capabilities that eliminate complexities and significantly lower CapEx and OpEx

    AUSTIN, Texas–(BUSINESS WIRE)–Vapor IO, provider of the world’s first intelligent, hyper modular data center solution, today announced a new release of the Vapor Open Data Center Runtime Environment (OpenDCRE). With broad community support including technology partners Open Compute Project (OCP), AppliedMicro Circuits Corporation (Nasdaq:AMCC), and BASELAYER, OpenDCRE is the first true infrastructure automation and DevOps platform connecting IT and physical infrastructure. These partnerships highlight Vapor IO’s goal of furthering development of hyper converged data center architectures within the open source community.

    OpenDCRE is an open source solution created by Vapor IO to simplify data center infrastructure communication. The new release now supports AppliedMicro X-Gene server family and BASELAYER Anywhere modular data center (MDC) products. OpenDCRE is a superior alternative to competing proprietary rackscale architectures/infrastructure, eliminating vendor lock-in.

    “As a founding member of the Open Compute Project, we are proponents and early adopters of open source solutions,” said Grant Richard, Managing Director, Technology, at Goldman Sachs. “OpenDCRE presents an opportunity to simplify data center infrastructure communication and advances OCP’s mission to build the most efficient server architecture possible. We are pleased to be working with Vapor and our partners in the open-source community toward this mission.”

    “The Open Compute Project is dedicated to ensuring community led standards are brought to market through open interfaces,” said Corey Bell, CEO, Open Compute Project. With Vapor IO’s OpenDCRE hardware, which was submitted for contribution, end users now have the ability to remotely manage OCP compatible infrastructure via a completely free and completely open API.”

    Creating an Intelligent, Hyper-Modular Data Center

    OpenDCRE provides a secure, RESTful API for monitoring and completely controlling your entire data center and IT equipment. It can be used as an open platform for monitoring and managing data center hardware, software and environmental characteristics. The OpenDCRE API enables easy integration with third-party monitoring, management and orchestration providers. An alternative to proprietary interfaces and custom silicon, it provides a simple, curl-able interface for common and custom DevOps tasks. There are a wide variety of possible applications, deployments, physical mounting strategies, and network connectivity options for which Vapor IO is working to foster community support.

    OpenDCRE 1.2 provides the following capabilities to enterprises:

    • Out-of-the-box management to the Open Compute Project (OCP) community while removing the complexities, CapEx, and OpEx of top-of-rack, out of band management switches and complex network architecture.
    • Ability to speak directly with data center critical environment systems removing additional CapEx from the M&E cost of the building
    • Linux-like compatibility with its licensing under GNU General Public License version 2 (GPLv2)

    The Applied Micro ARMv8-A 64-bit quad-node X-Gene based OCP platform is the first of its kind and marks the entry of ARM servers into OCP,” said Kumar Sankaran, associate vice president, software and platform engineering, AppliedMicro. “This platform is particularly suited for the high density compute market segment. With the integration of OpenDCRE into this platform, it paves the way for a very highly efficient management infrastructure within the data center.”

    BASELAYER founder and CEO William D. Slessman stated, “We are pleased to be working with Vapor IO. The combination of Vapor IO’s OpenDCRE with BASELAYER’s modules and RunSmart data center operating software extends the range of our platform, and enables our customers to achieve improved operating performance.”

    “Data center environments are becoming increasingly complex and filled with a myriad of hardware and software solutions and tools from various vendors. In order for IT organizations to succeed they need to run efficient and agile environments. The collection of resources that make up today’s data centers must work together seamlessly, but at the same time exist as independent components so they can be replaced, repaired or upgraded as necessary,” said Cole Crawford, founder and CEO, Vapor IO. “Our mission is to take the disaggregated data center, and turn it into a highly efficient, well-connected but intentionally decoupled IT system.”

    Vapor IO was founded by Cole Crawford, an industry veteran with deep expertise in open source hardware and software technologies. With over 20 years of experience in the data center industry, Crawford has co-founded companies and nonprofits alike dedicated to transforming IT including OpenStack, where he served on the foundation formation committee and the Open Compute Project, where he served as its founding executive director.

    Supporting Resources

    About Vapor IO

    Vapor IO provides the industry’s first intelligent, hyper modular data center solution. Significantly lowering capex and opex costs when building and running data driven data centers, Vapor IO provides an integrated solution to integration problems. Eliminating complex structures and parking lot data centers, Vapor IO offers a true intelligence platform for any data center workload. For additional information, please visit www.vapor.io.

    Contacts

    Mindshare PR
    Heather Fitzsimmons, 650-279-4360
    Heather@mindsharepr.com

  • DevOps and Agility for Multi-Speed IT

    DevOps and Agility for Multi-Speed IT

    Let’s step back for a moment and look at the IT world a bit differently from the traditional technology-centric lens through which most of us IT peeps tend to look at things. Line of business (LOBs) need us, the IT organizations, to deliver capabilities to their customers and users that deliver business value. They also rely on these systems to provide feedback on how customers and users are consuming the business capabilities and deriving value; how they are interacting the business systems; and what capabilities and features they need to get better value. The LOBs are asking the IT organizations to deliver these capabilities with:

    • Velocity
    • Agility
    • Innovation
    • Cost Management

    IT organizations, in most cases, are not designed for velocity, agility or innovation. They are large organizations hindered in their ability to deliver these by legacy systems, myriad practices and tools, overbearing governance and compliance regimes, archaic and siloed organizational structures and cultural inertia. This lack of ability of the IT organizations to deliver agility, velocity and innovation in some cases even results in LOBs creating their own “Shadow IT” organizations to deliver their IT needs.

    Finding Velocity, Agility and Innovation

    The solution of late has been to undergo a DevOps transformation that enables IT organizations to adopt the necessary practices, automation tools and organizational and cultural change to deliver with velocity and agility, and become innovative by being able to deliver rapid experimentation. The origins of DevOps lie in Lean IT, and adopting DevOps is really applying Lean principles to help achieve agility, velocity and innovation.

    DevOps does so by making organizations that are delivering IT systems and software more efficient and lean. Organizations that have adopted DevOps are able to:

    • Get ideas out to production faster
    • Have users/user surrogates use them
    • Get rapid feedback

    Using this feedback the organizations can improve three things:

    1. Applications delivered
    2. The infrastructure delivered
    3. The process by which IT systems and software are delivered

    However, large organizations have been struggling to achieve the results promised by DevOps and achieved by the poster children of DevOps, with whom the movement started. For every Netflix and Etsy out there, there is a large, complex, organization that has been struggling with simply where to start. They may be able to achieve success in some parts of their IT organization—with small, innovative ‘two pizza’ teams working on isolated projects—but not at enterprise scale. They struggle with how to achieve even the results of DevOps adoption they see in their own successful teams, at scale. The organizational and cultural inertia appears to be too difficult to overcome.

    The major reason of this inability to achieve at scale is the persistent struggle in all large organizations between the desire to innovate, and the need for stability. This push-and-pull exists in all organizations—even an innovative startup feels it. The Dev teams are focused on creating innovation thru rapid change and experimentation, and the Ops teams are focused on creating stability and continuity. DevOps addresses this existential struggle by adopting a series of practices that drive cultural change, automation and process adoption that allow these Dev and Ops teams to work toward common goals and balance their needs. Even in large organizations, this can be achieved on small teams that are able to circumvent the legacy organizational structures and practices and figure out how to get all the stakeholders working toward common goals. That is why this works great on small, strategic projects that have well-defined goals and timelines and can “fly below the radar” of corporate governance enforcers. As we move to larger projects with large, potentially distributed teams, spread across different groups and corporate “fiefdoms,” adoption struggles and often fails.

    The Rise of Multi-Speed IT

    One fact these large organizations need to recognize is that they really must have two modes of delivering IT: one focused on innovation (and velocity and agility) and the other focused on optimization (stability and continuity, with agility and velocity). This view is being referred to in the industry as “bi-modal IT” and is actually more of a continuum than a clear-cut two modes model. Hence, the term is evolving now to “multi-speed IT.” However, classifying the continuum into two broad categories based on the business intents of innovation or optimization serves the purpose of determining how to adopt DevOps very well.
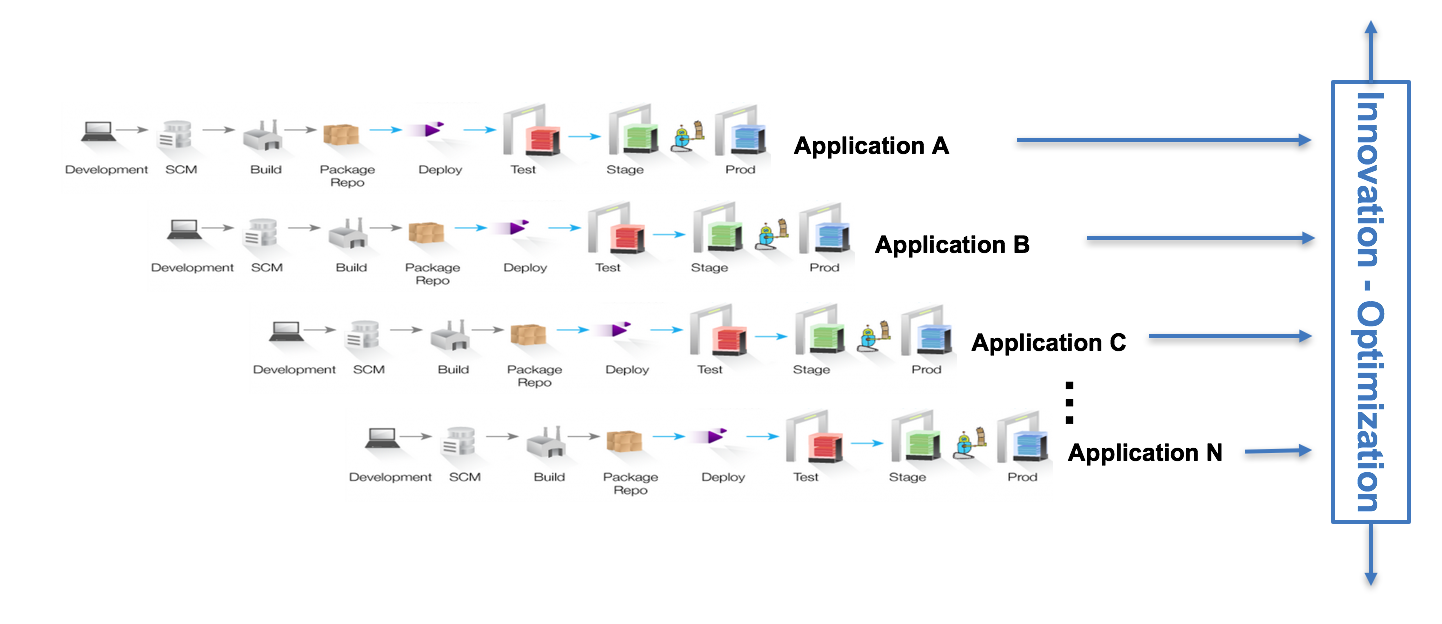
    Multi-Speed ITMulti-Speed IT

    One interesting way to look at these two modes is to classify them as:

    1. The ‘Industrialized Core’ that delivers core business capabilities—things that keep the business going, and the primary business intent is optimization
    2. The ‘Innovation Edge’ where experimentation happens and new systems get identified and developed; in other words, the primary business intent is innovation
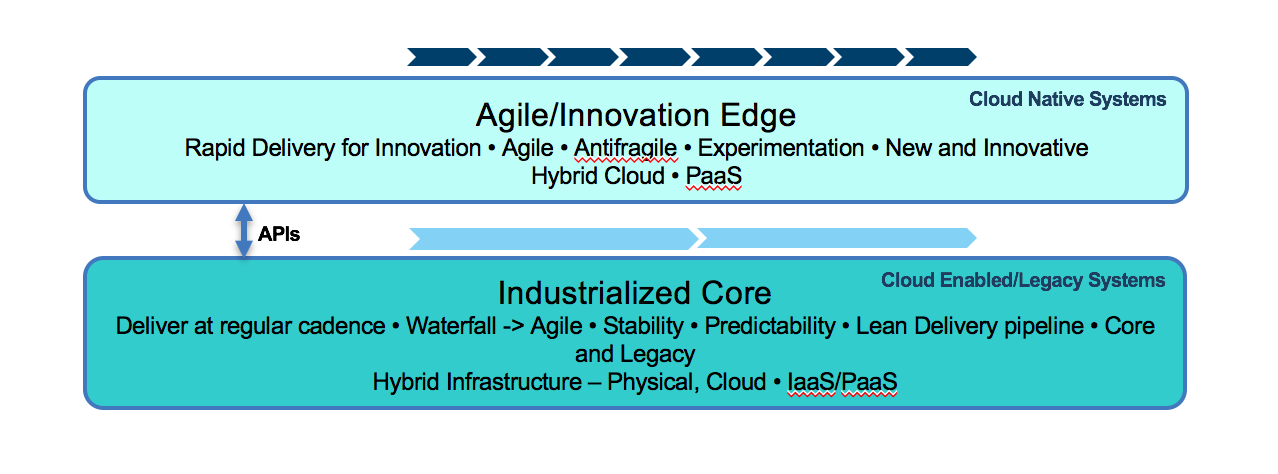
    Innovation vs OptimizationInnovation vs. Optimization

    The goal of the Innovation Edge is to allow for rapid experimentation, development of minimum viable products (MVP), rapid delivery and fast failure. The goal of the Industrialized Core, on the other hand, is to be lean and efficient and deliver business capabilities in an optimized, predictable, stable and secure manner, with the ability to scale as needed. Note: Eventually systems from the Innovation Edge will need to be “industrialized” once they start serving a core business function. This is a continuum from innovation to optimization.

    The Industrialized Core itself needs to be continuously incrementally industrialized to provide the stability and reliability needed, while getting leaner and more efficient, at scale. The core needs to get to optimization, with agility and velocity, as it delivers the core systems, again at scale. The core, too, needs to adopt DevOps and agile development practices, even for legacy systems, including those on the mainframe. This Industrialized Core is, after all, what keeps the business going and delivers the ongoing business value as the Innovation Edge seeks out new and disruptive business capabilities and avenues to deliver them.

    However, they both need different DevOps approaches and platforms delivering Agility, Velocity and Innovation at different levels.

    These two systems to deliver business capabilities are, in reality, joined at the hip. The systems delivered on the Innovation Edge are dependent on the services provided by the Industrialized Core to deliver the innovations they are developing. The Industrialized Core, on the other hand, consumes most of the budget in typical large organizations, and needs to be optimized to free resources for innovation.

    Consider a typical mobile application (say, mobile banking). To deliver that application, there is a team charged with developing the mobile front end. These kind of applications are developed and delivered in the Innovation Edge. Does all of the data and business logic sit on your mobile phone when you use that application? Of course not. Most likely, the business logic and certainly the data are components of the application that are delivered by pre-existing systems or services in the Industrialized Core. So, the mobile application is hybrid, comprised of components running in both places. To deliver even some experimental features of this mobile app, the company needs to release a hybrid or composite application, delivering components delivered by both the Innovation Edge and the Industrialized Core.

    During the Dev/Test cycle, these two modes of application delivery must be as decoupled as possible, so the development schedules and cycles of one does not drag the other, to prevent the Core from becoming a drag on the Innovation. Creating an API ecosystem is thus essential to decouple the Industrialized Core from the Innovation Edge. The Core provides the business services consumed by the innovative applications being delivered by the Innovation Edge as APIs. A key benefit of developing this API-based architecture is that these APIs potentially can be monetized to third-party partners, generating a revenue source at the same time.

    It is important to note that the architectural and process needs for adopting DevOps in both of these modes are different in many ways. Their needs and how they deliver applications and services differ as they are serving different business goals. In my next post, I will start delving into these architectural and process needs for adopting DevOps for both the Innovation Edge and for the Industrialized Core, which allow the Innovative Edge to allow for experimentation and innovation, and for the Industrialized Core become more optimized.

    Watch this discussion between industry practitioners as to how they have adopted DevOps in a multi-speed IT model: the challenges faced, successes achieved and lessons learned.

    About the Author/ Sanjeev Sharma
    Sanjeev

    Sanjeev Sharma, CTO and Distinguished Engineer – DevOps Technical Sales and Adoption, IBM Cloud Unit, is a 20-year veteran of the software industry with expertise in DevOps, Mobile Development and UX, Lean and Agile Transformation, Application Lifecycle Management and Software Supply Chains. He is a DevOps Thought Leader at IBM and speaks regularly at conferences. He has written several papers and is the author of the DevOps for Dummies book.

  • Building a Business Case for DevOps

    Building a Business Case for DevOps

    You can get your DevOps vehicle as fast and fine-tuned as you like, but until you provide an effective business case to the board it will remain in the garage. To get the thumbs up, you have to prove your model is efficient and makes financial sense for the company as a whole.

    Do You Need to Make a Business Case for DevOps?

    Coherent business cases are needed for companies at various different stages of their DevOps journey, not just those at the very beginning. Ask yourself which one of these scenarios best suits your current situation:

    1. You/your CIO know(s) the company needs to become more agile, but you don’t know how to quantify the benefits.
    2. Your teams have started to implement DevOps practices locally and can see the benefits, but you don’t know how to quantify the success to sell it to management.
    3. Your organization sees the success of DevOps pilots, but need to justify the investment to bring DevOps to an enterprise scale.

    DevOps can represent a huge shakeup of the IT department that must be justified clearly and logically. The risk must be outweighed by the projected financial gain. Crucially, this needs to be quantified in language that finance department can relate to. It is referred to as the hurdle rate: the necessary annual or total return of a project to compensate for the risk.

    What Should the Business Case Contain?

    1. Executive briefing
    2. Recommendations
    3. Required decisions
    4. Business drivers
    5. Scope
    6. Assumptions
    7. Analysis
    8. NPV (Net Present Value)
    9. Strategic options

    Hallmarks of a Successful DevOps Business Case

    Agility

    This is the main benefit of DevOps: the ability to deliver applications faster and allow for frequent changes and adoptions all the way into production. But how do we measure and quantify the benefits of agility?

    Time Value of Money

    The time value of money expresses the fact that money today is worth more than money tomorrow. The more you have to invest early (instead of over time) and the longer it takes to receive the return, the lower the present value of your investment.

    The number you receive when calculating the present value of an investment (benefits minus costs) is called NPV (Net Present Value). It tells you what your future investment is worth today.

    With agile and DevOps you are able to develop an application and deliver it to your end user in small chunks rather than in big ones; thus, you will improve the NPV (Net Present Value) of your project even if the total amount of investment and output are the same.

    Delivering software continuously rather than yearly creates benefits in the same way as receiving interest on your savings account every day rather than just once a year.

    The precise time value of money depends on the average cost of capital a company has to bear. For example, a large, publicly traded company has a lower cost of capital than a small, privately owned one. Your finance department will know it.

    Cost of Waste

    A second aspect, which speaks for agility in a quantifiable manner, is the reduction of waste.

    Functionality delivered using non-agile software engineering practices may be irrelevant or outdated once it reaches the end user because of the time gap and mismatches in requirements and expectations. The cost of such waste can be reduced drastically by using DevOps.

    Calculate the benefit of waste reduction using available statistics on the average percentage of functionality used without changes in your applications. It may pay off to assess this number for the last two or three releases delivered.

    Take into consideration:

    1. Total cost of development and delivery of these releases.
    2. Relative efforts of different functionalities delivered by release.
    3. Cost of change requests that arrived during and after the release date.
    4. End-user survey on the need and usability of these functionalities.

    Combine the benefit of waste reduction and of frequent delivery and add them as positive future cash flows to your calculation.

    You also need to calculate the forecasted costs of your DevOps initiative. Consider:

    1. Investment in build, test, deploy and provisioning and related operating expenses.
    2. Investment in IT infrastructure.
    3. Investment to complement skills in development and operations teams.
    4. Investment in organizational changes.
    5. Operating expenses for all above.
    6. Extra cost of non-automated activities in test, release and deploy due to increased release velocity.

    As part of your strategic options in the business case, balance your investments in automation with investments in more resources for build, test and deploy for given agility scenarios. The higher the release velocity, the more build, test and deploy activities are required. The more automation, the less of these activities must be done manually. Visualize in diagrams how the investment in more automation starts to pay off with increasing release velocity.

    Finally, sum up positive and negative cash flows and use your company’s hurdle rate to calculate your NPV.

    About the Author/Michael Schmidt

    Courtney-Glymph_avatar_1435225162-96x96Michael Schmidt heads DevOps Practice at Automic, a management and technology advisory service established to help Automic customers to prepare for and transform their organizations toward DevOps. Michael spent his carrier as consultant, entrepreneur and in several product-related leadership positions. He has a passion for building lean IT organizations. Michael holds a joint MBA from New York University, London School of Economics and HEC Paris and a Master of Computing Science.

  • Chef Makes DevOps Workflow Faster and Safer for Enterprises Amid Rapid Business Growth

    New Chef Delivery Product Enhancements Come as Company’s Annual Recurring Revenue Grows 94 Percent Year-Over-Year in 2015 and Chef Nears 1,000 Customers

    SEATTLE, WA–(Marketwired – Mar 10, 2016) – Chef, the leader in automation for DevOps, today introduced Dependency Management, a new feature of its Chef Delivery product, that enables faster and safer developer collaboration by allowing Chef Delivery to know which services and applications in the pipeline depend on one another. With Dependency Management, not only must changes pass local tests, but related, downstream components or services must pass those tests, as well. Only service changes that pass are promoted, so deployments to production are safe. Dependency Management enables a reliable, repeatable and scalable process for cross-team collaboration in large enterprises. It doesn’t matter if there are two developers or thousands of staff — teams can create and safely deploy interconnected services on diverse runtime environments, including containers.

    Chef also today announced enhanced capabilities for Chef Compliance to enable automated management of compliance policies that are based on the broadly used Center for Internet Security (CIS) benchmarks. Users can now implement CIS and other compliance policies as code, called “compliance profiles.” In addition, Chef Compliance offers an enhanced Windows experience by allowing users to import Windows policies from the Microsoft Security Compliance Manager.

    By using compliance profiles in conjunction with Dependency Management, users can enforce these policies with Chef Delivery to ensure that changes to infrastructure and applications meet all requirements across the pipeline. Together these two new features enable users to easily input, track, and test service runtime dependencies. Simultaneously, users can incorporate CIS benchmarks profile into Delivery’s automated testing pipeline to create a foundation for meeting Payment Card Industry (PCI) standards.

    Software is now the competitive currency of the enterprise. However, software is also becoming increasingly complex and composed of interdependent services that reside in the cloud. Businesses must be able to develop and maintain these intricate applications, along with the infrastructure that supports them, while moving at high velocity. It is critical that any changes to applications and infrastructure be versioned and tested before they are deployed to production. Because multiple teams often work on a single application, cross-team collaboration and transparency are critical to the success of a project. The DevOps workflow, which uses both culture and technology to foster these values, is becoming the most effective approach to developing software quickly and safely. Chef has distilled its customers’ successful workflow patterns into Chef Delivery, where service dependencies can be predefined and compliance requirements become part of the development pipeline. Chef Delivery eliminates silos and project segregation, enabling developers and operations personnel to begin committing code to the primary development pipeline in their first week on the team, instead of waiting weeks or even months in traditional environments.

    “Enterprises need comprehensive solutions to safely implement DevOps in the push toward ever-greater development velocity. Unlike other frameworks and tools, Chef Delivery doesn’t just help you build a change management pipeline, it is the pipeline,” said Alex Ethier, vice president of product, Chef. “We’re committed to advancing our product in a way that enables developers, operations and IT to collectively manage the speed and scale of enterprise business.”

    Company, Customer and Community Growth
    The new product enhancements reflect Chef’s rapidly growing footprint in the enterprise. Today, more than 80 percent of the company’s revenue comes from enterprise organizations, and more than half of the Fortune 50 use Chef. Chef has tens of millions of machines under management on any given day. To date, the Chef client has been downloaded more than 27 million times, with more than 13 million client downloads in 2015 alone. Among the increased demand from the enterprise, Chef’s annual recurring revenue (ARR) grew 94 percent year-over-year in 2015.

    Regionally, Chef’s EMEA business continues to rapidly expand. Q4 2015 was a record quarter for Chef EMEA, accounting for nearly 20 percent of the company’s total ARR for the quarter. Chef’s EMEA business now serves more than 150 customers and ARR for 2015 grew 91 percent year-over-year.

    Chef is closing in on 1,000 customers worldwide, with Chef’s commercial offerings used by organizations including Nordstrom, Facebook, Disney, Target, Standard Bank, and Etsy.

    Critical to Chef’s success is its open source community, which has more than doubled in size – at a clip of more than 100 percent year-over-year for three consecutive years – to nearly 70,000 registered members and thousands of active constituents contributing code daily. As adoption of open source technologies rise and more developers adopt Chef skills, the value of those abilities is reflected in enterprise careers. Dice recently noted that developers who cultivate Chef skills see return in a more than $130,000 annual salary.

    Recently, Chef announced a new Partner Cookbook Program to allow even greater collaboration and integration for its open source community. Some of our partners include 3Scale, Alert Logic, CloudPassage, Dynatrace, Infoblox, and NetApp.

    Availability
    Chef Delivery’s new Dependency Management capability is now available to all current Delivery customers. Read more on accessing and utilizing this new feature. Register for a webinar demonstrating Chef Delivery with Dependency Management on April 7, at 10 am PT.

    The CIS and Microsoft Security Compliance Manager profiles for Chef Compliance will be available on March 31 and demonstrated via a webinar that day at 10 am PT. Register here for this webinar and for more information on the profiles’ availability.

    Additional Resources

    About Chef
    Founded in 2008, Chef Software is changing the way companies build and deliver software to delight customers. Chef is the leader in automation for DevOps, empowering customers to build and operate high velocity organizations. Built on a strong open source foundation, we have distilled the proven patterns and practices for fast and scalable software development into our leading IT automation platform. Chef automates the continuous and unified delivery of applications and infrastructure, enabling enterprises worldwide to deliver software much faster with minimal risk. With hundreds of commercial customers and tens of thousands of open source community members, we are leading one of the strongest technology movements today. Our company is based in Seattle, WA, and financed by DFJ Growth, DFJ Ventures, Battery Ventures, Citi Ventures, Ignition, and ScaleVP. Learn more about Chef at www.chef.io.

    CONTACT INFORMATION

  • Top 5 Reasons to Back Up Your OpenStack Environment

    Top 5 Reasons to Back Up Your OpenStack Environment

    I am a big fan of lists. If you recall the movie “High Fidelity,” John Cusack’s character Rob and his co-workers—armed with an encyclopedic knowledge of all things musical—compile “top five” lists for every conceivable occasion, openly mock the tastes of people, and, every so often, sell a few records. In the spirit of a lists, here are the top five reasons to back up your OpenStack environment. We thought that it would be helpful to many.

    If you’re currently working with OpenStack clouds, or are in the process of embracing it, you need to include backup and recovery for OpenStack on your list of to-dos from the start. You may ask, “Why? I have orchestrated/automated everything, I just need to spin resources up and down.” Cloud environments are fundamentally different from the virtualization we have become used to. Virtualization relies on infrastructure for resiliency. In the cloud, distributed applications are responsible for their own resiliency, and are independent of the underlying infrastructure. Therefore, cloud apps need backup and recovery options, lest you face a complete machine, data or file meltdown.

    We’ve compiled the top five reasons to backup your OpenStack environment. Take a read and it will become clear why you must include backup in your OpenStack plans.

    1. Compliance — Compliance may seem like an issue for only certain industries—finance and health care come to mind—but nearly every organization has to deal with compliance issues. For some, it’s compliance to external regulations, while for others it’s simply complying with internal policies and best practices. Backup for OpenStack is an essential component for compliance; it ensures the availability of the data at a specific point in time within your OpenStack applications. I was recently involved in a dialogue/string on LinkedIn watching experienced OpenStackers go back and forth debating “pet vs. cattle.” “I am getting tired of it,” one person said. “This is cloud. It’s about scaling up and out … With automation and orchestration there is no need for cattle.” This conversation went on for days. Theory is great. Practice is reality. What people failed to discuss is that compliance or the business units will drive many requirements (such as backup) either today or tomorrow. End of story.
    2. DevOps — Backup is often the forgotten tool for DevOps. Containers are great to use, but the ability to test with real data is an issue. The reason to use backup is quite simple: test and development. With a copy of a production environment, you now can test upgrades and new features in your agile development process. Furthermore, if you lose a machine or your data, or you end up with corrupted files while in the middle of testing or development, your life will be much easier if you have an appropriate backup solution in place. Restoring machines, data and files is a better option than re-creating them entirely. Cookbooks and recipes are great as well, but you still need to couple it with the appropriate “ingredients.” It is like playing with a fake kitchen as a child … do you want to make breakfast with plastic pancakes and toast? Nothing beats the real thing. Yes, more resources are required for one over the other, but when something goes wrong—it is unfortunate—people point fingers.
    3. Disaster recovery plans — While the terms “backup” and “disaster recovery” often are used interchangeably, they are actually not the same thing. You might have what appears to be a great recovery environment (ideally one that mirrors your production environment for high availability), but without a comprehensive backup solution, your recovery might not be the painless experience you expect it to be. Perhaps the solution for intelligent disaster recovery is to marry backup with a Swift environment so you can recover from any point in time, anywhere in your organization.
    4. Save time — Often recovery can be a frantic process, driven by a business need to have the machine, data or files recovered as soon as possible. Or, more likely, sooner than possible. If you are trying to re-create something under that type of environment, there’s a likelihood that mistakes could be made. This becomes increasingly true the more complex and mature your cloud becomes (think about the growing number of workloads and applications). A much easier approach—one that provides you with peace of mind—is to have a comprehensive backup solution ready and available for when you need it. There’s also another reason backup can save you time: When you have to re-create the lost information, you are taking your time away from something else—and that means you are taking a big hit to your productivity. Save yourself and your organization a big headache with backup.
    5. Security and forensics — You never know when you are going to be asked to provide data or files related to a security issue or a forensics investigation. The right backup solution not only makes it easier to assist with the activity, but think how good you’ll look by being able to deliver the information the forensics team needs quickly.

     Are you currently looking into backup solutions for OpenStack? Now that you know why you need backup for OpenStack, learn more about how to backup OpenStack.

  • Threat Stack Cloud Security and Monitoring Now Integrates With Slack For Real-Time Response to Security Threats

    New Integration Provides Security Alerting and Immediate Collaboration for Security and DevOps Teams

    BOSTON– March 9, 2016 – Threat Stack, a leader in cloud security management and compliance, today announced its integration with team communication platform Slack. The Slack integration with Threat Stack’s Cloud Security Platform™ alerts channel members to security concerns and enables instant workflows for cloud-based security operations center (SOC) teams. The Threat Stack Slack integration improves the speed at which team members can respond to and communicate about real threats the instant they happen.

    “Threat Stack’s integration with Slack alerts our entire DevOps team to security concerns and alerts in real-time,” said John de Freitas, principal software engineer, OnShape.”Threat Stack helps us to collaboratively detect potential security issues, and Slack allows us to communicate and address them immediately.”

    “Today’s fast growing businesses leveraging modern infrastructure for scale need to incorporate security into day-to-day workflow tools,” said Pete Cheslock, senior director of operations and support, Threat Stack. “Integrating Threat Stack security alerts into Slack allows for context and conversation around important events, providing valuable insight into activities happening across your infrastructure.”

    Threat Stack’s Slack integration automates SOC team’s processes, delivering only the most important security alerts directly into a designated Slack channel. After all alerts are thoroughly analyzed and baselined within Threat Stack, Severity 1 and 2 alerts are delivered to Slack, including:

    • Abnormal user behavior (e.g., insider threats)
    • Abnormal process behavior (e.g., new process behavior)
    • Abnormal network behavior (e.g., connections to new and bad IPs)
    • File tracking and copying of files
    • Abnormal infrastructure and CloudTrail activity

    The Slack integration works alongside Threat Stack’s audit trail capabilities, and improves SOC teams’ workflows by pinning alerts, dismissing alerts and identifying new patterns and rules. Additionally, Slack Plus users can easily archive conversations for audit and compliance purposes.  By leveraging the benefits of Slack’s real-time communication, users gain deeper context on Threat Stack security alerts and the ability to collaborate pre- and post-alert to determine the best course of action.

    To learn more about Threat Stack’s Slack integration, please visit our blog.

    Availability

    Existing customers can get started by simply providing their webhook API and alert severity preferences in the Threat Stack dashboard.  New customers can get started here: http://get.threatstack.com/threat-stack-free-trial

    About Threat Stack

    Threat Stack enables growth-driven companies to scale with confidence by identifying and verifying insider threats, external attacks and data loss in real-time. The only fully integrated, cloud-native continuous monitoring solution that gives companies instant visibility and automatically responds to changes in their environment, Threat Stack provides the coverage needed to run secure and compliant, in all environments, without sacrificing speed and efficiency. For more information, or to start a free trial, visit threatstack.com.

  • Embracing DevOps in the IoT Era

    Embracing DevOps in the IoT Era

    To those of us struggling to cope with the challenges of delivering software over the Internet of Things (IoT), DevOps can be the savior.

    Delivering software over the Internet is no easy task, and delivering it over the Internet of Things is even more formidable. How do you deliver software to so many “things,” many of which are “loners” unconnected to the rest of the world?

    What’s encouraging is that the software management processes and tools that we know and have learned to love still work in the IoT era. In fact, not only do they work, they are essential.

    We need teams to work together more smoothly and communicate more quickly to mitigate the higher technological risks. DevOps processes and tools, therefore, are critical in the IoT era because they facilitate smooth, well-oiled collaboration between teams.

    A Typical IoT Scenario

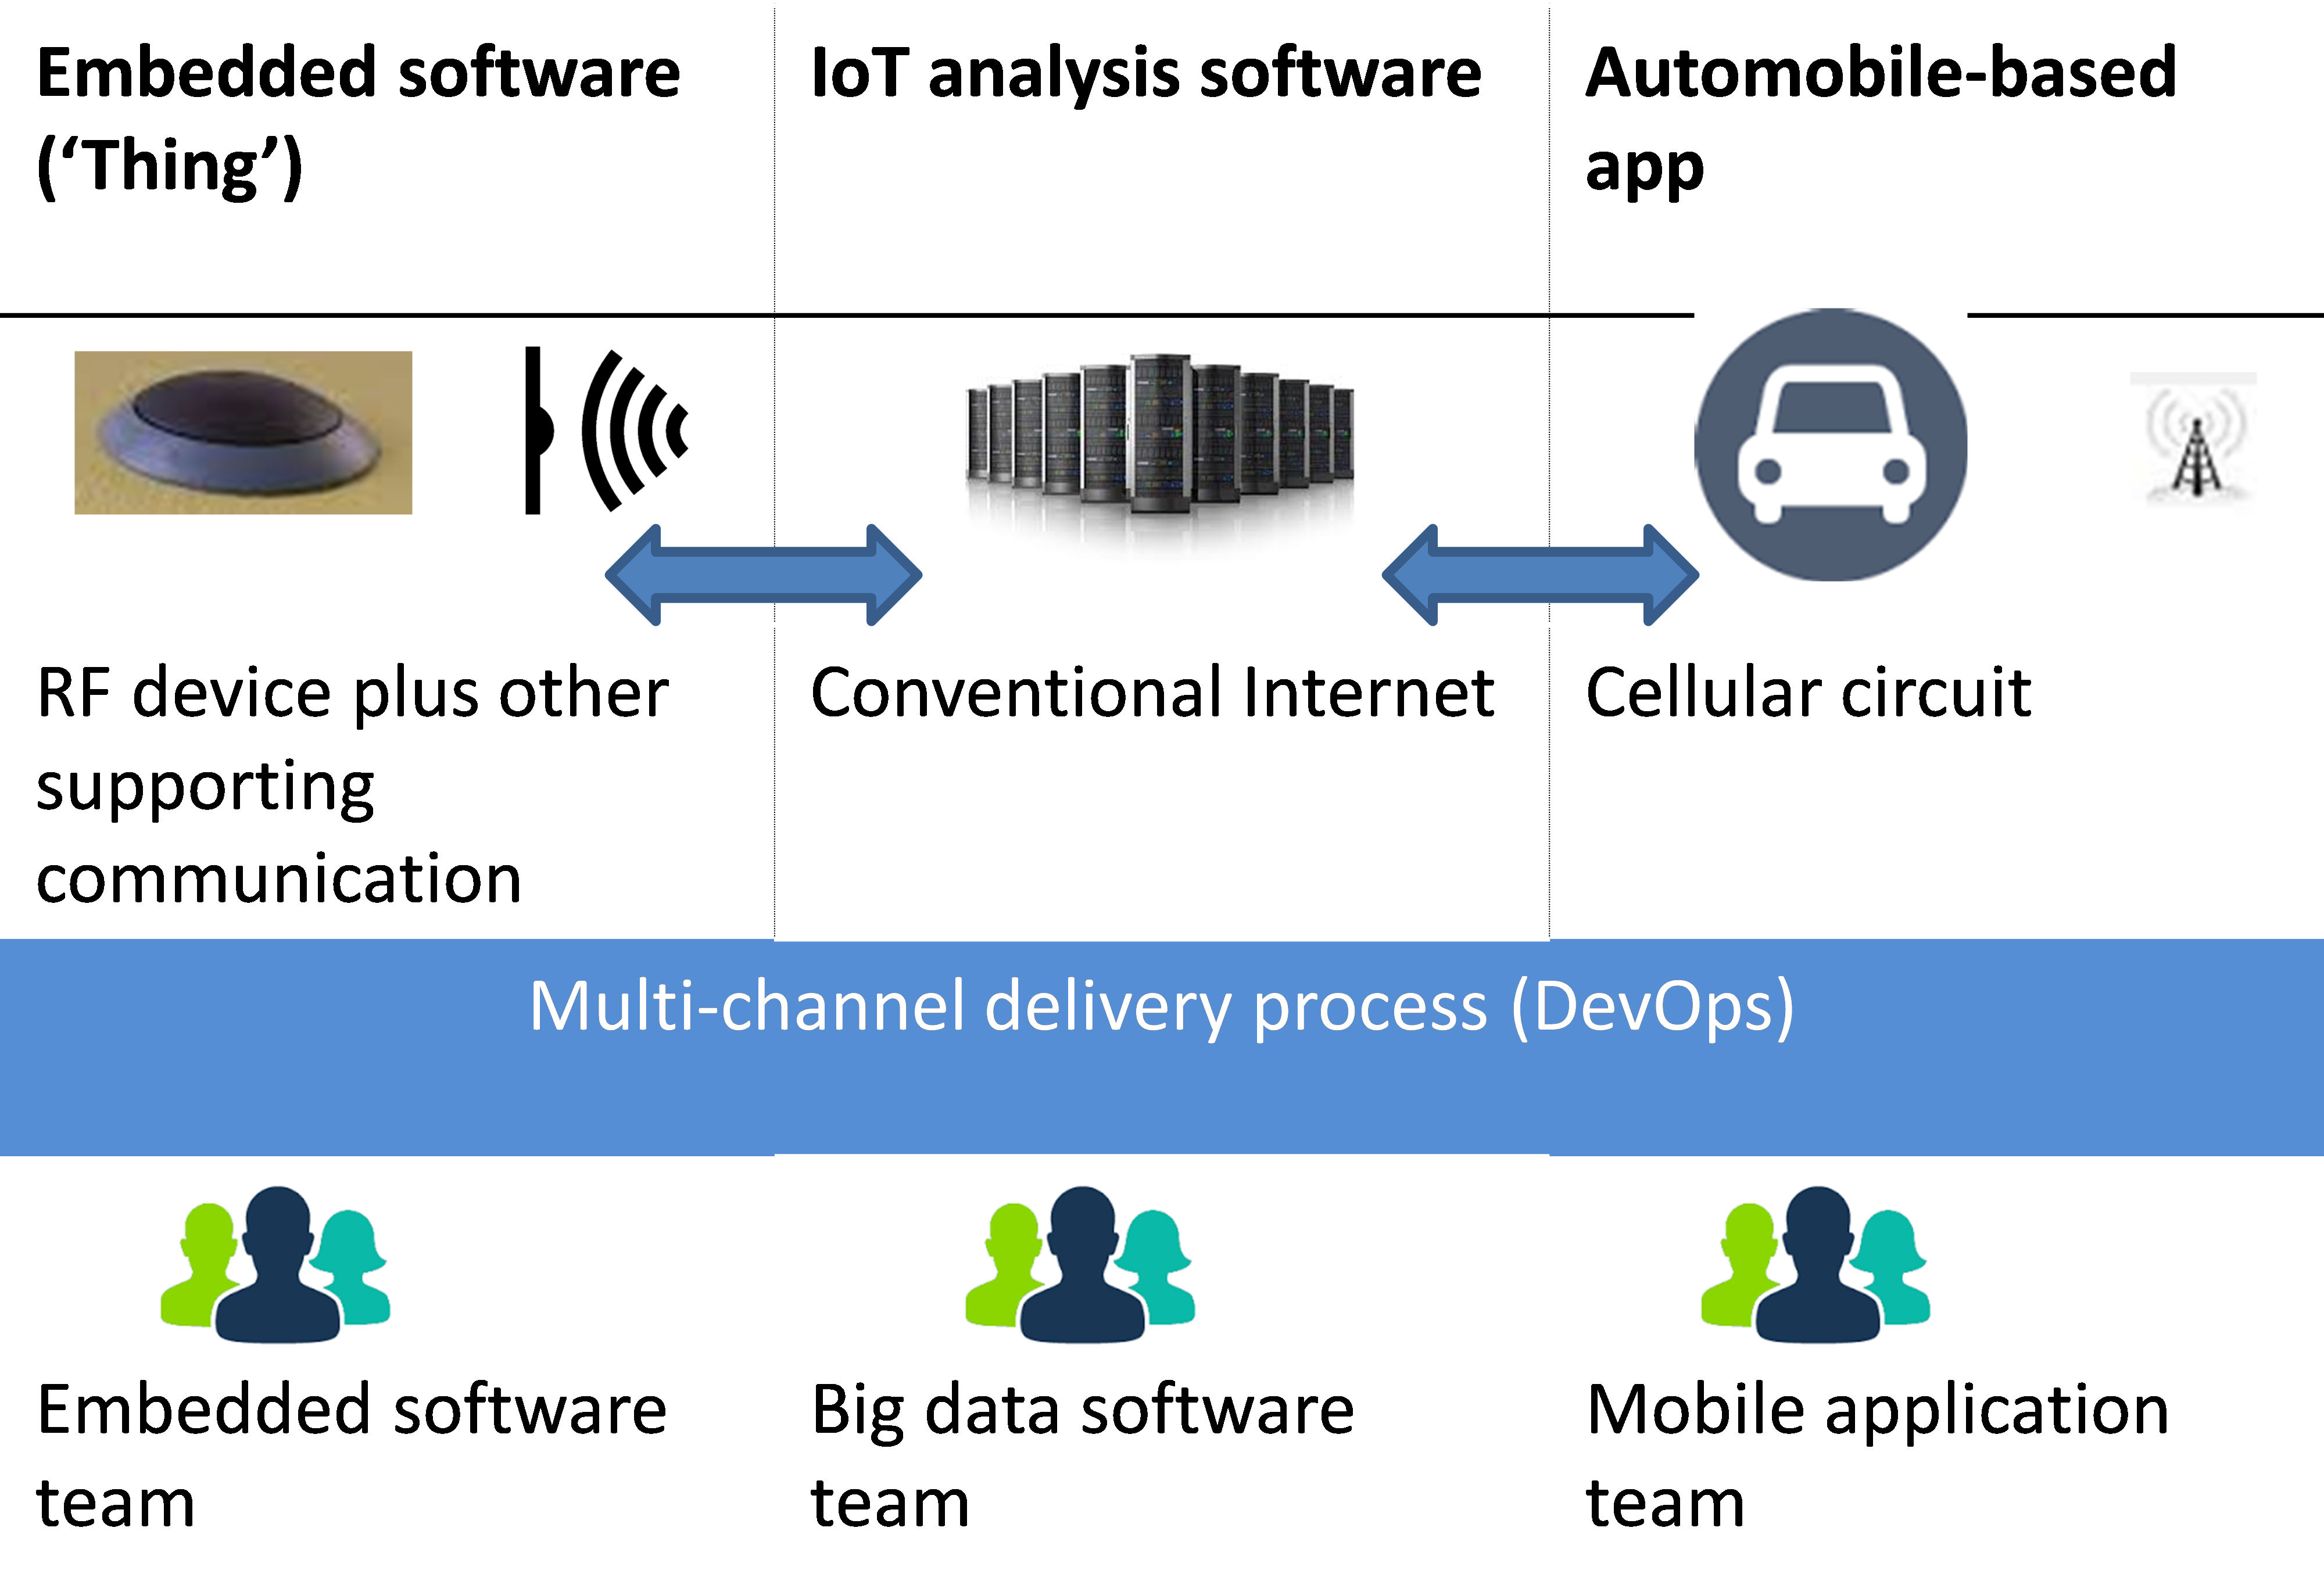
    Consider a scenario in which you need to develop a “smart” parking system for a “smart” city. The system will involve multiple sensors in the parking lots, a display device in each parking area along with communication equipment, a central server for control and analysis and a smart device in each car.

    Drivers can check how many slots are available in nearby parking lots on their automobile devices and navigate to the appropriate parking lot. They also can book slots in advance and start paying from the time they book the slot. When they leave a slot, the parking slot sensor automatically detects that the slot is free and updates a central server. The central server transmits slot availability to the car-based devices, where they become visible to drivers. The central server also generates various kinds of reports and performs various kinds of high-end analysis.

    As with any conventional Internet system, there are multiple software components. All of them have their respective delivery (development, testing and deployment) streams. These streams need to work interdependently and collaboratively, and they need centralized configuration management and dashboards.

    DevOps & IoT

    The Scale and Diversity of IoT

    The differences and challenge, however, lie in the sheer scale of deployment, the diversity of deployment environments and the multiple deployment channels. As you can imagine, any large city will have millions of cars, thousands of parking lots and, hence, hundreds of thousands of individual slots. The number of deployment devices easily can run into the millions.

    In the interest of preventing monopolies, not all the parking sensors will be from one manufacturer. The same holds for the car-based devices. While certain standards can be enforced, not all manufacturers will adhere to one universal protocol. It will be necessary to allow multiple communication and security protocols on these devices. This multiplicity of protocols can complicate software deployment on the devices.

    Other Considerations

    What makes the entire deployment process even more complex is the fact that most of the deployment will be done over the air (OTA). Given that OTA deployment is susceptible to radio-frequency interference and other transmission issues, the deployment process must allow for more robustness than conventional wired deployments.

    There are even more factors to consider: A city-based system can be extremely dynamic. New cars get registered every day, adding to the traffic. New parking lots may be built every now and then and get integrated into the smart city system. New kinds of chips from new sensor manufacturers could be added, as mentioned earlier, to increase competition. New, more sophisticated car-based devices coming into the market might offer to host the smart parking software. Of course, as in conventional systems, new functionality and patch fixes would be released frequently. Finally, as the system becomes part of city life, its utility as an analytical tool could increase beyond analyzing parking trends to other spheres of activity.

    These business and technological factors can exert tremendous evolutionary pressures on the system. A smart system in a smart evolving city must evolve, too. Yet, no change anywhere in the system must be allowed to break the system anywhere else. The chances of this happening are higher in an IoT system because interconnection protocols have not matured enough to become universal and because physical device conditions can never be predicted perfectly. For instance, a single extra field required by the central big data server could place an unsustainable additional burden on the fragile radio-frequency system in the parking lot and bring down the entire data transmission.

    How DevOps Can Help

    To offset the increase in technological and business risk in the IoT, we need robust processes and tools that mitigate the additional risk by improving communication and collaboration between teams. Tools that have the following features become indispensable:

    • A centralized dashboard providing a cross-stream view of the software development;
    • The ability to trace linkages between all related software artifacts across streams and lifecycle stages, given the stressful nature of interdependencies between streams; and
    • A tool that can detect broken linkages.

    The tools also need a well-oiled DevOps management culture that encourages close collaboration and rapid communication between development and operations.

    IoT heightens the need for close collaboration between multiple software streams and within streams between development and operations. Adopting a DevOps culture and DevOps enabling tools is the way to offset the risks of software delivery in the Internet of Things.

    About the Author / Vidhya V. Kumar

    Vidhya V Kumar

    Vidhya is an advisory software engineer at IBM. An evangelist and practitioner of agile methodologies, continuous delivery and documentation, she has about 10 years of experience in the IT industry. She is a subject matter expert in DevOps, application lifecycle management and search methodologies.

  • Taking Stock of DevOps: Where to from Here?

    Taking Stock of DevOps: Where to from Here?

    Have you noticed how every technology trend goes through a series of stages on the path to mainstream adoption? First comes doubt and denial, then tacit acceptance and finally acknowledgement that it works fine after all. The DevOps movement is no different.

    First came questions about what DevOps actually is and its usefulness in an enterprise context (whatever an enterprise actually means these days), then a trickle of success stories and finally the publication of tangible and quantifiable benefits.

    Thankfully, we’ve moved on from the “Is it a bird or is it a plane?” stage. Of course, that doesn’t stop hype, but at least the publication of benefits—such as those recently illustrated in the global study, “Assembling the DevOps jigsaw“—allow us to cut through all the “DevOps solves global warming”-type of nonsense being written.

    So with the value jury finally in, the next question we should be asking about DevOps is, Where to from here? Interestingly, the old Wikipedia entry for DevOps provides some guidance, stating that DevOps is:

    … a culture, movement or practice that emphasizes the collaboration and communication of both software developers and other information-technology (IT) professionals while automating the process of software delivery and infrastructure changes.

    That’s pretty good, because it emphasizes the importance of collaboration across all IT functions (not just Dev and Ops). However, this still doesn’t quite cut it for me. Although lots of cultural and automation heavy lifting has been done to bridge Dev and Ops, more work is needed to understand how aligning other IT functions to DevOps actually benefits the function itself and the business. Also—and perhaps just as important—how aligning other business functions, such as HR and finance, can lead to more success.

    DevOps Works Because It’s Good for Business

    Business leaders talk in terms such as faster lead times, customer conversions and time-to-value, which (putting cultural discussion aside) is really the essence of DevOps. And because DevOps adoption directly correlates to making a buck, it has a fair chance of garnering attention and investment from the business.

    That said then, information security and other professionals would do well to hitch their wagon to DevOps. One of the beauties of the movement is that teams collaborate and provide input much earlier in the development life cycle, with processes then automated to ensure faster release time and quality. By also involving security earlier, businesses could feasibly harden security, balancing all those “rain on your parade” audits and checklists with automated methods that ensure compliant configurations lead to faster deployments.

    An interesting but important benefit is how this approach helps align IT security to business outcomes. Rather than proving its worth through a whole raft of technical sounding measures, such as penetration test scores, patched vulnerabilities or security incidents detected, security can report functional value in context of business goals, such as how automated compliance equals faster releases, leading to increased revenue.

    Of course, DevOps doesn’t just involve Dev, Ops and security, it also will involve other functions providing valuable input to help increase speed and quality. Think of it like the old “Stone Soup” story but without the trickery—everyone, be they software designers, product managers and enterprise architects, providing advice and expertise earlier in the software life cycle so essential elements of resilience, supportability and scale are baked in right from the get-go.

    DevOps Shouldn’t Start and End in IT

    The DevOps way suggests that we shouldn’t just restrict ourselves to IT functions—start there, yes, but other facets of the business should also participate. This sounds like common sense, but in reality it’s more critical because the boundaries between business and digital have blurred significantly. Fail to recognize this and we could end up a silo of good intentions: culturally correct but lacking any teeth.

    This explains why even the much-maligned HR function has a DevOps role to play. For too long, many HR departments have been fundamentally back-office, dipping their toes in the muddy waters of organizational culture with periodic staff surveys and performance appraisals. But this doesn’t go far enough. Now, HR leaders must step out onto software factory floor and work hand-in-step with other DevOps practitioners to identify all the organizational and psychological barriers that inhibit business growth and the development of talent.

    Finance, too, must become aligned to DevOps. This involves moving beyond traditional IT cost-center thinking to developing new fluid funding models needed to stimulate software innovation by agile teams. This means business change agents must join forces with DevOps practitioners to look at better ways to capitalize or expense software development costs or optimally monetize new apps, APIs and information assets. Once again, the earlier this happens in the software life cycle, the better.

    From an IT perspective, we’ve come a long way with DevOps in a relatively short amount of time. But this is only the start of the journey. Most businesses haven’t even considered transformation of the whole organization using DevOps principles as a change agent. Those that do most likely will gain first-mover advantage—and that’s a good place to be in an economy increasingly shaped by application software.

  • Murphy’s DevOps: 7 Habits of Rugged DevOps

    Murphy’s DevOps: 7 Habits of Rugged DevOps

    Attendees of Rugged DevOps Connect at RSA packed Moscone West’s second floor Feb. 29 to immerse themselves in security. Among the presenters of the daylong event was Forrester analyst Amy DeMartine, who provided a tutorial on how security, developers and operations folks can work together better in the new DevOps world.

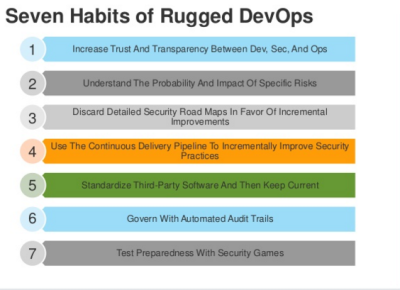
    Through a slide show, DeMartine laid out her Seven Habits of Rugged DevOps, three of which are discussed in this column:

    1: Increase Trust and Transparency Between Dev, Sec and Ops

    We live in a world where technology’s goal increasingly is to automate everything, with less reliance on humans—at least, that’s what many marketers would have us believe. However, DeMartine emphasized that Security and Risk groups, if they are going to play a key role in DevOps, need to speak to the practice’s true owners—App Dev and Infrastructure and Ops—in a language they can understand. Here, it’s not automation that matters most. It’s communication—among actual human beings—that’s paramount.

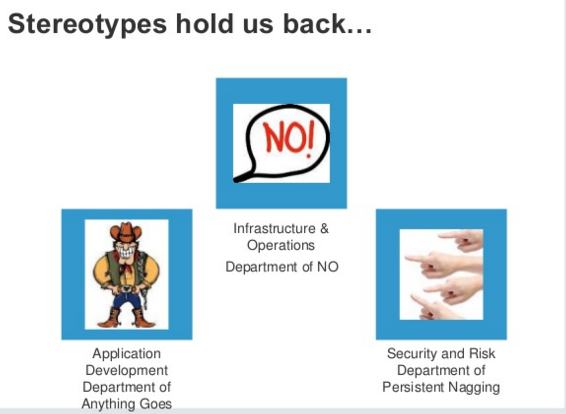
    She emphasized a real disconnect between these groups, with AppDev being perceived as the department of “Anything Goes,” Infrastructure and Ops thought of as the division of “No,” and Security and Risk seen as the “Persistent Nagging” sector.

    7 Habits 4
    Imagine for a minute, a family unit comprised of Mom, Dad and a highly motivated teenager. The teenager is fast, full of energy and always pulling the trigger; Mom is pragmatic, a disciplinarian always having to tug at the teenager’s reins; and Dad is constantly frustrated that no one listens to his determined warnings. The family’s living room is the scene of many “heated” debates, where each side scores its share of wins but there are really no common agreements that satisfy everyone’s needs. When the teenager wins, it’s because Mom simply doesn’t have the energy to resist any further. When Mom wins, the teenager turns on the iTunes, plugs in the headphones, withdraws and possibly even starts searching for a new family. Dad’s victories are often followed by a series of door slams and the silent treatment.

    Now imagine if the three sides found a common language? One that not only got each to see the others’ viewpoints but also developed a system where the teenager was set free to operate within defined boundaries, and where he or she even wore enough safety gear to keep risk to a minimum. We’d have a much more harmonious place, one where the teenager continued to grow without risking the family ship.

    Interestingly enough, there really isn’t any technology available that addresses this very real human communication challenge. No mater how counter intuitive it may seem, an effective Rugged DevOps environment is highly dependent on human-to-human relations.

    3: Discard Detailed Security Road Maps in Favor of Incremental Improvements

    The U.S. Office of Personnel Management (OPM), Sony, Hollywood Presbyterian, Anthem—each of these organizations experienced a security breach of massive scale. If these breaches all shared a word in common it would be PANIC—or at least headlines would have us believe this. The OPM breach was the ultimate example, wherein almost as soon as the alarm bell rang the government announced an elaborate plan followed by the big “Sprint.” Although, it might have been wiser just to beef up phishing defenses (smiley face).*

    It turns out that a detailed long-term plan may not be the answer to data breaches, ransoms and system shut-downs.

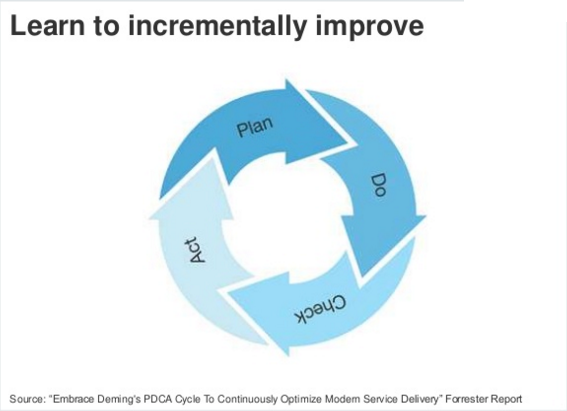
    DeMartine said outright that a comprehensive road map for addressing threats should be discarded in favor of a vision for real-time measurement and incremental improvements. Below is the “circle of life in security and DevOps,” as envisioned by DeMartine:

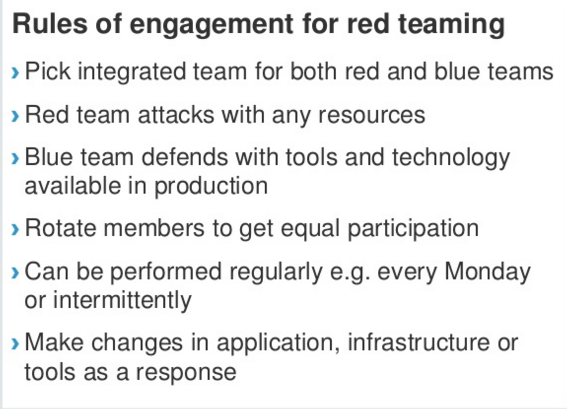
    7: Test Preparedness with Security Games

    Who doesn’t like competition? Not many. I think security folks and hackers are probably some of the most competitive people around; visit a Black Hat conference and watch as attendees intently capture flags, break out of handcuffs and hack signs.

    With that in mind, it makes sense that this is one of the seven habits. There’s little doubt that simulations will do more to prepare people for real-life situations—after all, practice makes perfect.

    Communication is a Rugged DevOps Essential Tool

    Increasing trust between Dev, Sec and Ops mandates effective and, likely, improved communication. Perhaps one of the biggest takeaways is that, for all the technological bells and whistles the industry throws at combating cybercrime, in the end an age-old skill—communication—is at the foundation of the most-effective security.

    *Phishing is assumed the most likely cause of the OPM breach; it is important to disclose that one of my clients, PhishMe, is a phishing defense solutions provider.